GPT-5 Capabilities: The Complete Technical Guide for Developers & Founders
Everything that actually matters about OpenAI’s flagship model — benchmarks, pricing, hallucinations, and what it means for your product in 2025–2026.
NeuralWired Research Desk
|
May 28, 2026
|
18-min read
GPT-5 CapabilitiesDeveloper GuidePricing Alert
On August 7, 2025, OpenAI didn’t just release a new model. It collapsed its entire model portfolio into one, and then the flagship feature broke on launch day. Nine months later, GPT-5 is the engine behind 900 million weekly active users and a $25 billion revenue run rate. This guide separates what GPT-5 actually delivers from what OpenAI wants you to believe it delivers.
By NeuralWired Research Desk · Updated May 28, 2026
What Is GPT-5?
GPT-5 is OpenAI’s flagship large language model, released on August 7, 2025 at 10AM PT. It’s available across ChatGPT (all user tiers), the OpenAI API platform, and the GitHub Models Playground.
The defining architectural move: GPT-5 is a unified system, a single model that houses a fast conversational sub-model for routine queries and a deep reasoning sub-model (“GPT-5 Thinking”) for complex tasks. A real-time router decides which mode engages, based on query complexity, tool requirements, and signals like a user typing “think carefully about this.”
Before GPT-5, users had to manually choose between the GPT-4o series (fast, conversational) and the o-series reasoning models (o1, o3, slower, more accurate on math and science). GPT-5 eliminates that decision entirely. Or it was supposed to, the router malfunctioned on launch day, which we’ll get to.
“It’s like talking to an expert. A legitimate, PhD-level expert in any area you need.”
Sam Altman, CEO, OpenAI, Pre-recorded press briefing, August 7, 2025
That PhD-level framing maps to specific benchmarks: 88.4% on GPQA Diamond (graduate-level science) and 67.2% on HealthBench (medical conversations). The claim isn’t hype without data. Whether the data holds up in your production environment is a different question.
94.6%
AIME 2025 Math
74.9%
SWE-bench Verified
88.4%
GPQA Diamond Science
88%
Aider Polyglot Coding
84.2%
MMMU Multimodal
67.2%
HealthBench Medical
GPT-5 Benchmark Scores: The Complete Breakdown
Benchmarks are the language enterprises use to justify procurement and the numbers engineers use to set expectations. Here’s what GPT-5 actually scored, source-attributed, with methodology noted.
Benchmark
GPT-5 Score
What It Measures
Why It Matters
AIME 2025
94.6%
High school olympiad mathematics
Stumps most adults. Signals deep reasoning without tools.
SWE-bench Verified
74.9%
Real-world software engineering (bug-fixing)
GPT-4.1 scored 54.6% four months earlier — a 20-point jump.
Aider Polyglot
88%
Cross-language coding ability
Multi-language production relevance for full-stack teams.
GPQA Diamond
88.4%
PhD-level physics, chemistry, biology
Curated to be hard even for the PhDs who wrote the questions.
MMMU
84.2%
Multimodal understanding
Image + text reasoning for document-heavy workflows.
HealthBench
67.2%
Clinical conversation quality
Benchmark for medical AI deployments in regulated settings.
The SWE-bench figure deserves special attention. OpenAI’s developer page documents the trajectory: GPT-4o scored 33.2%, GPT-4.1 reached 54.6%, and GPT-5 hit 74.9%, all within a 12-month window. For engineering teams, that isn’t a benchmark number. That’s the delta between “AI assists with code” and “AI autonomously closes GitHub issues.”
Key Insight
GPT-5’s token efficiency is a hidden financial story. OpenAI reports 50–80% fewer output tokens than o3 for equivalent performance, meaning if your pipeline previously ran on o3, switching to GPT-5 can cut token costs roughly in half before factoring in any price-per-token differences.
How GPT-5 Differs from GPT-4o and o3
The simplest framing: GPT-5 is what you’d get if GPT-4o and o3 had a child that also knew when to think slowly.
GPT-4o was fast and conversational. o3 was slow and brilliant at math and science. Users had to choose between them depending on the task, a friction point that caused constant miscategorization. GPT-5’s real-time router eliminates that choice.
Three concrete differences that change day-to-day developer experience:
No manual model selection. The router decides whether to engage fast or deep reasoning based on query complexity. In practice, this works better for ambiguous tasks than users tended to perform at self-selection.
45% fewer factual errors than GPT-4o in OpenAI’s internal testing. In reasoning mode, the figure climbs to 80% fewer errors versus o3. (Independent validation is mixed, see Section 7.)
Front-end web development outperforms o3 70% of the time in OpenAI’s internal evaluations. For developers doing full-stack work, that’s not marginal, that’s a genuine first-pass quality shift.
⚠ Launch Day Reality Check
The routing feature — GPT-5’s central innovation, malfunctioned on August 7, 2025. The flagship technical differentiator did not function correctly on day one. Additionally, OpenAI published benchmark bar charts that visually contradicted their own numerical data: the “coding deception” chart showed GPT-5 with a shorter bar than o3, despite GPT-5’s lower number indicating better performance. InfoQ documented both issues in detail. OpenAI issued corrections. Both errors raised legitimate questions about internal quality control for the company’s most important launch in two years.
GPT-5 API Pricing: What You’ll Actually Pay
This is the section that should be pinned to every startup’s engineering Slack. GPT-5 launched at a price point that made it seem like the cost curve was finally working in developers’ favor. What happened next was not that.
Model Version
Release Date
Input (per 1M tokens)
Output (per 1M tokens)
GPT-5 (launch)
August 7, 2025
$1.25
$10.00
GPT-5.4
~March 2026
$2.50
—
GPT-5.5 (“Spud”)
April 23, 2026
$5.00
$30.00
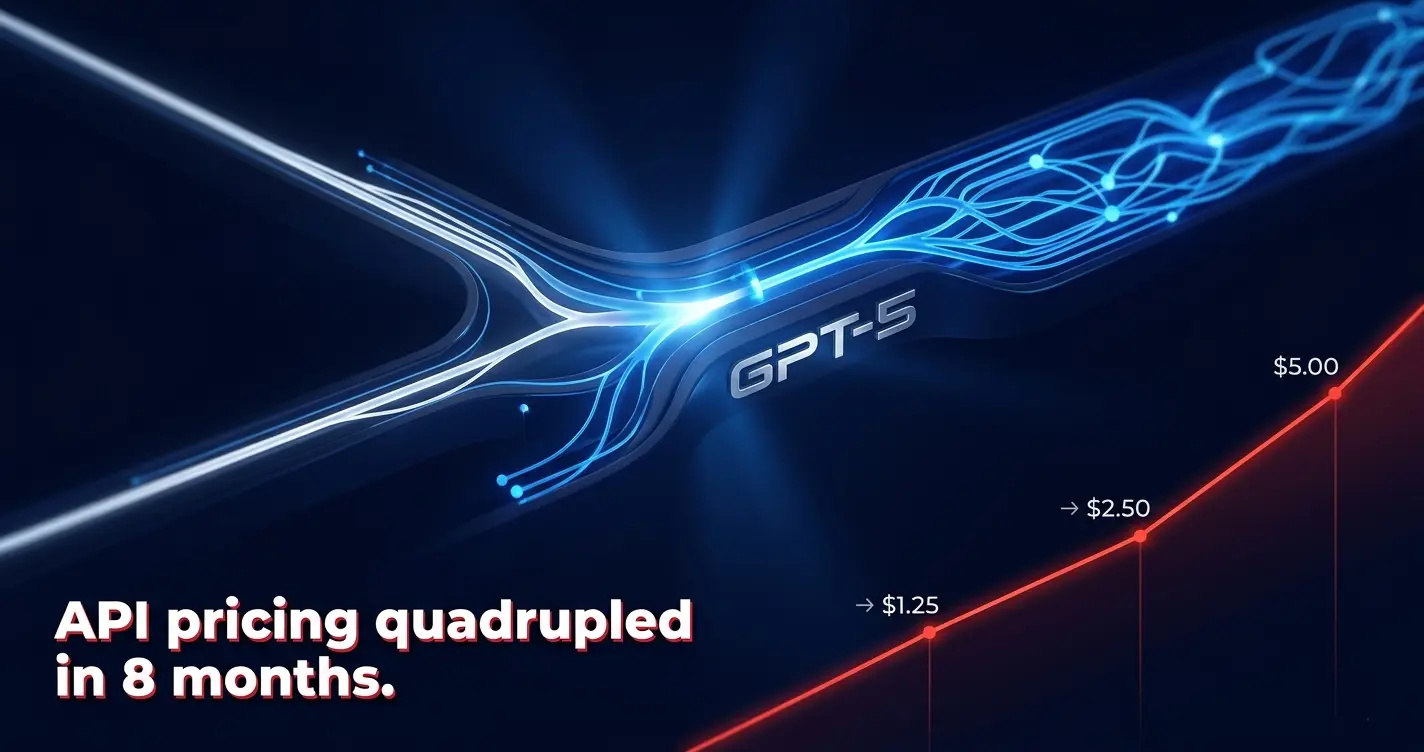
API input pricing quadrupled in eight months. Output pricing tripled. During the same period, NVIDIA CEO Jensen Huang stated that hardware costs per inference token dropped approximately 35×. OpenAI’s pricing trajectory is not following infrastructure economics. It’s following market demand and competitive positioning.
Any product with significant token throughput that was budgeted at $1.25/M input is now facing 4× the cost if it has migrated to current models. That’s not a price increase, it’s a category change in unit economics.
NeuralWired Research Desk analysis, May 2026
For ChatGPT users: Plus ($20/month) includes GPT-5 with usage limits on thinking-mode messages. Pro ($100–$200/month, restructured from launch’s $200 flat) includes GPT-5 Pro with extended reasoning and no token budget restriction. Ed Zitron, tech critic and writer, framed the launch bluntly:
“Meaningful functionality… is being completely removed for ChatGPT Plus and Team subscribers.”
Ed Zitron, Technology Critic — “Where’s Your Ed At” newsletter, August 2025, via Voiceflow
Our read: Zitron’s critique is specifically about model-selection removal and rate limits, not raw capability. Both things can be true, GPT-5 is technically more capable than GPT-4o, and Plus users received fewer choices with the upgrade. Whether that trade is acceptable depends entirely on your use case.
GPT-5 Context Window and Technical Specs
Parameter
GPT-5 (August 2025)
GPT-5.5 (April 2026)
Context Window
400,000 tokens
1,050,000 tokens (1M+)
Max Output
128,000 tokens
—
Knowledge Cutoff
September 2024
—
Latency (tokens/sec)
~77.7 (Artificial Analysis)
—
Training Infrastructure
Microsoft Azure AI supercomputers
Distribution at Launch
ChatGPT, OpenAI API, GitHub Models, Agents SDK
The 400K context window matters for enterprise document workflows, processing full legal contracts, entire codebases, or multi-year financial filings in a single call. GPT-5.5’s 1M+ token context is available via the API and makes whole-repository code analysis practically viable for the first time in the OpenAI stack.
GPT-5 vs Claude and Gemini
The short answer: neither model is comprehensively superior. Benchmark leadership is task-specific, and it’s shifting faster than procurement cycles can track.
Benchmark
GPT-5.5 (Apr 2026)
Claude Opus 4.7 (Apr 2026)
Leader
Terminal-Bench 2.0
82.7%
69.4%
GPT-5.5
ARC-AGI-2
85.0%
75.8%
GPT-5.5
SWE-Bench Pro
58.6%
64.3%
Claude Opus 4.7
The competitive moat OpenAI held during the GPT-4 era has narrowed materially. Artificial Analysis scores GPT-5 at 45/100 on their Intelligence Index — above most models but not the categorical lead OpenAI commanded in 2023. ChatGPT’s US mobile app daily active user share fell from 69.1% in January 2025 to 38.7% by May 2026. Anthropic’s Claude app went from under 2% to 10% DAU share in three months.
GPT-5 is still the market leader by revenue and user count. It isn’t the unchallenged technical leader on every dimension.
Does GPT-5 Still Hallucinate?
Yes. Less than before — but the gap between what OpenAI claims and what independent testers find is real and worth understanding before you deploy in a regulated environment.
OpenAI’s claim: 45% fewer factual errors versus GPT-4o; 80% fewer errors in reasoning mode versus o3.
Independent testing: Vectara found GPT-5.2 had an 8.4% hallucination rate in their methodology, trailing DeepSeek. OpenAI’s own figure for GPT-5.2 was a reduction from 8.8% to 6.2%: a more modest 30% improvement, not the dramatic leap marketing suggested.
PCMag’s Ruben Circelli, who reviewed GPT-5 against real-world production tasks rather than benchmark conditions, was direct:
“GPT-5 is an ‘insignificant update.’ While it has some upgrades, it ‘doesn’t solve the problems that actually matter’ and he has not ‘noticed a significant improvement’ in areas like hallucination reduction.”
Ruben Circelli, Senior Analyst, PCMag — August 2025, via Voiceflow
That’s the practitioner gap: benchmark-measured hallucination uses controlled scenarios with defined correct answers. Production use involves open-ended, ambiguous queries where the model can’t know what it doesn’t know. GPT-5 is more reliable than GPT-4o. It’s not hallucination-free. Deploy accordingly.
One genuinely encouraging signal: a peer-reviewed study by Polat et al. (six MDs across four Turkish hospitals, published November 2025 in Letters to the Editor, NCBI) concluded that GPT-5’s measurable reduction in hallucination rates represents a meaningful milestone for medical and scientific writing, one of the first published academic assessments from clinical practitioners in a domain where errors cost lives. That’s cautious optimism, not a blanket clearance.
GPT-5 for Developers: Coding, Agents, and the Agents SDK
If you’re building software with or on AI, GPT-5 changes three things materially, and creates one significant risk.
What changes in practice
74.9% SWE-bench means autonomous issue resolution, not just code suggestions. At GPT-4o’s 33.2%, AI-assisted coding meant “AI suggests, human implements.” At 74.9%, the model can autonomously close real GitHub issues in verified test conditions. Combined with the Agents SDK (which provides orchestration, tracing, and MCP connectivity to external tools like CRM, payment, and support systems), multi-step autonomous pipelines are production-grade for the first time.
GPT-5 beats o3 at front-end web development 70% of the time. For developers doing full-stack work, that’s not marginal assistance, it’s output-quality output at first pass. The net result is that senior engineering time spent on routine implementation patterns (API integrations, UI scaffolding, documentation) can shift toward architecture and review.
What to do right now
Audit your current stack for tasks that consume disproportionate senior engineering time but follow a pattern: bug triage, code review, documentation, API integration. These are GPT-5’s highest-ROI targets. Evaluate the Agents SDK as an integration layer before building a custom orchestration system from scratch.
The risk you need to price in
⚠ API Pricing Risk
API pricing quadrupled from August 2025 to April 2026. Any product budgeted at GPT-5 launch pricing with significant token throughput is now 4× the cost if it has migrated to current models. Build pricing escalation assumptions into any business case that relies on the GPT-5 stack. A multi-vendor or open-source fallback strategy isn’t optional caution at this point — it’s basic financial hygiene.
GPT-5 for Founders: What Changes in Your Build-vs-Buy Decisions
The uncomfortable truth: GPT-5 compressed the moat of a large class of AI startups in a single launch. If your competitive advantage was “we built a better AI wrapper,” that advantage has narrowed to the point where you need to name what specifically you still do better than the base model.
The opportunity is real too. Enterprise deployments at GPT-5 launch included Morgan Stanley (financial workflows), Amgen (scientific research), and T-Mobile (customer operations). Fortune 500 procurement of AI tools has accelerated. If you serve any of those verticals, GPT-5 integration is now a procurement requirement, not a differentiator.
42% of new SaaS platforms with AI capabilities launched in 2025 relied on OpenAI models. That means GPT-5 is infrastructure. The differentiation layer has shifted up the stack, to proprietary data, domain-specific fine-tuning, and integration quality. Prompt engineering alone isn’t a moat anymore. It arguably never was, but GPT-5 made that unavoidable.
Founder Action Item
Invest now in proprietary data pipelines and fine-tuning infrastructure. The competitive question for any AI-native product is no longer “is our model good?”, it’s “do we have data the base model doesn’t?” That’s where defensible differentiation now lives.
The Skeptic’s Case: What GPT-5 Doesn’t Solve
Balanced coverage means saying the things OpenAI’s press releases don’t.
The AGI framing is marketing
Sam Altman’s description of GPT-5 as offering “PhD-level expertise” maps directly to one benchmark: GPQA Diamond. In controlled academic tests with defined answers, GPT-5 performs at a PhD level on scientific knowledge retrieval. On open-ended reasoning chains involving novel problems, ambiguous real-world data, or multi-domain synthesis, it remains significantly below expert human performance.
GPT-5 performs comparably to or better than human experts in roughly half of cases across 40+ occupations. That means it performs worse than human experts in the other half. At NeurIPS 2025, only 2 of 5,000 papers mentioned AGI. Prominent researchers including Demis Hassabis have emphasized that scaling transformers hits a cognitive scaling wall, current paradigms require paradigm-level innovation, not just larger models, to reach genuine general intelligence.
Agentic reliability isn’t solved yet
GPT-5’s agentic capabilities are real. The reliability math is not flattering for complex pipelines. A 95% success rate per tool call yields approximately 60% end-to-end success over 10 sequential steps. Enterprises deploying GPT-5 agents in customer-facing workflows without robust human-in-the-loop checkpoints are assuming a reliability threshold the model doesn’t yet consistently meet.
Regulatory exposure in regulated sectors
GPT-5’s use in healthcare, legal, and financial services creates EU AI Act exposure. OpenAI hasn’t published a conformity assessment for GPT-5 under the Act’s high-risk provisions. Companies deploying it in these domains are accepting compliance risk that OpenAI itself hasn’t fully addressed publicly. If you’re a CTO in a regulated vertical, that’s not a footnote, it’s a procurement risk factor that belongs in your security review.
The GPT-5 Model Family: From 5.1 to 5.5
GPT-5 is not a single model, it’s an ongoing release cadence. Five significant versions shipped in the nine months after launch.
Coding and agentic focus, front-end design improvements
GPT-5.5 “Spud”
April 23, 2026
1M+ token context, Terminal-Bench 2.0 at 82.7%, API pricing doubled from 5.4
The pace is deliberate. Sam Altman reportedly referred to GPT-5.5 as “the last big milestone before AGI” in internal remarks reported by the Financial Times in April 2026. Read carefully: that statement describes the current training paradigm having one or two more generations of runway before requiring a fundamental architectural shift, not a claim that AGI is imminent. It’s being read by many outlets as a promise it isn’t.
Our read: the GPT-5 series demonstrates that OpenAI has internalized the launch-iterate model from consumer software. The implication for anyone building on it is that the model you ship against today may be meaningfully different in six months, for better (capability) and worse (pricing).
Frequently Asked Questions
What is GPT-5?
GPT-5 is OpenAI’s flagship large language model, released August 7, 2025. It’s a unified system combining a fast conversational sub-model and a deep reasoning sub-model, with an automatic router that selects the right mode per query. It powers ChatGPT by default and is available via the OpenAI API. GPT-5 sets leading benchmarks in math (94.6% AIME 2025), coding (74.9% SWE-bench), and science (88.4% GPQA Diamond).
How is GPT-5 different from GPT-4o?
GPT-5 unifies GPT-4o’s conversational speed with the o-series reasoning models into one system, eliminating manual model selection. It reduces factual errors by 45% compared to GPT-4o, scores 20 percentage points higher on SWE-bench (74.9% vs. GPT-4o’s ~54%), and introduces a real-time routing system that decides when to engage deeper reasoning without user input.
What are GPT-5’s benchmark scores?
GPT-5’s official benchmark scores: 94.6% on AIME 2025 (advanced math), 74.9% on SWE-bench Verified (software engineering), 88% on Aider Polyglot (coding), 84.2% on MMMU (multimodal), 88.4% on GPQA Diamond (PhD-level science, Pro reasoning), and 67.2% on HealthBench (medical). Published by OpenAI at launch, August 2025.
How much does GPT-5 cost via the API?
GPT-5 launched at $1.25/M input tokens and $10/M output tokens (August 2025). Pricing escalated significantly: GPT-5.4 (March 2026) costs $2.50/M input; GPT-5.5 (April 2026) costs $5.00/M input and $30/M output, a 4× input increase in eight months. ChatGPT Plus ($20/month) includes access with usage limits; ChatGPT Pro ($100–$200/month) includes GPT-5 Pro with full extended reasoning.
What is GPT-5’s context window?
GPT-5 launched with a 400,000-token context window and a maximum output of 128,000 tokens per response. Knowledge cutoff is September 2024. GPT-5.5 (April 2026) extended the context window to over 1,050,000 tokens (1M+) via the API, making whole-repository code analysis and large-document processing viable in a single call.
Is GPT-5 better than Claude?
It depends on the task. GPT-5.5 leads Claude Opus 4.7 on Terminal-Bench 2.0 (82.7% vs. 69.4%) and ARC-AGI-2 (85.0% vs. 75.8%). Claude Opus 4.7 leads on SWE-Bench Pro (64.3% vs. 58.6%). Neither model is comprehensively superior, and benchmark leadership is shifting faster than it has at any prior point in the LLM competitive cycle.
Does GPT-5 still hallucinate?
Yes, less than before, but not eliminated. OpenAI reports 45% fewer errors versus GPT-4o. Independent testing by Vectara found an 8.4% hallucination rate in GPT-5.2. PCMag reviewers reported no significant improvement in real-world use. The gap between benchmark hallucination and production hallucination is real; GPT-5 is more reliable than its predecessors but not hallucination-free.
What is GPT-5 Pro?
GPT-5 Pro is the maximum-compute reasoning variant of GPT-5, exclusive to ChatGPT Pro subscribers ($100–$200/month as of April 2026). It enables extended “thinking” reasoning with no token budget restriction, producing more thorough answers on complex tasks. It scores higher than standard GPT-5 on GPQA Diamond (88.4%) and FrontierMath benchmarks.
When was GPT-5 released?
GPT-5 was officially released on August 7, 2025, at 10AM PT. OpenAI teased the launch the previous day via a post on X embedding the number “5” in the announcement text. The model launched simultaneously on ChatGPT (all user tiers), the OpenAI API platform, and the GitHub Models Playground.
What You Now Know | And Where This Goes Next
GPT-5 is the most commercially successful AI model ever released. It is also an imperfect product that malfunctioned on launch day, shipped benchmark charts that contradicted their own data, and has since quadrupled its API pricing while hardware costs fell 35×.
Both things are simultaneously true. The model is genuinely capable, 74.9% SWE-bench and 88.4% GPQA Diamond are not noise. The commercial moat is real, $25B+ ARR and 900 million weekly users are not accidents. And the operational risks are real: pricing escalation, benchmark-to-production hallucination gaps, regulatory exposure in high-risk sectors, and compounding error rates in agentic pipelines.
Three things to watch over the next 6–18 months:
The competitive parity story. Claude Opus 4.7 already leads on SWE-Bench Pro. Gemini 3.1 competes on multimodal benchmarks. ChatGPT’s US mobile market share is below 40% for the first time. GPT-5 may not hold the benchmark lead across all dimensions by the end of 2026.
The pricing ceiling. There’s no economic argument for API pricing increasing 4× in 8 months when inference costs are dropping. OpenAI is pricing against demand, not against cost. Watch for whether competition forces a reversal, or whether the market absorbs it.
Agentic deployment reliability. The gap between GPT-5’s agentic capabilities and production-grade reliability in multi-step autonomous pipelines is the defining technical question for enterprise AI in 2026. The teams that figure out human-in-the-loop architectures that are fast enough to be useful will define what enterprise AI actually becomes.
GPT-5 is infrastructure now, the same way GPT-4 became infrastructure. The question isn’t whether to use it. It’s how to build on it without being entirely at the mercy of OpenAI’s pricing decisions, and where to differentiate above the model layer.
Stay Ahead of the AI Model Cycle
The Neural Loop covers frontier model releases, benchmark analysis, and what they actually mean for your product, before the hype settles.
Subscribe to The Neural Loop →
Artificial IntelligenceCareer Guide • May 23, 2026
How to Become a Prompt Engineer in 2026: The Honest Guide
The standalone job title is collapsing. The underlying skill is becoming mandatory across every technical role. Here’s the real path, skills, salaries, courses, and the warnings nobody else will tell you.
N
NeuralWired Editorial
12 min read • Updated May 23, 2026
⏱ 12 min
In 2023, Anthropic posted a job listing that broke the internet. The role: Prompt Engineer and Librarian. The salary ceiling: $335,000. The requirement that caused the real frenzy: no PhD, minimal coding experience. For a brief moment, the world believed you could earn a doctor’s salary just for being very, very good at talking to chatbots.
That moment is over.
Searches for “prompt engineer” on Indeed have dropped 86% from their April 2023 peak. Microsoft surveyed 31,000 workers across 31 countries and found that Prompt Engineer ranked second-to-last among roles companies plan to hire in the next 18 months. The standalone title, for most organizations, never really materialized.
And yet, here you are, reading a guide on how to become a prompt engineer. And the search volume for that exact phrase has surged 5,000%+ in the past 12 months. Both things are true at once, and the tension between them is exactly what this guide is about.
Our Read
The job title is dying. The skill is becoming mandatory. If you’re learning how to become a prompt engineer in 2026, you’re not chasing a job title, you’re building a capability layer that will sit underneath every technical role in the next decade. That reframe changes everything about how you should approach this.
The Paradox Nobody Is Talking About
Two credible, opposing forces are pulling at this field simultaneously. Understanding both is the foundation of making any smart career decision here.
The optimistic case is real: Grand View Research puts the global prompt engineering market at $222 million in 2023, projecting it to hit $2.06 billion by 2030, a CAGR of 32.8%. McKinsey reports that 71% of organizations now use generative AI in at least one business function. Every one of those deployments requires someone who knows how to work with language models systematically. That’s real demand.
The skeptical case is equally real. Fortune reported in May 2025 that Allison Shrivastava, economist at Indeed, put it plainly:
Prompt engineering as a skill is still definitely a good thing to have, but it’s not an entire title.
Allison Shrivastava, Economist, Indeed (Fortune, May 2025)
Jared Spataro, Microsoft’s Chief Marketing Officer for AI at Work, was even more direct. After his team’s survey of 31,000 workers across 31 countries:
Two years ago, everybody said, ‘Oh, I think prompt engineer is going to be the hot job.’ It’s not turning out to be true at all.
Jared Spataro, CMO AI at Work, Microsoft (Wall Street Journal, 2025)
His argument: modern AI models now ask clarifying questions, acknowledge uncertainty, and self-iterate. The human middleman who translated vague instructions into precise prompts is being absorbed into the model itself.
So which camp is right? Both. The reconciliation is simple: the discipline is real; the job description isn’t. Prompt engineering is becoming what spreadsheet literacy became in the 1990s, not a career, but a baseline competency that elevates every career it touches. Andrew Ng made this comparison explicitly, and it’s the clearest mental model available.
32.8%
Projected annual market growth (CAGR) through 2030
71%
Organizations now using generative AI in at least one function
−86%
Drop in “prompt engineer” job searches on Indeed since peak (April 2023)
What a Prompt Engineer Actually Does
Strip the hype and the definition is precise. Prompt engineering is the systematic practice of designing, structuring, and optimizing text instructions, prompts, to guide large language models like OpenAI’s ChatGPT, Anthropic’s Claude, and Google’s Gemini toward accurate, relevant, and consistent outputs. It combines natural language processing, cognitive science, linguistics, and iterative systems design.
That last part matters: iterative systems design. The most important thing Isa Fulford’s widely-used curriculum at DeepLearning.AI establishes is that effective prompting is not about finding “magic words.” It’s about systematic evaluation, measurement, and structural thinking. The people who treat it that way build things that work in production. The people who treat it as a creative guessing game produce inconsistency at scale.
The Core Techniques You Actually Need to Know
Technique
What It Is
When to Use It
Zero-shot prompting
No examples given; model uses training knowledge alone
Simple, well-defined tasks; quick prototyping
Few-shot prompting
1–5 examples embedded in the prompt to guide output format
Consistent formatting, classification tasks, tone matching
Chain-of-thought (CoT)
Instructs model to reason step by step before answering
Logic, math, multi-step problem solving
Retrieval-Augmented Generation (RAG)
Combines LLM with external knowledge base to reduce hallucination
Background instructions defining model persona, scope, and constraints
Product deployments, customer-facing AI tools
Prompt chaining
Linking multiple prompts sequentially; each output feeds the next
Complex multi-step workflows, agent pipelines
The Skills That Actually Matter in 2026
Here’s where most guides go wrong: they describe the skills that got people hired in 2023. The market has moved. Based on aggregated requirements from active listings at Google, Microsoft, Amazon, JPMorgan Chase, Booz Allen Hamilton, and leading AI-native startups, here’s what employers are actually looking for right now.
LLM API proficiency, At minimum one of: OpenAI, Anthropic Claude, Google Gemini, or Microsoft Copilot. Not just using the chat interface, working with the API programmatically.
Prompt technique mastery, Zero-shot, few-shot, chain-of-thought, RAG. These aren’t optional vocabulary; they’re the toolkit every practitioner is expected to have.
Python programming, Strongly preferred for senior roles; not always required for entry-level marketing or content positions. If you want engineering-tier compensation, this is non-negotiable.
Token economics and context window management, Understanding how models handle input length, what falls out of context, and how to structure information for reliability.
Evaluation and benchmarking, The ability to design A/B tests for prompts, measure output quality systematically, and build evals that catch prompt drift when models update. This is where most entry-level practitioners fall short.
Responsible AI and bias detection, Not a box-check skill. Organizations deploying AI at scale have legal and reputational exposure; people who can identify and mitigate bias in LLM outputs are genuinely scarce.
Domain expertise, The highest-value prompt engineers are domain experts first. A healthcare analyst who can engineer clinical documentation prompts is worth more than a generic prompt specialist. The skill multiplies domain knowledge; it doesn’t replace it.
⚠ Career Risk
The “no coding required” framing from 2023 is obsolete for any role paying over $90K. Entry-level positions at non-technical companies still exist without code, but AI lab and enterprise engineering roles almost universally require Python and API experience. Plan accordingly.
Salaries: The Honest Numbers
The $335,000 Anthropic listing was real. It was also an outlier at an elite AI safety lab during a period of acute talent scarcity, for a senior specialized role. Using it as a benchmark is like using NBA contracts to estimate what competitive basketball players earn. Here’s the actual range.
Source
Salary Range
Context
ZipRecruiter (June 2025)
$33K – $95K (avg $63K)
Includes contract and part-time; skews low
Glassdoor (via Coursera, Dec 2025)
$90K – $160K (avg $123K)
Full-time tech roles; more representative for career changers
Big Tech (Google, Microsoft, Amazon, Meta)
$110K – $250K
Senior IC and staff-level roles; equity separate
AI Labs (OpenAI, Anthropic, Cohere)
$150K – $335K+
Equity-heavy; total comp often exceeds base significantly
Government / Consulting (Booz Allen)
Up to $212K
Cleared roles; lower equity but high stability
The signal worth watching: Forward Deployed Engineers (FDEs) are where the highest-demand adjacent hiring is concentrating right now. OpenAI formalized its FDE program at scale on May 11, 2026, these are hybrid engineering and client-facing practitioners who embed with enterprise customers to deploy AI in production. Job postings for FDEs reportedly grew 800%+ in 2025. If you’re building prompt engineering skills and want a clear career target, FDE is the most concrete emerging track.
Best Courses and Certifications in 2026
No industry-standard certification equivalent to AWS or PMP exists in this field yet. Expert consensus is consistent: a portfolio of real AI applications outweighs any certificate. That said, one recognized credential on a resume does open doors, it signals fluency to hiring managers who don’t know how else to screen for it.
Course
Provider
Cost
Credibility Signal
ChatGPT Prompt Engineering for Developers
DeepLearning.AI (Andrew Ng + Isa Fulford)
Free, ~90 min
Highest technical credibility among engineering hiring managers
Prompting Essentials
Google Cloud Skills Boost
Paid (Credly badge issued)
HR-recognizable; Google brand carries weight in enterprise
Prompt Engineering for ChatGPT
Vanderbilt / Coursera
~$49 certificate, ~18 hours
University-backed; more respected by non-technical HR
AI Prompt Engineering Series
IBM
Varies
Enterprise-credible brand; useful for Fortune 500 applications
Azure OpenAI Prompt Engineering
Microsoft Learn
Free
Best for roles targeting Microsoft Copilot ecosystem
Best strategy: Complete one certificate from a recognized platform (DeepLearning.AI for technical roles; Google for enterprise roles). Then build a GitHub repository with three to five real LLM application examples, prompt chains, evaluation scripts, RAG pipelines. The portfolio is what gets you the interview. The certificate is what gets you past the keyword filter.
Step-by-Step Career Roadmap
This is for three distinct readers: developers who want to integrate AI into existing work, career switchers approaching this from a non-technical background, and engineering leaders building team capabilities. The path diverges early.
For Developers
Start with the DeepLearning.AI course, 90 minutes, free, co-taught by Andrew Ng and Isa Fulford. It’s the closest thing to canonical teaching the field has, and engineering hiring managers recognize it. Do it this week.
Build with the APIs directly, Sign up for OpenAI and Anthropic developer accounts. Write scripts. Chain prompts. Build a small RAG prototype using your own documents. The tactile experience is irreplaceable.
Learn to evaluate, not just generate, The hardest part of prompt engineering at production scale isn’t writing good prompts; it’s detecting when they fail. Build an eval suite for your prompts. Measure output quality. This is what separates junior from senior practitioners.
Move toward context engineering, The field is converging on “context engineering”, managing what information enters the model’s input window at runtime. This is the next layer above basic prompting. Study LangChain, agent frameworks, and retrieval architecture.
Target FDE or LLM Engineer roles, These titles are where serious engineering-grade prompt work is actually happening and where compensation reflects the skill level.
For Career Switchers (Non-Technical)
The pure “prompt engineer” title pivot carries real risk. The correct framing is not “become a prompt engineer” but rather “add prompting capability to your domain expertise.” A healthcare writer who can engineer clinical documentation prompts is far more valuable than a generic prompt specialist with no domain background. The skill multiplies; it doesn’t substitute.
Identify your domain expertise first. That’s your differentiator.
Take the Google Prompting Essentials or Vanderbilt/Coursera certificate, HR-recognizable and accessible without technical prerequisites.
Build domain-specific examples: if you’re in finance, build a portfolio of prompts that automate financial reporting tasks. If you’re in healthcare, build clinical documentation workflows.
Target titles like AI Trainer, AI Integration Specialist, Applied AI Analyst, these are where standalone prompt-adjacent hiring is actually occurring in 2026, not under the “Prompt Engineer” label.
The Webmaster Analogy
In the mid-1990s, “Webmaster” was a defined, specialized, high-paying role. Within a decade, web skills were distributed across designers, developers, content managers, and marketers, the title disappeared but the skills proliferated. Prompt engineering is following an identical trajectory on a compressed timeline. This isn’t a reason to avoid the skill. It’s a reason to acquire it before it becomes a baseline expectation rather than a differentiator.
The Future: Context Engineering Is What Comes Next
The practitioners who are most valuable in 2026 aren’t optimizing individual prompts, they’re designing the full information pipeline that feeds AI systems at runtime. This is context engineering: the discipline of systematically managing what information gets included in a model’s input window, in what form, and in what order.
The progression looks like this: basic prompting → structured prompt design → RAG architecture → context engineering → LLM evaluation systems. The further right you sit on that spectrum, the more durable your value and the higher your compensation ceiling.
Two dynamics are compressing this timeline. First, models are improving fast, GPT-4 and its successors already self-refine outputs more capably than GPT-3.5. By 2027, routine prompt iteration for common tasks may be largely automated. What remains valuable is strategic prompt architecture: system design, evaluation framework design, and context pipeline engineering. Second, OpenAI’s formalization of its Forward Deployed Engineer program in May 2026 signals that the highest-leverage prompt-adjacent work is becoming institutionalized as a distinct engineering discipline, not a standalone role, but a specialization within software engineering.
Stanford’s 2025 AI Index, analyzing over 51,000 job posting websites, found that 1.8% of all U.S. job postings now require AI skills, up from 1.4% in 2023. That trajectory doesn’t stop. The question is whether you’re building the deeper skills before they become the expectation.
Frequently Asked Questions
What does a prompt engineer do?
A prompt engineer designs, tests, and refines text instructions given to AI language models like ChatGPT, Claude, and Gemini. They craft inputs that guide models toward accurate, useful, and consistent outputs across applications from customer service automation to code generation and content creation. The role combines linguistics, systems thinking, and iterative testing, not creative guessing.
Do you need to know how to code to become a prompt engineer?
Basic prompt engineering doesn’t require coding. However, senior roles increasingly require Python for API integration, evaluation scripting, and RAG pipeline design. Entry-level positions at non-technical companies rarely require code; AI lab and enterprise engineering roles almost always do. The “no coding required” framing from 2023 is effectively obsolete for roles paying above $90K.
How much does a prompt engineer earn?
U.S. salaries range from roughly $63,000 (ZipRecruiter national average, including contract roles) to $123,000 (Glassdoor average for full-time tech positions). Senior roles at major AI companies reach $250,000 and above in total compensation. Anthropic’s widely reported outlier listing reached $335,000, but that was a senior, specialized role at an elite AI lab during a period of acute talent scarcity. It is not a typical benchmark.
Is prompt engineering a good career in 2026?
The skill is highly valuable; the standalone job title has underperformed expectations. Prompt engineering is most powerful as a capability layer added to existing domain expertise, a software developer, healthcare analyst, or marketing strategist who prompts effectively commands a premium. As a standalone career pivot with no domain background, the path is significantly narrower than 2023 coverage suggested.
What are the best certifications for prompt engineering?
The most employer-recognized options are Google’s Prompting Essentials (issues a Credly badge, HR-recognizable), Vanderbilt/Coursera’s Prompt Engineering for ChatGPT (university-backed, roughly 18 hours), and DeepLearning.AI’s course with Andrew Ng and Isa Fulford (highest technical credibility among engineering hiring managers). No industry-standard certification equivalent to AWS or PMP exists yet. A portfolio of real projects matters more than any single certificate.
What is the future of prompt engineering?
The standalone job title will continue shrinking. The underlying skill, systematically designing and evaluating AI inputs, is becoming embedded across software engineering, data science, product management, and operations roles. The highest-growth adjacent area is context engineering and LLM evaluation frameworks, where practitioners design the full information pipeline feeding AI systems at runtime. That’s where the durable, high-value work is concentrating.
What You Now Know That Most People Don’t
The prompt engineering story isn’t boom or bust. It’s transformation. The job title peaked in April 2023 and didn’t recover. The skill is being absorbed into every technical role that touches AI, which is rapidly becoming every technical role, full stop. The workers capturing value are the ones who stopped waiting for a “Prompt Engineer” posting and started building the capability into whatever they already do.
Three things to watch and act on in the next 6–18 months:
The Forward Deployed Engineer track is formalizing fast, OpenAI’s May 2026 program announcement is the clearest signal of where prompt-adjacent work is going at scale
Context engineering is the next layer, start learning RAG architecture and LLM evaluation frameworks before they become baseline expectations
Model updates will devalue model-specific prompt knowledge, build technique fluency, not platform-specific tricks
Machine Learning Engineer Salary in 2026: Google, Meta, and OpenAI vs. Everyone Else
NeuralWired Research·May 2026·14 min read·Salary & Careers
A machine learning engineer at Meta’s E6 level cleared $786,000 in total compensation last year. An entry-level ML engineer at a mid-market company in Dallas earned $69,000. Both carry the same job title. This is the central problem with every ML engineer salary article you’ve read, they average those two people together, then tell you the result means something.
The machine learning engineer salary in 2026 isn’t a number. It’s a range so wide it makes the average nearly useless. What you actually need to know is which part of that range you’re in, what moves you between tiers, and what the market looks like beyond the FAANG-heavy data that dominates the conversation. That’s what this article delivers.
$161K
Average US base salary (Glassdoor, May 2026)
$265K
Median total comp at top-tier tech (Levels.fyi)
3.2:1
Open ML roles vs. qualified candidates
56%
Wage premium for AI skills globally (PwC 2025)
The Real Numbers | By Source, Not By Average
Every major salary database is measuring a different population. Before you benchmark against any figure, you need to know who that figure actually describes. Here’s what each source is actually telling you:
Source
Figure (US, 2026)
What It Actually Measures
Glassdoor
$161,030 avg base; up to $248,375 at 90th pct
Self-reported, delayed, skews toward large employers
Built In
$162,080 base; $212,022 total comp
Verified tech-industry responses; most common bracket $200K–$210K
ZipRecruiter
$128,769 average; $101.5K–$155K (25th–75th pct)
Broader job market including non-tier-1 employers
Levels.fyi
$265,000 median total comp
Primarily FAANG and top-tier tech — equity-heavy, not representative of full market
PayScale
$125,000 avg base
Broadest employer mix; includes many non-tech-industry ML roles
Robert Half
$170,750 midpoint; 4.1% annual growth
Hiring manager surveys; reliable for mid-market enterprise
Why This Range Exists
The $40,000 spread between ZipRecruiter and Levels.fyi isn’t a measurement error, it’s a structural reality. One database captures a Series B startup in Austin; the other captures a staff engineer at Google. They’re different jobs with the same title. Any article that gives you a single average number without this context is wasting your time.
Entry level is a separate market entirely. Entry-level ML engineers in the US average $69,362 as of May 2026, with the majority earning $51,500–$78,500. The headline $200K+ figures are for engineers with three to seven years of production deployment experience. Not bootcamp graduates. Not new master’s program completers.
Google, Meta, OpenAI: What the Data Actually Shows
If you want the ceiling, Levels.fyi’s verified compensation data from May 2026 is the place to look. But interpret these numbers as the top end of the market, not the market itself.
Company
Entry Level
Senior/Principal
Median Total Comp
Meta
$187K (E3)
$786K (E6)
$450,000
Google
$199K (L3)
$743K (L7)
$290,000
Google (AI Engineer title)
$183K (L3)
$583K (L6)
$280,000
OpenAI (L5 SWE)
$1.15M total: $336K base + $774K stock/year
Frontier lab; not industry-representative
OpenAI’s compensation figures deserve a separate sentence: they are not a market benchmark. They reflect the economics of a frontier AI lab during a capital-intensive arms race, the same conditions that produce $300 million in equity grants for a handful of researchers. Anthropic operates in the same tier. These numbers are real; they’re just not what a hiring manager at a healthtech company or a Series C startup is competing against.
“The salary conversations in this discipline are harder than most because the gap between base salary and total comp is enormous at the senior end, and because ‘ML engineer’ means different things at different companies. Someone building recommendation systems at a Series D startup and someone fine-tuning foundation models at Meta are both called ML engineers. They’re not doing the same job. They’re not paid the same either.”
— Robert, Co-Founder & Strategic Advisor, KORE1 (ML Engineer Salary Guide, May 2026)
Which Skills Move the Needle (With Dollar Figures)
The single most actionable finding from 2026 salary data: specialization has a larger salary impact than switching companies, changing cities, or earning an additional degree. Here’s the breakdown from Signify Technology’s 2025–2026 US Market Benchmarks:
Skill / Specialization
Premium Over Base
Dollar Range
Generative AI / LLM Fine-tuning
+40%–60%
+$56,000–$110,000
MLOps Expertise
+25%–40%
+$35,000–$74,000
NLP
+20%–35%
+$28,000–$64,000
PyTorch Proficiency
+8%–12%
+$10,000–$22,000
RAG architecture, retrieval-augmented generation, deserves specific mention because KORE1’s placement data shows it triggering negotiating power in a way that generic “AI experience” doesn’t. One placement example from their May 2026 guide: a healthcare AI engineer moving to fintech negotiated a $22K base increase specifically because she had built a production RAG system processing 400,000 clinical documents. That’s not a hypothetical. That’s a closed deal.
The premium compounds with seniority. Levels.fyi’s Q3 2025 analysis found that entry-level AI engineers earn 6.2% more than non-AI peers, but staff engineers earn 18.7% more. Investing in AI specialization early isn’t a one-time bump; it’s a multiplier that widens as you advance.
“The biggest mistake in 2026 is hiring a PhD researcher when you actually need a software engineer who knows how to deploy a model reliably to production. The highest ML Engineer salaries are no longer going to those who can theorize about AI. They are going to those who can ship AI products reliably.”
— Optiveum, specialist ML recruitment (April 2026)
The Credential Debate | What the Data Actually Shows
There’s a narrative circulating that portfolio beats degree, and it’s partially true. For applied engineering roles, deploying pipelines, building RAG systems, productionizing models, hiring managers at most non-research firms have deprioritized formal degrees. The PwC 2025 data found employer demand for formal degrees falling 9 percentage points for AI-exposed jobs between 2019 and 2024.
But the counterpoint matters: the percentage of job postings mentioning PhDs jumped over 6% year-over-year in 2026, while postings requiring master’s and bachelor’s degrees dropped. At the frontier research tier, the roles with the highest ceilings, academic credentials are becoming more important, not less. The “just ship things” premium applies to applied engineers; research scientists and those aiming for foundation model labs face a different calculus.
The Global Gap: US vs. UK, Canada, Australia
The US salary differential isn’t narrowing. For ML engineers outside the US, this is one of the most financially consequential career facts of the decade.
Market
Average ML Salary (USD equiv.)
Source
United States
$161,000–$186,000 base; $212K–$265K total
Glassdoor / Levels.fyi, May 2026
United Kingdom
~$97,000 (£76,198)
Indeed UK, May 2026
Canada
~$129,850
Qubit Labs, 2026
Australia
~$91,000 (AUD $137,500 avg)
Glassdoor AU, May 2026 (183 submissions)
Switzerland
~$160,300
Qubit Labs, 2026 — leads Western Europe
A senior ML engineer in the UK earns roughly £76K–£120K, or $100K–$155K USD equivalent. The same profile in the US commands $180K–$300K+ total comp. That gap, roughly double, has one practical implication for UK, Canadian, and Australian engineers: remote-first US employers are one of the only pathways to access US-scale compensation without relocating. It’s not a small opportunity; it’s a career-defining one for engineers who pursue it deliberately.
Why Salaries Are This High | And the Risks That Could Change That
The ML salary premium has a structural explanation, not just a hype explanation. Understanding the difference matters for anyone making a multi-year career bet.
The Supply Problem
There are approximately 1.6 million open AI/ML positions and only around 518,000 qualified candidates, a 3.2-to-1 demand-to-supply ratio. That’s not a hiring freeze number; that’s the ratio driving upward pressure on compensation. The ML market is projected to reach $503.4 billion by 2030, up from $113.1 billion in 2025. Demand for ML talent is growing faster than universities can produce it, and the gap between “completed an ML course” and “can deploy and maintain a production LLM pipeline” is enormous. That gap is where the compensation premium lives.
PwC’s 2025 Global AI Jobs Barometer, the largest study of its kind, based on analysis of close to one billion job ads across six continents, found that workers with AI skills command a 56% wage premium over equivalent roles that don’t require AI skills, across every industry analyzed. That premium was 25% the year prior.
“In contrast to worries that AI could cause sharp reductions in the number of jobs available, this year’s findings show jobs are growing in virtually every type of AI-exposed occupation, including highly automatable ones. Even if they can pay the premium required to attract talent with AI skills, those skills can quickly become out of date without investment in the systems to help the workforce learn.”
— Joe Atkinson, Global Chief AI Officer, PwC (PwC Press Release, June 2025)
Meanwhile, ML engineering is growing while general software engineering contracts. AI/ML job postings were up 59% from the pre-pandemic baseline in July 2025 (Indeed Hiring Lab), while general software engineering positions were down 49%. The “tech layoffs” and “ML demand” headlines are describing different talent pools. They are not contradictory.
The Risks | Two Worth Taking Seriously
Contrarian Signal
Glassdoor’s 2026 data shows ML engineers as the only category with a year-over-year salary decrease, down approximately $10,000 from early 2025. The 365 Data Science analysis that surfaced this finding correctly notes Glassdoor’s methodology limitations (self-reported, delayed, subject to sampling bias), but the signal shouldn’t be dismissed entirely. Our read: this likely reflects early normalization in generalist ML roles while LLM and GenAI specialists continue to see premiums. It’s not evidence of a crash, but it’s a reason not to assume unlimited upward trajectory.
The second risk is structural: the 2021 SaaS hiring bubble inflated headcount on speculative valuations, then deflated hard. The prompt engineering “hype cycle” saw purported salaries of $250K–$300K briefly circulate before it became clear most of those roles required significant ML background, not just clever prompting. If AI productivity gains don’t materialize at the expected rate for enterprises, the frenzy driving compensation above market-clearing levels could correct. It’s a real scenario. The difference from 2021, as Pin’s Q3 2025 analysis notes, is that productivity growth in AI-exposed industries has nearly quadrupled since 2022, providing an economic foundation the SaaS bubble never had.
What This Means for Your Career Right Now
If You’re an Active ML Engineer
The most valuable move available to you in 2026 isn’t switching companies, though that’s worth $30K–$60K on average. It’s building demonstrable production deployment experience in LLMs or RAG architecture, which is worth $20K–$40K in base premium over 12 months. Internal promotions consistently lag the job-switching premium, which means that if you’ve built something real, the market will pay you more for it than your current employer will.
If You’re Making a Career Switch Into ML
The share of AI/ML engineering roles in overall tech hiring grew from 10% in 2023 to over 50% in 2025. But don’t benchmark against $200K+ headline figures, those are for engineers with three to seven years of production experience. Entry-level in this field averages $69,362. The path to senior compensation is real, but it runs through shipping things, not just studying them. Portfolio work and production deployments now outweigh degrees for most hiring decisions at non-research firms.
If You’re Hiring
AI/ML job postings increased 89% in the first half of 2025. Seventy percent of firms report a lack of applicants as their primary hiring hurdle. Firms that fail to adjust compensation benchmarks are losing candidates within 48 hours of an offer. One tactical lever that’s underused: contract-to-perm structures. Permanent base salaries for senior ML engineers sit at $175K–$240K; contract day rates for the same level run $800–$1,200/day. Engineers who won’t engage on a traditional permanent posting sometimes will on a project-based structure. That’s not a salary hack, it’s a pipeline access strategy.
Frequently Asked Questions
What is the average machine learning engineer salary in 2026?
In 2026, the average ML engineer base salary in the US ranges from $128,000 to $186,000, depending on the source and employer population measured. Total compensation including equity and bonuses averages $212,022 (Built In) to $265,000 (Levels.fyi). Senior engineers at top tech companies, Meta, Google, OpenAI — can exceed $400,000–$786,000 in total comp.
How much do machine learning engineers make at Google and Meta?
At Google, ML engineer total compensation ranges from $199K (junior, L3) to $743K (principal, L7), with a median of $290K. At Meta, the range is $187K (E3) to $786K (E6), with a median of $450K. Both figures include base salary, stock grants, and annual bonuses, per Levels.fyi updated May 2026.
Do machine learning engineers make more than software engineers?
Yes, by a significant margin. The BLS median for software developers is $133,080. ML engineers average $161K–$186K base in the same market. At the staff/principal level, the AI premium reaches 18.7% over non-AI peers. Specialists in LLM fine-tuning earn 40–60% above baseline ML salaries.
What machine learning skills pay the most in 2026?
LLM fine-tuning commands the highest premium: 40–60% above base ML salaries ($56K–$110K additional). MLOps expertise adds 25–40% ($35K–$74K). NLP adds 20–35%. Generative AI and RAG architecture are the fastest-rising skills. ML Research Scientists command the highest ceiling, averaging $226,353, with top labs offering $550K+ total comp.
What is the machine learning engineer salary in the UK vs. USA?
The gap is stark. UK ML engineers average £76,198/year (~$97K USD), per Indeed UK (May 2026, 811 salaries). In the US, the average is $161K–$186K base, roughly double the UK figure. Senior US roles at FAANG clear $300K–$700K+ total comp. Switzerland leads Europe at ~$160K USD. Canada averages ~$130K USD.
Is machine learning engineering a good career in 2026?
By most metrics, yes. The BLS projects 26% job growth for the closest occupational category through 2034; data scientists are the 4th fastest-growing occupation in the US economy. AI/ML postings were up 163% year-over-year in 2025. Demand outstrips supply 3.2:1. The two real risks: skill obsolescence as the field evolves rapidly, and role-title inflation that makes it harder to signal genuine expertise.
What You Now Know That Most People Don’t
The ML engineer salary story in 2026 isn’t “AI pays well.” That’s a headline. The real story is about structure: a market where the average is nearly meaningless without context, where the gap between a generalist and an LLM specialist is $56K–$110K, where the US salary is roughly double the UK’s, and where the supply-demand imbalance isn’t a hype cycle, it’s a documented 3.2:1 ratio that’s been consistent for multiple years.
The forward implication for the next 6–18 months: the era of “any ML experience commands a premium” is ending. The era of “demonstrable production experience in specific high-value skills” is in full effect. Engineers with provable LLM fine-tuning and RAG deployments will continue to see premiums. Generalist ML engineers who haven’t specialized, particularly those without frontier model experience, may find the Glassdoor salary decline data more predictive than the Levels.fyi headline numbers.
Three things to watch:
Credential inflation at research labs. PhD demand in ML job postings jumped 6% in 2026. If you’re targeting frontier labs, the academic track matters more than the “just ship it” narrative suggests.
Remote-first US employer expansion. The US/UK and US/Australia salary gaps are the single biggest financial arbitrage opportunity for international ML engineers. Watch for US companies formalizing remote hiring for senior roles.
The productivity ROI test. Enterprise AI spending is enormous. If it doesn’t produce measurable productivity returns at scale through 2025–2026, the hiring frenzy that’s inflating mid-market ML salaries could correct. The signal to watch: Fortune 500 renewal rates on AI contracts.
Stay ahead of the market.
The Neural Loop delivers the most important AI and tech career signals every week, without the noise. Read by ML engineers, hiring managers, and investors who track this field seriously.
Subscribe to The Neural Loop →
AI hallucinations cost global enterprises an estimated $67.4 billion in 2024. Not from science fiction scenarios. From real production systems confidently generating wrong information, fabricated citations, and invented facts, all delivered with the tone of certainty. And 47% of enterprise AI users made at least one major business decision based on hallucinated content that same year, according to Deloitte’s 2026 AI adoption survey.
The headline numbers from model vendors are misleading. Yes, GPT-4o hallucinates just 0.7% of the time on general knowledge summarization benchmarks. But legal AI tools hallucinate on 17–34% of real legal queries. Medical AI reaches 64% hallucination rates on clinical cases without mitigation. And the Stanford AI Index 2026 reports hallucination rates ranging from 22% to 94% across 26 leading LLMs on complex reasoning tasks. The gap between benchmark and production is not a rounding error. It’s an operational hazard.
This guide gives engineering and security leaders the complete picture: what AI hallucination actually is at the model level, why it gets dramatically worse in agentic AI systems, how to measure it in your production environment, and the proven 3-layer mitigation stack that reduces rates by over 85% when properly implemented. This is the article your model vendor doesn’t want you to read before signing a procurement contract.
What AI Hallucination Actually Is | Beyond the Buzzword
The Technical Reality Most Explainers Skip
LLMs do not retrieve facts. They predict the most statistically probable next token based on patterns absorbed from training data. Hallucination is not a bug in the traditional software sense, it is an inherent property of probabilistic text generation. A 2025 mathematical proof confirmed that hallucinations are structurally inevitable under current LLM architectures. Retrieval-augmented generation and human-in-the-loop review reduce them. Neither eliminates them.
That framing matters for enterprise planning. The question is not whether your deployed model hallucinates. It does. The question is how much it hallucinates in the specific domain, on the specific query types, under the specific conditions you’ve deployed it in, and what you’ve built to catch it before it affects a decision.
The Four Hallucination Types
Type
Description
Example
Detection Difficulty
Factual
States something verifiably false as true
Wrong court case dates, fabricated statistics
Moderate — verifiable against external sources
Citation
Invents a source or attributes claims to the wrong source
A journal article that doesn’t exist
Moderate — link checking catches most
Reasoning
Individual facts are correct but the logical chain is invalid
“Revenue grew 20%, costs grew 15%, so margins expanded”, not necessarily true
High — everything looks right until the conclusion
Instruction
Model ignores or partially follows a prompt constraint
Generates content outside specified boundaries
Low to moderate — output review catches it
Factual hallucinations were present in 8–12% of queries in 2024. Top models have pushed general-knowledge factual error rates down to 0.3–0.7%, but rates spike sharply on obscure topics and recent events. Citation hallucinations remain in 30%+ of chatbot-generated answers in research contexts. Reasoning hallucinations are the hardest to catch because the output looks internally coherent.
Why Benchmark Numbers Don’t Reflect Production Reality
The Vectara HHEM Leaderboard measures grounded hallucination: how often a model fabricates facts when summarizing a document it was explicitly given. Top models score below 1% here. Production enterprise AI rarely works on clean single-document summarization. Real enterprise queries involve multi-document retrieval, complex reasoning chains, recent events, and domain-specific knowledge, all conditions where hallucination rates multiply 10–50x above benchmark levels.
The Stanford AI Index 2026 puts the range bluntly: 22% to 94% across 26 leading LLMs on complex tasks. That range is not model variance, it is the gap between what models are benchmarked on and what enterprises actually ask them to do.
The Entropy Gap: Why Creativity and Accuracy Trade Off
Based on Shannon’s information entropy, low entropy produces high accuracy with limited novelty. High entropy produces creative but often false answers. When users push models toward nuanced analysis or edge-case advice, they push models toward higher entropy, and higher hallucination risk. This is the core tension in enterprise AI deployment, and no prompt can fully resolve it. It has to be managed at the architecture level.
Why Hallucination Is Far Worse in Agentic AI Than in Copilots
The Compounding Effect No One Models
A copilot hallucinates once per user interaction, and a human reads the output before acting. An AI agent hallucinates once per step in a multi-step reasoning chain, and acts before a human sees the output. Gartner’s March 2026 research puts agentic workflows at 10–20 LLM calls per task. If each call carries a 2% hallucination rate, a 15-step agent chain has a 26% probability of at least one hallucination affecting the final output, before compounding effects from hallucinations feeding into subsequent steps.
Multi-turn conversational agents show hallucination rates of up to 35% during extended interactions. That’s not a benchmark quirk, it’s what happens when context accumulates, retrieval gaps appear, and the model starts predicting forward from its own earlier (potentially flawed) outputs rather than from grounded source material. This is the stat that should make every engineering lead re-examine their agentic AI production failures retrospective.
When Hallucination Becomes an Unauthorized Action
When agents hallucinate, they don’t just return wrong text. They can make unauthorized API calls, misroute data, trigger incorrect workflows, or delete the wrong records. The Stanford AI Index 2026 specifically flags this: in agentic systems, hallucinations can lead to unauthorized API calls or data leaks. That is categorically different from a copilot hallucination, which a human can catch and discard. An agent hallucination may be irreversible before anyone sees the output.
This is not a theoretical risk. Production agentic systems in finance and legal workflows are triggering real downstream consequences from planning-stage hallucinations. The architecture has to account for this.
Role Separation: The Right Architectural Response
The most effective architectural control for agentic hallucination is role separation. One model plans the actions. A separate deterministic script or monitor model validates the plan against an allowlist of permitted actions before execution. This prevents a planning hallucination from becoming an execution error. It’s the same principle as a four-eyes approval process, except it runs in milliseconds.
For high-stakes agents in security, finance, or healthcare, the complementary principle is “fail-closed”: if the model’s confidence or grounding score falls below a defined threshold, the system escalates to a human analyst rather than proceeding. This is the architectural equivalent of a circuit breaker. Agents designed to fail open, continuing with low-confidence outputs rather than halting, are production liabilities waiting for the right query to expose them.
Hallucination Rates by Domain: Where Your Enterprise Risk Actually Lives
The table below is the insight most enterprise AI conversations skip. Hallucination is not a model property, it is a domain × deployment × mitigation property. The same GPT-4o that hallucinates 0.7% on summarization benchmarks produces hallucinated legal citations in 17–34% of legal research queries. Model selection alone cannot solve this. Architecture and mitigation layers must.
Domain / Use Case
Hallucination Rate
Risk Level
Key Finding
General summarization
0.7–1.8% (top models)
Low
Vectara HHEM Leaderboard 2026, benchmark conditions only
Enterprise chatbots (live production)
~18%
Medium-High
Real production rates far exceed benchmark numbers
Medical / Clinical AI
43–64% without mitigation
Critical
MedRxiv 2025: drops to 23% with structured mitigation prompts
Stanford: RAG reduces but doesn’t eliminate; retrieval failures persist
Product recommendation AI
Up to 25% accuracy impact
Medium
UC San Diego 2026: AI summaries hallucinated in 60% of tested scenarios
Legal and medical are the clearest danger zones. In legal, the Stanford RegLab/HAI study remains the definitive benchmark: LLMs hallucinate between 69% and 88% of the time on specific legal queries. Researcher Damien Charlotin maintains a database of 120+ court cases where AI-hallucinated quotes, fabricated cases, or fake legal citations were discovered. In legal, hallucination is synonymous with malpractice risk, full stop.
In medical, ECRI listed AI risks as the #1 health technology hazard for 2025. Without mitigation prompts, hallucination rates on clinical cases reach 64.1% on long cases and 67.6% on short cases, according to the MedRxiv 2025 study of 300 physician-validated vignettes. Even at the best-case rate of 23% with full mitigation applied, nearly 1 in 4 medical AI responses contains fabricated information. These are not acceptable residual rates without mandatory physician review on every clinical output.
How to Measure Hallucination Rate in Your Production System
The Measurement Gap Most Teams Don’t Know They Have
91% of enterprises have implemented explicit hallucination mitigation protocols. Far fewer measure actual hallucination rates in production. Without measurement, mitigation is guesswork. Most teams implement RAG and assume the problem is solved. Stanford research shows RAG-powered legal tools still hallucinate 17–33% of the time. Organizations implementing RAG without measuring outcomes are deploying production AI systems they cannot describe, audit, or improve.
The Four RAG Evaluation Metrics Every ML Team Must Track
Metric
What It Measures
What Low Scores Signal
Context Precision
Does the retrieved chunk actually contain the answer?
Retriever is surfacing irrelevant content
Context Recall
Did the retriever find all necessary information?
Model is forced to fill gaps, hallucination risk rises sharply
Faithfulness
Is the answer derived only from the provided context?
Primary hallucination signal in RAG systems
Answer Relevance
Does the response address what was actually asked?
Off-topic generation that can mask hallucinated content
Production Monitoring Tools in 2026
The market for AI hallucination detection tools grew 318% between 2023 and 2025. The tooling has matured to the point where every production enterprise AI system can and should have continuous hallucination monitoring. The leading platforms: Braintrust for real-time monitoring and automated regression testing; Galileo for scalable model-driven evaluations at high output volumes; Fiddler for explainability and compliance-focused evaluation with governance integration; Arize AI for real-time monitoring with drift detection.
The LLM-as-judge pattern is now a production standard: a more capable, accurate model, Claude Sonnet or GPT-4o, evaluates the output of a faster, cheaper model for factual grounding and instruction following. Self-consistency checking, sampling 3–5 responses and comparing for agreement, catches a significant share of remaining hallucinations at low additional cost. Both patterns give teams a practical alternative to human review at scale.
Hallucination Measurement Starter Checklist
If your team can’t answer all six of these questions, you don’t yet have production-grade hallucination visibility:
What is our baseline hallucination rate in our target deployment domain, measured in production, not taken from a vendor benchmark?
Which of the four RAG evaluation metrics do we track continuously, and what are our current scores?
What is our post-mitigation hallucination rate, and when was it last measured?
What are the specific query types or topics where our system shows elevated hallucination risk?
At what confidence or grounding score does our system escalate output to human review rather than proceeding autonomously?
Have we had any documented hallucination-caused production errors, and are they tracked in an incident log?
The 3-Layer Mitigation Stack That Reduces Hallucination by 85%+
Three complementary layers, each additive. Used together, research supports a combined reduction of 85–92% in domain-specific enterprise hallucination rates for properly implemented stacks. This transforms AI hallucination mitigation from “inherent unfixable problem” to “manageable engineering challenge with known solutions.”
The simplest and cheapest intervention. Effective prompt constraints include: “Only answer based on the provided context,” “If uncertain, say you don’t know,” and “Cite the specific source passage for each claim.” A 2025 Nature study confirmed prompt-based mitigation reduces hallucinations by approximately 22 percentage points on medical tasks. That’s a meaningful reduction for near-zero implementation cost.
The ceiling is real, though. LLMs don’t reliably follow instructions when statistical pressure to generate a confident response is high, particularly on topics where the model has strong training signal. Prompt engineering is Layer 1, not a standalone solution. Teams that treat it as sufficient are relying on the model to police itself.
The most impactful single technical intervention available. RAG shifts the model from recalling facts from training data, unreliable, unauditable, to synthesizing information from provided documents. Across 847 production deployments, RAG produced a median 71% hallucination reduction, with a range of 58–89% depending on retrieval corpus quality and chunking strategy, according to February 2026 enterprise vendor consortium data.
Key implementation requirements: a comprehensive retrieval index, accurate chunking, sufficient context window to hold retrieved content, and regular index freshness maintenance. Stale retrieval indexes are a hidden hallucination accelerant, when the index doesn’t contain current information, the model defaults to training-data prediction, bypassing the entire grounding mechanism. This is the most common RAG implementation failure in production.
Post-generation verification catches errors that RAG misses. A verification API checks each claim against external sources after generation. Self-consistency checking, sampling 3–5 responses and comparing, adds approximately 65% reduction in residual hallucinations. LLM-as-judge evaluation provides scalable automated review at production volumes.
For regulated industries, finance, healthcare, legal, a human-in-the-loop review layer remains mandatory for high-stakes outputs. It should be the fourth line of defense, not the first. Organizations that rely on human review as their primary hallucination control are paying $14,200 per AI-using employee per year in verification overhead, according to Forrester Research. That’s 4.3 hours per week of pure fact-checking time. The 3-layer stack eliminates most of that cost and shifts human review to the residual edge cases where it actually belongs.
“The question isn’t whether large language models hallucinate, they do, by design. The question is whether your organization has built the architecture to catch and contain hallucinations before they reach decision-makers. Most enterprises haven’t.”Percy Liang, Director, Center for Research on Foundation Models, Stanford University — Stanford AI Index 2026
Industry-Specific Risk Levels and Mitigation Requirements
Healthcare: The Highest Stakes, the Widest Gap
Without mitigation prompts, hallucination rates on clinical cases reach 64.1% on long cases and 67.6% on short cases, per the MedRxiv 2025 study across 300 physician-validated vignettes. With structured mitigation prompts, rates drop to 43.1% and 45.3%, a meaningful 33% reduction. But even at the best-in-class rate of 23% with full mitigation, nearly 1 in 4 medical AI responses contains fabricated information. ECRI named AI risks the #1 health technology hazard for 2025.
Mitigation requirement: Full 3-layer stack plus mandatory physician review for any clinical output, with source citation required for every claim. Any clinical AI system that proceeds without human sign-off on a threshold basis is not compliant with ECRI guidance, and is a liability exposure waiting for a patient outcome to make it a headline.
Legal: Hallucination Is Malpractice Risk
The Stanford RegLab/HAI study is unambiguous: LLMs hallucinate between 69% and 88% of the time on specific legal queries. Even with retrieval augmentation, Lexis+ AI hallucinated in 17% of cases and Westlaw AI-Assisted Research in 34% in 2026. Researcher Damien Charlotin’s database has documented 120+ court cases where AI-hallucinated quotes, fabricated cases, or fake citations were discovered.
Mitigation requirement: Mandatory source disclosure and provenance logging, every LLM legal claim must link to a verified source document. No exceptions for speed or volume. A hallucinated legal citation is not a minor error; it is a professional conduct risk for the attorney who relied on it.
Finance: The Reasoning Hallucination Problem
Reasoning hallucinations are the dominant risk in financial analysis. The model may cite correct facts but produce an invalid logical inference. OpenAI’s o3 reasoning model, widely used for financial analysis, hallucinated 33% of the time on PersonQA benchmarks, double its predecessor. More processing power, more hallucination on open-ended reasoning tasks. Don’t assume a newer model is a safer model until you’ve benchmarked it in your specific deployment context.
Mitigation requirement: Dual-model validation. One model generates. A second model stress-tests the logical chain before the output is used. Output validation must check not just factual accuracy but logical validity, the reasoning hallucination won’t appear wrong until someone follows the chain to its flawed conclusion.
Security and Threat Intelligence: Design for Failure
A hallucinated vulnerability assessment or threat intelligence report can waste hundreds of analyst-hours and create false confidence in defenses. For security AI, the fail-closed principle is non-negotiable: if the confidence score falls below a defined threshold, escalate to a human analyst. Never return a low-confidence threat assessment as if it were confirmed intelligence. The cost of a false negative in security, a missed real threat, far exceeds the cost of a false positive that sends an analyst to verify.
The Cost Anchor That Should Drive Every Procurement Conversation
Global business losses from AI hallucinations reached $67.4 billion in 2024. Enterprises spend an average of $14,200 per AI-using employee per year in hallucination verification overhead, equivalent to 4.3 hours per week of pure fact-checking time. For a 500-person AI-enabled workforce, that’s $7.1 million annually just checking AI’s homework. The 3-layer mitigation stack eliminates most of that cost. Its implementation cost, at any enterprise scale, is a fraction of the overhead it removes.
Building a “Hallucination Datasheet” for Every AI System in Production
What a Hallucination Datasheet Is
A hallucination datasheet is a standardized internal document that profiles the hallucination behavior of each AI system deployed in production: domain-specific rates, known failure modes, measurement methodology, active mitigation layers, and residual risk after mitigation. Leading AI governance controls teams now maintain these as part of their AI registry. It makes hallucination risk visible, comparable, and auditable, the three properties that regulators and enterprise procurement teams will increasingly demand.
The Seven-Field Hallucination Datasheet Template
Field
What to Document
1. Baseline hallucination rate
Measured in target domain in production, not vendor benchmark
2. Active mitigation layers
Which of prompt engineering / RAG / output validation are implemented
3. Post-mitigation hallucination rate
Measured in production after all mitigation layers are applied
4. Known failure modes
Specific query types, topics, or conditions with elevated hallucination risk
5. HITL threshold
Confidence or grounding score below which output requires human review
6. Last measurement date and review cadence
When rates were last measured and how frequently they’re reassessed
7. Incident history
Any documented hallucination-caused errors in production, dates, impacts, resolutions
The Regulatory Case for Doing This Now
Under EU AI Act Article 13, users of high-risk AI must ensure that users understand the system’s capabilities and limitations. A hallucination datasheet is the most direct way to document known limitations in a format regulators, auditors, and enterprise procurement teams can evaluate. Organizations that maintain these documents can demonstrate due diligence in a way that ad-hoc governance cannot.
“Transparency about AI system limitations, including hallucination rates and failure modes, is not optional under the EU AI Act for high-risk applications. It is a documentation requirement with enforcement consequences.”Luca Bertuzzi, AI Policy Correspondent, MLex Media — EU AI Act Compliance Analysis, 2026
Teams that integrate hallucination datasheets into their AI registry now are building the audit trail that procurement reviews and regulatory audits will require in 2027. Teams that don’t are creating a documentation gap that gets expensive to close retroactively.
The Future of Hallucination: Will It Ever Be Solved?
The Structural Constraint That Won’t Go Away
The 2025 mathematical proof is clear: hallucinations are structurally inevitable under existing LLM architectures. They are an emergent property of probabilistic text prediction. Analysis of Hugging Face leaderboard data suggests that zero hallucinations would require models with roughly 10 trillion parameters, a scale not expected before approximately 2027. For enterprise planning purposes, treat hallucination mitigation as a permanent operational discipline, not a problem the next model update will solve.
The Counterintuitive Trend: Better Reasoning, More Hallucination
OpenAI’s o3 reasoning model hallucinated 33% of the time on PersonQA benchmarks, double its predecessor o1. o4-mini reached 48% on person-specific questions. The most sophisticated reasoning models push into higher entropy generation, creating a direct trade-off between reasoning depth and factual accuracy on open-ended queries. Enterprise teams deploying reasoning models for complex financial or legal analysis should benchmark hallucination rates specifically in their deployment domain. Don’t assume newer means more reliable, in reasoning tasks, the evidence currently suggests the opposite.
The 2026 Direction: From Mitigation to Architecture
The frontier of hallucination management is moving from post-generation mitigation to generation-time architecture. “Guarded Generation” patterns, pre-retrieval validation, constrained generation, post-generation verification, are becoming standard in production LLM engineering. The goal is not to prevent hallucination in the model. That’s not achievable at current scales. The goal is to catch and contain it before it reaches enterprise decision-making.
The organizations that will lead on AI reliability through 2026 and beyond are not those that found a hallucination-free model. No such model exists at useful enterprise scale. They are the organizations that built layered mitigation architectures, measured production hallucination rates continuously, and integrated hallucination governance into their enterprise AI reliability strategy and incident response plans. That is the practical definition of production-grade enterprise AI, and it’s an engineering discipline, not a vendor promise.
Frequently Asked Questions
What is AI hallucination and why does it happen in enterprise applications?
AI hallucination occurs when a language model generates information that is factually incorrect, fabricated, or logically invalid, delivered with the same confident tone as accurate output. It happens because LLMs predict the most statistically probable next token based on training data patterns, not factual retrieval. It is structurally inherent to probabilistic generation under current architectures, confirmed by a 2025 mathematical proof, and rates are significantly higher in enterprise production environments than vendor benchmarks suggest.
How much do AI hallucinations cost enterprises financially?
Global business losses from AI hallucinations reached $67.4 billion in 2024, according to a comprehensive AllAboutAI study. Per enterprise employee, organizations spend approximately $14,200 annually in hallucination verification overhead, equivalent to 4.3 hours per week of fact-checking time, per Forrester Research. For a 500-person AI-enabled workforce, that equates to $7.1 million annually in pure verification cost before any downstream error costs are counted.
Does RAG eliminate AI hallucinations completely?
No. RAG significantly reduces hallucinations but cannot eliminate them. Across 847 production deployments, RAG produced a median 71% hallucination reduction, with a range of 58–89% depending on retrieval corpus quality and chunking strategy. However, Stanford researchers found that RAG-powered legal AI tools still hallucinate in 17–33% of queries due to retrieval failures and gaps in the retrieval corpus. RAG should be the foundation of a 3-layer mitigation stack, not a standalone solution.
What are hallucination rates for the best AI models in 2026?
On grounded summarization benchmarks, top models achieve below 1% hallucination rates, GPT-4o and Claude 3.5 Sonnet both score around 0.7–0.8% on the Vectara HHEM Leaderboard. Production rates are dramatically higher: approximately 18% in live enterprise chatbot interactions, 17–34% in legal AI tools, 43–64% in medical AI without mitigation, and 22–94% across 26 models on complex reasoning tasks per the Stanford AI Index 2026.
How do you measure AI hallucination rate in a production system?
Track the four RAG evaluation metrics, Context Precision, Context Recall, Faithfulness, and Answer Relevance, using monitoring tools like Braintrust, Galileo, or Arize AI for continuous production tracking. Implement LLM-as-judge evaluation for scalable automated review. Set a baseline hallucination rate before mitigation is applied, then measure post-mitigation rates on a continuous basis. The current industry improvement trend is approximately a 3-point annual decline in hallucination rate for teams actively measuring and iterating.
Why is hallucination worse in AI agents than in standard chatbots?
Agentic AI workflows trigger 10–20 LLM calls per task, according to Gartner’s March 2026 research. With each call carrying even a modest hallucination probability, the compound probability of at least one hallucination affecting a multi-step chain rises dramatically, and agents act before human review occurs. Multi-turn agents show hallucination rates up to 35% during extended interactions. A chatbot hallucination is caught by the human reader; an agent hallucination may trigger an unauthorized API call, misroute data, or take an irreversible action before anyone sees the output.
How do I reduce LLM hallucination rates in a regulated industry like healthcare or finance?
Regulated industries require the full 3-layer mitigation stack, prompt constraints, RAG implementation, and post-generation output validation, plus mandatory human-in-the-loop review above a defined confidence threshold. Healthcare deployments should require physician sign-off on all clinical outputs and source citation for every claim, given hallucination rates of 43–64% without mitigation. Finance deployments should implement dual-model validation where a second model stress-tests the logical chain before output is used, specifically to catch reasoning hallucinations.
What is a hallucination datasheet and does my team need one?
A hallucination datasheet is a standardized internal document profiling the hallucination behavior of a specific AI system in production: baseline rate, active mitigation layers, post-mitigation rate, known failure modes, human review thresholds, and incident history. EU AI Act Article 13 requires that users of high-risk AI understand system limitations, a hallucination datasheet is the most auditable way to document this. Any enterprise running AI in legal, medical, financial, or security contexts should maintain one for every production deployment.
Artificial IntelligencePublished: May 15, 2026 · Updated: May 2026
How to Measure AI ROI in Enterprise: The Framework CFOs and CTOs Actually Agree On (2026)
Only 25% of enterprise AI initiatives delivered their expected ROI in 2025, yet budgets keep growing. Here’s the measurement framework that closes the gap between engineering logic and P&L reality.
Only 25% of enterprise AI initiatives delivered their expected ROI in 2025, according to IBM’s CEO Study. Yet global AI spending surpassed $301 billion in 2026, and 65% of enterprises increased their AI budgets year-over-year. The math doesn’t add up, and it’s because most organizations are measuring AI ROI the wrong way.
The problem isn’t the technology. CTOs are building business cases in the language of engineering while CFOs think in the language of P&L. This guide gives you the framework that closes that gap: a 3-layer ROI model, a full cost accounting checklist of variables most teams undercount, and a ready-to-use ROI scorecard you can bring into your next budget review.
Why Most AI ROI Calculations Fail: The Vanity Metric Trap
Only 47% of IT leaders said their AI projects were profitable in 2024. A further 33% broke even, and 14% recorded outright losses, according to an IBM-commissioned report from 2025. Boards keep approving AI budgets anyway, because the ROI numbers they’re seeing are built on pilot economics, not production reality.
The root cause is a reliance on four vanity metrics that inflate AI ROI on paper without producing anything verifiable on the P&L. These are: time-saved-per-employee projections that never get audited against actual output, accuracy improvement percentages disconnected from any revenue figure, user adoption numbers that count logins rather than business outcomes, and model benchmark scores that measure lab performance against real-world deployment complexity.
The credibility gap is wide. Only 51% of organizations said they could confidently evaluate the ROI of their AI spend, according to the CloudZero State of AI Costs 2025, even as average monthly AI spend reached $62,964 per month. The gap between spending confidence and measurement confidence is where most AI investment goes to die.
“Organizations that account for technical debt in their AI business cases project 29% higher ROI than those that don’t. That single discipline explains most of the performance gap between AI winners and losers.”
IBM Institute for Business Value, CEO Study 2025 — ibm.com
That 29% gap from technical debt accounting alone tells you everything. The AI projects that never reach production almost universally share one trait: they were greenlit on pilot economics and then surprised their sponsors with production costs nobody had modeled.
The 3 ROI Layers: Efficiency, Revenue Impact, and Strategic Value
Most enterprise AI ROI frameworks collapse everything into a single number. That’s the wrong structure. There are three distinct layers of return, each with a different measurement timeline, owner, and ceiling. Conflating them is how you end up with a CFO who thinks the AI program is underperforming and a CTO who thinks it’s working fine. They’re measuring different things.
Competitive positioning, talent attraction, data asset accumulation, capabilities unlocked for future initiatives
24+ months
CEO / Board
Layer 1: Efficiency ROI
This is the fastest and most measurable layer. It includes cost per task reduction, headcount reallocation, error rate reduction, and processing speed gains. According to Deloitte’s 2026 State of AI report, surveying 3,235 business leaders, 66% of organizations report productivity and efficiency gains from AI. This is where most enterprise AI ROI lives today, and it’s the only layer most CFOs ever see.
Layer 2: Revenue Impact ROI
This layer is harder to measure but carries a significantly higher ceiling. It covers faster time-to-market, improved customer retention, upsell and cross-sell from AI personalization, and revenue recovered through churn prediction. Deloitte found that 74% of organizations aim to grow revenue through AI, but only 20% are already doing so. That gap is a measurement problem, not a technology one. Teams that don’t define revenue attribution before deployment never close it.
Layer 3: Strategic Value ROI
This is the most important and least measured layer. It includes competitive positioning, talent attraction, data asset accumulation, and optionality: the capabilities unlocked for future initiatives that don’t exist yet. McKinsey’s AI high performers, the 6% of enterprises where 5% or more of EBIT is attributable to AI, invest in this layer intentionally. Most organizations treat it as an afterthought.
Cross-study meta-analysis from MasterOfCode (2026) finds that visionary AI adopters show 1.7x revenue growth, 3.6x three-year total shareholder return, and 2.7x return on invested capital versus laggards. That performance spread is the 3-layer ROI model working as designed: efficiency funding the case, revenue expanding it, and strategic value compounding it.
How to Calculate Time-to-Value for an AI Initiative
Time-to-Value (TTV) and payback period are not the same thing, and most enterprise AI teams conflate them in ways that produce wildly optimistic board presentations. TTV is the time from project approval to the first measurable business impact. Payback period is the time until cumulative returns exceed total investment. Both matter. Confusing them skews your planning horizon by months.
The TTV Formula
TTV = Development Time + Integration Time + Change Management Time + Stabilization Period. Each phase carries hidden time costs that teams routinely underestimate, particularly change management, which pilots consistently treat as a rounding error.
The industry median for AI agent deployments is 5.1 months from approval to first measurable business impact, based on BCG and Forrester 2026 surveys. But that median masks significant variation by function. Sales and SDR agents pay back in 3.4 months. Finance and operations agents average 8.9 months. If your team is planning a finance automation initiative with a 4-month payback model, the benchmarks say you’re off by more than half.
The Three TTV Killers
🗄️
Data Readiness
Data preparation consumes 30–50% of AI project budget and time. It’s the single most underestimated phase in every enterprise AI business case.
🔗
Integration Complexity
60% of enterprises name legacy system integration as their top AI challenge (Deloitte 2026). The API layer looks simple in the architecture diagram. It never is in production.
👥
Adoption Lag
The human change curve that pilots always ignore. Users resist new workflows regardless of tool quality. Change management is not a soft cost; it’s a hard timeline driver.
Forrester data shows 44% of AI projects that move to production achieve positive ROI within 12 months. That number sounds encouraging until you flip it: 56% of production AI deployments take longer than 12 months to reach positive ROI, or never do. Proper TTV planning is the difference between being in the 44% and explaining to the board why you’re in the 56%.
Cost Variables CTOs Always Undercount
Companies underestimate total AI costs by 30% or more, according to analysis from the Ramsey Theory Group published in April 2026. The hidden costs tied to inference at scale, data engineering, model monitoring, and continuous retraining now surpass initial model development costs in most production AI systems. The business case looks clean at approval. The invoice looks very different 18 months later.
Operating cost exceeds build cost within 18–24 months in many production AI systems. Hidden costs add 30–50% beyond initial estimates across multiple independent analyses. This is not an edge case. It’s the default outcome for teams that treat AI like a capital project rather than a permanent operating expense line.
Hidden Cost 1: Inference at Scale
A support assistant handling 50,000 conversations per month at $0.01 per turn costs $5,000 per month. Add multi-step reasoning and retrieval-augmented generation and that number multiplies. Enterprise LLM inference costs run $5,000 to $50,000 per month at production scale, per CloudZero’s State of AI Costs report. The critical detail most AI ROI models miss: agentic workflows trigger 10–20 LLM calls per user task versus one call for a standard chatbot, according to Gartner’s March 2026 analysis. If your business case was built on chatbot-level consumption economics, your actual inference bill will arrive as a shock.
This is where hybrid cloud AI cost strategy becomes a practical requirement rather than an architectural preference. Teams that model inference costs at agentic call volumes before deployment avoid the budget revision conversation entirely.
Hidden Cost 2: Model Retraining
Budget $15,000 to $40,000 per year for a moderately complex model running quarterly retraining cycles. Most initial business cases budget exactly $0 for this line item. Annual AI maintenance runs 15–25% of the initial build cost and should be treated as a permanent operating expense, not a one-time project cost. That framing matters for how the CFO categorizes it: CapEx at approval, OpEx forever after.
Hidden Cost 3: Data Pipeline Maintenance
Continuous data ingestion, cleansing, and labeling don’t stop when the model goes live. Enterprise AI projects add $500 to $3,000 per month in data infrastructure costs that don’t appear in initial estimates. When you combine this with the 30–50% of project budget that data preparation consumed during build, data is easily the largest single cost category in any AI initiative over a three-year horizon.
Hidden Cost 4: Human-in-the-Loop Operations
High-stakes AI deployments in legal, medical, and customer-facing contexts require human review workflows. The cost of building, staffing, and managing these pipelines is real and almost never in the initial estimate. Teams that skip this step don’t avoid the cost. They discover it during a compliance review or a customer escalation, at which point the retrofit bill is higher.
Hidden Cost 5: MLOps Retrofit
Teams that skip monitoring deploy blind. Emergency remediation and retroactive MLOps build costs $40,000 to $100,000, which is more than the cost of implementing monitoring correctly from the start, according to Azilen’s 2026 analysis. This cost category doesn’t appear in the P&L until something breaks. It then appears all at once.
“The shift to agentic AI workflows changes the cost calculus entirely. A task that triggered one LLM call as a chatbot now triggers 10–20 calls as an agent. Most enterprise ROI models weren’t built for that volume.”
Gartner, March 2026 Agentic AI Cost Analysis
The CFO Conversation: Translating AI Metrics into P&L Language
CTOs speak in tokens, latency, accuracy, and model size. CFOs speak in EBIT margin, payback period, net present value, and OpEx versus CapEx. These are different languages, and most AI initiatives die in the translation. The technology works. The business case doesn’t survive the budget review.
The board pressure signal is already shifting the dynamic. CFOs are now killing more AI projects than CTOs launch, according to Solutions Review’s Enterprise AI Predictions for 2026. The era of approving AI spend on future potential is over. CFOs now require P&L impact in quarters, not years. If your CTO can’t speak that language, the initiative won’t get funded, regardless of how good the model is.
The Translation Table: CTO Metrics to CFO Equivalents