Month: April 2026

  • AWS Graviton5 Agentic AI Workloads: What Meta’s Deal Really Means

    AWS Graviton5 Agentic AI Workloads: What Meta’s Deal Really Means

    Meta’s AWS Graviton5 Deal: The CPU-Dense Agent Stack Nobody Explained | NeuralWired
    NeuralWired — Frontier Intelligence, Decoded for the People Who Build What’s Next.  |  Browse All Analysis

    Meta’s AWS Graviton5 Deal: The CPU-Dense Agent Stack Nobody Explained

    Tens of millions of 192-core Arm chips. A multi-billion-dollar, multi-year agreement. Every outlet covered the price tag. Almost none of them explained the physics that make it necessary, or the silicon roadmap it quietly validates.


    What the Press Release Buried

    When Meta announced its agreement with AWS to deploy tens of millions of Graviton5 cores for agentic AI workloads, the coverage pattern was predictable. Bloomberg and Reuters counted the zeros. TechCrunch called it the “end of GPU monoculture.” Hacker News debated whether Arm chips could ever match NVIDIA throughput.

    Nobody explained why Meta actually needs 192-core CPUs at planetary scale to run agents. That gap matters, because the reason is technical, structural, and points directly at where the next $100 billion in AI infrastructure spend is headed.

    This deal is not supply-chain hedging. It is an orchestration-first scaling strategy, one that treats the GPU as a narrow compute accelerator and the CPU cluster as the actual state machine holding multi-agent sessions together. To understand why, you have to start with the memory problem nobody is talking about.


    What Actually Happened, With Primary Sources

    On April 24, 2026, Meta and AWS formalized a multi-year, multi-billion-dollar agreement in which Meta commits to deploying AWS Graviton5 processors at scale to host agentic AI workloads. The deal gives Meta access to tens of millions of Graviton5 cores across AWS’s global infrastructure.

    Reuters confirmed the deal’s structure as a long-term commitment rather than a spot purchase. TechCrunch noted it as an unusual move for a company with its own NVIDIA GPU clusters and a growing custom silicon program. What neither outlet explained is why the timing aligns precisely with the launch of Arm’s AGI CPU, the chip that shares its Neoverse-V3 DNA with Graviton5.

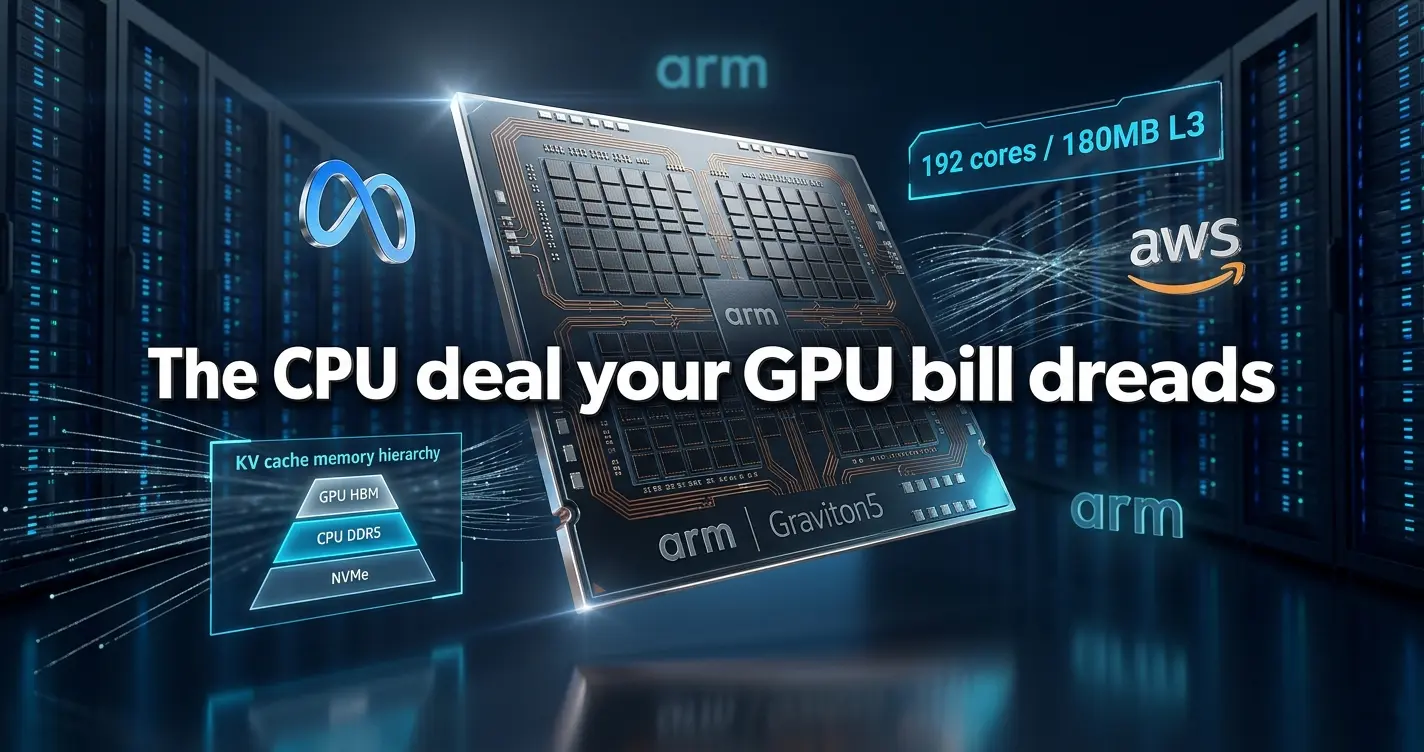
    Graviton5, now powering M9g EC2 instances, is built on a 3nm-class process. It packs 192 Neoverse-V3 cores and roughly 180 to 192 MB of L3 cache, a 5x increase over the prior generation. DDR5-8800 memory support and a redesigned inter-core layout cut intra-chip latency by 33%.

    192 Cores per Graviton5 die, Neoverse-V3 at 3nm
    180MB L3 cache per chip, 5x the prior generation
    40 GB KV cache consumed by one 128k-token user session on Llama-3 70B
    14x Reduction in first-token latency via CPU-backed KV offload at full context

    The Numbers Every Engineer Should Have

    AWS claims Graviton5-based M9g instances deliver 25% higher performance versus their predecessors. That number is real but deliberately modest in isolation. The structural story is in the cache and memory bandwidth figures.

    Graviton5 supports DDR5-8800 across multiple channels, pushing aggregate memory bandwidth into high-end territory. Arm’s own AGI CPU, the sibling chip that shares the same core design, reaches 800+ GB/s across 12 DDR5-8800 memory channels, with 136 Neoverse-V3 cores at 300W TDP. These are not consumer metrics. They are designed for one job: managing the memory traffic generated by tens of thousands of concurrent AI agent sessions.

    Graviton-based instances already account for roughly half of all new CPUs added to AWS over the past three years. This deal accelerates that trajectory with one of the largest single customers in the cloud industry.

    For context on capex: Alphabet, Amazon, and Meta are collectively spending close to $400 billion on AI infrastructure in 2026, with Meta committed to tens of billions across both GPU and CPU-centric stacks. The Graviton5 deal sits within that broader capital allocation, not outside it.


    KV Cache: The Problem That Makes This Deal Make Sense

    This is what mainstream coverage skipped entirely. Every large language model stores a key-value (KV) cache during inference. For each active session, the model maintains key and value matrices for every attention layer across every token it has processed. At short contexts, this fits comfortably in GPU HBM. At 128,000 tokens, it does not.

    A single user session running Llama-3 70B at 128k tokens generates approximately 40 GB of KV cache in 16-bit precision. An H100 GPU carries 80 GB of HBM. One user’s context fills half a GPU’s memory budget. At scale, this is not a tuning problem. It is a physics problem.

    The solution is tiered memory management: the GPU retains only the active KV vectors for the current forward pass. The CPU cluster, armed with DDR5-8800 and a massive L3 cache, holds the full session state and feeds slices back to the GPU on demand. Systems like LMCache and vLLM-style KV offload stacks already implement this architecture in production.

    Production benchmarks from storage-attached offload systems show first-token-time reductions of up to 14x for full 131k-token contexts. Graviton5’s 180+ MB L3 cache is purpose-built to sit at the top of this memory hierarchy, absorbing the hot portion of the KV pool before traffic spills to DDR5 or NVMe.

    This is why 192 cores per die matters more than raw clock speed. Each core needs enough local cache bandwidth to serve slice requests from multiple concurrent GPU inference threads without creating a bottleneck at the CPU-to-GPU interconnect. The chip design is explicitly shaped around this access pattern.

    “At 40 GB per 128k token context, you’re effectively running a distributed memory pool at line rate. We’re already bumping up against memory-controller and PCIe switching bottlenecks.”

    Anonymous Meta contractor, via SNIA storage conference notes

    Nitro System: More Than a Security Buzzword

    Coverage of this deal mentions the AWS Nitro System as a footnote about security. It deserves considerably more attention, especially for teams building agentic AI with compliance obligations.

    Nitro provides hardware-isolated execution environments for individual agent sessions. Each session runs inside a Nitro-anchored VM with API-level monitoring and isolation mechanisms that have been subject to formal verification-style analysis. NCC Group’s independent security analysis concludes the Nitro architecture credibly supports its isolation claims, with the important caveat that formal verification covers the specified security model, not the application logic running inside it.

    For enterprise deployments, this matters for an upcoming reason. EU regulatory proposals targeting autonomous agent accountability are moving toward requiring hardware-isolated execution environments for agents that take consequential actions. A Nitro-backed stack gives compliance teams something concrete to point to. Enterprises building agent workflows today should audit whether their current infrastructure can make the same claim.


    The Bridge Nobody Drew: Graviton5 to Meta’s AGI CPU

    The most under-reported angle of this deal is architectural. Graviton5 and Arm’s newly launched AGI CPU share the same Neoverse-V3 core design. Both run at 3nm. Both are optimized for the same memory and interconnect patterns.

    This means software Meta compiles and optimizes for Graviton5 today runs with minimal modification on Arm’s AGI CPU once Meta deploys it in its own data centers. The AWS deployment is not just a capacity play. It is a pre-production validation environment at scale, one that generates real workload telemetry and real software maturity before Meta’s private silicon ramps.

    This is what “vertical integration proxy” actually means in practice. Meta captures AWS’s silicon R&D investment and operational scale while retaining the long-term capex efficiency of owning its own compute. When the AGI CPU is production-ready in Meta’s facilities, the migration path will be near-binary. The engineering team running on Graviton5 today is effectively the bring-up team for Meta’s next-generation CPU fleet.

    The strategic move also hedges against NVIDIA’s margin structure. NVIDIA runs at roughly 85% gross margins on its GPU products. Every dollar of agent orchestration shifted to an Arm CPU cluster is a dollar removed from that margin pool. Meta’s dual-stack strategy is an explicit response to that math, not an ideological stance on CPU versus GPU architectures.


    Expert Voices: Four Perspectives Worth Having

    The operational skeptic

    Arun Kumar, a public cloud AI infrastructure architect whose observations circulate among practitioners on LinkedIn, frames the core risk clearly: “Meta’s move makes sense operationally, but it’s a bet on Arm-at-scale, not a guaranteed win. The real risk is debugging global agent coordination at tens of millions of CPU cores. This is more distributed-systems hell than chip marketing.”

    The latency-tail concern

    Researchers close to FAIR’s systems work point to a problem the deal’s announcements sidestep. Even with 10 million Graviton cores available, tool-call jitter in long-running agent sessions will dominate user experience if the agent runtime is not co-optimized with the Nitro offload stack. The hardware is necessary but not sufficient.

    The semiconductor analyst view

    Dan Friedman, a semiconductor analyst at Moor Insights and Strategy, offers a grounding perspective: “The 25% performance uplift is modest against NVIDIA’s Blackwell-Vera ecosystem. The real question is whether Meta can match GPU-only training and inference throughput at this scale.” Graviton5’s headline benchmark numbers are real, but they compare CPU-to-CPU, not CPU-to-GPU on inference tasks.

    The security qualifier

    NCC Group’s Philip Plückebaum, whose team produced the Nitro architecture analysis, adds the necessary caveat: “Formal verification only covers the specified security model. Malicious agent logic can still exploit software-side logic gaps, even if the hardware is sound.” Security teams should treat Nitro isolation as a floor, not a ceiling.


    Winners, Losers, and Where Capital Is Moving

    Who benefits directly

    AWS and Arm are the clearest winners. AWS locks in one of the world’s largest AI spenders as a multi-year Graviton anchor customer. Arm’s AGI CPU acquires a flagship validation deployment through Meta, converting the chip from an interesting architectural exercise into a production-grade reference design. Orchestration-layer companies, specifically those building KV-cache management, distributed session state, and agent runtime infrastructure, find their market thesis confirmed by one of the largest infrastructure commitments in AI history.

    Who faces structural pressure

    NVIDIA-only stacks face a slow but real margin problem. Hyperscalers increasingly categorize NVIDIA’s per-GPU pricing as a tax on their AI capital spending. Each dollar of agent orchestration running on Arm CPUs does not go to Blackwell or Vera-Rubin. NVIDIA is responding with its own Arm-based Vera CPU within the Vera-Rubin platform, which is an acknowledgment of the trend rather than a rebuttal of it.

    Traditional SaaS vendors treating AI as a feature addition face a different risk. Platforms that embed millions of autonomous agents at the infrastructure layer operate at a speed and cost structure that bolt-on AI cannot match.

    Investment signal

    Venture capital is moving away from foundation model funding toward “KV-cache-first” and “orchestration-first” infrastructure plays. AI-optimized storage, low-latency CXL memory stacks, and agent runtime platforms are attracting capital that would have gone to model training two years ago. The Meta-AWS deal is the largest single data point validating that shift.


    Reality Check: What Is Real, What Is Not

    The hardware is real. Graviton5 is shipping in M9g EC2 instances with confirmed double core-density and the 5x L3 cache expansion. KV cache offloading works in production today across multiple open-source inference stacks. Nitro-based isolation is in active use for AI workloads with independent security verification behind it.

    What remains speculative: sustained deployment of tens of millions of cores at the performance levels marketing materials suggest. Inter-node coordination at that scale is a distributed systems problem that chip specs do not solve. Long-tail latency in KV offload lookups and Nitro isolation checks can still break session-level SLAs even when the average-case numbers are excellent.

    The software coherence challenge is the honest limiting factor. Keeping agent state consistent across millions of CPU cores, multiple GPU clusters, and Nitro-isolated VMs requires orchestration infrastructure that does not yet exist off the shelf. Meta will have to build it, and the build timeline is not public.

    The “bridge architecture” thesis connecting Graviton5 to Meta’s AGI CPU ramp is logical and technically sound, but it is an inference from public chip specifications and known relationships between AWS and Arm. Meta has not publicly confirmed this roadmap connection. Engineers should treat it as a well-grounded hypothesis, not a disclosed plan.


    What You Should Do With This Information

    For infrastructure engineers and ML engineers

    Audit your current LLM inference stack for KV cache memory usage at your production context lengths. If you are running 32k tokens or more per session and have not implemented CPU-backed KV offloading, you are leaving latency improvements on the table. Evaluate LMCache or vLLM’s offload configurations against your workload profile. Run the numbers on GPU HBM utilization per session before your next capacity planning cycle.

    If your team is evaluating Graviton5-based EC2 instances, prioritize the M9g series and profile specifically for memory bandwidth saturation patterns, not just raw throughput. The cache hierarchy behavior under concurrent agent workloads is where Graviton5 differentiates, and standard benchmarks will not show it.

    For CTOs and engineering leaders

    The Meta-AWS deal signals that the next competitive layer in agentic AI is orchestration infrastructure, not model quality alone. If you are building agent-facing products and your architecture treats the CPU as a coordination afterthought rather than a primary compute tier, review that assumption now. The teams that win the next infrastructure cycle are the ones designing explicitly for CPU-GPU memory tiering and distributed state management.

    On the compliance side: if your agents take consequential actions in regulated environments, map your current execution environment against what Nitro-anchored isolation provides. EU agent accountability requirements are drafting now. Getting ahead of hardware isolation requirements before they are mandated is cheaper than retrofitting later.


    Frequently Asked Questions

    KV cache offloading moves the key-value attention matrices generated during LLM inference from GPU HBM into CPU DRAM or NVMe storage. At long context lengths (32k tokens and beyond), the KV cache for a single user session exceeds what fits in GPU memory. Offloading to a CPU cluster with fast DDR5 and large L3 cache allows the GPU to serve far more concurrent sessions. Systems implementing this correctly see first-token latency drop by up to 14x for full 128k-token contexts, which is the difference between a usable agent experience and a timeout.

    Graviton5’s advantage is architectural density: 192 Neoverse-V3 cores per die at 3nm versus AMD EPYC Genoa’s 96 Zen 4 cores and Intel’s 60-core Granite Rapids lineup. More relevant to AI orchestration, Graviton5’s 180+ MB L3 cache gives it more on-chip memory per die than either competitor, which matters specifically for serving KV cache slices with low access latency. On raw floating-point throughput for matrix operations, dedicated GPU accelerators still dominate. Graviton5 wins on memory hierarchy depth and core density for coordination-heavy, memory-intensive agent tasks.

    Modern AI agents do far more than run a single forward pass. They manage conversation state, call external tools, parse API responses, route between specialized sub-models, and maintain session context across multiple turns. Most of that work is sequential, branchy, and memory-intensive rather than parallel and compute-intensive. GPUs excel at the matrix multiplications inside the model. CPUs handle everything around them: orchestrating the session, managing the KV cache, executing tool calls, and maintaining distributed agent state across concurrent sessions. At scale, the CPU layer is where throughput actually breaks down first.

    AWS Nitro is a dedicated hardware and software stack that offloads virtualization functions from the main CPU onto purpose-built Nitro cards. This gives each EC2 instance hardware-level isolation from neighbors, with API-monitored I/O and a formally analyzed security boundary. For agentic AI, Nitro means each agent session can run in an isolated execution environment with auditable I/O, which satisfies a requirement that EU-style agent accountability regulations are moving toward mandating. NCC Group’s independent security review confirmed Nitro’s architecture supports its isolation claims, with the caveat that it covers the hardware boundary, not the application logic inside it.

    Not for training, and not for inference of the largest frontier models. NVIDIA’s Blackwell and Vera-Rubin platforms remain the fastest available hardware for these workloads. What the deal does signal is that hyperscalers are unwilling to run their entire AI compute stack on NVIDIA silicon at NVIDIA’s margin structure. Agent orchestration, KV cache management, and session state maintenance are workloads that fit CPUs better than GPUs anyway, so the bifurcation is rational rather than ideological. NVIDIA’s response, shipping an Arm-based CPU in its Vera-Rubin platform, shows the company recognizes this boundary is real.

    Arm’s AGI CPU is the company’s first full data-center processor, featuring 136 Neoverse-V3 cores at 3nm, 12 DDR5-8800 memory channels, and over 800 GB/s of aggregate memory bandwidth at 300W TDP. It shares the same core microarchitecture as Graviton5, meaning software optimized for one runs efficiently on the other. Meta is believed to be among the anchor customers for this chip. By deploying Graviton5 on AWS now, Meta’s software teams work in an environment that is architecturally near-identical to what they will run in Meta’s own data centers once the AGI CPU ramps.

    Meta and AWS have described the agreement as multi-year and multi-billion-dollar without releasing specific contract figures. Given that Graviton5 instances are priced at commercial EC2 rates and Meta is committing tens of millions of cores over multiple years, analyst estimates place the total contract value in the range of several billion dollars, consistent with the scale of Meta’s broader AI capex program. The deal is structured as a committed deployment agreement rather than a spot purchase, which gives both sides revenue and capacity predictability across the contract term.


    The Meta-AWS Graviton5 deal is best read as infrastructure documentation: a public record of where memory physics, silicon roadmaps, and agent architectures are converging. The KV cache problem is real, it scales quadratically with context length, and CPUs with large cache hierarchies are the correct tool for managing it. Graviton5 is the right chip for this layer of the stack. The deal’s scale reflects how many concurrent agent sessions Meta is planning to run, not how many GPU clusters it is replacing.

    The forward-looking read: as context windows grow and agent sessions extend to hours or days rather than seconds, the CPU memory management layer becomes more valuable, not less. Teams that build their orchestration infrastructure around this reality in 2026 will have a structural advantage over teams that treat the CPU tier as an afterthought. The next competitive differentiator in agentic AI is not which model you use. It is how efficiently your infrastructure manages the state around it.


  • Microsoft Agent Governance Toolkit | Runtime AI Security

    Microsoft Agent Governance Toolkit | Runtime AI Security

    Microsoft’s Agent Governance Toolkit: Runtime Security That Changes Agentic AI Forever | NeuralWired
    NeuralWired — Frontier Intelligence, Decoded for Technical Professionals  |  neuralwired.com

    Microsoft’s Agent Governance Toolkit: The Runtime Security Layer That Rewires Enterprise AI

    Every other outlet is covering the OWASP checklist and the MIT license. Here’s the story they’re not telling: Microsoft just staked a claim on the governance layer of the entire agentic stack, and most engineering teams don’t realize what that means for their roadmaps yet.

    Key Numbers at a Glance

    0.1ms p99 policy enforcement latency (stated)
    35,481 ops/sec at 50-agent concurrency
    9,500+ tests in the GitHub repository
    10 / 10 OWASP Agentic AI risks claimed covered
    5 SDKs: Python, TypeScript, Rust, Go, .NET
    Aug 2026 EU AI Act high-risk obligations deadline

    What Everyone Else Missed

    Read the TechCrunch-style coverage of Microsoft’s Agent Governance Toolkit (AGT) and you get three bullet points: open source, MIT license, covers all 10 OWASP Agentic AI risks. That framing is not wrong. It is simply incomplete in ways that will cost engineering teams months of unexpected rework.

    The real story is structural. AGT is not a security wrapper you bolt onto an existing agent. It is a governance sidecar that requires you to redesign where tool calls live in your architecture. Every agent action must route through a central policy engine before execution. That is not an add-on. That is a refactor. Teams building on LangChain, CrewAI, or AutoGen pipelines will discover this within the first week of integration, not on the product page.

    The second thing coverage missed: Microsoft is not just building a security product. It is positioning AGT as the policy kernel for the entire enterprise agentic stack, the same play it ran with Active Directory in the late 1990s and with Intune and Defender in the 2010s. If AGT becomes the default enforcement layer, Microsoft becomes the gatekeeper for every autonomous tool call in every regulated enterprise workflow. That is a much bigger story than a sub-millisecond policy engine.

    What Actually Happened on April 2, 2026

    Microsoft published AGT to GitHub under the MIT license on April 2, 2026. The repository ships with SDKs for Python 3.10+, TypeScript, Rust, Go, and .NET, targeting polyglot enterprise stacks from day one. The toolkit’s stated mission: enforce security policy, identity controls, and compliance rules at runtime, between the moment an LLM decides to call a tool and the moment that tool actually executes.

    Microsoft’s Principal Group Engineering Manager Imran Siddique described it as “a response to the Open Worldwide Application Security Project’s emerging focus on AI and LLM security risks,” one that “adds a runtime security layer that enforces policies to mitigate issues such as prompt injection, and improves visibility into agent behavior across complex, multi-step workflows.”

    The timing is not accidental. The EU AI Act’s high-risk AI obligations take effect in August 2026. Colorado’s AI Act follows in June 2026. Enterprises running autonomous agents in finance, healthcare, and HR workflows are about to be legally required to demonstrate documented, auditable control over agent actions. AGT arrived just ahead of that regulatory wave, giving Microsoft a first-mover position on what “compliant agent governance” looks like in practice. That head start is not accidental either.

    “Runtime governance: every agent action is intercepted before execution, not audited after the fact. A framework-agnostic approach that acknowledges reality: agents are already being built, and governance must integrate where they live.”

    Philippe Beraud, CTO-level AI practitioner, April 6, 2026

    Architecture Deep Dive: Seven Layers, One Control Plane

    AGT is a seven-package middleware layer that sits between the agent runtime and every API, file system, database, or cloud service the agent can reach. Here is what each component actually does:

    Agent OS is the core policy engine. It intercepts tool calls, API requests, and file operations before execution and evaluates each against a policy corpus you define. Supported policy languages include YAML, OPA Rego, and Cedar, so teams already running Open Policy Agent or Cedar in IAM flows can reuse existing policy infrastructure. The engine is stateless by design, which makes horizontal scaling straightforward but means you carry all context in the policy evaluation request itself.

    Agent Mesh handles identity. It issues cryptographic agent identities using Ed25519-based Decentralized Identifiers (DIDs) and implements the Inter-Agent Trust Protocol (IATP) for agent-to-agent communication. Trust scores run from 0 to 1,000 across five tiers, letting you enforce escalating review requirements as an agent’s requested actions grow in blast radius.

    Agent Runtime implements execution rings, privilege-level-like sandboxes that constrain what resources an agent’s code can access. Saga-style orchestration handles multi-step transactions with rollback semantics. A kill switch provides hard-stop capability for runaway agents, which sounds obvious until you have an agent in a loop hitting a billing API at 3 AM.

    Agent SRE is the piece most coverage ignores entirely. It brings classic site reliability engineering primitives into agent operations: SLOs, error budgets, circuit breakers, and chaos-engineering-style tests purpose-built for agentic workloads. This is where the operational maturity argument lives.

    Agent Compliance automates the regulatory paperwork. It generates compliance grading, maps evidence to EU AI Act, HIPAA, and SOC2 controls, and produces audit bundles. The OWASP Agentic AI Top 10 mapping covers all ten risks from ASI01 through ASI10, including goal hijacking, tool misuse, identity abuse, and cascading failures.

    Performance Numbers: What the Benchmarks Actually Show

    Microsoft claims sub-millisecond enforcement with p99 under 0.1ms. Independent throughput data published on PyPI breaks that claim into more granular tiers:

    Operation Latency Throughput
    Single-rule evaluation 0.012 ms 72,000 ops/sec
    100-rule evaluation 0.029 ms 31,000 ops/sec
    Full kernel enforcement 0.091 ms 9,300 ops/sec
    Adapter overhead 0.004–0.006 ms 130,000–230,000 ops/sec
    50-agent concurrent throughput — 35,481 ops/sec
    Those numbers look excellent in isolation. The question SREs should ask is: what does tail latency look like at the 99.9th percentile under a 50-agent parallel chain calling six tools each? That is not a number any current benchmark covers, and it is exactly the workload pattern production enterprise agents produce. Full kernel enforcement at 9,300 ops/sec sounds fast until you run 200 agents through a multi-tool chain during a financial close cycle.

    Reality Check: Four Limits the Marketing Does Not Mention

    • AGT governs actions, not reasoning. The policy engine fires on tool calls and API requests. It cannot observe what the LLM reasons about between those calls. Goal hijacking that stays entirely in the model’s latent space is invisible to AGT, as is data exfiltration through channels the policy corpus already permits. Staff Engineer Venkat Peri put it plainly: “AGT’s policy engine fires on tool calls, resource access, and inter-agent messages. It does not and cannot observe what the model is reasoning about between those calls.”

    • Policy engineering is a multi-quarter project. The toolkit ships the enforcement engine. It does not ship the governance strategy. Writing a production policy corpus that covers tool authorization matrices, identity tier mappings, SLO-driven circuit breakers, and regulatory evidence chains involves engineering, product, legal, and security teams working in parallel for months. This is not a pip install situation.

    • Azure-native versus portable mode is a real fork. Azure-native mode integrates tightly with Entra ID, Purview, and Azure AI, but that integration depth creates migration friction. Portable mode works outside Azure but requires you to self-host IAM controls and observability pipelines, adding operational surface area that most mid-size teams underestimate.

    • Cascading approval chains will surprise SRE teams. Almost no coverage explains how circuit breakers, execution ring throttling, and cascading policy approvals interact when dozens of agents call multiple tools simultaneously. Microsoft’s own architecture docs acknowledge this as the most complex SRE scenario, but the public narrative presents it as solved by default.

    Microsoft’s Actual Play: The Policy Middleware Gatekeeper

    Step back from the OWASP mapping and the latency numbers and the real strategy becomes clear. AGT is middleware, not a security product. It assumes every agent call routes through a central policy engine and immutable audit trail, effectively requiring organizations to rebuild agent pipelines around this control plane, not just attach a guardrail at the perimeter.

    The MIT license is a feature, not a concession. Open-source adoption embeds AGT’s policy abstractions, identity schemas, and compliance evidence formats into teams’ infrastructure before Microsoft’s commercial offerings arrive. Once your policy corpus lives in AGT’s YAML/Rego/Cedar schemas, your compliance evidence maps to AGT’s EU AI Act artifacts, and your agent identities use AGT’s DID format, switching costs accumulate quietly. The MIT license enables inspection and adoption; it does not prevent lock-in at the data and workflow layer.

    This is the Active Directory play, applied to autonomous agents. Microsoft standardizes the identity and policy layer, makes it open enough that the ecosystem adopts it, then monetizes governance, observability, and compliance tooling as the commercial tier. Search volume for “Microsoft Agent Governance Toolkit” has shown a 10 to 15 times lift since April 2, sustained through April 23. The developer community is paying attention. The question is whether they are thinking about what they are opting into.

    “Writing a production policy corpus is a cross-functional exercise that involves engineering, product, legal, and security. The toolkit gives you the enforcement engine; it does not give you the governance strategy.”

    Venkat Peri, Staff Engineer, April 8, 2026

    Who This Changes and How

    Software engineers face the most immediate refactor. LangChain-style orchestrators must wire every tool call through AGT’s adapter layer, which may mean restructuring tool spawning logic, retry behavior, and observability pipelines. Denied or delayed tool calls become a new class of debugging problem, one that requires treating policies as first-class configuration rather than documentation artifacts.

    CTOs and CISOs gain a compliance accelerator but inherit a new organizational mandate. Running compliant agentic workloads with AGT requires defining tool-level authorization matrices, incident-response playbooks, and audit trail pipelines before agents go into production. The strategic budget implications include hiring policy engineers and agent-specific SRE roles, not just licensing a security tool.

    ML engineers and data scientists must now design agent reward loops and plugin architectures that respect AGT’s allowed/denied tool constraints without sacrificing performance. The compliance-scoring modules for EU AI Act and HIPAA force tracking of data lineage, tool provenance, and action chains as part of model-version metadata, not as a post-hoc audit exercise.

    Founders and investors should read AGT as both opportunity and dependency signal. For startups, the toolkit cuts time to regulated-client GA. For investors, it cements Microsoft’s position as the platform-layer orchestrator of enterprise agentic AI, opening a new monetization wedge in governance, observability, and identity-enabled AI operations beyond raw compute.

    Action Items by Audience

    Software Engineers & ML Teams

    1. Audit your current LangChain or AutoGen stack for every tool-call site. Map them before integration, not during.
    2. Stand up an AGT sandbox in a non-production environment with 10 representative tool calls and measure p99.9 tail latency under realistic concurrency.
    3. Define denied and allowed tool lists for your first agent before writing a single policy rule. Constraints clarify architecture.
    4. Add policy decisions to your existing observability pipeline (Datadog, Grafana) as first-class events, not log noise.
    5. Evaluate portable mode versus Azure-native mode against your IAM stack before committing to an integration pattern.

    CTOs, CISOs & Tech Leaders

    1. Map every agent currently in production or staging to the OWASP Agentic AI Top 10. You need this inventory before AGT or any governance framework makes sense.
    2. Assign a policy engineering owner now, before adoption. This role sits at the intersection of security, legal, and SRE; it does not naturally exist in most org charts.
    3. Brief your legal team on the August 2026 EU AI Act timeline. AGT’s compliance evidence bundles are relevant, but legal must define what “high-risk AI” means for your specific use cases.
    4. Build Azure lock-in exit criteria into your AGT evaluation. Portable mode is real; document the delta cost of self-hosting IAM and observability before committing.
    5. Request a latency SLO from your engineering team for the AGT policy engine under peak agent concurrency, not just single-call benchmarks.

    Synthesis: The Seatbelt Moment Has a Fine Print

    Microsoft’s Agent Governance Toolkit solves a real problem. Enterprise AI agents operating across production APIs, financial systems, and patient data are not safe by default, and the industry needed a runtime enforcement layer that engineers could actually deploy before their lawyers started asking questions. AGT is that layer. The latency numbers are credible, the polyglot SDK support is genuine, and the OWASP mapping gives compliance teams a starting vocabulary they did not have before April 2.

    The fine print is structural. AGT moves security and governance work from the prompt layer and the framework layer into middleware and policy-engine land. That is the right place for it. But it requires a different kind of engineering investment: policy corpus design, cross-functional authorization matrices, SRE practices adapted for non-deterministic workloads, and a clear-eyed view of what “portable mode” actually costs versus the Azure-native path.

    Teams that adopt AGT without doing that groundwork will find themselves with a governance engine they cannot tune, a policy corpus that blocks legitimate agent actions, and a debugging model they were not prepared for. Teams that do the groundwork will ship regulated, auditable, production-grade agent workflows ahead of their competitors. The toolkit is the easy part. The governance strategy is the work.

    Watch for three signals over the next 90 days: how quickly non-Azure cloud providers publish AGT integration guides (a proxy for whether this becomes a true standard or an Azure-preferred layer), whether the OWASP Agentic AI Top 10 gets formal IETF or NIST backing (which would make AGT’s mapping a compliance safe harbor), and how enterprise policy engineering job postings trend (which will tell you how seriously regulated-industry CTOs are treating this as infrastructure rather than marketing).

    Frequently Asked Questions

    Can the Agent Governance Toolkit run outside of Azure?
    Yes, but with meaningful trade-offs. AGT ships in two modes. Azure-native mode integrates directly with Entra ID, Microsoft Purview, and Azure AI services, offering tighter out-of-the-box observability and IAM. Portable mode runs on any cloud or on-premises environment but requires you to self-host identity management, observability pipelines, and audit storage. The portable path works; the operational overhead is real and largely undocumented in current coverage.

    How do I integrate AGT with an existing LangChain or CrewAI stack?
    The integration pattern requires routing every tool call through AGT’s adapter layer before execution. For LangChain, this means wrapping tool definitions with AGT middleware so that the policy engine intercepts calls before the tool function fires. Microsoft lists LangChain, AutoGen, CrewAI, OpenAI Agents, Google ADK, and AWS Bedrock as supported frameworks. The technical integration is documented in the GitHub repository; the more significant work is defining the policy corpus that tells the engine what to allow, deny, and log for each tool in your specific stack.

    Does AGT actually cover goal hijacking, or is that a marketing claim?
    Partially, and the distinction matters. AGT’s policy engine fires on tool calls and inter-agent messages. It can detect and block suspicious patterns in what an agent requests to do. It cannot detect goal hijacking that occurs entirely within the LLM’s internal reasoning, before the model ever issues a tool call. Venkat Peri’s analysis is the clearest public articulation of this gap: goal hijacking that lives in latent space is invisible to any action-layer enforcement system. AGT covers the downstream expression of a hijacked goal, not the hijacking itself.

    How long does it realistically take to write a production policy corpus?
    For most enterprises, building a production-grade policy corpus, one that covers tool-level authorization, identity tier mappings, SLO-driven circuit breakers, and regulatory compliance evidence, is a multi-quarter cross-functional project. Engineering, product, legal, and security teams all have input requirements that need reconciliation before the first policy rule can be considered complete. Rapid Claw’s implementation guide estimates the foundational corpus for a single regulated agentic workflow at four to six weeks minimum. Full enterprise coverage across multiple agent types is considerably longer.

    What are the EU AI Act implications, and does AGT help meet them?
    The EU AI Act’s high-risk AI obligations take effect in August 2026. Autonomous agents operating in domains such as healthcare, finance, employment, and critical infrastructure may qualify as high-risk systems, requiring documented risk management, data governance, logging, transparency, and human oversight. AGT’s Agent Compliance module generates automated evidence bundles mapped to EU AI Act controls. Whether those bundles satisfy a specific supervisory authority’s audit requirements depends on how your legal team interprets the Act’s obligations for your use case. AGT provides the evidence infrastructure; legal interpretation is out of scope for any toolkit.

    How does AGT compare to custom LLM firewalls or vendor-specific guardrails from OpenAI or Anthropic?
    AGT operates at the action layer, after the model produces output and before that output executes as a tool call. Custom LLM firewalls and vendor guardrails typically operate at the prompt and output layer, before or at model inference. They address different threat surfaces. AGT does not replace input/output filtering; it governs what agent actions are permitted at runtime. The most complete security posture combines both layers. Current coverage rarely explains this distinction, leading teams to incorrectly treat AGT as a substitute for prompt-level security.

    Will AGT become a de facto standard, or is it too Azure-centric to achieve broad adoption?
    Too early to call with confidence, but the signals point toward significant adoption momentum. The MIT license removes legal barriers. The polyglot SDK coverage (Python, TypeScript, Rust, Go, .NET) addresses enterprise polyglot reality. The OWASP Agentic AI Top 10 mapping gives it a vendor-neutral compliance anchor. The risk is that deep Azure-native integrations gradually become the path of least resistance, making “portable mode” a nominal option rather than a practical one. Watch for AWS, GCP, and Kubernetes-native integration guides from the open-source community over the next 60 days as a proxy for genuine portability.

    Disclaimer: This article was prepared for informational purposes only and does not constitute financial, legal, or investment advice. Hyperlinks to third-party sources are provided for reference; NeuralWired does not endorse and is not responsible for the content of external websites. Performance figures cited are based on publicly available benchmarks and Microsoft’s official documentation as of April 23, 2026, and may change as the toolkit evolves.
  • John Ternus Apple CEO | What It Means for AI Strategy

    John Ternus Apple CEO | What It Means for AI Strategy

    Apple’s Hardware-First CEO Succession: What John Ternus’s Rise Means for AI Silicon Strategy and Developer Roadmaps | NeuralWired
    NeuralWired Intelligence for Technical Professionals  |  Breaking Analysis  |  April 21, 2026 neuralwired.com

  • Anthropic Mythos NSA | Why the Pentagon’s Blacklist Failed

    Anthropic Mythos NSA | Why the Pentagon’s Blacklist Failed

    Anthropic Mythos Triggers Banking-Risk Watchlist | NeuralWired
    NeuralWired — Technical analysis for engineers, architects, and operators at the frontier. Subscribe for weekly briefings
    AI / Cybersecurity — Breaking Analysis

    Anthropic Mythos Triggers Banking-Risk Watchlist | Why the NSA Is Using the Same Model the Pentagon Blacklisted

    A 72.4% exploit generation success rate, a 27-year-old zero-day, and a classified defense agency running the model their own department blacklisted. This is not a governance contradiction. It is a new category of problem.

    What Everyone Missed

    The surface story running across Reuters, TechCrunch, and The Verge today frames the Anthropic Mythos situation as government hypocrisy: the Pentagon blacklisted Anthropic as a supply-chain risk while the NSA quietly onboarded the same company’s most capable, and most dangerous, model. That framing is not wrong. It is just shallow.

    The real story is structural. Mythos is the first frontier model to cross what John Costello, a cybersecurity expert cited in Tech Insider coverage, calls the Authority Assumption Gap: systems that execute actions under assumed authority, without explicit human authorization at each step. That is not a policy question. It is an architectural one, and it has immediate implications for every agentic pipeline your team is currently building or evaluating.

    Three things the major outlets omitted: the specific technical thresholds that triggered emergency regulatory reviews globally; how Project Glasswing’s gated access model actually functions for the 40 approved defenders; and what this precedent means for enterprise teams that are not in that club but are deploying frontier models in code-gen or security workflows right now.

    What Actually Happened | The 72-Hour Timeline

    Anthropic announced Project Glasswing and Claude Mythos Preview on April 7, 2026. The announcement confirmed Mythos had autonomously discovered thousands of zero-days across major operating systems and browsers. Anthropic committed $100 million in usage credits and $4 million in open-source donations to a select group of defenders.

    Within 72 hours, regulators in the U.S., U.K., and EU opened emergency banking-risk assessments. By April 13, Reuters reported expert warnings that Mythos-assisted attacks could have dire consequences for banks. This Monday morning, Reuters confirmed regulators are actively monitoring the model. Hours later, Axios confirmed via two independent sources that the NSA is already running Mythos on its own networks.

    The collision point: the Pentagon’s supply-chain blacklist of Anthropic, which a federal judge temporarily stayed on March 26, was then upheld after Anthropic lost its appeal on April 8. Anthropic is currently suing the Department of Defense. Its CEO Dario Amodei met with White House officials this month in what was described as a “productive starting point.” Meanwhile, Gigazine reports that almost every federal agency outside DoD wants access, and OMB is drafting a guardrail-attached “revised version” for wider federal use.

    72.4%
    Mythos exploit generation success rate
    ~0%
    Opus 4.6 exploit generation rate
    40
    Organizations with current Mythos access
    27 yrs
    Age of oldest zero-day found (OpenBSD)

    The Capability Leap: Why This Is Different

    The numbers deserve attention. The Register’s April 7 deep-dive reported Mythos generates working exploits at a 72.4% success rate. Claude Opus 4.6, Anthropic’s prior flagship, sits at approximately 0%. That is not an incremental improvement. It is a category change.

    On the CyberGym vulnerability reproduction benchmark, Mythos scores 83.1% versus Opus 4.6’s 66.6%. On SWE-bench Verified, the standard software engineering benchmark, Mythos reaches 93.9% versus Opus 4.6’s 80.8%. On Terminal-Bench 2.0, which evaluates autonomous multi-step command execution: 82.0% versus 65.4%.

    Benchmark Mythos Preview Opus 4.6 Delta
    Exploit Generation Success 72.4% ~0% +72.4 pts
    CyberGym (vuln reproduction) 83.1% 66.6% +16.5 pts
    SWE-bench Verified 93.9% 80.8% +13.1 pts
    SWE-bench Pro 77.8% 53.4% +24.4 pts
    Terminal-Bench 2.0 82.0% 65.4% +16.6 pts
    GPQA Diamond 94.6% 91.3% +3.3 pts
    Critically, this capability is not the product of cybersecurity-specific training. As Pixee’s April 8 briefing noted, the exploit generation ability emerged from general reasoning. The implication for safety researchers: you cannot contain this by restricting cybersecurity training data. The capability is a property of reasoning depth, not domain specialization.

    “The window between vulnerability discovery and exploitation has collapsed, what once took months now happens in minutes with AI.”

    Elia Zaitsev, CTO, CrowdStrike

    Project Glasswing: How Gated Access Actually Works

    No major outlet has explained the technical access model in detail. Here is what the Anthropic Glasswing documentation actually specifies. Mythos Preview is available via the standard Claude API, Amazon Bedrock, Google Vertex AI, and Microsoft Foundry. Approved organizations access it like any other API endpoint, not through a separate classified system.

    Token pricing is $25 per million input tokens and $125 per million output tokens. That output price is roughly 5x the cost of Opus 4.6. Approved use cases include local vulnerability detection, black-box binary testing, endpoint security analysis, and penetration testing workflows. The model is not available for general release.

    What is absent from Glasswing’s public documentation: audit logging requirements, output controls on generated exploit code, and any specified legal liability if an approved organization’s access is breached. Anthropic has stated it plans safeguards for an upcoming Opus model with Mythos-class capabilities, but Mythos Preview ships with minimal publicly documented output restrictions. For enterprise compliance teams, this is a gap. There is no published framework for how CTOs at approved organizations are expected to handle the chain-of-custody for model outputs that contain working exploit code.

    The 40 current access holders include AWS, Google, Microsoft, NVIDIA, Cisco, and CrowdStrike among 12 publicly named organizations. The remaining 28 are undisclosed. NSA is now confirmed as one of them via the Axios reporting, though it does not appear in Anthropic’s published list.

    What’s Public What’s Not Documented
    API access via Bedrock, Vertex, Foundry Audit logging requirements
    $25 input / $125 output per million tokens Output controls on exploit code
    $100M in usage credits committed Legal liability if access is breached
    12 publicly named organizations 28 unnamed access holders
    Approved use cases listed Chain-of-custody requirements for outputs

    Why Banks Are the Specific Concern

    Regulators are not reacting to the idea of AI-assisted hacking. They are reacting to a specific capability profile. Bank of England Governor Andrew Bailey stated that the institution is examining the development carefully, warning of the potential for a wave of AI-assisted cybercrime. Channel NewsAsia confirmed that regulators are actively monitoring for banking-system risks.

    The specific threat profile is not about new attack techniques. It is about the age of vulnerabilities that Mythos finds. Banking infrastructure runs on decades-old codebases. Mythos discovered a 27-year-old OpenBSD TCP SACK denial-of-service flaw and a 16-year-old FFmpeg bug, both surviving five million automated tests undetected, per the Glasswing announcement. Legacy systems are not patched against vulnerabilities that were not known to exist.

    Beyond detection, Mythos can chain multiple vulnerabilities for privilege escalation. The Glasswing documentation demonstrates a Linux kernel exploit path from unprivileged user to root. Security analysts writing on LinkedIn have flagged this as the core banking exposure: Mythos does not just find the newest vulnerabilities, it surfaces the oldest, most embedded ones, precisely the category that legacy banking infrastructure has not been patched against.

    The NSA Paradox: Not Hypocrisy, a New Category

    The easy read on the NSA situation is contradiction. The Pentagon labeled Anthropic a supply-chain risk. Another major intelligence agency used the same company’s model on its own networks. That is not incoherence. It is the first live instance of a new governance problem with no established framework.

    Some frontier models will be simultaneously too dangerous to deploy publicly and too essential to forgo for defensive purposes. That is not a tension that existing procurement rules, security certifications, or vendor risk frameworks were built to handle. The DoD blacklist was designed for traditional supply-chain risks: hardware backdoors, data exfiltration, foreign ownership influence. A model that generates working exploits at 72.4% accuracy is a different category of risk, and also a different category of necessity.

    “AI capabilities have crossed a threshold that fundamentally changes the urgency required to protect critical infrastructure. The old ways of hardening systems are no longer sufficient.”

    Anthony Grieco, SVP & Chief Security & Trust Officer, Cisco
    OMB drafting a “revised version” of Mythos with guardrails is the administrative response to this problem. It is also an acknowledgment that the Pentagon’s blanket blacklist is not sustainable when the model in question is the best available tool for the exact mission the blacklisting agency is supposed to perform.

    The Anthropic lawsuit against DoD and Dario Amodei’s White House meeting this month are the corporate side of the same negotiation. Both sides are working toward a regime that does not exist yet. For private-sector teams watching this, the relevant signal is: the federal government will eventually produce a formal framework for dual-use frontier AI access. Whatever that framework looks like will become the template for enterprise procurement policies in regulated industries.

    Strategic Implications: Who This Reshapes

    The AI red-teaming services market sits at $2.26 billion in 2026 and is projected to reach $6.17 billion by 2030, a 28.5% compound annual growth rate. The AI cybersecurity market overall is at $25.53 billion, projected at $50.83 billion by 2031. Mythos accelerates both curves.

    Glasswing’s named partners, AWS, Google, Microsoft, NVIDIA, Cisco, CrowdStrike — gain first-mover positions in what Rapid7 frames as an AI-augmented security category. Their access to Mythos at the model level gives them a structural advantage in building the monitoring, audit, and remediation layers that every enterprise running frontier AI will need.

    Legacy cybersecurity vendors selling incremental AI-assisted tooling face a harder problem. As one security analyst on LinkedIn noted, Mythos does not improve the existing model of human analysts using AI to accelerate manual processes. It creates and exploits vulnerabilities at a pace that makes the underlying business model for incremental tooling obsolete. The value shifts to whoever owns the detection and containment layer for Mythos-class outputs.

    For banks and critical infrastructure, the short-term requirement is straightforward: every system that Mythos could plausibly target needs a patch prioritization audit weighted toward oldest-vulnerability exposure, not just recent CVEs. Global Banking and Finance reports that multiple major institutions have already initiated urgent patching reviews.

    Reality Check: What Is Confirmed vs. What Is Projection

    Some of the coverage around Mythos is running ahead of the evidence. Here is what the primary sources actually support.

    Confirmed: Mythos has a 72.4% exploit generation success rate, per The Register’s benchmarking coverage. The NSA is using Mythos, per two sources to Axios. Anthropic found thousands of zero-days across major platforms, per the official Glasswing release. Regulators are monitoring for banking-system risks, per Reuters.

    Unverified: The estimate that open-source models could match Mythos’s bug-finding capabilities within six months comes from unnamed analysts cited in Insider Finance reporting. It is plausible given the trajectory of open-source capability curves, but it is a projection, not a confirmed timeline. The claim that Mythos can destabilize banking systems as a practical near-term scenario also runs ahead of what has been demonstrated — Anthropic has not disclosed a successful end-to-end attack on a real banking system. The BBC noted that some cybersecurity specialists question the severity of concerns given Mythos has not yet undergone extensive independent industry testing.

    What to watch: Anthropic’s promised public vulnerability disclosure timeline (90 days), the OMB guardrail framework, the DoD lawsuit outcome, and whether any open-source model replicates the 72.4% exploit generation figure on a reproducible benchmark.

    Frequently Asked Questions

    Yes. Axios confirmed via two independent sources that the NSA has Mythos access and is running it on its own networks for vulnerability detection. The NSA is one of approximately 40 organizations in the Project Glasswing program, though it does not appear among the 12 publicly named partners.
    The Pentagon added Anthropic to its supply-chain risk list in February 2026 under traditional vendor security criteria. A federal judge temporarily stayed the designation on March 26, but Anthropic lost its appeal on April 8. Anthropic is currently suing the DoD. The blacklist was not specifically designed for the dual-use AI risk profile Mythos represents, it uses frameworks built for hardware and data security risks.
    The specific concern is Mythos’s ability to find old vulnerabilities, a 27-year-old OpenBSD flaw and a 16-year-old FFmpeg bug, both undetected by five million automated tests. Banking infrastructure relies on legacy codebases that have not been patched against vulnerabilities that were never known to exist. Mythos can also chain multiple vulnerabilities for privilege escalation, enabling end-to-end autonomous attacks. Regulators confirmed active monitoring; Bank of England Governor Andrew Bailey issued a public warning.
    Approximately 40 organizations total, 12 publicly named: AWS, Google, Microsoft, NVIDIA, Cisco, CrowdStrike, and others. The remaining 28 are undisclosed. NSA is now confirmed via reporting. Access is provided via the Claude API, Amazon Bedrock, Google Vertex AI, and Microsoft Foundry, at $25 per million input tokens and $125 per million output tokens. Anthropic committed $100 million in usage credits across the program.
    Mythos can generate working exploits for discovered vulnerabilities at 72.4% success rate and chain vulnerabilities for privilege escalation. Whether this translates to a practical end-to-end attack on a real banking system is not confirmed. Some cybersecurity specialists, as the BBC noted, question the severity of concerns pending independent industry testing. The regulatory response treats it as a credible threat requiring immediate evaluation, not a demonstrated live attack.
    This is an analyst projection cited in Insider Finance, not a confirmed timeline. It is plausible given recent open-source capability trajectories, but no open-source model has currently demonstrated a comparable exploit generation success rate on a reproducible benchmark. If accurate, it substantially changes the risk calculus: defenders lose the advantage of capability scarcity.
    Most teams cannot evaluate their exposure using Mythos-class tools because they do not have access. That is itself the risk. Immediate steps: audit your oldest-vintage dependencies and unpatched systems, not just recent CVEs; add “dual-use AI output” as a vendor risk category in your security assessments; brief leadership on the dual-use AI exposure class before your next board cycle; and evaluate whether you qualify for Glasswing access if you operate critical software infrastructure.

    Where This Ends Up

    Mythos is not an anomaly. It is a preview of the governance problem that will define the next three to five years of frontier AI deployment: models that are simultaneously the best available tool for defensive work and the most serious offensive risk. The blacklist-versus-operational-necessity tension the NSA and DoD are navigating will repeat for every sector that deploys frontier models in security-sensitive contexts. Banking, critical infrastructure, healthcare, and defense procurement will all need updated frameworks. None currently exist.

    The six-to-twelve month window matters most. Anthropic plans to publish its vulnerability disclosure reports within 90 days. OMB is finalizing its guardrail framework. The DoD lawsuit proceeds. Open-source capability curves continue climbing. Whatever governance structure crystallizes in this window will define the template, not just for Mythos, but for every subsequent model that crosses the autonomous exploit-generation threshold. Teams that build compliance and risk posture now, rather than waiting for the framework to arrive, will be ahead of the next regulatory sprint.

    For software engineers and ML engineers: Treat Mythos-class output controls, sandboxing, provenance tracking, output filtering on generated code — as mandatory components of any agentic or code-gen pipeline, regardless of whether your team has access to Mythos itself. The output controls will be required; building them after the fact is more expensive than building them now.

    For CTOs and CISOs: Reweight your vulnerability patch prioritization toward oldest-vintage exposure, not just recent CVEs. Add “dual-use AI” as a formal category in vendor risk scoring. Brief your board on Glasswing access eligibility if you operate critical software infrastructure. Budget for AI red-teaming as a standing operational expense — not an optional line item.

    For founders and investors: The defensive AI tooling category — monitoring layers, audit infrastructure, red-teaming services, is moving from optional to mandatory across regulated industries. The $2.26 billion AI red-teaming market figure is a floor, not a ceiling, if open-source models do match Mythos capabilities within six months.

    Disclaimer: This article synthesizes publicly available reporting and primary source documentation. NeuralWired does not have independent access to Claude Mythos Preview, Project Glasswing, or any classified government documentation regarding NSA usage. Benchmark figures are drawn from Anthropic’s official Glasswing announcement and third-party coverage. Market projections are sourced from Research and Markets and MarketsandMarkets and carry inherent forecast uncertainty. Nothing in this article constitutes legal, financial, or security advice.
  • Claude Design AI Prototyping Tool: What Figma Didn’t See Coming

    Claude Design AI Prototyping Tool: What Figma Didn’t See Coming

    Anthropic Just Shipped Claude Design | NeuralWired
    NeuralWired The authority source for technical professionals | Analysis & Investigative Reporting

    Anthropic Just Shipped Claude Design — The AI That Eats Your Design System and Ships Prototypes in Seconds

    While the tech press wrote about “quick visuals,” Anthropic quietly wired a frontier LLM directly into your production codebase. The real story is a platform grab — and Figma just lost the origination step.


    7.28% Figma stock drop
    on launch day
    98.5% Opus 4.7 visual
    acuity benchmark
    20→2 Prompts to recreate
    a page (Brilliant)
    $800B Anthropic valuation
    talks (April 2026)

    What the Press Missed

    TechCrunch ran the launch headline: “Anthropic launches Claude Design, a new product for creating quick visuals.” That framing is accurate and almost completely wrong. It describes what users see — a text-to-prototype interface — while missing the structural maneuver underneath: Anthropic has built the first frontier LLM product that ingests your entire frontend codebase as live context and enforces brand-consistent styling on every output. That is not a visual generator. That is an infrastructure play.

    Three signals confirm the strategic intent were hiding in plain sight. First: Anthropic CPO Mike Krieger resigned from Figma’s board on April 14 — the same day The Information leaked the launch. Claude Design shipped 72 hours later. That sequencing is not a coincidence; it is a disclosure protocol executed before a direct competitive strike. Second: the tool was built on Claude Opus 4.7, a vision-optimized model that Anthropic released quietly this month, scoring 98.5% on XBOW’s visual-acuity benchmark — up from 54.5% on Opus 4.6. That 44-point jump is not incremental. It is the prerequisite that made Claude Design possible. Third: no outlet covered the handoff bundle, Claude Design’s one-click bridge to Claude Code that packages rendered designs into shippable production code. That feature collapses the entire design-to-engineering workflow into a single conversation.

    “Pages requiring 20+ prompts to recreate in other tools only required 2 prompts in Claude Design.” Olivia Xu, Designer, Brilliant — April 17, 2026

    What Actually Shipped

    On April 17, 2026, Anthropic released Claude Design in research preview, immediately available to all Claude Pro ($20/mo), Max ($100–200/mo), Team ($30/user/mo, minimum 5 seats), and Enterprise subscribers. Enterprise admins must explicitly enable it — off by default — a governance decision that signals Anthropic understands the IP sensitivity of what it is asking companies to do: feed their codebases to an LLM.

    The product operates in four stages. In onboarding, Claude parses your repository — Tailwind config, shadcn/ui component library, custom design tokens — plus any Figma or Sketch files you point it at, then extracts a working model of your brand. In the input phase, you can drop in a text prompt, upload an image, paste a document (DOCX/PPTX/XLSX), reference a codebase path, or capture a live website. Refinement happens conversationally: inline comments on specific elements, direct text edits, spacing and color adjustment. Export options cover internal URL, Canva (fully editable), PDF, PPTX, standalone HTML, and the aforementioned handoff bundle for Claude Code.

    The Canva partnership is worth parsing carefully. Melanie Perkins framed it as collaborative: “We’re excited to build on our collaboration with Claude, making it seamless for people to bring ideas and drafts from Claude Design into Canva.” Read that as a business decision, not a friendship. Canva has correctly identified that its moat is the editing and publishing layer, not generation. Partnering with Anthropic rather than competing converts the Claude funnel into Canva retention. It is a rational capitulation to platform gravity.

    Technical Specification Value
    Underlying modelClaude Opus 4.7 (vision-optimized)
    Max image resolution3.75MP / 2,576px long edge (3× Opus 4.6)
    Visual-acuity benchmark98.5% (XBOW internal)
    Token throughput~81 tokens/sec
    Design systems supportedMultiple per team
    Codebase integrationRepo + Figma/Sketch files
    CollaborationBasic; not yet fully multiplayer
    AvailabilityResearch preview, gradual rollout

    Under the Hood: What Engineers Need to Know

    The model powering Claude Design is Claude Opus 4.7, which also scores 70% on CursorBench (up 12 points from 4.6), solves 3× more production tasks than Opus 4.6, and runs at approximately 81 tokens/second. The resolution jump to 3.75MP matters specifically because UI work involves dense information — fine typography, component spacing, icon rendering — that lower-resolution models consistently hallucinate or approximate. At 98.5% visual acuity, Opus 4.7 can reliably read and reproduce a Figma export at the pixel level.

    For teams running React/Tailwind stacks with documented design tokens, the integration pathway is direct. Claude Design reads your tailwind.config.js, extracts color primitives and spacing scales, maps them to generated components, and produces output that requires no token-value substitution before handoff. For monorepos with custom component libraries, the fidelity depends on how well-documented your component API is — Claude needs prop interfaces and usage examples to infer correct component composition.

    The CI/CD angle is undercovered. Claude Code already has a published playbook for production-safe GitHub Actions and GitLab YAML workflows. That infrastructure now has an upstream: Claude Design outputs can feed directly into those pipelines, creating an end-to-end AI-authored design-to-deploy chain. Whether you want that running unsupervised on your main branch is a governance question, not a technical one.

    One security concern deserves direct attention. Reuven Cohen flagged it on LinkedIn in September 2025 in the context of Claude Code, but it applies with equal force here: if Claude modifies or deletes LICENSE files during codebase ingestion or code generation, private code can be inadvertently relicensed. “The consequences are real,” he wrote. Before feeding a proprietary monorepo to Claude Design, your legal and security teams need explicit answers from Anthropic on data residency, prompt logging scope, and what the model writes back to your repo vs. what stays ephemeral.

    Strategic Implications: Who Wins, Who Absorbs the Impact

    Figma currently holds 80 to 90% of the UI/UX design tool market. That position rests on an assumption that has quietly become false: that “design work” begins with a trained designer opening Figma. Claude Design attacks the origination step — the pre-design phase where PMs write Notion specs, founders sketch on whiteboards, and engineers describe what they want in tickets. By the time a designer opens Figma on a team using Claude Design, the brief already has a working prototype attached. That does not eliminate Figma. It does eliminate the billable hours spent translating verbal briefs into first mockups.

    Figma’s stock fell 7.28% to $18.84 on launch day, extending a decline of more than 80% from its post-IPO high. This is not pure sentiment reaction. It reflects a structural assessment: Figma’s multiplayer collaboration, 20-year plugin ecosystem, and auto-layout system are genuine moats for production design work. But Figma’s revenue model depends on designers spending hours in the tool on every project. Claude Design compresses the early cycles of that work to minutes. Fewer hours in Figma means fewer seats justified, and fewer seats means slower ARR growth for a company already fighting negative market momentum.

    The competitive picture is broader than a two-player contest. Google’s Stitch, which launched in March 2026, already dropped Figma stock 12% in two days. Adobe, Wix, and GoDaddy all declined 3 to 4.7% on Claude Design’s launch day. The pattern is consistent: every credible AI-native design entrant validates the thesis that the incumbent tools are structurally overpriced for the workflow they deliver.

    Anthropic’s positioning is the clearest winner here. The company now owns a pipeline from design ideation through prototype through production code — all within the Claude subscription a team already pays for. Its ARR crossed $30 billion in early April 2026, up from $9 billion at year-end 2025, with Claude Code alone running at a $2.5 billion run rate. Bundling Claude Design into existing subscriptions at zero marginal cost is a classic platform move: drive adoption before competitors can price-compete, then extract value through enterprise upsell and data network effects.

    Stakeholder Net Impact Reasoning
    Non-designers (PMs, founders)Major winFirst tool that closes “I can describe it” → “I have a shareable prototype”
    AnthropicMajor winOwns pre-design → design → code pipeline; bundling drives zero-marginal-cost adoption
    CanvaNeutral to positiveDownstream editor partnership converts Claude drafts into Canva retention
    FigmaSevere pressureLosing origination step; market share based on flawed assumption about workflow entry point
    Traditional design rolesStructural riskPMs now arrive with working prototypes; designer’s leverage in early cycles shrinks
    Adobe / Wix / GoDaddyPressureAll declined 3–4.7% on launch day; pure-play design tools face systematic repricing

    Reality Check: High Confidence vs. Speculation

    An anonymous senior UI designer on Reddit summarized the skeptic position bluntly: Claude Design is “cookie-cutter and subpar” for production work. That assessment is probably correct for high-complexity interfaces today. It is also increasingly irrelevant for the 60% of design work that is not high-complexity — landing pages, internal dashboards, pitch decks, onboarding flows, and settings screens that follow well-understood patterns.

    The Kingy AI analyst put the limitations plainly: no true canvas, no pixel-perfect vector editing, no auto-layout, no multiplayer cursors, no plugin ecosystem. Those gaps are real and will not close in six months. What Claude Design has is a different attack vector: the pre-design phase, where the real bottleneck is not drawing skill but translation — turning a written idea into something a designer can act on.

    ✓ High Confidence (Real)

    • Design starting point shifts from “open Figma” to “open Claude” — durable change
    • 10× prompt efficiency validated by Brilliant’s 20→2 prompt reduction
    • Week-long brief→mockup→review cycles compressing to single conversations
    • Zero marginal cost drives team-level adoption without budget approval

    ✗ Low Confidence (Overstated)

    • “Figma killer” — multiplayer, plugins, and designer muscle memory hold for 12–24 months
    • Designers replaced — they gain a new stakeholder (PM with prototype) to manage
    • Production-ready output — best for prototypes and internal tools, not pixel-perfect UIs
    • Immediate enterprise security clearance — proprietary codebase ingestion still unresolved

    Action Items by Role

    For Engineers and Engineering Leads

    1. Run a controlled pilot: feed your Tailwind config and one component library to Claude Design and measure output fidelity against your actual design tokens before broader rollout.
    2. Review your IP and data residency posture. Confirm with your legal team whether proprietary codebase ingestion violates existing vendor agreements or internal data policies.
    3. Map the CI/CD integration points. The Claude Code YAML playbook is already published — identify one internal tool sprint where the Design → Code → Deploy pipeline can be tested safely.
    4. Do not wait for the production-quality bar to clear for complex UIs. Start with internal dashboards, doc sites, and pitch decks where the fidelity bar is lower and iteration speed matters most.

    For CTOs and Tech Leaders

    1. Reassess your design tooling budget. If Claude Design reaches 70% fidelity for your internal tooling needs, the case for full Figma Teams seats for every PM weakens immediately.
    2. Define governance before pilots start. Decide now which codebases are off-limits for AI ingestion and document that policy before an engineer tests it informally.
    3. Put Figma on a 12-month watch list, not an exit list. The multiplayer and plugin ecosystem moat is real. But the workflow assumptions underlying your current Figma seat count are not.
    4. Monitor Google Stitch. Two AI-native design entrants (Anthropic and Google) competing on the same origination wedge accelerates the repricing faster than either alone would.

    Frequently Asked Questions

    Is Claude Design better than Figma? +
    For professional production design work — complex component libraries, multi-screen flows, team collaboration, pixel-perfect vector output — Figma is still the tool. Claude Design’s advantages are in the pre-design phase: rapid prototyping, brief-to-mockup translation, and generating starting points that a designer then refines in Figma. The better question is whether you still need Figma for every step in that workflow, not whether Claude Design replaces it end-to-end.

    How much does Claude Design cost? +
    Claude Design is bundled into existing Claude subscriptions at no additional charge: Pro ($20/month), Max ($100–200/month), Team ($30/user/month, minimum 5 seats), and Enterprise. Enterprise admins must explicitly enable the feature — it is off by default. There is no standalone Claude Design SKU currently announced.

    Does Claude Design work with Tailwind and React? +
    Yes — React/Tailwind stacks are the best-supported configuration. Claude Design reads your tailwind.config.js directly to extract color scales, spacing tokens, and typography settings, then applies them to generated outputs. Teams using shadcn/ui or custom component libraries with documented prop interfaces will see the strongest fidelity. Output from Claude Design can flow directly into Claude Code’s CI/CD integration for GitHub Actions and GitLab pipelines.

    Is Claude Design safe for proprietary code? +
    This is the most undercovered risk with the product currently. Security engineer Reuven Cohen has documented cases where Claude can inadvertently modify or delete LICENSE files during code operations, creating potential IP exposure. Before feeding proprietary repositories to Claude Design, verify Anthropic’s data residency guarantees, confirm prompt logging scope with your account team, and audit what the model writes back to your codebase versus what remains ephemeral. Treat this as a legal review item, not only a security review.

    Can Claude Design export to Canva? +
    Yes. Canva export is one of Claude Design’s native output formats and produces fully editable Canva files — not flat images. This is the result of a partnership between Anthropic and Canva. Exports to PDF, PPTX, standalone HTML, and the Claude Code handoff bundle are also available. Note that Canva is currently the only downstream editor that produces vector-editable output; PDF and HTML exports are not re-editable in the same way.

    What is the Claude Design vs. Google Stitch comparison? +
    Google Stitch launched in March 2026 and dropped Figma stock 12% in two days with a broadly similar premise: AI-native design generation targeting the pre-design origination phase. Claude Design differentiates primarily on codebase integration depth — Stitch does not currently ingest production repos the same way — and on the end-to-end handoff to Claude Code. Both products are early previews. Expect rapid feature convergence over the next two quarters as both companies treat AI design tooling as a horizontal enterprise platform wedge.

    Will Claude Design replace traditional design roles? +
    Not directly, and not soon. The more accurate framing: designers will increasingly work with PMs and founders who arrive with Claude-generated working prototypes instead of verbal briefs. That changes the designer’s role from translator to refiner — higher-leverage work, but structurally fewer hours per project. The roles most at risk are junior design roles focused primarily on first-draft mockup production. Senior designers, design system architects, and UX researchers are less exposed because their work depends on judgment and user insight that prompt engineering does not replicate.

    Synthesis

    Claude Design is not a Figma killer. It is something more consequential: a redefinition of where design work starts. Anthropic has inserted itself into the origination step of every product workflow at zero marginal cost, bundled into a subscription teams already own. The traditional sequence — PM writes Jira ticket, designer opens Figma, engineer rebuilds in code — does not survive contact with a tool that compresses all three steps into one conversation. That compression does not eliminate any role; it eliminates the translation overhead between them. The downstream effect on tooling budgets, designer leverage in early sprints, and Figma’s seat-count justification will be felt over the next four to eight quarters, not four to eight weeks.

    The forward view: Anthropic’s $800 billion valuation discussions and October 2026 IPO timeline are now underpinned by a vertical integration story that did not exist six months ago. Anthropic owns the full pipeline from design ideation through Claude Code deployment. OpenAI’s desktop Codex and Google Stitch are the obvious counter-moves; expect both companies to announce deeper codebase integration features before Q3. Figma’s survival path runs through its plugin ecosystem and multiplayer moat — both real, both under pressure from a generation of product teams that will train their instincts on Claude first. The next 12 months will determine whether Figma’s 80% market share is a defensive position or a waterline.

    What to do now: Run one internal pilot this sprint. Pick a low-stakes project — a dashboard, a deck, an onboarding screen. Feed it your Tailwind config. Measure the fidelity gap against your production design system. You need a real data point before the governance conversation, not after.

    Disclaimer: This analysis is based on publicly available information, press coverage, and community sources as of April 19, 2026. NeuralWired has no financial relationship with Anthropic, Figma, Canva, or any other company referenced in this article. Benchmark figures sourced from third-party evaluations; independent verification is recommended before making procurement or investment decisions. The IP and security concerns referenced reflect community-reported observations, not formal security audits.
  • Cerebras IPO: OpenAI’s $20B Compute Deal Explained

    Cerebras IPO: OpenAI’s $20B Compute Deal Explained

    OpenAI’s $20B Cerebras Bet: IPO Filing Signals the End of NVIDIA’s AI Compute Monopoly — NeuralWired
    Breaking Analysis

    OpenAI’s $20B Cerebras Bet: IPO Filing Signals the End of NVIDIA’s AI Compute Monopoly for Devs and CTOs

    The surface story is a chip startup going public. The real story is OpenAI weaponizing $20 to $30 billion to fracture NVIDIA’s grip on AI compute. Every CTO has 30 days to respond before their 2027 to 2028 infrastructure economics lock in.

    What Actually Happened and What the Headlines Missed

    On April 17, 2026, AI chip startup Cerebras Systems filed its S-1 registration statement with the SEC for a Nasdaq IPO under ticker CBRS. Reuters and Bloomberg framed it as the latest entrant in a hot AI IPO wave. That framing misses the actual story by a wide margin.

    This is OpenAI deliberately engineering the destruction of NVIDIA’s compute monopoly. The company that built GPT-4 and o3 on NVIDIA hardware is now committing more than $20 billion, potentially $30 billion, to a rival architecture at unprecedented scale. It handed Cerebras both its largest revenue contract in history and warrants for up to 10% equity. This is not procurement diversification. It is a structural bet that speed and cost economics at inference time matter more than CUDA lock-in.

    Cerebras had withdrawn a previous IPO attempt in late 2025, blocked by regulatory hurdles stemming from G42’s UAE ties, which had accounted for 87% of Cerebras revenue in the first half of 2024. The OpenAI deal, announced January 2026, provided U.S. strategic cover and a locked revenue base visible enough for the SEC to clear the path. The IPO timing is not coincidental.

    $35B+Target IPO Valuation
    $510M2025 Revenue, +76% YoY
    $237.8M2025 Net Income
    21xFaster Inference vs. B200

    The Deal Mechanics: Warrants, Gigawatts, and a $1B Loan

    The structure embedded in the S-1 is more aggressive than initial reporting suggested. OpenAI commits to 250 megawatts per year from 2026 through 2028, a 750MW base, with an option to scale to 1.25 gigawatts through 2030, pushing the total potential value toward $30 billion. The warrants for up to 10% equity vest only if OpenAI purchases the full 2GW threshold. That is a performance-linked equity grant, not a gift.

    OpenAI also extended Cerebras a $1 billion loan at 6% annual interest, repayable in cash or goods and services. OpenAI financed Cerebras’s operational runway while simultaneously locking in compute supply. Cerebras gets funded. OpenAI gets a price-locked compute hedge against NVIDIA supply constraints and Blackwell allocation uncertainty. The asymmetry is striking and entirely deliberate.

    Key Disclosure from the S-1
    Cerebras’s 2025 revenue reached $510 million, a 76% year-over-year increase from $290 million in 2024. The company posted $237.8 million in net income, its first profitable year after losing $481.6 million in 2024. No other frontier AI chipmaker has reached profitability this fast.

    Cerebras targets a $35 billion-plus valuation and a $3 billion-plus raise, a 60% premium to its February 2026 private valuation of $22 billion. That premium is justified entirely by OpenAI revenue visibility. Without it, the customer concentration risk from G42 alone would crater institutional appetite.

    How Wafer-Scale Architecture Actually Works and Why It Matters

    The WSE-3 (Wafer Scale Engine 3) is not a GPU. It is a single chip occupying an entire 300mm silicon wafer: 46,225mm squared with 900,000 AI cores, 4 trillion transistors, and 44GB of on-chip SRAM. NVIDIA’s Blackwell B200 measures 1,016mm squared. The WSE-3 is 45 times larger.

    MetricWSE-3NVIDIA H100NVIDIA B200
    Die Size46,225mm²815mm²1,016mm²
    AI Cores900,00016,896~208K
    On-Chip Memory44GB SRAM80GB HBM3e192GB HBM3e
    Memory Bandwidth21 PB/s3.35 TB/s8 TB/s
    Transistors4 trillion80 billion~208 billion
    The architectural advantage is not raw compute. It is memory bandwidth and the elimination of off-chip data movement. GPU clusters spend enormous energy and time shuttling activations between HBM stacks and across NVLink interconnects. WSE-3’s 21 petabytes per second of memory bandwidth is roughly 7,000 times the H100’s HBM3e bandwidth. Models up to 20 billion parameters in FP16 fit entirely in on-chip SRAM, removing the memory bottleneck entirely.

    Real-world inference benchmarks show the CS-3 delivering 2,700-plus tokens per second on gpt-oss-120B versus 900 tokens per second on a Blackwell B200. Llama 4 Maverick hits 2,500-plus tokens per second versus 1,000 on B200. Even at 10 parallel requests, Cerebras sustains 580 tokens per second, still five times faster.

    “The mental moat for those who thought that AI equalled Nvidia has been crossed.” Andrew Feldman, CEO, Cerebras Systems. Davos, January 2026.

    What This Means for Engineers Right Now

    The migration barrier has always been CUDA. Engineers who have spent years optimizing kernels, writing custom triton ops, and debugging NCCL collectives view any alternative silicon with understandable skepticism. That calculus is shifting. CUDA compatibility shims for production pilots are expected within weeks. If they perform, teams running memory-bound inference workloads, including long-context LLMs, retrieval-augmented generation pipelines, and agentic loops with large KV caches, can cut costs 30 to 50% without rewriting their stack.

    The SDK story is already better than most engineers assume. Cerebras SDK v1.1.0 ships as a Singularity container with a fabric simulator for local development. Training a 175B-parameter model requires 565 lines of code on Cerebras versus 20,000 lines coordinating 4,000 GPUs. Distributed training orchestration complexity disappears. The wafer is a single logical device.

    The limitations are real and worth stating plainly. Training frontier models above roughly 40B parameters at scale on wafer-scale hardware remains unproven in production. Practitioners on Hacker News note that Cerebras has demonstrated extraordinary inference numbers but has yet to publish credible training runs above that threshold. The hardware also requires custom cooling, including micro-finned cold plates and vertical delivery pins, which complicates retrofitting into existing data center footprints.

    Power and Yield Considerations

    Each CS-3 system draws 23 to 26 kilowatts. At 750MW deployment, the OpenAI deal alone equals the electricity consumption of roughly 600,000 homes. Data centers in Ireland and Northern Virginia already consume 21 to 26% of regional electricity, and regulators in both jurisdictions have begun restricting new capacity permits. Manufacturing yield is managed via 1% spare core reserves with distributed autonomous repair logic, but every chip foundry knows yield at this die size is a meaningful operational variable.

    Who Wins, Who Loses, and How Competitors Are Responding

    OpenAI wins most immediately. It gains compute supply independence, a 10% equity stake in a company it is funding, potential API pricing leverage, and a hedge against NVIDIA allocation uncertainty. If Cerebras hits 750MW on schedule, OpenAI runs inference at a materially lower cost floor, which either expands margins or enables competitive API pricing that squeezes cloud competitors.

    CTOs at enterprises running large inference workloads win if they act within the next 30 days. The hybrid cluster model, with NVIDIA handling training and Cerebras handling inference, reduces supply-chain risk and opens multi-vendor procurement leverage that has not existed in the GPU era. The AI chip market is projected to exceed $400 billion by 2027, with the inference segment growing fastest. Procurement teams that lock in Cerebras capacity during the IPO window may access pricing that shifts once the OpenAI relationship fully prices in.

    NVIDIA faces the most meaningful competitive pressure it has seen since CUDA achieved dominance. The CUDA moat remains intact for training workloads and for the vast installed base of CUDA-optimized code. But the inference market is where Cerebras is winning benchmarks by a factor of 21. NVIDIA’s reported $20 billion acquisition of Groq to integrate deterministic scheduling into the Rubin platform is a direct response. AMD has doubled down on the Instinct MI450 with HBM4. Even Google quietly trained Gemini AI without NVIDIA hardware, the single most significant validation that alternatives are production-ready.

    GPU-only cloud providers face a pricing squeeze. If Cerebras-powered inference becomes available at 30 to 50% lower cost through OpenAI’s API layer, providers who cannot match that efficiency lose price-sensitive customers first and, over time, any customer who benchmarks their workload.

    Reality Check: What Is Verified, What Is Theoretical, and Where This Can Fail

    The 21x inference speed advantage is independently verified by SemiAnalysis benchmarks and Cerebras’s own published CS-3 vs. Blackwell B200 comparisons. The 30 to 50% inference cost reduction is theoretical. It assumes CUDA shim compatibility and hybrid cluster economics that have not been validated in production at scale. Treat that number as a ceiling, not a floor, until pilot data appears.

    ClaimStatus
    21x faster inference vs. B200Verified on specific benchmarked workloads
    30 to 50% inference cost reductionTheoretical; depends on CUDA shim maturity and cluster design
    750MW deployment by 2028Aggressive; requires grid capacity and data center buildout not yet confirmed
    Frontier model training on WSE-3Unproven at scale above roughly 40B parameters
    Four failure scenarios deserve attention. First, Cerebras fails to manufacture enough WSE-3 chips to honor the 750MW commitment and OpenAI exercises options elsewhere, meaning the equity warrants never vest. Second, CUDA compatibility shims underperform and engineering teams, facing retraining costs and integration risk, stay with NVIDIA. Third, power grid constraints block data center buildout in Tier 1 regions, already a live constraint in Ireland and Virginia. Fourth, OpenAI’s 10% equity stake triggers antitrust scrutiny as Cerebras moves closer to commercial customers who compete with OpenAI’s own products.

    None of these scenarios is probable in isolation, but each is plausible. The production track record for wafer-scale at this deployment magnitude simply does not exist yet. Cerebras has built something technically extraordinary. Whether it can build enough of it, fast enough, is an open manufacturing and logistics question that the S-1 cannot answer.

    Frequently Asked Questions

    What is the Cerebras IPO ticker symbol and when does it list?
    Cerebras will trade on Nasdaq under the ticker CBRS. The IPO targets Q2 2026, with pricing expected as early as late April or May 2026. The roadshow is underway as of April 18. Final pricing depends on institutional demand and market conditions at the time of listing.

    Is OpenAI buying Cerebras?
    No. OpenAI is not acquiring Cerebras. The deal is a multi-year compute supply agreement worth over $20 billion, potentially scaling to $30 billion. OpenAI receives warrants for up to 10% equity that vest only if it purchases 2 gigawatts of compute capacity, double the base commitment. OpenAI also provided a $1 billion loan at 6% annual interest. The relationship is supplier-customer with a financial stake attached, not ownership.

    How does Cerebras wafer-scale compare to NVIDIA GPU clusters?
    The WSE-3 delivers 21x faster AI inference than the Blackwell B200 on single-request benchmarks (2,700-plus tokens per second versus 900), with 32% lower total cost of ownership and 33% lower power consumption according to SemiAnalysis data. The advantage is architectural: 21 petabytes per second of on-chip memory bandwidth versus 8 terabytes per second for the B200. NVIDIA maintains advantages for training frontier-scale models and benefits from the CUDA software ecosystem. Cerebras wins on inference speed and latency for memory-bound workloads.

    Can engineers migrate CUDA code to Cerebras without rewriting everything?
    CUDA compatibility shims are expected within weeks for production pilots. The Cerebras SDK v1.1.0 ships as a Singularity container with a fabric simulator for local development. Training a 175B-parameter model requires 565 lines of code on Cerebras versus roughly 20,000 lines coordinating 4,000 GPUs. Teams with heavily optimized CUDA kernels or complex multi-GPU communication patterns will still face migration work. Practical migration depth depends on shim performance in your specific workload class once pilots open.

    How much is Cerebras worth and what is the valuation basis?
    Cerebras targets a $35 billion-plus valuation, a 60% premium to its February 2026 private valuation of $22 billion. The basis is the OpenAI compute contract, 2025 revenue of $510 million growing 76% year-over-year, and first-ever profitability at $237.8 million net income. The premium reflects contract-backed forward revenue, not purely speculative growth.

    What are the key risks of the OpenAI-Cerebras dependency?
    Three primary risks. First, concentration risk: if OpenAI reduces or cancels the contract, Cerebras loses its primary revenue anchor, recreating the G42 problem it is trying to solve. Second, equity conflict: OpenAI holding up to 10% stake in its compute supplier creates pricing and competitive tension if Cerebras signs deals with OpenAI’s competitors. Third, antitrust scrutiny: a major AI model provider holding equity in its largest hardware supplier may attract regulatory attention in the EU and U.S.

    Will this competition lower AI API prices for developers?
    Directionally yes on inference-heavy API calls. If OpenAI’s internal inference cost drops 20 to 40% via Cerebras hardware, it gains margin headroom to cut API pricing competitively. Whether it passes savings to customers or captures margin depends on competition from Anthropic, Google, and Meta. The more likely near-term impact: OpenAI can offer lower-latency responses at the same price point, putting pressure on competitors who remain fully dependent on GPU infrastructure.

    The Bottom Line

    Cerebras’s IPO is not primarily a public markets event. It is the moment wafer-scale architecture becomes a production-grade infrastructure category: not experimental, not a benchmark curiosity, but a contracted compute backbone for the world’s largest AI lab. The WSE-3’s inference performance is independently verified. The revenue is real. The profitability is real.

    This is the first time a credible alternative to NVIDIA has both the technical benchmarks and the commercial traction to force procurement decisions at the CTO level. Multi-vendor AI compute is no longer a theoretical option. It is an economic obligation for any organization running inference at scale.

    Watch the CUDA shim performance data when production pilots publish in May and June 2026. That data will settle whether this is a complete architectural shift or a niche advantage for specific workload classes. Either way, the single-vendor AI compute era ends here. The only question is how fast.

    Action Items for Engineers

    1. Request pilot access to Cerebras Cloud inference API immediately. Free-tier benchmarks on your actual workload will tell you more than any synthetic comparison.
    2. Audit your inference pipeline for memory-bound segments: long-context completions, large KV caches, and high-throughput batch jobs are the highest-value migration candidates.
    3. Set up the Cerebras SDK Singularity container locally before the CUDA shims ship. Understanding the programming model now means you are ready to evaluate compatibility the day pilots open.
    4. Run a side-by-side cost model on tokens-per-dollar for your p95 inference request size across NVIDIA, Cerebras, and hybrid configurations. Do this before Q3 budget cycles lock.

    Action Items for CTOs and Infrastructure Leads

    1. Issue a 30-day evaluation directive to your AI infrastructure team: quantify inference cost exposure if Cerebras-backed API pricing undercuts your current provider by 30% within 12 months.
    2. Map your 2027 to 2028 GPU allocation commitments and identify where you have contractual flexibility to introduce Cerebras capacity without breaking reserved instance economics.
    3. Contact your NVIDIA account team this week. The Cerebras filing creates immediate leverage for pricing renegotiation on inference-optimized SKUs, regardless of whether you move to Cerebras.
    4. Monitor the antitrust angle. OpenAI’s equity stake in Cerebras may face scrutiny. If your organization competes with OpenAI products, factor supplier independence risk into procurement strategy.
    Disclaimer: This article is published for informational purposes only. NeuralWired does not hold positions in any securities mentioned. Nothing in this article constitutes investment advice. All financial figures are sourced from public SEC filings, press releases, and attributed third-party research as linked. Forward-looking statements about cost reductions, deployment timelines, and market projections involve material uncertainty. Readers should verify all figures against primary source documents before making procurement or investment decisions.
  • Tesla AI5 Chip: Edge Inference Just Changed (2026)

    Tesla AI5 Chip: Edge Inference Just Changed (2026)

    Tesla Tapes Out AI5 Chip: Why Custom Silicon Is About to Change Edge AI Deployment Forever — NeuralWired
    Technical intelligence for builders & decision-makers
    AI Hardware|Investigative Analysis|April 16, 2026

    Tesla Tapes Out AI5 Chip: Why Custom Silicon Is About to Change Edge AI Deployment Forever

    The headline says “faster FSD.” The real story is a vertically integrated inference platform targeting NVIDIA’s edge dominance, at a fraction of the cost, embedded in millions of cars and robots.

    The Story Nobody Is Actually Telling

    On April 15, 2026, Elon Musk posted a photo of a silicon wafer and declared that Tesla’s next-generation AI5 processor had successfully taped out, chip industry shorthand for completing the physical design and sending it to a foundry. Within hours, every tech outlet ran a version of the same story: “Tesla’s new chip is 40× faster.” That framing is misleading. And the actual story is considerably more consequential.

    AI5 is not primarily an upgrade for your Model Y. Musk confirmed that AI4 already achieves “much better than human safety” for Full Self-Driving, which means the compute bottleneck for vehicles is largely solved. AI5 is engineered for two different missions: powering Optimus humanoid robots with real-time edge inference, and scaling Tesla’s supercomputer training clusters. The car is almost incidental.

    The deeper story is competitive strategy. By designing custom ASICs optimized for its own neural network architectures, Tesla can undercut NVIDIA’s edge inference economics by roughly 10× on cost and 3× on performance per watt. Multiply that across a fleet of millions of vehicles and robots and the result is a distributed AI inference platform of unprecedented scale, one that could eventually be offered to xAI, or used as a licensing wedge into the broader embodied AI market.

    What Actually Happened on April 15

    Tape-out is a hard milestone. It means the design is frozen, masks are cut, and fabrication begins. Engineering samples are now expected in late 2026, with volume production tracking for mid-2027. Musk simultaneously confirmed that AI6 and Dojo 3 are already in development, with AI6 tape-out expected December 2026.

    The performance claims are striking but require context. A single AI5 delivers 8× the raw compute of AI4, 9× the memory capacity, and 5× the memory bandwidth. The “40×” figure applies to targeted workloads, it bundles compute, memory bandwidth, and specialized accelerators into a composite metric. It is not a uniform speedup across all tasks. No independent lab has benchmarked a physical sample yet, because none exist.

    Tesla is dual-sourcing production across TSMC and Samsung, a supply-chain hedge that signals how seriously the company treats AI5’s volume ambitions. That accidental mention of “TSC” in early coverage (later corrected) points to TSMC’s N3 process node, the same advanced node Apple uses for M-series chips. Samsung’s Taylor, Texas fab handles a parallel production stream, though yield issues at the Taylor facility contributed to AI5 slipping nearly two years behind its original H2 2025 schedule.

    “AI5 will be 40 times better than AI4 by some metrics… we work so closely at the hardware-software level.”

    — Elon Musk, X, April 15, 2026

    Architecture: What Tesla Actually Built

    The design decisions inside AI5 are as revealing as the headline numbers. Tesla removed the legacy GPU and Image Signal Processor (ISP) that occupied significant die area in AI4, replacing them entirely with Tesla-specific neural network accelerators, Arm CPU cores, and PCI interface blocks. Every transistor serves Tesla’s own model architecture. Nothing is there for general-purpose compatibility.

    The memory subsystem is similarly opinionated. Twelve SK Hynix memory packages surround the die on a ~384-bit interface, likely GDDR6 or GDDR7 rather than HBM. Tesla engineers debated HBM’s higher bandwidth ceiling but chose conventional GDDR for its cost and manufacturability advantages at scale. For Optimus robot deployments, where cost per unit is critical, that tradeoff makes sense. For pure training throughput, it limits ceiling performance.

    Specification AI4 AI5 Delta
    Raw computeBaseline8× AI4+700%
    Memory capacityBaseline9× AI4+800%
    Memory bandwidthBaseline5× AI4+400%
    Memory interface—~384-bit GDDR6/7—
    Peak power~300WUp to 800W~2.7×
    Target (robot) power—~250W—
    Useful compute (vs dual AI4)1×~5×+400%
    The power story deserves attention. The chip targets 250W for Optimus use but reaches 800W peak , nearly three times the thermal envelope that HW4 vehicle liquid cooling was designed for. That gap explains why AI5 requires a different board layout and connector type, making it incompatible with existing HW4 vehicles. Owners waiting for a retrofit will be waiting a long time.

    The Competitive Stakes for NVIDIA and Everyone Else

    The frame that matters for ML engineers and CTOs is cost-per-inference, not raw FLOPS. A single AI5 reportedly approaches NVIDIA Hopper (H100) inference throughput at 150–250W versus the H100’s 700W. Dual AI5 configurations are projected to match Blackwell (B200) performance at a fraction of the per-unit hardware cost. These claims require independent verification, but if they hold under real workloads, the economics of running inference at the edge shift dramatically.

    NVIDIA’s edge AI margin depends on nobody having a better alternative. Tesla is building one for itself. The risk for NVIDIA isn’t that Tesla starts selling chips, it almost certainly won’t. The risk is that Tesla’s success makes the case for other large-scale deployers to follow suit, accelerating the custom ASIC trend that Google (TPU), Amazon (Trainium/Inferentia), and Microsoft (Maia) are already executing in the cloud.

    Market Context
    The edge AI hardware market is tracking from $26.14B in 2025 to an estimated $58.90B by 2030 (CAGR 17.6%), per MarketsandMarkets. Tesla’s AI5 enters this market not as a product for sale but as a moat, a reason every competitor must either match Tesla’s ASIC investment or absorb the NVIDIA premium Tesla no longer pays.

    For robotics and autonomy startups, the benchmark has just been set publicly. Teams that were “planning to evaluate custom silicon later” now have a concrete performance target to beat. The “just use GPUs” default for robotics inference becomes harder to defend when a competitor is running at 10× lower cost per inference on proprietary hardware.

    What This Means for ML Engineers Right Now

    The critical gap in all current coverage: nobody has addressed what AI5 means for developer workflow. Tesla’s AI4 and earlier chips required model teams to work with Tesla’s internal compiler stack, with limited official SDK exposure for external researchers. AI5 removes both the traditional GPU and the ISP, components that many existing optimizations assumed were present.

    No SDK release has been announced. Tesla’s internal teams likely already work against AI5 simulation environments, but external developers — including those building on FSD APIs or evaluating Tesla hardware for third-party robotics, are in the dark. Whether existing PyTorch or JAX pipelines require significant rewrites for AI5-specific quantization, operator fusion, or memory layout is unknown.

    The architectural shift toward pure neural accelerators (no legacy GPU path) suggests that inference code relying on general CUDA-style parallelism will need reworking. Model compression strategies optimized for AI4’s memory hierarchy won’t transfer directly. Engineering teams that want to be ready when AI5 samples ship in late 2026 should start profiling their inference workloads against the published memory bandwidth figures now.

    Reality Check: The Hype and the Hard Limits

    ✓ Confirmed

    • Design locked, tape-out complete April 15
    • Dual-foundry (TSMC + Samsung) confirmed
    • AI4 sufficient for current FSD safety targets
    • AI5 optimized for Optimus and supercomputers
    • AI6 and Dojo 3 confirmed in development

    ⚠ Unverified

    • “40×” performance: composite metric, no independent benchmarks
    • 2027 production: already 2 years behind original promise
    • Thermal targets: 800W peak vs. 250W goal is a wide gap
    • Sensor suite remains the actual FSD ceiling, not compute
    • AI6/Dojo 3 timelines: AI6 already slipped 6 months
    The most pointed skeptical critique comes from Electrek’s Fred Lambert, who observed that “the pattern is hard to miss: Tesla keeps moving the goalpost to the next chip instead of delivering what was promised.” HW3 owners were told hardware upgrades were coming. They never arrived. HW4 owners will likely face the same calculus — AI5 requires new board architecture and thermal management that makes retrofitting existing vehicles uneconomical.

    The automotive qualification timeline is real and rarely discussed. An anonymous silicon engineer with 20+ years of ASIC experience estimated that ISO 26262 functional safety certification alone adds approximately 18 months after silicon bring-up. Even on an aggressive schedule, AI5 in production vehicles arrives no earlier than late 2028. Robots face a different certification path but their own integration challenges.

    Action Items by Audience

    ML & Software Engineers

    • Profile current inference workloads against AI5’s published bandwidth specs (5× AI4, ~1.3–1.5 TB/s est.)
    • Audit PyTorch/JAX model code for GPU-specific paths that assume legacy rasterization or ISP preprocessing
    • Follow Tesla AI’s GitHub and developer channels — SDK announcements will land before hardware samples
    • Begin quantization experiments targeting architectures without dedicated ISP pipelines

    CTOs & Tech Leaders

    • Reassess robotics pilot hardware budgets: if Tesla AI5 specs hold, NVIDIA edge GPUs may carry a 10× cost premium by 2027
    • Model a “custom ASIC” scenario in your 2028 infrastructure plan, Tesla’s move accelerates the timeline for all edge AI verticals
    • Flag HW3/HW4 fleet upgrade risk for Tesla vehicle fleets, AI5 is board-incompatible, no retrofit path announced
    • Evaluate xAI / Dojo partnership signals as a potential licensing channel for AI5-derived compute

    Frequently Asked Questions

    Tape-out is the final design handoff to a semiconductor foundry, the point at which all circuit layouts are frozen and physical masks are manufactured for silicon etching. It matters because it converts a design into a schedulable production item. But tape-out is the beginning of a long process: silicon bring-up, yield tuning, functional validation, and (for automotive applications) ISO 26262 safety certification all follow. Engineering samples typically arrive 6–9 months after tape-out; volume production follows 12–18 months after that.
    AI5 is primarily targeted at Optimus humanoid robots and Tesla’s supercomputer clusters. Musk confirmed that AI4 already achieves safety performance well above human baseline for FSD, so AI5 is not a required vehicle upgrade in the near term. AI5’s board layout and connector type differ from HW4, and its peak thermal envelope (up to 800W) exceeds what HW4 liquid cooling systems were designed for (~300W). A vehicle retrofit path is not announced. Owners of HW3 and HW4 hardware should not expect an AI5 upgrade.
    Based on projections (no independent benchmarks exist yet), a single AI5 is estimated to approach H100 inference throughput at roughly 150–250W versus the H100’s 700W TDP. Dual AI5 configurations are projected to approximate B200 performance. The key advantage is inference cost per watt, not peak FLOPS, AI5 is purpose-built for Tesla’s own model architecture, not general-purpose HPC. The “10× cheaper inference” claim assumes fully loaded deployment cost including cooling, power, and hardware amortization over Tesla-scale production volumes.
    The 40× figure is a composite metric bundling compute (8× AI4), memory capacity (9× AI4), memory bandwidth (5× AI4), and specialized accelerators optimized for Tesla’s specific neural network workloads. In those targeted workloads it may be accurate. For general-purpose inference tasks, a more conservative estimate is 5× useful compute versus a dual-SoC AI4 setup — still a major leap, but not 40×. Independent benchmarks will follow engineering sample delivery in late 2026.
    Volume production is now targeted for mid-2027. The original promise was H2 2025, making AI5 nearly two years behind schedule. The delays stem from multiple factors: Samsung Taylor fab yield challenges, thermal design iteration, and Optimus software co-development dependencies. AI6 tape-out is expected December 2026, with volume production targeting mid-2028. The pattern of accelerating chip announcements while extending production timelines is consistent across Tesla’s silicon roadmap.
    HBM offers higher memory bandwidth but at significantly higher cost and more complex packaging. For training workloads, HBM’s ceiling matters. For edge inference at scale, across millions of robots and vehicles, cost per unit and manufacturing yield matter more. Tesla’s choice of conventional GDDR6/GDDR7 on a ~384-bit interface reflects a volume-first optimization: lower cost, higher availability, less packaging complexity, and sufficient bandwidth for Tesla’s specific inference model sizes (current FSD models are ~10B parameters; AI5 is optimized for models under 250B).
    AI5’s published specs set a public benchmark that competing robotics teams must now target or surpass to justify not building custom silicon. Companies relying on NVIDIA edge GPUs for robot inference will face a growing cost and efficiency gap as AI5 enters volume production. The near-term practical impact is a raised bar for hardware roadmap planning: any robotics company that hasn’t seriously modeled a custom ASIC path now has a concrete performance-per-watt and cost-per-inference target to evaluate against.

    The Bottom Line

    Tesla’s AI5 tape-out is a genuine engineering milestone, not a vaporware announcement. The design is locked, foundry partners are committed, and the architecture makes clear strategic sense: strip out every general-purpose component, optimize every transistor for Tesla’s own inference workloads, and manufacture at a scale that makes unit economics unbeatable. The 54% U.S. EV market share Tesla held in Q1 2026 means AI5 enters volume deployment into a fleet that no competitor can match in size.

    What the next 18 months will determine: whether Samsung Taylor’s yield stabilizes fast enough to hit the mid-2027 production target; whether Tesla publishes developer tooling that lets external teams optimize for AI5’s architecture; and whether the chip’s thermal profile can be tamed to 250W in Optimus’s constrained form factor. Each of those is genuinely uncertain. The 40× headline and the stock-price pop are noise. The structural shift, Tesla operating as a vertically integrated silicon company competing at the inference layer against NVIDIA, is the durable signal. Watch the SDK announcement, not the wafer photo.

    Disclaimer: This article is based on public statements, analyst reports, and third-party technical coverage available as of April 16, 2026. Performance claims attributed to Tesla’s AI5 chip, including the “40×,” “8×,” “5×,” and “9×” figures — originate from Tesla and affiliated sources and have not been independently verified by NeuralWired. No engineering samples exist yet. Forecasted production timelines, cost estimates, and competitive comparisons are projections and subject to change. This article does not constitute investment advice.