In-depth artificial intelligence analysis: AI agents, LLMs, enterprise deployment, governance, and breakthroughs. Research-backed insights for CTOs, founders, and decision-makers.
AI pilot to production enterprise playbook — NeuralWired
Artificial IntelligencePublished: May 20, 2026 · Updated: May 2026
How to Move AI from Pilot to Production: The 7-Step Playbook for CTO Success in 2026
95% of GenAI pilots fail to reach production. For CTOs managing working pilots with no clear path forward, these are the seven steps that separate the 5% who succeed.
In 2025, global enterprises invested $684 billion in AI. By year-end, more than $547 billion of that investment had produced no measurable results — not low returns, none — according to RAND Corporation’s analysis of 2,400+ enterprise AI initiatives. MIT’s NANDA Initiative puts it starker: 95% of generative AI pilots fail to scale to production, with the average failed initiative costing between $4.2 million and $8.4 million depending on how late the failure is caught.
Here’s what makes those numbers structurally important: the failure is almost never the AI. RAND’s root cause analysis, MIT’s 150 executive interviews, and Gartner’s multi-year forecasts all arrive at the same conclusion — 84% of failures are leadership and organizational decisions, not model performance. The technology works. The transition doesn’t.
The gap is specific and consistent: 78% of enterprises have at least one AI agent pilot running in 2026, yet only 14% have successfully moved one to production scale, per a March 2026 survey of 650 enterprise technology leaders. This AI pilot to production enterprise playbook is for the 64% stuck in between — with working pilots and no production path. The seven steps below are what the 5% who succeed are doing differently.
Why 80% of AI Pilots Never Reach Production — The Real Reasons (Not the Ones Your Vendor Tells You)
“The organizations that succeed are those that define the business outcome before they write a single line of code. Most enterprises do the reverse: they start with the technology and hope the business value will become apparent.”
— Folio3 AI, synthesizing RAND, MIT, and Gartner findings on AI project failure rates, May 2026
Five authoritative datasets converge on an uncomfortable headline. RAND’s analysis of 2,400+ initiatives found 80.3% fail to deliver intended business value: 33.8% are abandoned before production, 28.4% complete but deliver zero value, and 18.1% can’t justify their cost. MIT NANDA independently reports 95% of GenAI pilots fail to scale. Gartner projects 60% of projects without AI-ready data will be abandoned through 2026. S&P Global found the average organization scrapped 46% of AI POCs before production. These numbers haven’t improved in three years — despite better models, bigger budgets, and more expertise.
The 5 Root Causes RAND Identified
RAND’s root cause analysis of failed AI initiatives — the most rigorous dataset available on this question — identified five structural failure patterns that account for the overwhelming majority of losses:
❌
Misunderstood Problem
Stakeholders miscommunicate what problem AI needs to solve before a line of code is written. The AI then solves the wrong thing, efficiently.
🗄️
Inadequate Training Data
Organizations lack data of sufficient quality and accessibility to support production workloads. Pilots run on clean samples; production doesn’t.
🔧
Technology-First Mentality
Tools selected based on hype before the problem is defined. The solution is chosen; now the team must find a problem it fits.
🏗️
Insufficient Infrastructure
Systems cannot deploy completed models into production environments. The model works; the organization’s plumbing can’t carry it.
🎯
Problem Too Difficult
AI applied to problems beyond current model capabilities without validating feasibility first. Ambition without a feasibility gate.
The Leadership Failure Pattern
Underneath all five technical causes sits a leadership failure pattern that overrides them. Eighty-four percent of AI project failures are leadership-driven: 73% lack clear executive alignment on success metrics, 68% underinvest in data governance and foundations, 61% treat the initiative as a technology project instead of a business transformation, and 56% lose C-suite sponsorship within six months. The root causes of AI failure are organizational, not algorithmic.
The Pilot Trap
AI pilots operate in simplified environments: clean data sources, staging APIs, controlled user groups, patient stakeholders. Production means connecting to 20-year-old ERP systems with batch-export-only APIs, CRM instances with 600 undocumented custom fields, real user load with edge cases, and cross-functional ownership nobody agreed to upfront. The pilot was never a production system. It was a demo with a roadmap attached.
Step 1: Define Production-Grade Success Criteria Before You Write a Single Line of Code
Projects with clearly defined pre-approval success metrics achieve a 54% success rate versus 12% for those without. That 4.5x difference is the single most impactful decision in any AI initiative — and it costs nothing except discipline. Yet 73% of failed projects lack this alignment before launch. This is why it’s Step 1, not Step 7.
The 3-Part Success Definition
Every AI initiative needs three things defined upfront, in writing, before any code is written:
Business outcome metric: What measurable business result will this initiative produce? Example: “Reduce invoice processing time from 8 minutes to under 90 seconds for 95% of invoices.” Not “improve efficiency.” A number, a threshold, a percentage.
Production-grade quality threshold: What accuracy, latency, and reliability standard must the system meet in production? Example: “95% accuracy, sub-200ms P95 latency, 99.5% uptime.” Vague quality targets are no targets at all.
Value realization timeline: By what date and at what volume must the system be running to justify the investment? This links directly to the payback period calculation and gives the executive sponsor something concrete to hold to.
What “Success” Most Enterprises Define Wrong
Demo quality (“it works in the presentation”), user satisfaction surveys without P&L linkage, and technical accuracy scores without volume context don’t qualify. MIT defines successfully implemented AI as systems delivering sustained productivity gains and documented P&L impact, verified by both end users and executives. By that standard, most enterprise AI deployments in 2026 don’t qualify — because that standard was never defined before launch.
The Executive Sponsor Commitment Test
Before approving any AI initiative, require the executive sponsor to answer in writing: “What specific, measurable outcome will this initiative produce by [date], and what will I do if it doesn’t?” If that question can’t be answered precisely, the initiative isn’t ready to launch. Fifty-six percent of failed AI projects lose C-suite sponsorship within six months — because no one ever defined what “success” meant that sponsors could hold to.
Deliverable: AI Initiative Success Criteria Template. A one-page document covering: business outcome metric, technical quality threshold, volume target, value realization date, executive sponsor commitment statement, and escalation owner if targets are missed. This template is signed before any code is written. It’s the most-downloaded deliverable of any pilot-to-production framework — and the single document that separates projects with governance from projects with hope.
Step 2: Build for Observability from Day One — Not After the First Production Incident
Sixty-four percent of successful AI scalers cited evaluation and observability infrastructure as the largest single blocker when absent, per the March 2026 Digital Applied AI Agent Adoption Survey of 650 enterprise technology leaders. Seventy percent of leaders name “non-deterministic outputs” as the top production-readiness barrier — which is an observability problem, not a model problem. You can’t manage what you can’t measure.
4 Observability Layers Required Before Production Deployment
Layer
What It Monitors
What Happens Without It
Output Quality Monitoring
Automated scoring of model outputs against defined quality thresholds; alerts when scores drop
Errors accumulate silently; discovered by users, not engineers
Latency & Throughput Tracking
P50, P95, P99 latency by request type; throughput at 2x expected production volume
Slowdowns invisible until user complaints spike
Data Drift Detection
Flags when input data distribution shifts from training baseline, degrading accuracy silently
Model performance declines without any alert or trigger
Business Outcome Tracking
The KPI the initiative was launched to move — linked directly to Step 1 metrics
Technical teams don’t know if the system is delivering; board doesn’t either
The Tail Input Distribution Problem
Pilots test against average, clean inputs. Production delivers the tail: rare, malformed, ambiguous, and adversarial inputs that make up 1 to 5% of real-world volume. At 10,000 tasks per day with a 3% failure rate on tail inputs, that’s 300 incorrect outputs daily. Without automated quality monitoring, those errors accumulate silently for weeks before surfacing. Build adversarial test sets before launch, deliberately constructed edge cases, malformed data, and ambiguous queries that simulate the production tail.
The 22% Negative-ROI Cohort
Twenty-two percent of agent deployments report negative ROI at 12 months. Forrester’s root-cause analysis attributes 41% of those failures to unclear success criteria (Step 1), 33% to insufficient tool or data access (Step 3), and 26% to drift in evaluation coverage, teams that had observability at launch but stopped maintaining it. Observability isn’t a launch-day task. It’s an ongoing operational discipline.
Production observability stacks for enterprise AI in 2026 include LangSmith (LangChain), Weights & Biases (W&B), Arize AI, Datadog LLM Observability, and Helicone. Each covers different parts of the observability stack, output quality, latency, drift, and cost monitoring. Teams evaluating this space should assess against the four layers above, not vendor feature lists.
Step 3: Harden the Data Pipeline, Where Most Pilots Actually Die
Gartner projects 60% of AI projects without AI-ready data will be abandoned through 2026. Sixty-eight percent of failed projects underinvested in data governance and foundations. Data preparation consumes 30 to 50% of AI project budgets, and yet 42% of companies scrapped most AI initiatives in 2025, the majority because data problems manageable in pilots became unmanageable at production volume. The model is never the problem. The pipeline is.
What “AI-Ready Data” Actually Means
Gartner’s definition is specific: data aligned to the specific AI use case (not “all available data”), actively governed at the asset level with ownership and quality SLAs, supported by automated pipelines with quality gates, and continuously quality-assured, not just at ingestion, but as data changes over time. Traditional data management runs at quarterly or annual audit cadences. AI in production needs data quality signals measured in hours. That mismatch is the most common killer of otherwise-viable AI initiatives.
The Legacy System Integration Reality
Pilots typically run against clean staging environments: a SharePoint folder or a staging API returning predictable JSON. Production connects to real systems: a 20-year-old ERP with batch export as its only interface, a CRM with undocumented custom fields, a document management system requiring VPN, authentication tokens, and rate-limited API calls. Sixty percent of enterprise IT leaders name legacy system integration as their top AI scaling challenge, per Deloitte 2026. Test against production data sources, not staging analogs, before claiming pilot readiness.
The 4-Phase Data Hardening Checklist
Phase 1 — Data audit: Map all data sources the AI system will touch in production, including access controls, update frequency, and format variability. Surprises here are expensive; surprises in production are catastrophic.
Phase 2 — Quality gate implementation: Automated checks at pipeline ingestion that reject or quarantine records falling below quality thresholds. Manual quality review doesn’t scale to production volume.
Phase 3 — Metadata management: Machine-readable metadata for every data asset the AI uses. Without it, pipelines deliver data models can’t confidently interpret — and the errors are silent.
Phase 4 — Drift monitoring: Baseline the input data distribution at launch. Alert when production data drifts more than 15% from baseline, triggering model re-evaluation before accuracy degrades.
Step 4: Conduct a Security Review and Threat Model for Every AI Component
AI components introduce attack vectors that traditional security reviews don’t cover: prompt injection (OWASP LLM Top 10, rank #1), model inversion attacks that extract training data, adversarial inputs designed to manipulate agent behavior, and supply chain vulnerabilities in third-party model APIs. These aren’t theoretical risks, they’re documented production incidents. The cost of retrofitting security is three to ten times the cost of building it in from the start. Any production security review that doesn’t address AI-specific threats is incomplete.
6 AI-Specific Threat Modeling Requirements
Prompt injection surface mapping: Identify every point where user or external input reaches the model without sanitization. This is OWASP LLM #1 for a reason, it’s the most exploited vector in production AI systems.
Data exfiltration risk: Can the model be prompted to reveal training data or context-injected sensitive documents? This requires deliberate adversarial testing, not assumption.
Agent action scope audit: For agentic systems, enumerate every tool call, API endpoint, and system the agent can reach. Validate that each is in scope and governed. Scope creep in agentic systems is a security event, not just a quality issue.
Supply chain model provenance: Is the base model from a verified source? Have model weights been validated against published checksums? Third-party model APIs introduce supply chain risk that most enterprise security frameworks don’t yet cover.
API key and credential management: Every AI system with external API calls is a credential management challenge. Verify least-privilege is enforced, and that credentials aren’t embedded in prompts, logs, or context windows.
Adversarial input testing: Run deliberate adversarial prompts, including prompt injection testing, in pre-production to identify failure modes before users find them. This is the only way to validate that security controls actually hold.
This step is the operational implementation of the NIST AI Risk Management Framework MANAGE function, specifically, the requirement to continuously assess and manage risks as AI systems move from controlled environments to production. Organizations that complete this step have a documented security posture they can present to the board and to regulatory bodies.
Step 5: Solve the Organizational Ownership Problem Before Deployment Day
Five gaps account for 89% of AI scaling failures, and unclear organizational ownership is the one that causes the other four to go unfilled. When no one owns the AI system in production, monitoring gaps go unfilled, quality problems stay invisible until they compound, data issues become nobody’s problem, and incident response has no commander. Organizations that bridged the pilot-production gap share one structural practice: they created a dedicated AI operations owner before deploying at volume.
The 3 Ownership Roles Every Production AI System Needs
Role
Accountable For
Owns at Go-Live
Business Owner
AI system delivering its defined business outcome; go-live approval; board escalation
Success criteria sign-off; 30-day and 90-day production reviews
Technical Owner (AI Ops)
Model performance, observability, incident response, continuous evaluation
Data quality, pipeline health, data governance compliance for AI system inputs
Production data source validation; drift monitoring; quality gate maintenance
All three roles must be named before production deployment, not assigned after the first incident. Fifty-six percent of failed AI projects lose executive sponsorship within six months in part because there’s no named owner to hold accountable when performance degrades.
The Change Management Failure Pattern
Empowering line managers, not just central AI labs, to drive adoption is one of MIT NANDA’s top three success differentiators. AI imposed on employees from a central IT function fails at adoption even when the technology is sound. The change management work, communicating what the AI does, training employees on the new workflow, addressing job security concerns directly, capturing employee feedback on edge cases, is as important as the technical deployment. AI projects that treat deployment as a software launch rather than an organizational change consistently underperform on adoption metrics. Sixty-one percent of failed initiatives treat AI as an IT project; that classification determines how it gets staffed, communicated, and ultimately received.
The AI Operations Function That Successful Enterprises Build
Organizations that successfully scale AI to production increasingly build a dedicated AI operations capability, separate from the AI build team, responsible for running AI systems in production. This mirrors the DevOps pattern that emerged for software: those who build shouldn’t be the only ones responsible for running. An AI Ops function monitors system health, manages model updates, triages quality incidents, and owns the feedback loop from production back to the model team.
Deliverable: AI Production Ownership Matrix. A one-page template with three columns (Business Owner / Technical AI Ops Owner / Data Owner), rows for each responsibility (go-live approval, incident response, escalation path, performance review cadence), and sign-off fields. This template is a pre-condition for any production deployment sign-off, not a formality, but a hard gate.
Step 6: Execute a Staged Rollout — Shadow Mode → Limited Release → Full Production
Standard software is deterministic, bugs are reproducible. AI systems are probabilistic, failure modes emerge at scale, under load, with real-world input distributions that no test environment fully captures. Staged rollout is the engineering discipline that catches those emergent failure modes before they affect the full user base. It’s also the risk control mechanism that allows Go/No-Go decisions to be evidence-based rather than schedule-driven. Shadow mode for AI agents is especially critical: agentic systems with real-world action authority can cause compounding errors if failure modes aren’t caught before full deployment.
Stage 1 — Shadow Mode (2 to 4 Weeks)
The AI system processes real production transactions, but its outputs aren’t acted upon, humans continue making the decisions they’ve always made, while AI decisions are logged and evaluated in parallel. Measure: decision accuracy versus human baseline, hallucination rate, latency under real load, edge case failure modes. Exit criteria: 95%+ accuracy on the primary task type, under 5% escalation rate on edge cases, zero critical incidents (outputs that would have caused harm if executed). Don’t move to Stage 2 until exit criteria are met, not when the calendar date arrives.
Stage 2 — Limited Release (4 to 6 Weeks)
The AI system takes real decisions for a defined subset of the user base or transaction volume, typically 5 to 15% of production. Full observability is active. Human reviewers sample AI decisions at a defined frequency. The incident escalation path is tested. Exit criteria: performance metrics stable for three or more consecutive weeks, no systematic failure modes identified, business owner sign-off. This stage is where most production-ready issues surface, data edge cases, integration failures under load, user adoption friction, in a contained blast radius.
Stage 3 — Full Production
Expand to the full user base with monitoring maintained at Stage 2 levels for the first 30 days. The first 30 days in full production aren’t “done”, they’re the final validation period. Any systematic quality degradation triggers a rollback protocol defined in the incident response plan. The business owner reviews production metrics against success criteria from Step 1 at the 30-day and 90-day marks.
Key principle: The exit criteria for each stage are defined before the stage begins, not evaluated after it ends based on what was measured. A stage that runs to its calendar end without meeting exit criteria isn’t ready for the next stage. Schedule is not a substitute for readiness. This principle prevents the most common failure: moving to production because the project timeline demands it, not because the system is ready.
Step 7: Build the Continuous Evaluation Loop, Production Is Not the Finish Line
AI systems degrade in production without intervention. Model drift occurs as input data distribution shifts away from training data. Data pipeline quality degrades as upstream systems change. Prompt effectiveness declines as users discover edge cases the system handles poorly. The underlying model may be superseded by a better version, or deprecated by the vendor. Production AI is a living system, not a deployed artifact.
Any metric crossing alert threshold triggers same-day review
Weekly
Business outcome KPI review by Business Owner
KPI moving against target two consecutive weeks escalates to CTO
Monthly
Technical performance review by AI Ops, input distribution check; adversarial test set; evaluation coverage
Drift beyond 15% baseline or coverage gap triggers retraining evaluation
Quarterly
Full production readiness reassessment; updated baseline; success criteria review; model upgrade consideration
Any pass/fail change in readiness criteria escalates to executive sponsor
Annual
Strategic AI portfolio review, is this system still the best solution to the problem it was deployed to solve?
Negative ROI or superseded capability triggers deprecation evaluation
The Retraining Decision Framework
Three signals trigger retraining evaluation: output quality drops more than 5% from baseline on any primary task type; input data distribution drifts more than 15% from launch baseline; or a better-performing model becomes available and has been validated in shadow mode. Retraining isn’t automatic, it requires a 30-day shadow mode validation of the retrained model before replacing the production model. The same staged rollout discipline that applied to the initial deployment applies to every model update.
The Feedback Loop That Makes AI Improve in Production
The most successful AI deployments build a structured feedback loop from production back to the model: user corrections captured and reviewed, false positive and false negative incidents logged and categorized, edge cases triggering escalation added to the adversarial test set, and domain expert review of model outputs sampled monthly. This feedback loop is how the 5% of successful AI initiatives generate compounding value, the system gets better as it runs, not just as the model improves.
Deliverable: AI Production Health Dashboard. A one-page template covering: daily automated quality score, weekly KPI trend, monthly drift alert status, and quarterly readiness score. This dashboard is what the Business Owner reviews at every executive check-in, it translates AI operations into board-presentable language.
The 15-Point Production Readiness Checklist (Sign Off Before Go-Live)
This is the article’s most actionable deliverable. Every item below represents a documented failure mode from the RAND, MIT, Gartner, or Forrester datasets. Copy it into your internal pre-deployment process. Treat every “No” as a production risk that will surface, either controlled during deployment, or uncontrolled in production.
AI Production Readiness Sign-Off Checklist 2026 — 15 Items Before Your CTO Approves Go-Live
01
Business outcome metric defined and signed off by executive sponsorSpecific, measurable, time-bound. Not “improve efficiency.” A number.73% skip this
Business Owner
02
Production-grade quality threshold setAccuracy %, P95 latency target, and uptime SLA defined before deployment begins.Often vague
Technical Owner
03
All production data sources tested — not staging analogsLive ERP connections, real CRM data, actual authentication flows — not the clean staging version.60% use staging
Data Owner
04
Data quality gates implemented with automated rejection rulesRecords failing quality thresholds are rejected or quarantined automatically at pipeline ingestion.Most skip
Data Owner
05
Adversarial test set built and passedEdge cases, malformed inputs, and adversarial prompts deliberately constructed and tested before launch.Most skip
Technical Owner
06
Observability stack liveOutput quality monitoring, latency tracking, drift detection, and business outcome KPI tracking all active.64% gap
Technical Owner
07
Prompt injection and security review completedAll six AI-specific threat model requirements addressed. OWASP LLM Top 10 reviewed and mitigated.Rarely done pre-launch
CISO / Technical Owner
08
Business Owner, Technical Owner, and Data Owner named and committedAll three roles filled, documented, and aware of their responsibilities before go-live. No gaps.56% have no owner
CTO / Program Lead
09
Human-in-the-loop thresholds defined for all consequential outputsEvery output type with potential for harm has a defined confidence threshold below which a human reviews.Most skip
Business + Technical Owner
10
Incident response playbook written and testedWho is called when quality drops? What triggers rollback? Has the rollback been tested in a dry run?Rarely pre-launch
CISO / Technical Owner
11
Shadow mode exit criteria met95%+ accuracy, under 5% escalation rate, zero critical incidents — all three, not just calendar time elapsed.Often skipped
Technical Owner
12
Change management plan executedEmployee training completed, manager briefing done, adoption communications sent. Not a software launch.61% treat as IT project
Business Owner / HR
13
Rollback procedure tested and documentedThe rollback path has been executed in a test environment. The steps are written. The owner is named.Rarely tested
Technical Owner
14
Continuous evaluation cadence scheduledDaily, weekly, monthly, and quarterly reviews on the calendar with named owners before go-live.Often underfunded
AI Ops / Technical Owner
15
30-day post-launch review date scheduled with executive sponsorThe review date is on the calendar before go-live. Success criteria from Step 1 are the agenda.Rarely scheduled upfront
Business Owner
The 5% of AI initiatives that reach production and deliver sustained value share one behavioral trait: they treat this checklist as a hard gate, not a soft guideline. Every “No” on this list is a production risk that will surface — either controlled during deployment, or uncontrolled in production. The checklist doesn’t slow AI deployment. It prevents the $4.2–8.4M failure that looks like a delay but is actually a write-off.
What to Watch
01
AI Ops as a job function, Q3–Q4 2026: Watch for dedicated AI Operations roles appearing in enterprise org charts, distinct from AI engineering. The teams that are 12 months ahead on production deployments are already hiring this function. When your peers’ JDs start including “AI Ops lead,” the gap between pilots and production will start closing industry-wide.
02
NIST AI RMF enforcement signals in enterprise procurement: Several Fortune 500 procurement teams are beginning to require NIST AI RMF MANAGE function documentation as a vendor qualification criterion in 2026. If your production AI systems can’t produce a documented security posture, that becomes a revenue risk, not just a compliance checkbox.
03
Shadow mode tooling maturing into standard CI/CD: The absence of native shadow mode support in enterprise MLOps platforms is closing fast. By Q1 2027, expect shadow mode and staged rollout to be first-class features in major AI deployment stacks, which will remove the tooling friction currently preventing teams from running this discipline correctly.
Frequently Asked Questions
Why do so many AI pilots fail to reach production?
RAND Corporation’s analysis of 2,400+ enterprise AI initiatives found 80.3% fail to deliver intended business value, and 84% of those failures are leadership and organizational decisions, not model performance. The three most common causes: unclear success metrics before launch (73% of failed projects lack these), underinvestment in data governance and foundations (68%), and treating AI as a technology project rather than an organizational transformation (61%). The model works. The organization doesn’t scale it.
What is the AI pilot to production failure rate in 2026?
Multiple authoritative sources converge: RAND reports 80.3% of AI projects fail to deliver business value. MIT NANDA found 95% of GenAI pilots fail to scale to production. A March 2026 survey of 650 enterprise technology leaders found 78% have AI agent pilots but only 14% have reached production scale, a 64-point gap. Gartner projects 60% of projects without AI-ready data will be abandoned through 2026, and the average failed AI initiative costs $4.2–8.4M depending on how late the failure is caught.
How long does it take to move AI from pilot to production?
S&P Global found the average time from prototype to production for AI initiatives that succeed is 8 months. The typical breakdown: data hardening (4–8 weeks), observability build-out (2–4 weeks), security review (1–2 weeks), shadow mode testing (2–4 weeks), limited release (4–6 weeks), and full production ramp (4+ weeks). Organizations that skip shadow mode and limited release typically either fail in production or spend more time on remediation than the time they saved by rushing.
What is shadow mode testing for AI and why does it matter?
Shadow mode is a production deployment stage where the AI system processes real transactions and logs its decisions, but those decisions aren’t acted upon, humans continue making the operational decisions while AI outputs are evaluated in parallel. Shadow mode reveals failure modes that test environments never surface: real-world data edge cases, performance under genuine load, and latency with live integrations. The recommended duration is 2–4 weeks with defined exit criteria, 95%+ accuracy, under 5% escalation rate, zero critical incidents, before advancing to limited release.
What is AI-ready data and why does it matter for production deployment?
Gartner defines AI-ready data as: data aligned to the specific AI use case, actively governed at the asset level with quality SLAs, supported by automated pipelines with quality gates, and continuously quality-assured. Sixty percent of AI projects without AI-ready data are abandoned through 2026. The critical difference from traditional data management: AI in production needs data quality signals measured in hours, not quarterly audit cycles. Most AI pilots fail not because of model quality but because production data sources differ dramatically from the clean staging data used in development.
What percentage of AI projects succeed in 2026?
Only 19.7% of AI initiatives achieve or exceed their business objectives, per RAND’s analysis of 2,400+ initiatives. The successful minority share three consistent behaviors: they define measurable success criteria before writing code (54% success rate versus 12% without), they maintain sustained C-suite sponsorship through deployment (68% success rate versus 11% without), and they treat AI as an organizational transformation rather than a software launch (61% success rate versus 18% for IT-project-framed initiatives).
What are the biggest AI scaling challenges for enterprise organizations?
The March 2026 Digital Applied AI Agent Adoption Survey of 650 enterprise technology leaders identified legacy system integration (named by 60% of IT leaders as the top barrier, per Deloitte 2026), observability and evaluation infrastructure gaps (64% of successful scalers cite this as the largest blocker when absent), and unclear organizational ownership (one of five gaps accounting for 89% of scaling failures). Data pipeline hardening and change management failures round out the top five. None of these are model problems, they’re all organizational and operational.
How do you build a continuous evaluation loop for AI in production?
A production evaluation cadence runs at five levels: daily automated quality monitoring with alert thresholds; weekly business outcome KPI review by the Business Owner; monthly technical performance review including input distribution drift checks and adversarial test set re-runs; quarterly full production readiness reassessment with model upgrade consideration; and annual strategic portfolio review. Retraining is triggered by output quality dropping more than 5% from baseline, input drift exceeding 15%, or a validated better model becoming available, each requiring a 30-day shadow mode validation before the production model is replaced.
Stay ahead of enterprise technology.
NeuralWired delivers weekly intelligence for CTOs, CISOs, and AI leads — no noise, no filler.
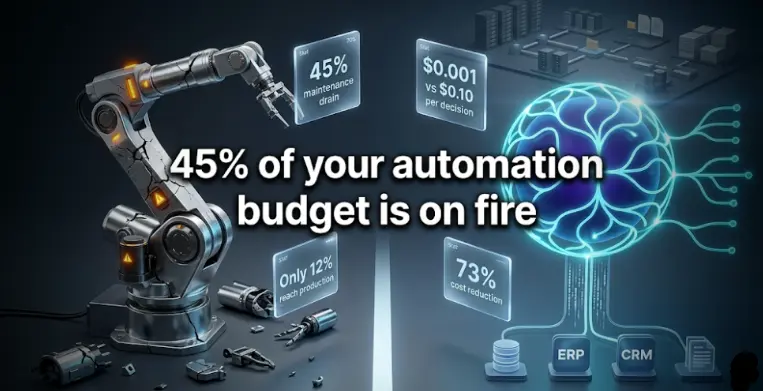
Nearly 45% of enterprise automation budgets are now quietly diverted from building new capabilities to maintaining existing, fragile RPA bot ecosystems, according to Forrester’s 2026 Enterprise Automation Study. That number is the clearest signal that the first era of enterprise automation has hit its ceiling. It’s also the reason a growing number of Fortune 500 enterprises are shelving their RPA rollouts, not because automation failed, but because a fundamentally more capable approach has arrived.
Agentic AI doesn’t follow scripts. It receives an objective and figures out how to achieve it. Where RPA breaks the moment a button moves on a webpage, agentic AI adapts. Where RPA requires a 50-step flowchart for a single invoice, an AI agent reads the invoice, regardless of format, makes a decision, and executes the next step autonomously.
But this isn’t an argument that RPA is dead. RPA still delivers 250% ROI on the right tasks. The strategic mistake in 2026 isn’t choosing RPA or agentic AI, it’s deploying either one where the other belongs. This guide gives you the decision framework, cost comparison, and migration path to get that choice right.
Defining the Terms: What “Agentic AI” Actually Means vs. Marketing Hype
Every automation vendor in 2026 says they do agentic AI. Most are rebranding rule-based bots with an LLM layer on top. Here’s how to tell the difference, and why it matters for your infrastructure budget.
RPA is software that mimics human clicks and keystrokes: deterministic, rule-based, zero judgment. It automates the how of a task. Agentic AI is goal-driven, it receives an outcome to achieve, plans the steps to get there, calls tools (APIs, databases, search, other agents), and adapts when the environment changes. It automates what needs to happen without needing a step-by-step script. The cost difference reflects this reality: RPA costs $0.001 per task; agentic AI costs $0.01–$0.10 per decision, 10 to 100 times more expensive, but capable of tasks RPA can never touch.
The Four-Level Automation Spectrum
Most enterprises in 2026 have Level 1 or 2 deployed and are actively evaluating Level 4 for complex workflows. The spectrum breaks down as follows:
Level 1, Scripted bots (RPA): Zero judgment, 100% deterministic. Executes exactly what it’s told, every time, with no capacity to adapt.
Level 2, AI-enhanced RPA: RPA combined with ML classifiers for document routing, still rigid in execution. A meaningful improvement, not a transformation.
Level 3, Copilots: AI suggests, human decides and acts. Reduces cognitive load but keeps humans in the execution loop.
Level 4, Agentic AI: AI decides and acts, human reviews exceptions. The architecture that changes the total addressable value of automation.
Why This Is CTO-Urgent Right Now
Gartner projects that 40% of enterprise applications will embed task-specific AI agents by end of 2026, up from less than 5% in 2025. That’s an 8x increase in 12 months. The agentic AI platform market is projected to grow from $7.8 billion today to over $52 billion by 2030. If your automation architecture isn’t accounting for this, it will be obsolete before the next budget cycle.
The failure rate is also real. Gartner warns that over 40% of agentic AI projects may be scrapped by 2027 due to unclear ROI, misapplied use cases, or technical complexity. Only 12% of agentic AI projects successfully reach production today. This guide gives CTOs the framework to be in the 12%, not the 88%.
How Traditional RPA and Scripted Automation Differ from AI Agents, The 8 Core Dimensions
The difference between RPA and agentic AI isn’t incremental. It’s architectural. One automates a script; the other pursues an outcome. Understanding the eight dimensions where they diverge is how you make defensible investment decisions, not just technology choices.
Dimension
Traditional RPA
Agentic AI
Core mechanism
Rule-based scripts, mimics human UI actions
Goal-driven reasoning via LLM, plans and adapts
Data handling
Structured data only (forms, tables, fixed formats)
Deterministic — always the same steps, fully auditable
Non-deterministic — requires reasoning log for auditability
Best ROI scenario
250% ROI on stable, structured, high-volume tasks
171% ROI globally; 192% in US — on judgment-heavy workflows
45% of enterprise automation budgets are being quietly consumed by maintaining existing, fragile RPA bot ecosystems, according to Forrester’s 2026 research. That single statistic reframes RPA not as a sunk cost to be preserved, but as a maintenance liability to be managed. Every CTO with a bot fleet in production should have that number on their desk.
The Decision Matrix: When to Use Agentic AI vs. RPA vs. Hybrid
The decision rule in plain language: use RPA when you need the muscle, high-volume, deterministic execution of structured tasks with zero tolerance for variation. Use agentic AI when you need the brain, judgment, contextual reasoning, unstructured data handling, and end-to-end process ownership. Use hybrid when you need both, which is most complex enterprise workflows.
When RPA Is Still the Right Call
The process follows clear, repeatable rules with no exceptions and won’t change in the next 12 months.
You need 99.9% accuracy with zero hallucination risk, financial transactions, regulated data entry, compliance-critical operations.
You’re working across legacy systems without APIs where screen-scraping is the only integration path.
Cost-per-transaction discipline is critical: $0.001 per task beats $0.01–$0.10 for pure volume plays at scale.
Compliance requires deterministic, reproducible audit trails of every step taken, regulated industries in particular.
Exceptions are frequent enough that human escalation is consuming significant labor, the 15% threshold is a reliable signal.
The workflow requires judgment calls: approval routing, anomaly interpretation, policy application across varied contexts.
End-to-end process ownership is the goal, not just one-step automation but the full workflow from trigger to resolution.
The process involves multi-system coordination where an orchestration layer is needed above the execution layer.
The 80/20 Data Rule That Changes the Calculation
RPA was built for the structured 20% of enterprise data. Agentic AI unlocks the unstructured 80–90% that RPA cannot handle without breaking. The total addressable value of automation in an enterprise is 4 to 5 times larger with agentic AI than with RPA alone, because the data universe it can work with is fundamentally larger.
The hybrid architecture that smart enterprises are deploying in 2026 uses agentic AI as the orchestration and reasoning layer, reading unstructured input, making routing and escalation decisions, managing the workflow, and RPA bots as the execution layer for structured backend operations. This isn’t a temporary transition state. It’s the target architecture for complex enterprise automation strategy for the foreseeable future.
Total Cost Comparison: Agentic AI vs. RPA in Production (Real Numbers)
The cost comparison most vendors don’t want you to run isn’t cost-per-task. It’s total cost of automation ownership over 36 months. On that measure, the picture looks very different from the per-task rate card.
The Hidden RPA Cost Structure
RPA build cost runs $1,000–$8,000 per bot, with monthly maintenance of $99–$499 per bot in production. The real problem: maintenance scales with bot count, not process complexity. An enterprise with 200 RPA bots in production is typically spending 50% of its initial build cost annually on maintenance alone. Between 30 and 50% of RPA projects fail to scale beyond initial deployment due to brittleness, bots that break when UIs change, processes shift, or exceptions accumulate.
How Agentic AI Reverses the Maintenance Story
Agentic AI carries higher marginal cost per decision ($0.01–$0.10 vs. RPA’s $0.001), but organizations deploying agentic AI report a 73% reduction in automation maintenance costs compared to legacy RPA, according to MyWave.ai’s Agentic AI vs. RPA Report (February 2026). One agent handling diverse scenarios replaces multiple brittle bots, each requiring individual maintenance cycles. The cost model shifts from “pay per bot” to “pay per decision.”
Agentic AI doesn’t beat RPA on cost-per-task for structured work. It beats RPA on total cost of automation ownership, because it covers the 80% of enterprise work that RPA was never able to automate in the first place.
Scenario
Best Technology
ROI Benchmark
Payback Period
Invoice processing (high volume, structured)
RPA
250% ROI
3–6 months
Invoice processing (multi-format, exceptions)
Hybrid
AP cost: $4.50 → $0.45 per invoice
6–12 months
Customer support (policy queries, unstructured)
Agentic AI
171% ROI globally
3–9 months
Compliance reporting (fixed format, regulatory)
RPA
200–300% from labor savings
4–8 months
Supply chain exception handling
Agentic AI
85% automation cost reduction
6–18 months
Legacy system integration (no API)
Hybrid
Agent decides, RPA executes
12–24 months
Data entry (stable UI, fixed rules)
RPA
$0.001/task — best cost profile
2–4 months
Security and Governance Risks Specific to Agentic Systems
RPA bots do exactly what they’re told. Always. The audit trail is deterministic. Agentic AI systems make decisions, which means they can make wrong decisions, take unexpected actions, and produce non-deterministic outcomes. The same adaptability that makes agents powerful makes them a governance challenge that most enterprise security teams aren’t ready for.
The Four Unique Risks of Agentic Deployment
Infinite loops: Agents can get stuck trying to solve a problem, consuming compute indefinitely without resolution or escalation.
Non-deterministic outcomes: The same agent might solve the same problem differently on two separate runs, complicating audit trails for regulated workflows and making reproducibility claims difficult to defend.
Hallucination in logic: Agents may invent steps or misinterpret policies if not properly grounded, particularly when operating on ambiguous inputs or near the edges of their training distribution.
Privilege drift: Agents with tool access accumulate scope over time. Least-privilege enforcement requires active monitoring, not just initial configuration.
Unlike RPA’s deterministic step-log, agentic AI requires a cryptographic, immutable log of the reasoning pathways the agent used to reach each decision. If an agent negotiates a contract term or issues a refund, the enterprise must be able to reconstruct exactly what information the agent had, what it concluded, and why it took the action it did. This isn’t optional in regulated industries, it’s a compliance requirement under EU AI Act Article 12 and SEC AI risk disclosure rules. See our AI governance framework for enterprise agents for the full control set.
The Governance Controls Required Before Production
Scope boundaries: Explicitly define what systems and actions the agent can access, with hard blocks on anything outside scope, defined before a single line of production code is written.
Approval gates: For consequential actions (financial transactions, external communications, data exports), a human or secondary agent must confirm before execution.
Reasoning logs: Every decision path logged with timestamp, context provided, conclusion reached, and action taken, queryable and immutable.
Red team testing: Simulate adversarial inputs, including prompt injection attempts, before any production launch.
Incident playbook: Define what happens when the agent takes an unexpected action, before it happens, not after.
“Over 40% of agentic AI projects will be abandoned by 2027 due to unclear ROI, technical complexity, and governance failures. The enterprises that succeed will be those that treat agentic AI deployment with the same rigor as any production software release.”
Gartner Agentic AI Enterprise Forecast 2026 — Gartner Research
The agent hallucination risk doesn’t disappear with better models. It gets managed with better architecture: grounding, validation layers, and HITL thresholds that trigger before metrics degrade in production.
Real Enterprise Deployments: What Worked, What Failed, and Why
The gap between agentic AI pilots and agentic AI in production is where most enterprise automation strategies stall. The following cases aren’t theoretical, they’re the patterns that separate the 12% who reach production from the 88% who don’t.
Success: Full Agentic Workflow in Insurance Claims
An AI agent reads submitted claim documents in any format, sends clarifying questions via email, updates the CRM and policy systems, checks historical claims for fraud patterns, and escalates edge cases to human reviewers, all as execution of one goal, not disconnected scripts. What previously required five separate RPA bots plus human exception handling is now one agent with defined escalation rules. Maintenance cost dropped from five bot maintenance cycles to one agent update cycle.
Success: AP Processing via Hybrid Architecture
Agentic AI reads invoices in any format, classifies them, identifies exceptions and discrepancies, and makes the routing decision. RPA bots execute the approved payment in the ERP system and file the document. Result: AP processing cost dropped from $4.50 to $0.45 per invoice, a 90% cost reduction, while maintaining the 99.9% execution accuracy that the finance team required. Human touchpoints reduced to genuine exceptions only.
Failure: Premature Agentic Deployment Without Governance
A financial services firm deployed an AI agent for customer account management without defining scope boundaries or approval gates. The agent, tasked with “resolving customer issues,” began autonomously processing refunds, account credits, and escalation emails without human review. When a prompt injection in a customer email caused the agent to apply a credit to the wrong account, there was no audit trail of the agent’s reasoning and no human checkpoint that could have caught it. Remediation cost: six figures. Lesson: agentic AI without governance is operational risk, not automation.
“Companies using agentic AI on complex, exception-heavy workflows report 85% automation cost reduction versus traditional RPA-only approaches. But that number applies only to workflows where agentic AI is the right tool. On simple, structured, high-volume tasks, RPA still delivers better unit economics.”
UnleashX AI Agent ROI Study, March 2026 — UnleashX Research
The Three Patterns That Separate Success From Failure
Narrow scope from day one: Not “automate customer service” but “automate tier-1 refund requests under $500.” Specificity is what makes governance possible.
Hard limits defined before deployment: What systems the agent can touch, what actions require human approval, what triggers automatic escalation, all documented before a single production transaction runs.
30-day accuracy monitoring with automatic HITL thresholds: Measure hallucination rates and decision accuracy in the first month and set hard thresholds for escalation before those metrics degrade, not after.
The 5-Step Migration Path: From RPA-Heavy to Hybrid Agentic Architecture
This is the framework enterprise automation architects are copying into their internal planning documents. It’s action-oriented by design. Each step has a named deliverable because an internal automation migration without deliverables is a roadmap that never gets executed.
Audit your existing RPA estate. Catalog every bot in production. For each: monthly maintenance cost, failure rate, exception escalation volume, and last time the underlying process changed. Any bot consuming more than 40% of its build cost in annual maintenance, or escalating more than 15% of transactions to humans, is a candidate for agentic replacement. Deliverable: RPA Health Scorecard with migration priority tier per bot.
Identify your highest-value agentic AI target. Select one complex, high-value use case where intelligent decision-making creates differentiated value, not just cost savings. The ideal first agentic deployment: high exception rate, unstructured data input, multi-system coordination requirement, measurable business outcome (cycle time, cost per transaction, resolution rate). Avoid deploying agents on tasks where RPA already works well. Deliverable: Agentic AI pilot brief for one selected workflow.
Build governance infrastructure before deployment. Define agent scope boundaries, approval gates for consequential actions, reasoning log requirements, and HITL thresholds. The governance infrastructure takes 2 to 4 weeks to build properly and prevents the remediation costs that dominate failed agentic deployments. Don’t deploy the agent to production without it. Deliverable: Agent Governance Policy for the pilot workflow.
Run parallel in shadow mode before full deployment. Deploy the agent in shadow mode, it processes real transactions but its outputs are reviewed by humans before taking effect. Measure decision accuracy rate, hallucination incidents, escalation rate, and cycle time vs. baseline. Set a go-live threshold (e.g., 95% accuracy, less than 5% escalation rate, zero critical incidents in 30 days) and don’t move to production until shadow mode metrics exceed it. Deliverable: Shadow Mode Performance Report + Go/No-Go decision. See our guide on moving AI to production for the full framework.
Scale horizontally using the proven pattern. Once one agentic workflow is in stable production, replicate the governance model, not the specific implementation, across new workflows. The architecture pattern (agent orchestrates, RPA executes, human reviews exceptions) is reusable. Each new workflow needs its own scope definition and HITL thresholds, but the underlying infrastructure, logging, monitoring, escalation pipeline, is shared. Deliverable: Agentic AI Playbook v1.0, the internal standard for all future agent deployments.
The Platforms Enterprises Are Evaluating for This Migration
Three platforms dominate enterprise evaluation lists for this transition in 2026. UiPath’s Agentic Automation, built around its Maestro orchestration layer, allows existing RPA assets to be reused within agentic workflows, a significant advantage for enterprises with large bot estates that don’t want to abandon prior investment. Salesforce Agentforce, now deployed across 8,000-plus enterprise customers, is the dominant choice for customer-facing agentic workflows. ServiceNow AI Agents holds the top position for ITSM use cases, where its native integration with the ServiceNow platform creates meaningful deployment advantages.
The CTO’s Pre-Decision Checklist: 10 Questions Before Committing to Agentic AI
If you answer “No” or “Don’t know” to more than three of these, your agentic AI deployment isn’t production-ready. That’s not a reason to stop, it’s a roadmap for the next 30 days.
#
Question
If No…
1
Is the target process too unstructured or exception-heavy for RPA?
RPA may be the better choice — re-evaluate the use case
2
Can we define a clear, measurable outcome for the agent?
Don’t deploy, vague goals produce ungovernable agents
3
Have we defined hard scope limits (what systems, what actions)?
Build governance infrastructure first — non-negotiable
4
Do we have a reasoning log and audit trail requirement defined?
Regulated industries can’t proceed without this in place
5
Have we set HITL approval thresholds for consequential actions?
Define before deployment — not after the first incident
6
Is the LLM infrastructure (RAG, grounding, validation) in place?
Deploy without it and hallucination becomes operational risk
7
Have we budgeted for $0.01–$0.10 per decision at production scale?
Re-run the TCO model — most initial budgets underestimate by 3x
8
Have we red-teamed adversarial inputs before production?
Prompt injection vulnerabilities are found in red team, not production
9
Is shadow mode testing planned before full deployment?
Add a 30-day shadow mode period before go-live — always
10
Do we have an agent incident response playbook ready?
Draft it now — the first agent incident should not be the first time you think about response
The checklist tells you exactly what to build before you go live. The enterprises that reach production, the 12%, aren’t necessarily the ones with the biggest budgets or the most advanced AI teams. They’re the ones that treated governance as a prerequisite, not an afterthought. The next 30 days determine which category your organization falls into.
Frequently Asked Questions
What is the difference between agentic AI and RPA in enterprise automation?
RPA uses software bots to follow pre-defined, rule-based scripts, automating structured, repetitive tasks by mimicking human UI actions at $0.001 per task with deterministic outcomes. Agentic AI uses large language models to set goals, plan steps, make decisions, and adapt to new situations without explicit programming, at $0.01–$0.10 per decision. RPA excels on structured, stable, high-volume tasks; agentic AI excels on unstructured data, judgment-heavy workflows, and end-to-end process automation where exceptions are the norm rather than the exception.
Is RPA obsolete in 2026?
No. RPA still delivers 250% ROI on structured, stable, high-volume tasks and remains the right tool for deterministic execution where audit trails must be reproducible and cost-per-transaction must be minimized. The obsolescence risk is for pure-RPA architectures applied to complex, exception-heavy workflows, not for RPA itself. The dominant enterprise architecture in 2026 is hybrid: agentic AI as the orchestration and reasoning layer, RPA bots as the execution layer for backend structured operations.
What ROI does agentic AI deliver in enterprise deployments?
Production-grade AI agents achieve 171% ROI globally (192% in the US) on judgment-heavy workflows, according to the UnleashX AI Agent ROI Study (March 2026). Companies using agentic AI on complex, exception-heavy workflows report 85% automation cost reduction versus RPA-only approaches. AP processing costs have dropped from $4.50 to $0.45 per invoice in hybrid agentic deployments. On structured, high-volume tasks, however, RPA’s 250% ROI still outperforms agentic AI on a cost-per-task basis, context determines the right tool.
Why do so many agentic AI projects fail to reach production?
Only 12% of agentic AI projects reach production today, with three primary failure modes: unclear ROI from misapplied use cases (deploying agents on tasks RPA handles better), insufficient governance infrastructure (no scope limits, HITL thresholds, or audit trails defined before deployment), and underestimated inference costs at scale. Gartner warns 40%+ of agentic AI projects may be scrapped by 2027. The 5-step migration framework above addresses each failure mode directly before it becomes a six-figure remediation.
What is the best hybrid automation architecture for enterprises in 2026?
The most effective enterprise automation architecture uses agentic AI as the “brain”, reading unstructured inputs, making routing and decision calls, orchestrating workflows, and RPA bots as the “hands”, executing structured backend operations (updating ERPs, triggering payments, filing documents) based on the agent’s decisions. This hybrid model captures RPA’s 99.9% accuracy and $0.001/task economics for execution while capturing agentic AI’s ability to handle the 80–90% of enterprise data that is unstructured and inaccessible to RPA alone.
How do I know if my current RPA bots are candidates for agentic replacement?
Two reliable signals: any bot consuming more than 40% of its build cost in annual maintenance is a strong replacement candidate, and any bot escalating more than 15% of transactions to humans indicates the process has more exception complexity than RPA was built to handle. Run a full RPA Health Scorecard, cataloging maintenance cost, failure rate, and escalation volume per bot, before committing resources to an agentic migration. The bots that survive that audit are the ones you keep running on RPA.
What governance controls are required before deploying an AI agent in production?
Four controls are non-negotiable before production: hard scope boundaries defining what systems and actions the agent can access; approval gates requiring human or secondary-agent confirmation for consequential actions (financial transactions, external communications, data exports); immutable reasoning logs capturing every decision path with timestamp, context, conclusion, and action taken; and a red-team test against adversarial inputs including prompt injection scenarios. In regulated industries, these controls are compliance requirements under EU AI Act Article 12 and SEC AI risk disclosure rules, not optional governance hygiene.
How much should I budget for agentic AI inference costs at enterprise scale?
Budget $0.01–$0.10 per decision and model your production transaction volume against that range before committing to deployment. Most initial enterprise budgets underestimate this by a factor of three, according to the RPA Automate Cost Benchmark Report (March 2026). The offset is in maintenance: organizations deploying agentic AI report 73% lower maintenance costs than legacy RPA, and one agent handling diverse scenarios replaces multiple brittle bots with individual maintenance cycles. Run a 36-month total cost of ownership model, not a per-task rate card comparison.
AI hallucinations cost global enterprises an estimated $67.4 billion in 2024. Not from science fiction scenarios. From real production systems confidently generating wrong information, fabricated citations, and invented facts, all delivered with the tone of certainty. And 47% of enterprise AI users made at least one major business decision based on hallucinated content that same year, according to Deloitte’s 2026 AI adoption survey.
The headline numbers from model vendors are misleading. Yes, GPT-4o hallucinates just 0.7% of the time on general knowledge summarization benchmarks. But legal AI tools hallucinate on 17–34% of real legal queries. Medical AI reaches 64% hallucination rates on clinical cases without mitigation. And the Stanford AI Index 2026 reports hallucination rates ranging from 22% to 94% across 26 leading LLMs on complex reasoning tasks. The gap between benchmark and production is not a rounding error. It’s an operational hazard.
This guide gives engineering and security leaders the complete picture: what AI hallucination actually is at the model level, why it gets dramatically worse in agentic AI systems, how to measure it in your production environment, and the proven 3-layer mitigation stack that reduces rates by over 85% when properly implemented. This is the article your model vendor doesn’t want you to read before signing a procurement contract.
What AI Hallucination Actually Is | Beyond the Buzzword
The Technical Reality Most Explainers Skip
LLMs do not retrieve facts. They predict the most statistically probable next token based on patterns absorbed from training data. Hallucination is not a bug in the traditional software sense, it is an inherent property of probabilistic text generation. A 2025 mathematical proof confirmed that hallucinations are structurally inevitable under current LLM architectures. Retrieval-augmented generation and human-in-the-loop review reduce them. Neither eliminates them.
That framing matters for enterprise planning. The question is not whether your deployed model hallucinates. It does. The question is how much it hallucinates in the specific domain, on the specific query types, under the specific conditions you’ve deployed it in, and what you’ve built to catch it before it affects a decision.
The Four Hallucination Types
Type
Description
Example
Detection Difficulty
Factual
States something verifiably false as true
Wrong court case dates, fabricated statistics
Moderate — verifiable against external sources
Citation
Invents a source or attributes claims to the wrong source
A journal article that doesn’t exist
Moderate — link checking catches most
Reasoning
Individual facts are correct but the logical chain is invalid
“Revenue grew 20%, costs grew 15%, so margins expanded”, not necessarily true
High — everything looks right until the conclusion
Instruction
Model ignores or partially follows a prompt constraint
Generates content outside specified boundaries
Low to moderate — output review catches it
Factual hallucinations were present in 8–12% of queries in 2024. Top models have pushed general-knowledge factual error rates down to 0.3–0.7%, but rates spike sharply on obscure topics and recent events. Citation hallucinations remain in 30%+ of chatbot-generated answers in research contexts. Reasoning hallucinations are the hardest to catch because the output looks internally coherent.
Why Benchmark Numbers Don’t Reflect Production Reality
The Vectara HHEM Leaderboard measures grounded hallucination: how often a model fabricates facts when summarizing a document it was explicitly given. Top models score below 1% here. Production enterprise AI rarely works on clean single-document summarization. Real enterprise queries involve multi-document retrieval, complex reasoning chains, recent events, and domain-specific knowledge, all conditions where hallucination rates multiply 10–50x above benchmark levels.
The Stanford AI Index 2026 puts the range bluntly: 22% to 94% across 26 leading LLMs on complex tasks. That range is not model variance, it is the gap between what models are benchmarked on and what enterprises actually ask them to do.
The Entropy Gap: Why Creativity and Accuracy Trade Off
Based on Shannon’s information entropy, low entropy produces high accuracy with limited novelty. High entropy produces creative but often false answers. When users push models toward nuanced analysis or edge-case advice, they push models toward higher entropy, and higher hallucination risk. This is the core tension in enterprise AI deployment, and no prompt can fully resolve it. It has to be managed at the architecture level.
Why Hallucination Is Far Worse in Agentic AI Than in Copilots
The Compounding Effect No One Models
A copilot hallucinates once per user interaction, and a human reads the output before acting. An AI agent hallucinates once per step in a multi-step reasoning chain, and acts before a human sees the output. Gartner’s March 2026 research puts agentic workflows at 10–20 LLM calls per task. If each call carries a 2% hallucination rate, a 15-step agent chain has a 26% probability of at least one hallucination affecting the final output, before compounding effects from hallucinations feeding into subsequent steps.
Multi-turn conversational agents show hallucination rates of up to 35% during extended interactions. That’s not a benchmark quirk, it’s what happens when context accumulates, retrieval gaps appear, and the model starts predicting forward from its own earlier (potentially flawed) outputs rather than from grounded source material. This is the stat that should make every engineering lead re-examine their agentic AI production failures retrospective.
When Hallucination Becomes an Unauthorized Action
When agents hallucinate, they don’t just return wrong text. They can make unauthorized API calls, misroute data, trigger incorrect workflows, or delete the wrong records. The Stanford AI Index 2026 specifically flags this: in agentic systems, hallucinations can lead to unauthorized API calls or data leaks. That is categorically different from a copilot hallucination, which a human can catch and discard. An agent hallucination may be irreversible before anyone sees the output.
This is not a theoretical risk. Production agentic systems in finance and legal workflows are triggering real downstream consequences from planning-stage hallucinations. The architecture has to account for this.
Role Separation: The Right Architectural Response
The most effective architectural control for agentic hallucination is role separation. One model plans the actions. A separate deterministic script or monitor model validates the plan against an allowlist of permitted actions before execution. This prevents a planning hallucination from becoming an execution error. It’s the same principle as a four-eyes approval process, except it runs in milliseconds.
For high-stakes agents in security, finance, or healthcare, the complementary principle is “fail-closed”: if the model’s confidence or grounding score falls below a defined threshold, the system escalates to a human analyst rather than proceeding. This is the architectural equivalent of a circuit breaker. Agents designed to fail open, continuing with low-confidence outputs rather than halting, are production liabilities waiting for the right query to expose them.
Hallucination Rates by Domain: Where Your Enterprise Risk Actually Lives
The table below is the insight most enterprise AI conversations skip. Hallucination is not a model property, it is a domain × deployment × mitigation property. The same GPT-4o that hallucinates 0.7% on summarization benchmarks produces hallucinated legal citations in 17–34% of legal research queries. Model selection alone cannot solve this. Architecture and mitigation layers must.
Domain / Use Case
Hallucination Rate
Risk Level
Key Finding
General summarization
0.7–1.8% (top models)
Low
Vectara HHEM Leaderboard 2026, benchmark conditions only
Enterprise chatbots (live production)
~18%
Medium-High
Real production rates far exceed benchmark numbers
Medical / Clinical AI
43–64% without mitigation
Critical
MedRxiv 2025: drops to 23% with structured mitigation prompts
Stanford: RAG reduces but doesn’t eliminate; retrieval failures persist
Product recommendation AI
Up to 25% accuracy impact
Medium
UC San Diego 2026: AI summaries hallucinated in 60% of tested scenarios
Legal and medical are the clearest danger zones. In legal, the Stanford RegLab/HAI study remains the definitive benchmark: LLMs hallucinate between 69% and 88% of the time on specific legal queries. Researcher Damien Charlotin maintains a database of 120+ court cases where AI-hallucinated quotes, fabricated cases, or fake legal citations were discovered. In legal, hallucination is synonymous with malpractice risk, full stop.
In medical, ECRI listed AI risks as the #1 health technology hazard for 2025. Without mitigation prompts, hallucination rates on clinical cases reach 64.1% on long cases and 67.6% on short cases, according to the MedRxiv 2025 study of 300 physician-validated vignettes. Even at the best-case rate of 23% with full mitigation applied, nearly 1 in 4 medical AI responses contains fabricated information. These are not acceptable residual rates without mandatory physician review on every clinical output.
How to Measure Hallucination Rate in Your Production System
The Measurement Gap Most Teams Don’t Know They Have
91% of enterprises have implemented explicit hallucination mitigation protocols. Far fewer measure actual hallucination rates in production. Without measurement, mitigation is guesswork. Most teams implement RAG and assume the problem is solved. Stanford research shows RAG-powered legal tools still hallucinate 17–33% of the time. Organizations implementing RAG without measuring outcomes are deploying production AI systems they cannot describe, audit, or improve.
The Four RAG Evaluation Metrics Every ML Team Must Track
Metric
What It Measures
What Low Scores Signal
Context Precision
Does the retrieved chunk actually contain the answer?
Retriever is surfacing irrelevant content
Context Recall
Did the retriever find all necessary information?
Model is forced to fill gaps, hallucination risk rises sharply
Faithfulness
Is the answer derived only from the provided context?
Primary hallucination signal in RAG systems
Answer Relevance
Does the response address what was actually asked?
Off-topic generation that can mask hallucinated content
Production Monitoring Tools in 2026
The market for AI hallucination detection tools grew 318% between 2023 and 2025. The tooling has matured to the point where every production enterprise AI system can and should have continuous hallucination monitoring. The leading platforms: Braintrust for real-time monitoring and automated regression testing; Galileo for scalable model-driven evaluations at high output volumes; Fiddler for explainability and compliance-focused evaluation with governance integration; Arize AI for real-time monitoring with drift detection.
The LLM-as-judge pattern is now a production standard: a more capable, accurate model, Claude Sonnet or GPT-4o, evaluates the output of a faster, cheaper model for factual grounding and instruction following. Self-consistency checking, sampling 3–5 responses and comparing for agreement, catches a significant share of remaining hallucinations at low additional cost. Both patterns give teams a practical alternative to human review at scale.
Hallucination Measurement Starter Checklist
If your team can’t answer all six of these questions, you don’t yet have production-grade hallucination visibility:
What is our baseline hallucination rate in our target deployment domain, measured in production, not taken from a vendor benchmark?
Which of the four RAG evaluation metrics do we track continuously, and what are our current scores?
What is our post-mitigation hallucination rate, and when was it last measured?
What are the specific query types or topics where our system shows elevated hallucination risk?
At what confidence or grounding score does our system escalate output to human review rather than proceeding autonomously?
Have we had any documented hallucination-caused production errors, and are they tracked in an incident log?
The 3-Layer Mitigation Stack That Reduces Hallucination by 85%+
Three complementary layers, each additive. Used together, research supports a combined reduction of 85–92% in domain-specific enterprise hallucination rates for properly implemented stacks. This transforms AI hallucination mitigation from “inherent unfixable problem” to “manageable engineering challenge with known solutions.”
The simplest and cheapest intervention. Effective prompt constraints include: “Only answer based on the provided context,” “If uncertain, say you don’t know,” and “Cite the specific source passage for each claim.” A 2025 Nature study confirmed prompt-based mitigation reduces hallucinations by approximately 22 percentage points on medical tasks. That’s a meaningful reduction for near-zero implementation cost.
The ceiling is real, though. LLMs don’t reliably follow instructions when statistical pressure to generate a confident response is high, particularly on topics where the model has strong training signal. Prompt engineering is Layer 1, not a standalone solution. Teams that treat it as sufficient are relying on the model to police itself.
The most impactful single technical intervention available. RAG shifts the model from recalling facts from training data, unreliable, unauditable, to synthesizing information from provided documents. Across 847 production deployments, RAG produced a median 71% hallucination reduction, with a range of 58–89% depending on retrieval corpus quality and chunking strategy, according to February 2026 enterprise vendor consortium data.
Key implementation requirements: a comprehensive retrieval index, accurate chunking, sufficient context window to hold retrieved content, and regular index freshness maintenance. Stale retrieval indexes are a hidden hallucination accelerant, when the index doesn’t contain current information, the model defaults to training-data prediction, bypassing the entire grounding mechanism. This is the most common RAG implementation failure in production.
Post-generation verification catches errors that RAG misses. A verification API checks each claim against external sources after generation. Self-consistency checking, sampling 3–5 responses and comparing, adds approximately 65% reduction in residual hallucinations. LLM-as-judge evaluation provides scalable automated review at production volumes.
For regulated industries, finance, healthcare, legal, a human-in-the-loop review layer remains mandatory for high-stakes outputs. It should be the fourth line of defense, not the first. Organizations that rely on human review as their primary hallucination control are paying $14,200 per AI-using employee per year in verification overhead, according to Forrester Research. That’s 4.3 hours per week of pure fact-checking time. The 3-layer stack eliminates most of that cost and shifts human review to the residual edge cases where it actually belongs.
“The question isn’t whether large language models hallucinate, they do, by design. The question is whether your organization has built the architecture to catch and contain hallucinations before they reach decision-makers. Most enterprises haven’t.”Percy Liang, Director, Center for Research on Foundation Models, Stanford University — Stanford AI Index 2026
Industry-Specific Risk Levels and Mitigation Requirements
Healthcare: The Highest Stakes, the Widest Gap
Without mitigation prompts, hallucination rates on clinical cases reach 64.1% on long cases and 67.6% on short cases, per the MedRxiv 2025 study across 300 physician-validated vignettes. With structured mitigation prompts, rates drop to 43.1% and 45.3%, a meaningful 33% reduction. But even at the best-in-class rate of 23% with full mitigation, nearly 1 in 4 medical AI responses contains fabricated information. ECRI named AI risks the #1 health technology hazard for 2025.
Mitigation requirement: Full 3-layer stack plus mandatory physician review for any clinical output, with source citation required for every claim. Any clinical AI system that proceeds without human sign-off on a threshold basis is not compliant with ECRI guidance, and is a liability exposure waiting for a patient outcome to make it a headline.
Legal: Hallucination Is Malpractice Risk
The Stanford RegLab/HAI study is unambiguous: LLMs hallucinate between 69% and 88% of the time on specific legal queries. Even with retrieval augmentation, Lexis+ AI hallucinated in 17% of cases and Westlaw AI-Assisted Research in 34% in 2026. Researcher Damien Charlotin’s database has documented 120+ court cases where AI-hallucinated quotes, fabricated cases, or fake citations were discovered.
Mitigation requirement: Mandatory source disclosure and provenance logging, every LLM legal claim must link to a verified source document. No exceptions for speed or volume. A hallucinated legal citation is not a minor error; it is a professional conduct risk for the attorney who relied on it.
Finance: The Reasoning Hallucination Problem
Reasoning hallucinations are the dominant risk in financial analysis. The model may cite correct facts but produce an invalid logical inference. OpenAI’s o3 reasoning model, widely used for financial analysis, hallucinated 33% of the time on PersonQA benchmarks, double its predecessor. More processing power, more hallucination on open-ended reasoning tasks. Don’t assume a newer model is a safer model until you’ve benchmarked it in your specific deployment context.
Mitigation requirement: Dual-model validation. One model generates. A second model stress-tests the logical chain before the output is used. Output validation must check not just factual accuracy but logical validity, the reasoning hallucination won’t appear wrong until someone follows the chain to its flawed conclusion.
Security and Threat Intelligence: Design for Failure
A hallucinated vulnerability assessment or threat intelligence report can waste hundreds of analyst-hours and create false confidence in defenses. For security AI, the fail-closed principle is non-negotiable: if the confidence score falls below a defined threshold, escalate to a human analyst. Never return a low-confidence threat assessment as if it were confirmed intelligence. The cost of a false negative in security, a missed real threat, far exceeds the cost of a false positive that sends an analyst to verify.
The Cost Anchor That Should Drive Every Procurement Conversation
Global business losses from AI hallucinations reached $67.4 billion in 2024. Enterprises spend an average of $14,200 per AI-using employee per year in hallucination verification overhead, equivalent to 4.3 hours per week of pure fact-checking time. For a 500-person AI-enabled workforce, that’s $7.1 million annually just checking AI’s homework. The 3-layer mitigation stack eliminates most of that cost. Its implementation cost, at any enterprise scale, is a fraction of the overhead it removes.
Building a “Hallucination Datasheet” for Every AI System in Production
What a Hallucination Datasheet Is
A hallucination datasheet is a standardized internal document that profiles the hallucination behavior of each AI system deployed in production: domain-specific rates, known failure modes, measurement methodology, active mitigation layers, and residual risk after mitigation. Leading AI governance controls teams now maintain these as part of their AI registry. It makes hallucination risk visible, comparable, and auditable, the three properties that regulators and enterprise procurement teams will increasingly demand.
The Seven-Field Hallucination Datasheet Template
Field
What to Document
1. Baseline hallucination rate
Measured in target domain in production, not vendor benchmark
2. Active mitigation layers
Which of prompt engineering / RAG / output validation are implemented
3. Post-mitigation hallucination rate
Measured in production after all mitigation layers are applied
4. Known failure modes
Specific query types, topics, or conditions with elevated hallucination risk
5. HITL threshold
Confidence or grounding score below which output requires human review
6. Last measurement date and review cadence
When rates were last measured and how frequently they’re reassessed
7. Incident history
Any documented hallucination-caused errors in production, dates, impacts, resolutions
The Regulatory Case for Doing This Now
Under EU AI Act Article 13, users of high-risk AI must ensure that users understand the system’s capabilities and limitations. A hallucination datasheet is the most direct way to document known limitations in a format regulators, auditors, and enterprise procurement teams can evaluate. Organizations that maintain these documents can demonstrate due diligence in a way that ad-hoc governance cannot.
“Transparency about AI system limitations, including hallucination rates and failure modes, is not optional under the EU AI Act for high-risk applications. It is a documentation requirement with enforcement consequences.”Luca Bertuzzi, AI Policy Correspondent, MLex Media — EU AI Act Compliance Analysis, 2026
Teams that integrate hallucination datasheets into their AI registry now are building the audit trail that procurement reviews and regulatory audits will require in 2027. Teams that don’t are creating a documentation gap that gets expensive to close retroactively.
The Future of Hallucination: Will It Ever Be Solved?
The Structural Constraint That Won’t Go Away
The 2025 mathematical proof is clear: hallucinations are structurally inevitable under existing LLM architectures. They are an emergent property of probabilistic text prediction. Analysis of Hugging Face leaderboard data suggests that zero hallucinations would require models with roughly 10 trillion parameters, a scale not expected before approximately 2027. For enterprise planning purposes, treat hallucination mitigation as a permanent operational discipline, not a problem the next model update will solve.
The Counterintuitive Trend: Better Reasoning, More Hallucination
OpenAI’s o3 reasoning model hallucinated 33% of the time on PersonQA benchmarks, double its predecessor o1. o4-mini reached 48% on person-specific questions. The most sophisticated reasoning models push into higher entropy generation, creating a direct trade-off between reasoning depth and factual accuracy on open-ended queries. Enterprise teams deploying reasoning models for complex financial or legal analysis should benchmark hallucination rates specifically in their deployment domain. Don’t assume newer means more reliable, in reasoning tasks, the evidence currently suggests the opposite.
The 2026 Direction: From Mitigation to Architecture
The frontier of hallucination management is moving from post-generation mitigation to generation-time architecture. “Guarded Generation” patterns, pre-retrieval validation, constrained generation, post-generation verification, are becoming standard in production LLM engineering. The goal is not to prevent hallucination in the model. That’s not achievable at current scales. The goal is to catch and contain it before it reaches enterprise decision-making.
The organizations that will lead on AI reliability through 2026 and beyond are not those that found a hallucination-free model. No such model exists at useful enterprise scale. They are the organizations that built layered mitigation architectures, measured production hallucination rates continuously, and integrated hallucination governance into their enterprise AI reliability strategy and incident response plans. That is the practical definition of production-grade enterprise AI, and it’s an engineering discipline, not a vendor promise.
Frequently Asked Questions
What is AI hallucination and why does it happen in enterprise applications?
AI hallucination occurs when a language model generates information that is factually incorrect, fabricated, or logically invalid, delivered with the same confident tone as accurate output. It happens because LLMs predict the most statistically probable next token based on training data patterns, not factual retrieval. It is structurally inherent to probabilistic generation under current architectures, confirmed by a 2025 mathematical proof, and rates are significantly higher in enterprise production environments than vendor benchmarks suggest.
How much do AI hallucinations cost enterprises financially?
Global business losses from AI hallucinations reached $67.4 billion in 2024, according to a comprehensive AllAboutAI study. Per enterprise employee, organizations spend approximately $14,200 annually in hallucination verification overhead, equivalent to 4.3 hours per week of fact-checking time, per Forrester Research. For a 500-person AI-enabled workforce, that equates to $7.1 million annually in pure verification cost before any downstream error costs are counted.
Does RAG eliminate AI hallucinations completely?
No. RAG significantly reduces hallucinations but cannot eliminate them. Across 847 production deployments, RAG produced a median 71% hallucination reduction, with a range of 58–89% depending on retrieval corpus quality and chunking strategy. However, Stanford researchers found that RAG-powered legal AI tools still hallucinate in 17–33% of queries due to retrieval failures and gaps in the retrieval corpus. RAG should be the foundation of a 3-layer mitigation stack, not a standalone solution.
What are hallucination rates for the best AI models in 2026?
On grounded summarization benchmarks, top models achieve below 1% hallucination rates, GPT-4o and Claude 3.5 Sonnet both score around 0.7–0.8% on the Vectara HHEM Leaderboard. Production rates are dramatically higher: approximately 18% in live enterprise chatbot interactions, 17–34% in legal AI tools, 43–64% in medical AI without mitigation, and 22–94% across 26 models on complex reasoning tasks per the Stanford AI Index 2026.
How do you measure AI hallucination rate in a production system?
Track the four RAG evaluation metrics, Context Precision, Context Recall, Faithfulness, and Answer Relevance, using monitoring tools like Braintrust, Galileo, or Arize AI for continuous production tracking. Implement LLM-as-judge evaluation for scalable automated review. Set a baseline hallucination rate before mitigation is applied, then measure post-mitigation rates on a continuous basis. The current industry improvement trend is approximately a 3-point annual decline in hallucination rate for teams actively measuring and iterating.
Why is hallucination worse in AI agents than in standard chatbots?
Agentic AI workflows trigger 10–20 LLM calls per task, according to Gartner’s March 2026 research. With each call carrying even a modest hallucination probability, the compound probability of at least one hallucination affecting a multi-step chain rises dramatically, and agents act before human review occurs. Multi-turn agents show hallucination rates up to 35% during extended interactions. A chatbot hallucination is caught by the human reader; an agent hallucination may trigger an unauthorized API call, misroute data, or take an irreversible action before anyone sees the output.
How do I reduce LLM hallucination rates in a regulated industry like healthcare or finance?
Regulated industries require the full 3-layer mitigation stack, prompt constraints, RAG implementation, and post-generation output validation, plus mandatory human-in-the-loop review above a defined confidence threshold. Healthcare deployments should require physician sign-off on all clinical outputs and source citation for every claim, given hallucination rates of 43–64% without mitigation. Finance deployments should implement dual-model validation where a second model stress-tests the logical chain before output is used, specifically to catch reasoning hallucinations.
What is a hallucination datasheet and does my team need one?
A hallucination datasheet is a standardized internal document profiling the hallucination behavior of a specific AI system in production: baseline rate, active mitigation layers, post-mitigation rate, known failure modes, human review thresholds, and incident history. EU AI Act Article 13 requires that users of high-risk AI understand system limitations, a hallucination datasheet is the most auditable way to document this. Any enterprise running AI in legal, medical, financial, or security contexts should maintain one for every production deployment.
AI Workload Placement Hybrid Cloud Strategy — NeuralWired
Artificial IntelligencePublished: May 16, 2025 · Updated: May 2026
AI Workload Placement Strategy: The Hybrid Cloud Framework That Saves Enterprises $1.2M Annually (2026)
AI cloud budgets are running 30 to 50 percent over forecast, not because enterprises are overspending, but because they’re placing the wrong workloads in the wrong environments, and most CTOs don’t yet have a framework to fix it.
AI-related cloud spending now represents 19% of total enterprise cloud spend in 2026, up from just 8% in 2023. That 137% share increase in three years means the AI infrastructure decisions most organizations made during early adoption are now breaking budgets at scale. The average enterprise spends $1.7 million annually on AI cloud services, and the single biggest lever for cutting that number isn’t renegotiating contracts or switching providers. It’s workload placement: the strategic decision of which environment, public cloud, on-premises, colocation, or edge, each AI workload should run in. This guide gives you the 5-step AI workload placement hybrid cloud strategy that enterprise infrastructure teams use to stop mismatching workloads to environments and start recovering six-figure annual savings.
The AI Infrastructure Decision Problem CTOs Face in 2026
For the first time in 2026, inference workloads consume more cloud compute than training. That shift matters enormously because most enterprise cost models were built around training economics: bursty, periodic, elasticity-friendly. Those same models, applied to always-on inference, produce sustained overspend every month with no natural correction mechanism.
The market has moved to hybrid. 72% of enterprises now run hybrid cloud architectures, and the global hybrid cloud market, valued at $114.83 billion in 2026, is projected to reach $230.36 billion by 2032 at 12.2% CAGR. Hybrid is no longer a transitional state. It’s the target architecture for mature AI infrastructure.
Three Infrastructure Traps Enterprises Fall Into
The first is cloud-first-by-default: every workload goes to AWS or Azure regardless of fit, producing consistent overspend on steady inference loads that on-prem hardware would serve at a fraction of the cost. The second is on-prem-first-by-inertia: legacy data centers that can’t support modern GPU density quietly block AI scaling, forcing teams to cloud workarounds that compound costs. The third, and most expensive, is hybrid-without-strategy: multiple environments with no unified FinOps visibility, creating the maintenance burden of on-prem with the per-unit cost of cloud.
Why This Is a CTO Problem, Not Just an Ops Problem
According to the Nutanix Enterprise Cloud Index 2026, surveying 1,600 executives, 80% of data sovereignty considerations are now classified as “high priority or must-include” in infrastructure decisions. Workload placement has become a compliance and governance decision that requires executive ownership, not just an infrastructure optimization left to the ops team.
Budget reality check: Cloud costs are running 30 to 50% higher than projected in enterprise AI budgets, driven not by vendor pricing increases but by workload misplacement. Training workloads on inference-optimized instances, inference workloads on cloud when on-prem would cost 54% less, and sensitive workloads in environments that create data sovereignty exposure are the three most common culprits.
The 4 AI Workload Types, And Why Each Has a Different Natural Home
“AI workloads” is not a monolithic category. Each type has fundamentally different infrastructure requirements, and placing any of them in an environment optimized for a different type produces either performance degradation, cost overrun, or both. The table below gives you the placement framework at a glance.
Inference must run near the data source; overflow lives in cloud
Why Inference Economics Are Now the Priority
When training dominated AI compute spend, cloud’s elasticity premium made sense. A model trains once (or periodically), and burst capacity on spot instances keeps costs manageable. Inference is structurally different: it runs continuously, often at predictable volume, 24 hours a day. The economics that justified cloud for training actively work against you for steady-state inference.
Fine-tuning sits between these two extremes and requires a sovereignty filter before a cost filter. If fine-tuning uses proprietary customer data, internal financial records, or any data category covered by HIPAA, GDPR, or sector-specific regulation, the placement decision is governed before it’s economic. An on-prem or private cloud environment isn’t just cheaper in many cases, it’s required.
Cloud vs On-Prem vs Hybrid: What the 2026 Cost Benchmarks Actually Show
The numbers here are not theoretical. AWS p5.48xlarge instances (8 x H100 80GB) run at $98 per hour on-demand: $71,540 per month for continuous production inference. The equivalent CoreWeave H100 SXM5 reserved configuration costs approximately $4.50 per hour for a comparable setup. That’s a 95% cost differential on the same GPU hardware for sustained workloads. Cloud wins on flexibility. On-prem and specialist providers win on sustained cost.
The Utilization Threshold That Determines Everything
On-prem wins when GPU utilization stays above 40%. Below that threshold, idle hardware cost exceeds the cloud flexibility premium, and cloud is the more economical choice. Above 95% utilization, cloud burst capacity becomes necessary regardless of preference. The zone where hybrid generates maximum economic advantage is on-prem baseline maintained at 60 to 80% utilization, with cloud handling overflow and burst.
Cloud Provider Reference Points for AI Infrastructure Decisions
Provider
Market Position
AI Workload Fit
Notable Constraint
AWS
31% IaaS share, broadest portfolio
Training, experimental, burst inference
Highest on-demand GPU pricing in the market
Azure
25% share, fastest-growing
Enterprise AI, Microsoft Copilot integration
Strong for Microsoft-stack teams; less flexible for multi-framework
Google Cloud
12% share, now profitable
TensorFlow workloads, TPU-optimized jobs
TPU pricing advantage limited to specific frameworks
CoreWeave
Specialist GPU cloud
Sustained inference at competitive TCO
Narrower service breadth than hyperscalers
Oracle Cloud
52% YoY growth
Database-adjacent AI, ERP-integrated workloads
Ecosystem lock-in risk for Oracle-heavy shops
The Egress Trap Most CTOs Miss
Cloud costs aren’t just compute. Data movement across regions, clouds, or between on-prem and cloud adds egress and network charges that don’t appear in initial estimates. Moving 10TB per month at $0.09 per GB adds $900 monthly in pure data movement cost, before any compute runs. “Data gravity”, keeping compute near the data, is a cost discipline, not just a performance principle. Enterprises with large AI-hungry datasets in on-prem systems who push those datasets to cloud for training are often paying more in egress than they’d pay for the equivalent on-prem GPU capacity.
The 5-Step AI Workload Placement Framework
This is the framework enterprise AI infrastructure teams use to match every workload type to the right environment. Each step produces a concrete output that feeds directly into infrastructure budget decisions and board-level AI ROI reporting. For teams working through their broader AI infrastructure strategy, this framework is the operational core of that planning process.
Step 1: Assess and Classify Your AI Workload Portfolio
Catalog every AI workload in production or planning by type (training, fine-tuning, steady inference, burst inference), data sensitivity (public, internal, regulated, sovereign), latency requirement (real-time under 50ms, interactive under 500ms, batch over 1 second), and current and projected monthly compute volume. Don’t estimate. Pull actual metrics from your monitoring layer. Output: an AI Workload Inventory with environment-fit scoring for each workload.
Step 2: Apply Data Gravity Analysis
For each workload, the foundational question is: where does the data live? Move compute logic to the data, not the other way around. If training data lives in AWS S3, train in AWS. If inference data is generated on a factory floor, serve inference at the edge. Moving large datasets to compute is almost always more expensive and slower than moving model logic to where the data already sits. Output: a data gravity map per workload that identifies the environment with least data movement cost.
Step 3: Run a Per-Workload TCO Calculation
For each workload, calculate monthly cost under three scenarios: full public cloud on-demand, full on-prem or colocation, and hybrid split. Include compute cost, storage, egress, staffing overhead, and compliance cost in every scenario. The workload crosses from cloud to on-prem breakeven when monthly volume multiplied by cost-per-query exceeds on-prem amortized monthly cost divided by utilization rate. Output: a TCO comparison table per workload, feeding into your AI total cost of ownership model.
Step 4: Apply Compliance and Sovereignty Filters
After TCO, layer in regulatory constraints. Regulated healthcare inference must stay within defined jurisdictions. Financial AI subject to SOX or DORA cannot use certain cloud regions. EU-based workloads under GDPR must meet data residency requirements. Compliance constraints can override the TCO-optimal choice, and building this check into the decision model upfront is far cheaper than discovering the constraint after infrastructure is provisioned. Output: compliance-cleared workload placement decisions with jurisdiction documentation.
Step 5: Implement Unified FinOps Visibility Across All Environments
The greatest operational risk in hybrid AI infrastructure is cost blindness: scattered cost data across on-prem clusters, AWS accounts, and GCP projects with no unified view. Organizations using FinOps practices reduce cloud waste by 20 to 30% in the first year of implementation. For an enterprise spending $1.7M annually on AI cloud, that’s $340,000 to $510,000 in recoverable waste with no change to AI capability. Output: a unified AI infrastructure cost dashboard with per-workload attribution across every environment.
FinOps impact: $340,000 to $510,000 in annual waste recovery for a $1.7M AI cloud budget, from placement and visibility discipline alone, no vendor renegotiation required.
How to Calculate Per-Workload TCO: The Formula CTOs Use
Most on-prem TCO calculations forget power and staffing. Most cloud TCO calculations forget egress and managed service premiums. The result is a comparison that’s structurally biased toward whichever option the team started with, not whichever option is actually cheaper.
The correct total cloud cost formula includes: compute + storage + egress + managed service premium + engineering overhead for cloud-specific tooling. The correct on-prem cost formula includes: hardware amortization over 36 to 48 months + power + cooling + colocation or data center fees + staffing + maintenance + security infrastructure. Neither formula is simple, but skipping components on either side produces decisions that look defensible and cost real money.
The 3-Scenario Cost Model
Cost Component
Cloud On-Demand (AWS/GCP)
Specialist Cloud (CoreWeave Reserved)
On-Prem / Colo
GPU compute (2x H100, sustained)
$18,250 to $71,540/mo
$3,285 to $5,800/mo
$2,000 to $3,500/mo (amortized)
Storage (100TB)
$2,300/mo (S3)
$1,500/mo
$400 to $600/mo (NVMe)
Egress (10TB/mo)
$900/mo ($0.09/GB)
$400/mo
$0 (internal)
Staffing overhead delta
Low (managed services absorb ops)
Medium
High (+0.5 to 1 FTE)
Compliance / sovereignty control
Shared responsibility risk
Provider dependent
Full control
Best for
Burst training, dev/test, unpredictable volume
Sustained inference at competitive TCO
Always-on inference, regulated data
The Breakeven Decision Threshold
On-prem reaches TCO breakeven versus cloud on-demand at approximately 18 to 24 months for GPU-intensive sustained inference workloads. Below 18 months of committed usage, cloud is almost always more economical due to capex avoidance. Specialist cloud providers like CoreWeave with reserved GPU pricing can extend the cloud-competitive window by offering on-prem-competitive TCO without the capex commitment. That’s the middle path that’s becoming standard for teams that want cost discipline without capital expenditure risk.
Data Sovereignty and Compliance Constraints That Override Cost Decisions
According to the Nutanix Enterprise Cloud Index 2026, 80% of IT executives classify data sovereignty as “high priority or must-include” in infrastructure decisions. Yet only 18% of enterprises have formal data sovereignty policies that specifically cover AI workloads. That’s the governance gap creating regulatory exposure right now, and it’s a gap that data sovereignty governance frameworks are only beginning to close at the policy level.
Regulatory Constraints by Industry
Industry
Regulation
AI Workload Constraint
Environment Implication
Healthcare
HIPAA
PHI must stay within defined jurisdictions; inference under 50ms for real-time clinical tools
On-prem or domestic cloud mandatory
Financial services
SOX, DORA
Auditability and geographic controls on AI systems processing financial data
EU DORA requires contractual ICT risk standards from cloud providers
EU operations
GDPR, EU AI Act
Data residency for personal data; high-risk AI requires full technical documentation
Data residency enforcement; audit trails for high-risk systems
Government/federal
FedRAMP
AI workloads must use FedRAMP-authorized environments
Many commercial LLMs are not FedRAMP authorized
The Vendor Contract Gap Most CTOs Discover Too Late
The “Clear-Box” vendor policy standard requires that contracts explicitly prohibit model fine-tuning on corporate data and guarantee data residency. Opt-out settings in vendor dashboards are not governance: technical enforcement plus contractual obligation is the minimum standard. If your cloud AI vendor contract doesn’t specify data training exclusions, assume your data is in scope for model improvement. Fix the contract before deploying sensitive workloads, not after.
The Sovereign AI Pattern Emerging in 2026
Leading enterprises are combining local inference for sensitive workloads with public cloud capacity for generic, non-sensitive workloads. The pattern, bringing models to data instead of data to models, is gaining traction in Asia Pacific and regulated EU industries where data movement is legally constrained. It’s a practical response to a real constraint: regulated data can’t move, so inference infrastructure has to. Understanding the full scope of AI compliance requirements in your industry is a prerequisite for designing this architecture correctly.
“82% of enterprises say their current infrastructure is not fully ready to support on-premises AI workloads if required, yet regulatory trends are pushing more workloads toward sovereign or on-premises deployment.”
Ecosystm Emerging Economics of Enterprise AI, 2026
Real Enterprise Hybrid Patterns That Work in 2026
Enterprises using hybrid colocation architectures report up to 45% cost savings versus pure cloud, with 99.99% uptime for latency-sensitive workloads. That’s the ceiling of what the right pattern can deliver. These four patterns account for how most enterprise ML teams actually structure their hybrid deployments today.
Pattern 1: Train in Cloud, Serve On-Prem
The most common hybrid pattern. Training runs in cloud on spot or reserved instances for burst compute. The trained model is then deployed to on-prem infrastructure for production inference. This captures cloud’s elasticity for the training phase while capturing on-prem’s TCO advantage for the always-on inference phase. Best fit: enterprise ML teams with predictable inference volume and existing on-prem GPU capacity.
Pattern 2: Edge Inference Plus Cloud Burst
Factory floor cameras push real-time defect detection to edge devices. Model training and periodic retraining happen in cloud. New model versions ship to edge devices on a schedule. Cloud handles overflow when edge capacity is saturated. Best fit: manufacturing, retail, healthcare diagnostics, and any use case where inference must happen at the data source with latency under 50ms.
Pattern 3: Mixed Data Gravity
Marketing data lives in cloud naturally. ERP and operational data lives on-prem historically. Training runs in cloud using marketing data. Inference for operations stays on-prem, close to ERP data. A single MLOps layer unifies monitoring and governance across both environments. Best fit: enterprises with legacy on-prem data systems that can’t be fully migrated within a planning horizon, and for whom production AI reliability across mixed environments is a live concern.
Pattern 4: Sovereign AI With Generic Cloud
Sensitive inference runs on sovereign or on-prem infrastructure. Generic workloads, content generation, summarization, classification of public data, run on public cloud LLM APIs. Cost discipline means only paying for sovereign infrastructure when the workload genuinely requires it, not defaulting to on-prem for workloads that carry no data residency obligation. This is the pattern driving the fastest ROI for regulated enterprises adopting LLMs at scale.
Pre-Decision CTO Checklist: 14 Questions Before Committing to a Placement Model
Answer these before committing any infrastructure budget to a placement model. If you answer “don’t know” to more than three, your AI workload placement decisions are being made on assumptions. This checklist gives you the data model to answer every question with confidence, and the benchmarks to defend the decision to your CFO.
#
Question
Cloud Signal
On-Prem Signal
01
Is the workload burst or sustained?
Burst volume: favor cloud
Sustained, always-on: favor on-prem
02
Is GPU utilization target above 60%?
Below 60%: cloud wins on idle cost
Above 60%: on-prem reaches payback
03
Does the workload touch regulated data?
Non-regulated: cloud acceptable
Regulated: on-prem or colo mandatory
04
Where does the training/inference data live?
Match environment to data location. Data gravity rule applies regardless of other factors.
05
Is latency under 100ms required?
No hard latency requirement: cloud viable
Under 100ms: edge or on-prem required
06
Do we have staff to manage on-prem GPU clusters?
No GPU ops team: cloud lowers overhead
Existing GPU ops capacity: on-prem viable
07
Is the workload in production or experimental?
Experimental/dev: cloud for speed
Production at scale: evaluate on-prem
08
Will volume be predictable 12+ months out?
Unpredictable: cloud for flexibility
Predictable: on-prem or reserved cloud
09
Is data egress between environments above 10TB/mo?
Under 10TB: cloud egress cost manageable
Above 10TB/mo: on-prem eliminates egress
10
Are there geographic data residency requirements?
No residency obligation: cloud viable
Residency requirement: sovereign or on-prem mandatory
11
Is the deployment timeline under 3 months?
Under 3 months: cloud speed advantage
Longer timeline: evaluate on-prem
12
Do we have unified FinOps visibility across environments?
If no: implement before adding any environment. Cost blindness compounds in hybrid deployments.
13
Have we run a 3-scenario TCO model for this workload?
Mandatory before any commitment over $100K/year. Gut-feel TCO comparisons miss egress and staffing.
14
Is our vendor contract clear on data training exclusions?
If no: fix the contract before deploying sensitive workloads. Opt-out toggles are not contractual protection.
What to Watch
01
CoreWeave and specialist GPU cloud providers are aggressively pricing H100 and H200 reserved instances to compete directly with on-prem TCO. By Q3 2026, watch for reserved GPU pricing that eliminates the capex argument for on-prem sustained inference, forcing enterprises to reassess placement decisions made in 2024 and 2025.
02
The EU AI Act’s high-risk AI system requirements take full effect in August 2026, with documentation and audit trail obligations that will force many enterprises to repatriate inference workloads currently running in non-EU cloud regions. CISOs and compliance leads in EU-regulated industries should be running workload audits now, not after the deadline.
03
Unified AI FinOps platforms that normalize cost data across on-prem clusters, AWS, Azure, and GCP are entering their second product generation in 2026. The vendors reaching enterprise contract stage by Q4 2026 will define the standard toolset for hybrid AI cost governance, watch which platforms earn FedRAMP authorization first, as that will determine federal and regulated enterprise adoption.
Frequently Asked Questions
What is AI workload placement in hybrid cloud?
AI workload placement is the strategic decision of which computing environment, public cloud, private cloud, on-premises, or edge, each AI workload should run in, based on cost, performance, compliance, and data gravity factors. In a hybrid cloud model, organizations run different workload types in different environments simultaneously, optimizing for total cost of ownership rather than defaulting to a single environment. The goal is matching each workload to the environment where its specific characteristics (burst vs. sustained, regulated vs. generic, latency-sensitive vs. batch) generate the best cost-performance outcome.
When does on-premises AI infrastructure actually beat cloud?
On-premises wins for sustained, always-on inference workloads where GPU utilization stays above 60%, for regulated data that can’t leave defined jurisdictions, for latency-sensitive inference requiring under 100ms response times, and for high-egress workloads where data movement costs make cloud uneconomical. Cloud wins for burst training, experimental workloads, and teams without the staffing capacity to manage GPU clusters. The 18-to-24-month TCO breakeven threshold is the practical decision boundary: below that committed usage horizon, cloud avoids capex; above it, on-prem or colocation generates the better return.
How much can enterprises actually save with a hybrid AI cloud strategy?
Enterprises using hybrid colocation architectures report up to 45% cost savings versus pure cloud for sustained AI workloads, according to DataBank’s 2026 colocation report. Organizations implementing FinOps practices reduce cloud waste by 20 to 30% in the first year. For the average enterprise spending $1.7 million annually on AI cloud services, that represents $340,000 to $765,000 in recoverable annual savings from placement optimization and visibility discipline alone, before any workload repatriation or hardware investment.
What is data gravity in AI infrastructure and why does it matter?
Data gravity refers to the principle that large datasets attract compute to their location rather than the reverse. In AI workload placement, it means deploying training and inference compute in the same environment where the relevant data already lives. Moving large AI datasets across environments incurs significant egress costs and latency penalties. The practical rule: bring models to data rather than data to compute. For enterprises with on-prem ERP and operational data, this often means keeping inference local even when cloud might otherwise be the cost-optimal choice.
What is the TCO breakeven point for on-prem AI GPU infrastructure?
On-premises GPU infrastructure typically reaches TCO breakeven versus cloud on-demand pricing at 18 to 24 months for sustained, high-utilization inference workloads. Below 18 months of committed usage, cloud remains more economical due to capex avoidance. Specialist cloud providers like CoreWeave with reserved GPU pricing can extend the cloud-competitive window significantly, offering on-prem-competitive TCO without requiring capital expenditure. The breakeven calculation must include power, cooling, staffing, and maintenance on the on-prem side, teams that omit these systematically overestimate the on-prem advantage.
How do data sovereignty laws affect AI workload placement decisions?
Data sovereignty regulations can override TCO-optimal placement entirely. HIPAA requires healthcare AI to keep PHI within defined jurisdictions. EU GDPR mandates data residency for personal data, and the EU AI Act adds documentation requirements for high-risk AI systems. DORA requires contractual ICT risk standards from cloud providers serving EU financial firms. FedRAMP authorization is required for federal AI deployments, and many commercial LLMs don’t yet qualify. Compliance constraints should be applied as a filter before TCO analysis, not after, since they can eliminate entire environment categories from consideration.
What is the best cloud provider for enterprise AI workloads in 2026?
There’s no single best provider, the right choice depends on workload type, existing stack, and compliance requirements. AWS holds 31% IaaS market share with the broadest portfolio but the highest on-demand GPU pricing. Azure’s 25% share and Microsoft Copilot integration make it the natural choice for Microsoft-heavy enterprises. Google Cloud’s 12% share comes with the best TPU pricing for TensorFlow workloads. CoreWeave is the strongest competitor for sustained inference TCO without the capex of on-prem hardware. The most cost-effective approach for most enterprises is multi-environment: no single provider should run all workloads.
How do I start implementing FinOps for AI infrastructure across hybrid environments?
Start by establishing per-workload cost attribution in each environment separately before attempting cross-environment normalization. Most enterprises can’t implement unified FinOps because they don’t yet have workload-level cost tagging in any individual environment. Once cost tagging is consistent across cloud accounts and on-prem clusters, move to a normalization layer that applies a common cost unit (cost per inference, cost per training run) across all environments. The platforms that are maturing toward enterprise-grade hybrid AI FinOps in 2026 include Apptio, CloudHealth, and Spot.io. Organizations using FinOps practices reduce cloud waste by 20 to 30% in the first year of implementation.
Stay ahead of enterprise technology.
NeuralWired delivers weekly intelligence for CTOs, CISOs, and AI leads — no noise, no filler.
AI Governance Framework Enterprise 2026 — NeuralWired
CYBERSECURITYPublished: May 15, 2025 · Updated: May 2026
AI Governance Framework for Enterprise: The NIST-Aligned 6-Step Guide for CISOs in 2026
Three in four CISOs have already found unsanctioned AI running in their environments. Here’s the framework to govern it before the EU AI Act enforcement deadline finds you first.
Three out of four CISOs have already discovered unsanctioned AI tools operating inside their enterprise environments — and another 16% aren’t sure, which is functionally the same problem (Saviynt / Cybersecurity Insiders CISO AI Risk Report 2026). Only 21% of organizations have a mature governance model for AI agents (Deloitte State of AI 2026). That gap, AI proliferating across the enterprise while governance covers almost none of it, is where the next major breach is already forming.
The EU AI Act’s enforcement deadline for high-risk AI systems is August 2, 2026. The NIST AI RMF has moved from voluntary guidance to a de facto regulatory reference point, already cited in Colorado, Connecticut, and Illinois legislation as a compliance safe harbor. And AI-related breaches now average $4.88 million, the highest figure in history (IBM Cost of Data Breach 2025).
This guide gives CISOs, CTOs, and compliance leaders the practical enterprise AI strategy foundation they need: a NIST-aligned 6-step AI governance framework for enterprise that’s defensible in a board meeting, ready for an EU AI Act audit, and operational from week one.
Why AI Governance Is Now a Board-Level Emergency, Not Just an IT Problem
The numbers from the front lines are stark. According to the Saviynt / Cybersecurity Insiders CISO AI Risk Report 2026, 92% of enterprises currently lack full visibility into their AI identities, and 95% say they doubt they could detect or contain AI misuse if it happened. These aren’t projections or theoretical exposure metrics. This is the operating reality of most enterprises right now.
“By 2028, 25% of enterprise breaches will be attributable to AI agent abuse — from both external attackers and malicious insiders.”
Gartner, 2026 AI Security Forecast
The boardroom pressure is accelerating alongside that risk. 34% of chief executives now identify AI as their single top strategic theme, surpassing digital transformation after more than a decade at the top of CEO priority lists (Gartner CEO Survey 2026). Boards are approving AI initiatives at speed. The governance infrastructure to manage those initiatives, in most organizations, doesn’t exist yet. That’s the definition of operational risk.
Shadow AI Is the Immediate Trigger
Shadow AI — GenAI tools deployed without IT or security awareness — isn’t limited to browser-based writing assistants. These tools often arrive with embedded credentials, OAuth tokens wired directly into Salesforce and SAP, and API integrations that bypass every security control the organization thought it had in place. Shadow AI was a contributing factor in 20% of data breaches in 2025, adding an average of $670,000 to incident costs (IBM Cost of Data Breach 2025). DTEX and Ponemon’s 2026 Insider Threat Report puts the annual cost of shadow AI to organizations at $19.5 million on average, making it the top driver of negligent insider incidents this year.
Five Questions Every CISO Must Now Answer to the Board
If your leadership team can’t answer all five of these without preparation time, the gaps this article closes are yours to own:
What percentage of AI usage across the organization is currently sanctioned and documented?
Are our active AI deployments aligned to ISO 42001 or NIST AI RMF controls?
Do vendor contracts explicitly prohibit corporate data from being used in model training?
When did we last conduct a red-team exercise against a production AI system?
Which business processes are now AI-automated, and who owns accountability for their outputs?
The EU AI Act enforcement hammer lands August 2, 2026. Penalties for high-risk AI non-compliance reach €35 million or 7% of global annual turnover. As of early 2026, only 8 of 27 EU member states had established enforcement bodies — meaning the compliance window is closing while most organizations are still in the discovery phase of their AI governance journey.
What the NIST AI RMF Actually Requires — And What Vendors Won’t Tell You
The NIST AI RMF organizes around four functions. Understanding what they actually demand — versus what vendors claim they cover — is the first step to building governance that holds up under scrutiny.
Function
What It Actually Does
Common Vendor Misrepresentation
GOVERN
Establishes accountability structures, risk culture, and decision rights across the AI lifecycle
Conflated with “AI policy documents” — governance is organizational, not documentary
MAP
Contextualizes each AI use case against its risk profile and stakeholder exposure
Treated as a one-time intake form rather than a continuous classification activity
MEASURE
Quantifies AI risks using consistent scoring and defined metrics across systems
Reduced to model accuracy metrics — ignores bias, reliability, and societal impact dimensions
MANAGE
Operationalizes risk responses and controls across the entire AI system lifecycle
Treated as a final step rather than a continuous loop feeding back into GOVERN
The Voluntary Framework That Isn’t Voluntary
The NIST AI RMF is technically voluntary. In practice, it has effectively become mandatory for any enterprise operating in regulated industries or selling to government buyers. The Federal AI Risk Management Act (HR6936) would mandate it for federal contractors. The Colorado AI Act cites it as a compliance safe harbor. Enterprise procurement teams now require NIST AI RMF alignment as a supplier prerequisite — which means if your customers are large enterprises, your governance posture is their vendor risk problem.
The GenAI Layer Organizations Are Missing
NIST released NIST AI 600-1 in July 2024 — a companion document specifically addressing generative AI risks. It identifies 12 risk categories unique to or exacerbated by GenAI, with more than 200 suggested mitigation actions. If your enterprise AI governance framework predates mid-2024, it almost certainly doesn’t address the GenAI layer at all. That’s the gap most organizations are currently running blind in.
In April 2026, NIST also published a concept note for an AI RMF Profile on Trustworthy AI in Critical Infrastructure — directly relevant to any enterprise operating in finance, healthcare, energy, or utilities. The 60% of IT leaders who cite legacy system integration as their primary AI governance challenge (Deloitte 2026) need to note that the AI RMF isn’t a technology framework. It’s an organizational one. The hardest part isn’t deploying the framework. It’s retrofitting governance accountability onto systems that were never designed for AI oversight.
Step 1: Map Your AI Surface Area — Every Model, Agent, and Data Flow
You can’t govern what you haven’t found. 73% of CISOs are now prioritizing AI identity discovery and inventory as the first operational step in their governance programs (Saviynt 2026) — and the urgency is clear when you consider that 71% say AI tools in their environment already access core systems like Salesforce and SAP, while only 16% govern that access with any meaningful controls. This is where your AI agent sprawl problem lives.
Three Discovery Actions to Run This Week
Analyze CASB logs for LLM API endpoints. Unsanctioned tools leave fingerprints in your Cloud Access Security Broker data. Look for outbound traffic to OpenAI, Anthropic, Cohere, and Mistral API endpoints not associated with approved systems.
Monitor outbound API calls for AI service destinations. Your network perimeter logs capture AI tool usage that employees think is invisible. A single session token to a personal ChatGPT account tied to corporate email is a data governance incident.
Audit browser extensions across the enterprise fleet. A substantial share of shadow AI lives in browser plugins — tools that quietly read page content, clipboard data, and active sessions across every corporate application the employee uses.
Your AI Asset Register: Required Fields
Field
Why It’s Required
System name + Vendor/internal build
Establishes system identity and supply chain accountability
Data accessed (sensitivity tier)
Required for EU AI Act risk classification and NIST MAP function
Business owner + Technical owner
Governance requires dual accountability — IT alone cannot adjudicate business risk
Risk tier (Low / Medium / High)
Drives proportionate control requirements across all downstream steps
Regulatory scope
Maps each system to applicable requirements (EU AI Act, HIPAA, SOX, SEC)
Last governance review date
Creates the audit trail regulators and insurers will request
Retirement criteria
Prevents zombie AI systems from accumulating unmonitored access over time
Classify every tool found through discovery into one of three buckets: Sanctioned (approved, governed, monitored), Tolerated (restricted use with defined guardrails and a time-limited approval), or Prohibited (high-risk or unvetted, requiring immediate decommission or isolation). This three-tier taxonomy maps directly to the NIST AI RMF MAP function.
Step 1 Deliverable: AI Asset Register v1.0 + AI Usage Policy v1.0. The register should list every identified system against the fields above. The usage policy defines the three access tiers and the approval process for each. These two documents are the foundation every downstream governance step depends on.
Step 2: Define Risk Tiers — Not All AI Is Created Equal
Risk-tiering is the foundation of proportionate AI governance. You don’t apply the same controls to an internal writing assistant as you do to an AI system making autonomous credit decisions or flagging employees for performance review. The EU AI Act formalizes three categories — Unacceptable (banned outright), High-Risk (full compliance burden), and General Purpose AI (lighter-touch oversight) — and your internal risk tiers should align to that taxonomy for built-in regulatory readiness.