In-depth artificial intelligence analysis: AI agents, LLMs, enterprise deployment, governance, and breakthroughs. Research-backed insights for CTOs, founders, and decision-makers.
What Is a Large Language Model? Explained Simply (2026 Guide) | NeuralWired
AI Fundamentals · 2026 Guide
What Is a Large Language Model? Explained Simply (2026 Guide)
By NeuralWired Editorial Team · May 27, 2026 · 14 min read
In 2026, 88% of enterprises have adopted AI, yet only 6% are seeing meaningful returns. The gap isn’t budget. It’s not talent. It’s that most of the people deploying large language models don’t actually understand what they are. This guide closes that gap.
A large language model (LLM) is the foundational technology behind ChatGPT, Claude, Gemini, and every AI writing tool you’ve encountered in the last three years. If you’re building a product, evaluating vendors, or just trying to understand what your engineering team is actually shipping, this is the piece you need to read first.
We’ll cover how LLMs work mechanically, how they’re trained, what makes them genuinely useful, and, critically, what they cannot do, no matter how well you prompt them. No hype. No padding. Just the technical reality, explained for people who make decisions.
The Simple Explanation: What an LLM Actually Does
Strip away the marketing and a large language model does one thing: it predicts the next word. That’s it. You give it text. It guesses what comes next. Then it takes that output, adds it to the input, and guesses again. Repeat a few hundred times and you have a paragraph. Repeat thousands of times and you have a research summary, a legal brief, or a working Python script.
The reason that feels magical, and the reason it’s not, is scale. LLMs are trained on hundreds of billions of words drawn from books, websites, scientific papers, code repositories, and conversations. Through that training, they don’t just learn vocabulary. They absorb grammar, factual associations, reasoning patterns, tone, cultural context, and the structural logic of arguments. All compressed into numerical weights, billions of them, that activate when you send a message.
The One-Line Definition
A large language model is a neural network trained on vast quantities of text to predict and generate human-like language, the foundational technology behind modern AI chatbots, coding assistants, and document tools.
One useful reframe: LLMs are more accurately described as large number models. Computers don’t understand words. They understand numbers. Every word you type is converted into a numerical token. Every token gets processed through layers of mathematical transformations. The output, which looks like language, is really just the winning number at the end of billions of calculations.
That reframe matters for something we’ll return to: when LLMs fail, they’re not being careless. They’re doing exactly what they’re designed to do. The math just doesn’t always produce truth.
How an LLM Works | Token by Token
Here’s the actual mechanism, in sequence.
You type: “What is the capital of France?” Before the model sees a single word, your message is tokenized, broken into chunks roughly 3–4 characters long. “What” becomes one token. “capital” might be one or two. “France” is one. The full sentence becomes roughly 8–10 tokens.
Each token is converted to a numerical vector, a list of numbers representing its position in a high-dimensional space where similar concepts cluster together. “Paris” and “capital” are numerically close. “Paris” and “bicycle” are far apart.
Those vectors pass through the model’s layers — stacked blocks of neural network transformations, each one adjusting the representation based on the attention mechanism (more on that shortly). At the end, the model produces a probability distribution across its entire vocabulary: token X has a 47% chance of coming next, token Y has 31%, and so on. The most probable token is selected. Added to the input. The process repeats.
1.8TEstimated GPT-4 parameters
200K+Max context window tokens (modern LLMs)
0.3 WhEnergy per GPT-4o text query
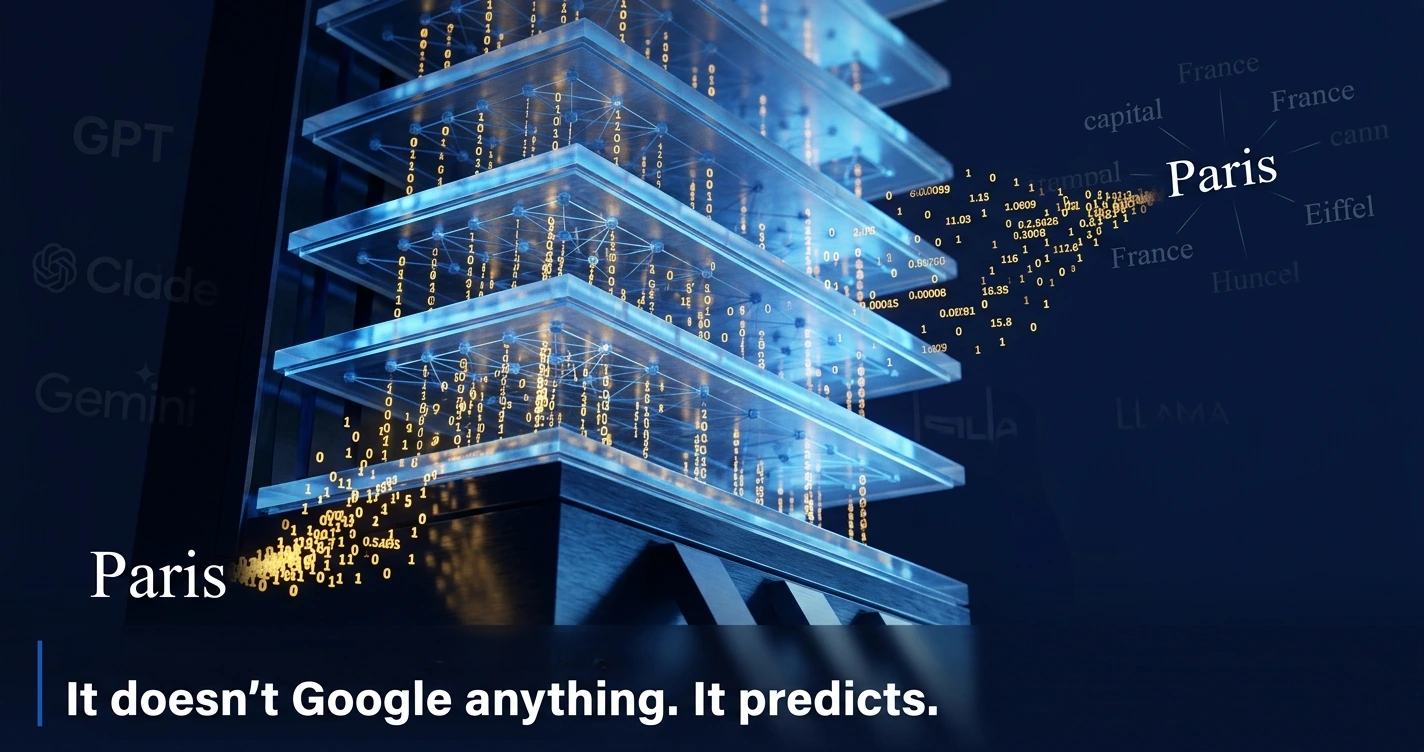
GPT-4 is estimated to contain approximately 1.8 trillion parameters, six times more than GPT-3’s 175 billion. Those parameters are the “knobs”, numerical weights tuned during training to make the predictions as accurate as possible. The model doesn’t look anything up. It doesn’t Google. It generates entirely from the patterns compressed into those weights during training.
This is exactly why LLMs are impressive and exactly why they can be wrong with total confidence. The mechanism that produces “Paris” when asked the capital of France is the same mechanism that produces a convincing-sounding but entirely fabricated legal precedent. It’s prediction, not retrieval. Fluency, not fact-checking.
How an LLM Is Trained, Step by Step
Training a frontier LLM is a multi-month, multi-hundred-million-dollar infrastructure project. Here’s the pipeline, simplified but accurate.
Data collection. Books, websites, academic papers, code repositories, and curated datasets are scraped and assembled into a corpus measured in terabytes. GPT-3 alone used 570GB of internet text.
Quality filtering. Automated classifiers and heuristic rules remove low-quality content, spam, duplicates, toxic material, boilerplate. This step is underrated; the quality of training data is a primary determinant of model quality.
Tokenization. All text is converted to numerical tokens using Byte-Pair Encoding (BPE), an algorithm that learns the most common character sequences in the corpus and merges them into single tokens. Efficient across languages, handles misspellings, and manages rare words gracefully.
Infrastructure setup. Training requires thousands of NVIDIA H100/H200 GPUs or equivalent TPUs running in parallel. Training GPT-3 required approximately 1,287 MWh of energy, equivalent to the annual consumption of around 120 average American homes.
Pre-training: next-token prediction. The model processes the entire corpus, repeatedly predicting the next token and adjusting its weights based on how wrong it was. Through billions of these adjustments, it learns grammar, world knowledge, reasoning patterns, and cultural context simultaneously, without any explicit labeling or instruction.
RLHF alignment. After pre-training, the raw model is brilliant but erratic. Human raters evaluate its responses. That feedback trains a separate “reward model,” which is then used to fine-tune the LLM toward outputs that are more helpful, accurate, and safe. This is how OpenAI, Anthropic, and Google turn base models into products.
What RLHF Actually Does
Reinforcement Learning from Human Feedback doesn’t make a model smarter, it makes it more aligned. It shifts the output distribution toward responses humans rate as good. The distinction matters: a well-aligned model can still be confidently wrong; it’s just less likely to be unhelpful or harmful.
The Transformer: The Engine Behind Every LLM
Every major LLM in production today, GPT-5, Claude 4, Gemini 2.5 Pro, Llama 4 — runs on a variation of the same architecture: the Transformer.
It was introduced in a 2017 paper from Google Brain titled “Attention Is All You Need” by Ashish Vaswani and colleagues. The paper demonstrated that an architecture based entirely on attention mechanisms, with no recurrence, no convolutions, was not only simpler but faster to train and better at the task. The authors showed it was “particularly well suited for language understanding,” outperforming both recurrent and convolutional models on major translation benchmarks.
“The Transformer is a neural network architecture that has fundamentally changed the approach to AI, the go-to architecture for deep learning models powering GPT, Llama, and Gemini.”
— Polo Club of Data Science, Georgia Tech
Before the Transformer, language models used Recurrent Neural Networks (RNNs) and LSTMs that processed text sequentially, one word at a time, left to right. Long-range context was nearly impossible to capture; the model effectively forgot what it read 50 words ago. The Transformer’s attention mechanism solves this by letting every token in a sequence attend to every other token simultaneously. “France” and “capital” can directly influence each other regardless of their distance in the sentence.
Between 2022 and 2025, the transformer architecture wasn’t replaced, it was relentlessly optimized. Mixture-of-experts (MoE) layers, sparse attention, quantization, and inference-time compute scaling transformed what was a promising research architecture into the infrastructure layer of a multi-billion-dollar industry. The chassis is the same. Everything else got a serious upgrade.
Key LLM Concepts Every Tech Professional Should Know
Term
What It Means
Why It Matters Practically
Parameters
Numerical weights tuned during training — GPT-4 has ~1.8 trillion
More parameters ≠ better for your use case; fine-tuned smaller models often outperform giants on specific tasks
Tokens
The unit of text LLMs process — roughly ¾ of a word in English
All cost, speed, and context limits are measured in tokens, not words or characters
Context window
How much text the model can “see” at once — 8K to 200K+ tokens in modern LLMs
The single most important spec for agentic tasks, long document analysis, and multi-turn workflows
RLHF
Reinforcement Learning from Human Feedback — alignment fine-tuning post pre-training
Why Claude, GPT, and Gemini behave differently from the same base architecture class
RAG
Retrieval-Augmented Generation — connecting an LLM to a live knowledge source at inference time
The primary mitigation for hallucination in production; essential for any factual-accuracy use case
Fine-tuning
Continued training on domain-specific data after pre-training
Fine-tuned domain models improve task accuracy by 30%+ over general models — a real engineering decision, not a buzzword
Hallucination
When a model generates plausible but false information with full confidence
Mathematically proven to be unavoidable at some level — architectural mitigation (RAG, verification layers) is mandatory for high-stakes deployments
Real-World LLM Applications in 2026
The enterprise LLM market reached USD 6.5 billion in 2025 and is projected to hit USD 49.8 billion by 2034 at a 25.9% CAGR. That growth reflects actual deployment across five broad categories:
Code generation and review: GitHub Copilot, powered by OpenAI models, is the most widely deployed enterprise LLM application. Developers use it for autocompletion, test generation, documentation, and bug explanation. The quality gap between a general model and a code-fine-tuned model is significant.
Document intelligence: Contract review, regulatory compliance scanning, and earnings report summarization. Law firms and financial institutions are the fastest-moving vertical, despite the highest risk exposure from hallucination.
Customer-facing assistants: LLM-powered support bots now handle first-line resolution for millions of enterprise queries. The critical architecture decision is whether to run RAG (grounding answers in live documentation) or rely on the base model, a choice with major accuracy implications.
Internal knowledge retrieval: Connecting LLMs to internal wikis, CRM systems, and policy documents. IBM’s Granite model series on watsonx.ai is designed specifically for this enterprise-internal use case.
Code infrastructure automation: Microsoft has integrated OpenAI models across Azure, GitHub, and Bing. Agentic LLM workflows, where the model takes multi-step actions, calls APIs, and executes code, are the frontier application as of 2026.
The Honest Limitations | What LLMs Cannot Do
This is the section most LLM explainers skip. Don’t skip it, your production architecture depends on it.
1. Hallucination Is Not a Bug You Can Patch
Researchers at the National University of Singapore published a formal mathematical proof in 2024 (revised February 2025) demonstrating that LLMs cannot learn all computable functions and will therefore inevitably hallucinate if used as general problem solvers. This isn’t a training quality issue or a prompting problem. It’s a hard theoretical ceiling.
Production Risk
If your application requires factual accuracy, medical, legal, financial, compliance, you need a retrieval or verification layer. Expecting the model to “not hallucinate” with better prompting is like expecting a calculator to write poetry. It’s using the tool wrong.
By 2025, 30% of all LLM research papers focused on limitations, with hallucination, reasoning failures, and out-of-distribution generalization as the top three. The scientific community is not bullish on these being resolved through scale alone.
2. Pattern Matching, Not Understanding
“One of the most profound illusions of our time is that most people see these systems and attribute an understanding to them that they don’t really have.”
— Gary Marcus, Professor Emeritus, NYU; author of Rebooting AI | The Decoder, 2025
Marcus, arguably the most credentialed persistent critic of LLMs, argues that when a model appears to know chess rules, it’s because it has seen chess text, not because it has an internal model of the game. It doesn’t reason from principles. It matches patterns. In familiar territory, this is indistinguishable from understanding. In genuinely novel situations, it breaks down.
The practical implication: LLMs are far more reliable on tasks that resemble their training data (summarizing news, writing code in Python, translating French) and far less reliable on tasks that require genuine abstraction or reasoning beyond their training distribution.
3. Interpretability at Scale Is Effectively Zero
“As LLMs scale, it becomes increasingly difficult for programmers to see what’s going wrong because the number of steps in the model’s thought process become ever larger, making it harder and harder to correct for errors.”
— Artur d’Avila Garcez, Professor of Computer Science, City University of London | The Conversation, 2025
At 1.8 trillion parameters, no human can audit why a specific output was produced. You can observe the output. You cannot trace the reasoning. In regulated industries, healthcare, finance, legal, this is a genuine liability, not a philosophical concern.
4. The AGI Timeline Is Longer Than the Headlines Suggest
Andrej Karpathy — who ran AI at Tesla and twice worked at OpenAI, stated in October 2025 that agents aren’t anywhere close to what’s promised, and that AGI remains a decade away. Our read: the 2024–2025 cycle of “AGI in two years” claims reflected investor narrative more than technical progress. Plan your roadmap accordingly.
Which LLM Should You Use in 2026?
The short answer: it depends on the task, not the benchmark. Fine-tuned domain-specific models improve task completion accuracy by over 30% compared to general models, choosing the wrong model for a production workflow is an engineering error with real cost.
Model
Provider
Best For
Deployment
GPT-5
OpenAI
General-purpose, coding, complex reasoning
API / Azure
Claude 4
Anthropic
Long documents, safety-critical, nuanced instruction-following
API / claude.ai
Gemini 2.5 Pro
Google DeepMind
Multimodal tasks, Google Workspace integration, large-context
API / Google Cloud
Llama 4
Meta AI
On-premise deployment, fine-tuning on proprietary data, cost control
The most important strategic decision isn’t which model, it’s build vs. buy vs. fine-tune. Proprietary models (GPT-5, Claude 4, Gemini 2.5 Pro) currently hold the largest enterprise market share at 42.62%, but open-source models like Llama 4 are closing the capability gap fast while offering portability and data sovereignty that proprietary APIs can’t match.
For a full evaluation across TCO, governance, and real-world coding performance, see our Large Language Models Comparison 2026, we score all four frontier models against six enterprise criteria with a decision framework for routing workloads to the right model.
The Deployment Reality Check
Enterprise AI adoption hit 88% in 2026, yet only 6% of companies are seeing real returns. The gap almost always traces to the same root cause: treating LLMs as general-purpose oracles rather than specialized prediction engines requiring retrieval layers, verification workflows, and task-specific fine-tuning. For a deeper breakdown of why most enterprise LLM deployments underperform, see our analysis at NeuralWired.com.
Frequently Asked Questions
What is a large language model in simple terms?
A large language model (LLM) is an AI system trained on billions of words of text to predict and generate human-like language. It works by guessing the next word in a sequence, billions of times over, until it can write sentences, answer questions, and hold conversations. Think of it as an extremely sophisticated autocomplete built on massive statistical patterns.
How does a large language model work?
An LLM converts your input into numerical tokens, then uses billions of internal connection weights to predict the most likely next token. It repeats this process hundreds of times per second. The model was trained on vast text data to simultaneously learn grammar, facts, reasoning patterns, and style, outputting language one token at a time until a complete response is formed.
What is the difference between AI and an LLM?
AI is a broad field covering all machine intelligence, image classifiers, recommendation engines, robotics controllers, and more. An LLM is one specific type of AI: a neural network trained exclusively on language data to understand and generate text. All LLMs are AI, but the vast majority of AI systems are not LLMs.
What are examples of large language models?
The most prominent LLMs include OpenAI’s GPT-4 and GPT-5, Google’s Gemini 2.5 Pro, Anthropic’s Claude 4, Meta’s Llama 4, and IBM’s Granite series. Each differs in parameter count, context window size, training approach, and alignment method. Open-source models like Llama 4 can be self-hosted; proprietary ones are accessed via API.
What are the core limitations of large language models?
LLMs have four structural limitations: (1) hallucination, generating plausible but false information, proven mathematically unavoidable; (2) no real-time knowledge without retrieval tools; (3) poor out-of-distribution generalization, they fail on genuinely novel tasks outside their training data; and (4) no genuine understanding, they pattern-match, not reason from principles.
How many parameters does GPT-4 have?
GPT-4 is estimated to contain approximately 1.8 trillion parameters, roughly six times more than GPT-3’s 175 billion. Parameters are the internal numerical weights adjusted during training that determine how the model responds to any input. OpenAI has not officially confirmed this figure; it comes from third-party analysis reported by Harvard Magazine.
What is RLHF in LLMs?
RLHF stands for Reinforcement Learning from Human Feedback. After initial pre-training, human raters evaluate model responses, and this feedback trains a reward model that guides the LLM toward more helpful and safer outputs. OpenAI, Anthropic, and Google all use RLHF to align their models, it’s why the same base architecture produces noticeably different behavior across providers.
What is tokenization in LLMs?
Tokenization converts raw text into numerical units called tokens before it enters an LLM. A token is roughly 3–4 characters, or about ¾ of an English word. Modern LLMs use Byte-Pair Encoding (BPE) to handle multiple languages and unusual spellings efficiently. All context window limits, API costs, and speed benchmarks are measured in tokens, not words or characters.
What You Now Know — and What Comes Next
If you’ve read this far, you understand something most LLM deployers don’t: the mechanism behind the magic. LLMs are next-token predictors trained at enormous scale on human text. Their apparent intelligence is real and useful. Their structural limitations, hallucination, distribution sensitivity, zero interpretability, are equally real and non-negotiable.
In the 6–18 months ahead, three developments are worth watching closely:
Inference-time compute scaling, the field has shifted from asking “how big can we make it?” to “how smart can we make it think at runtime?” Models that reason more carefully before answering, rather than simply scaling parameters, represent the next performance frontier.
Open-source capability parity, Meta’s Llama 4 and the models following it are closing the gap with proprietary frontier models. The enterprise build/buy/fine-tune calculus will shift significantly if open-source models reach 90% of GPT-5 capability at a fraction of the cost.
Regulation arriving in production, The EU AI Act is in force. Interpretability requirements in regulated industries will accelerate the adoption of hybrid architectures (neurosymbolic AI, RAG with audit trails) that address the verification gap LLMs alone cannot close.
The companies creating durable value from LLMs in 2026 are not the ones with the biggest models. They’re the ones who understand exactly what the technology is, and architect their systems accordingly.
Stay Ahead of the LLM Curve
The Neural Loop delivers the week’s most important AI developments, researched, contextualized, and written for people who build things.
Subscribe Free at NeuralWired.com →
EU AI Act Compliance 2026: Deadlines, Risks & What You Must Do Now
Regulation & Policy
EU AI Act Compliance in 2026: Every Deadline, Fine, and Action Step You Need Now
By NeuralWired EditorialMay 24, 2026Updated: AI Omnibus Deal Included
At 4:30 a.m. on May 7, 2026, EU legislators struck a deal that quietly reshuffled the EU AI Act compliance calendar for every AI company on the planet. Most organizations still haven’t processed what it means. Some think they’ve been handed a reprieve. They haven’t.
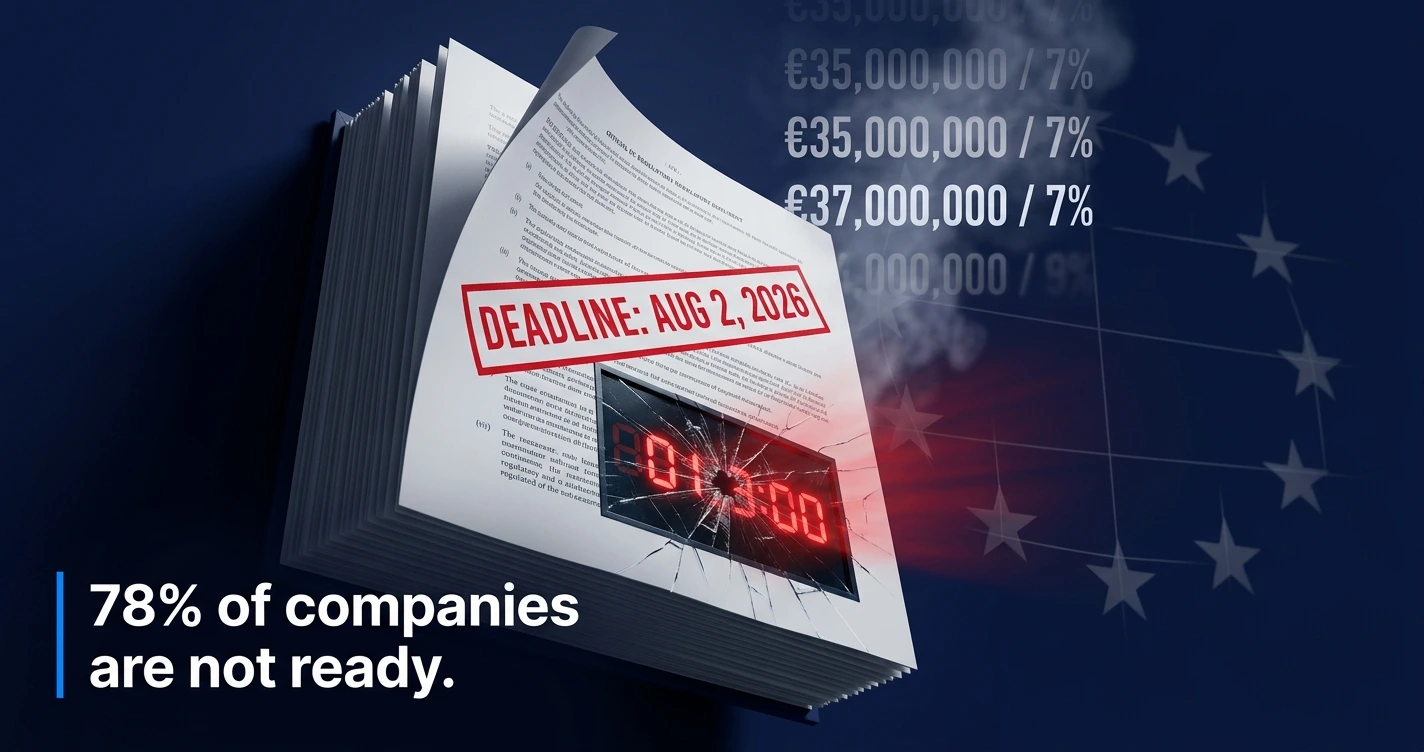
The EU AI Act, Regulation 2024/1689 and the world’s first comprehensive AI legal framework, has been enforcing prohibited practices since February 2025. GPAI model obligations have been live since August 2025. And the original high-risk AI deadline of August 2, 2026 is now roughly 70 days away as you’re reading this. Whether or not the Omnibus extension becomes law before that date, enforcement infrastructure is active, national authorities are operational, and the first criminal prosecution under the Act’s framework is already in the French courts.
This guide covers every deadline, every fine tier, every compliance action, updated as of May 24, 2026. If you’re a CTO, legal officer, or founder with EU users, here’s everything you need to act on Monday.
The May 7 Deal That Changed Everything
The EU AI Omnibus agreement, reached after six months of negotiations, is the most significant amendment to the AI Act since it passed. The headline change: the compliance deadline for high-risk AI systems under Annex III has been extended from August 2, 2026 to December 2, 2027. High-risk AI embedded in regulated products under Annex I gets until August 2, 2028.
Why did it happen? Latham and Watkins’ analysis puts it plainly: the extension responds to delayed harmonized standards, unclear governance structures, and heavier-than-expected compliance costs. In other words, the EU’s own implementation infrastructure wasn’t ready. The Omnibus wasn’t a strategic gift to industry. It was a rescue operation.
Critical Caveat: The Omnibus still requires formal endorsement and adoption before it becomes law. The August 2, 2026 deadline remains the operative legal deadline until formal adoption is complete. Do not treat the extension as guaranteed.
The deal also adds a new prohibition: “nudifier” AI applications capable of generating harmful intimate imagery, including CSAM, are now explicitly banned under the Act’s prohibited practices framework.
“A complete sectoral shift would fragment the AI Act’s horizontal framework into twelve separate compliance logics… I think it’s important we explore alternatives with Council.”
Brando Benifei, MEP and Lead AI Omnibus Negotiator, European Parliament (IAPP, April 2026)
Benifei’s comment reveals the deliberate architecture of the deal: the core legal structure of the Act was preserved intact. Simplification happened at the margins, on timelines, not obligations. The compliance work hasn’t changed. The clock has.
Full EU AI Act Enforcement Timeline
Deadline
What Applies
Status
Feb 2, 2025
Article 5 prohibited AI practices banned: social scoring, subliminal manipulation, real-time biometric identification in public spaces
Enforced
Aug 2, 2025
GPAI model obligations live. GPT-4, Claude, Gemini, and all foundation models must comply. EU AI Office governance active.
Enforced
Aug 2, 2026
Original Annex III high-risk AI deadline (operative until Omnibus is formally adopted)
~70 days
Dec 2, 2026
Watermarking and synthetic content disclosure for generative AI features
7 months away
Dec 2, 2027
Annex III standalone high-risk AI, under AI Omnibus deal (pending formal adoption)
Omnibus extension
Aug 2, 2028
High-risk AI embedded in regulated products (Annex I)
Omnibus extension
What’s Already Enforced Right Now
Before discussing what’s coming, understand what’s already active. Two major compliance waves have passed. If your organization hasn’t addressed them, you’re not preparing for the AI Act. You’re already in violation of it.
Prohibited Practices (Since February 2025)
Under Article 5, six categories of AI are flatly banned across the EU: social scoring systems, subliminal manipulation techniques, exploitation of vulnerable groups, real-time biometric identification in public spaces (with narrow law enforcement exceptions), emotion recognition in workplaces and schools, and, added by the Omnibus, nudifier applications. Investigations for workplace emotion recognition violations are already underway across multiple member states.
GPAI Model Obligations (Since August 2025)
If you provide or deploy a general-purpose AI model, meaning any LLM or foundation model capable of performing a wide range of tasks, you’ve been under obligation since August 2, 2025. In August 2025, 26 major AI providers signed the GPAI Code of Practice, including Microsoft, Google, Amazon, OpenAI, and Anthropic. Meta refused and now faces enhanced regulatory scrutiny from the EU AI Office.
The First Enforcement Case: Already in Court
On February 3, 2026, French prosecutors raided X’s Paris offices in a criminal investigation into Grok’s deepfake capabilities. Elon Musk and former CEO Linda Yaccarino were summoned for questioning in April. The case covers seven criminal offenses including creating sexual deepfakes, Holocaust denial, and operating an illegal platform as part of an organized criminal enterprise.
The precedent this sets: The behavior under scrutiny occurred in 2025. The criminal exposure materialized in 2026. Enforcement authorities will investigate backward in time. Your historical practices create present liability, not just your future ones.
High-Risk AI: Are You In Scope?
The most consequential classification decision your organization faces is this one: does your AI system qualify as high-risk under Annex III? Get it wrong in either direction and you either face penalties for non-compliance or waste millions over-engineering unnecessary conformity assessments.
Annex III defines eight categories of high-risk AI:
Biometric identification and categorization
Critical infrastructure management
Education and vocational training
Employment, worker management, and access to self-employment
Access to essential private and public services (credit scoring, insurance, healthcare triage)
Law enforcement
Migration, asylum, and border control
Administration of justice and democratic processes
The same underlying AI model can be minimal-risk as a customer service chatbot and high-risk if the identical model ranks job applicants or routes insurance claims. Context, deployment purpose, and actual use determine classification. Not technology architecture.
“‘It is just a chatbot’ is not a legal analysis. For Annex III systems, classification turns on intended purpose, function, use context and how the system is actually deployed… If there is no approved note explaining why a system is or is not high-risk, the decision is not strong enough to defend.”
IAPP Compliance Analyst, International Association of Privacy Professionals (IAPP, May 2026)
A 2026 study by the appliedAI Institute of 106 enterprise AI systems found 18% were clearly high-risk, while 40% had unclear classifications, concentrated in critical infrastructure, employment, law enforcement, and product safety. That 40% figure is alarming: it means nearly half of enterprise organizations genuinely cannot determine their own compliance status.
EU AI Act Fines, Penalties and Market Withdrawal
The EU AI Act doesn’t just fine companies. It can pull their products from EU markets entirely, a power GDPR never had. For SaaS companies, a single enforcement action could zero out European revenue overnight.
Violation Type
Maximum Fine
GDPR Comparison
Prohibited AI practices (Article 5)
35M euros or 7% global turnover
Exceeds GDPR ceiling
High-risk AI non-compliance
15M euros or 3% global turnover
Comparable to GDPR
Providing false information to regulators
7.5M euros or 1% global turnover
Below GDPR max
GPAI model violations
15M euros or 3% global turnover
New, no GDPR parallel
Always the higher of the two values applies. Italy’s AI Law (Law No. 132/2025, in force October 10, 2025) adds criminal liability under Decree 231, including disqualifying measures for up to one year. Finland became the first EU member state with full AI Act enforcement powers on December 22, 2025.
78%
of organizations have not taken meaningful steps toward AI Act compliance (Vision Compliance, April 2026)
18%
of organizations have fully implemented AI governance frameworks, despite 88% using AI operationally (ai2.work, Feb 2026)
40%
of enterprise AI systems have unclear risk classifications (appliedAI Institute, 2026)
50K euros
maximum cost of a conformity assessment per high-risk AI system, plus 20K to 50K euros in legal fees (SQ Magazine, April 2026)
The EU AI Act Compliance Checklist
Print this. Send it to your engineering lead. The conformity assessment process alone takes 6 to 12 months for a well-prepared organization. Starting after mid-2026, even with the Omnibus extension, means building extreme execution risk into your schedule.
Step 1: Build Your AI System Inventory
Identify every AI system in use across the organization, including third-party tools, APIs, and embedded models
Document each system’s intended purpose, deployment context, and actual use case
Flag any system touching employment decisions, credit, insurance, healthcare triage, law enforcement, or biometrics as high-risk candidates
Establish a process to capture new AI systems as they ship. Inventory is continuous, not a one-time audit.
Step 2: Classify Each System by Risk Tier
Conduct formal written classification analysis for each system. Verbal assessments do not satisfy documentation requirements.
Determine operator vs. deployer role for each system, as obligations differ significantly
Document classification rationale with approved sign-off, not just internal consensus
Step 3: For High-Risk AI, Technical Compliance
Implement automatic logging of all system events under Articles 12 and 13. Logs must enable tracing back to specific inputs and decisions.
Define log retention periods appropriate to the system’s sectoral law requirements
Design human oversight into the system architecture. The system must be stoppable, overridable, and actively monitored.
Prepare technical documentation and conformity assessment package (budget 6 to 12 months of engineering time)
Determine whether your system requires a third-party notified body, required for roughly 30 to 40% of high-risk systems
Step 4: GPAI and Generative AI, Immediate Actions
If you deploy any LLM or foundation model in the EU, compliance is required now, not in 2027
Implement watermarking and synthetic content disclosure for all generative AI features before December 2, 2026
Review copyright compliance for training data if you’re a model provider
If training compute exceeds 10 to the power of 25 FLOPs, you face systemic risk obligations including adversarial testing and incident reporting
Step 5: Governance Infrastructure
Appoint an AI compliance owner with documented authority
Establish an AI literacy program for staff interacting with AI systems (Article 4 requirement)
Build incident response and reporting procedures for AI system failures
If operating in Italy, review criminal liability exposure under Law No. 132/2025 specifically
Monitor national authority developments across all EU markets where you operate. There are 27 separate enforcement environments.
The Uncomfortable Truths About EU AI Act Compliance
Any compliance guide that only tells you what to do, without acknowledging what’s broken about the framework you’re trying to comply with, isn’t being straight with you.
The Commission Missed Its Own Deadline
The Commission was legally required to publish final guidelines on high-risk AI classification by February 2, 2026. That deadline was missed. As of late May 2026, those guidelines exist only in draft form, published 15 months after the Act entered into force. Companies are being asked to classify their AI systems according to rules the regulator hasn’t finished explaining. That’s not a compliance failure by industry. It’s a design failure by the Commission.
The SME Cost Is Existential
“These burdensome regulations put AI companies at a competitive disadvantage by driving up compliance costs, delaying product launches, and imposing requirements that are often impractical or impossible to meet.”
Oliver Roberts, Attorney, Holtzman Vogel (Bloomberg Law, February 2025)
For a startup deploying a single high-risk AI system, a 50,000 euro conformity assessment plus 20,000 to 50,000 euros in legal fees isn’t regulatory overhead. It’s potentially existential. Documentation preparation alone accounts for up to 40% of total assessment costs. The requirement for detailed logging creates genuine data storage and privacy exposure that larger enterprises can absorb and smaller ones often can’t.
Enforcement Will Be Fragmented and Unpredictable
There are 27 national enforcement authorities with different legal traditions, resource levels, and political priorities. Italy has criminal liability statutes. France has prosecutorial infrastructure that moved on X within months. Other member states are still establishing their market surveillance authorities. If you operate across the EU, you’re operating across 27 different enforcement environments under one regulation that doesn’t resolve those differences for you.
The Delay Doesn’t Mean Wait
The temptation, with a 16-month extension in hand, is to defer. That’s the wrong read. The hard compliance work, covering inventory, classification, technical documentation, and logging architecture, doesn’t get easier with time. Organizations starting compliance programs after mid-2027 won’t have months to refine. They’ll have weeks. The Omnibus extension buys time to do the work well. Not time to avoid doing it.
FAQ: What Everyone Is Searching Right Now
What is the EU AI Act compliance deadline in 2026?
The operative legal deadline for high-risk AI under Annex III remains August 2, 2026, until the AI Omnibus is formally adopted. A provisional political agreement reached May 7, 2026 would extend this to December 2, 2027, but formal adoption is still pending. Prohibited AI practices have been enforced since February 2, 2025. GPAI obligations have been active since August 2, 2025.
Does the EU AI Act apply to US, UK, and Australian companies?
Yes. The EU AI Act has extraterritorial scope identical to GDPR. Any company whose AI system’s output reaches EU users, through direct sales, SaaS subscriptions, APIs, or downstream integrations, is in scope. Non-EU companies face identical fines and the same risk of market withdrawal orders as EU-based organizations.
What are the EU AI Act fines and penalties?
Fines operate on three tiers: up to 35 million euros or 7% of global annual turnover for prohibited AI practices; up to 15 million euros or 3% for high-risk system non-compliance; up to 7.5 million euros or 1% for providing false information to regulators. Always the higher of the two values applies. These exceed GDPR maximums. Market withdrawal, unavailable under GDPR, is an additional enforcement tool.
What AI systems are considered high-risk under the EU AI Act?
High-risk AI falls into eight Annex III categories: biometrics, critical infrastructure, education and training, employment and worker management, access to essential services (credit, insurance, healthcare), law enforcement, migration and border control, and administration of justice. Context determines classification. The same model can be minimal-risk as a chatbot and high-risk if used to rank job applicants.
What is the EU AI Omnibus and what did it change?
The EU AI Omnibus is a package of amendments to the AI Act agreed provisionally on May 7, 2026. It extends the Annex III high-risk deadline from August 2, 2026 to December 2, 2027, and Annex I embedded systems to August 2, 2028. It adds a ban on nudifier applications. Core obligations, including logging, oversight, documentation, and conformity assessment, are unchanged. Formal adoption is still pending.
What is a GPAI model under the EU AI Act and do I need to comply?
A General-Purpose AI model is any large model trained on broad data capable of wide-ranging tasks, primarily LLMs and foundation models. If you provide or deploy one affecting EU users, obligations covering transparency, documentation, and copyright compliance have been in force since August 2, 2025. Models trained above 10 to the power of 25 FLOPs face additional systemic risk requirements including adversarial testing and incident reporting.
Does the EU AI Act have SME exemptions?
The AI Act includes lighter obligations for SMEs in some procedural areas, and the EU AI Office provides compliance support tools. However, the core obligations, covering risk classification, technical documentation, and conformity assessment for high-risk systems, apply to SMEs deploying or providing high-risk AI. There is no blanket SME exemption from substantive requirements.
What the Next 18 Months Actually Look Like
Here’s the honest forward view. The Commission’s classification guidelines will be finalized, probably before the end of 2026. National enforcement authorities will complete their buildout across most member states by early 2027. The first high-risk AI system enforcement actions, separate from the X/Grok criminal case, will likely arrive in the second half of 2027, targeting the clearest Annex III violators: employment AI, credit scoring systems, and biometric tools deployed without proper documentation.
The Brussels Effect will continue. Companies building for global markets will build to EU AI Act standards regardless of where they’re headquartered or where their users are concentrated. This is already shaping product decisions in San Francisco, London, and Sydney.
Three things to watch and act on now:
Commission classification guidelines final status. Still in draft as of publication; formal issuance changes your classification certainty significantly.
AI Omnibus formal adoption date. The August 2026 deadline remains operative until the deal is legally adopted; track this weekly.
Your December 2, 2026 watermarking deadline. If you ship any generative AI feature into the EU, synthetic content disclosure is a hard engineering deadline just seven months away.
The EU AI Act is the most consequential digital regulation since GDPR and by several measures more demanding. The companies that emerge from this compliance cycle in strong position won’t be the ones who started latest. They’ll be the ones who built inventory, governance, and documentation discipline before they needed it.
Stay Ahead of AI Regulation
The Neural Loop delivers the week’s most important AI policy, research, and business developments, every Friday, no noise.
Subscribe to The Neural Loop
ChatGPT vs Claude vs Gemini 2026: The Honest Head-to-Head | NeuralWiredNeuralWired
Intelligence on Artificial Intelligence
AI Comparison Guide
ChatGPT vs Claude vs Gemini 2026 | The Honest Head-to-Head Developers Actually Need
ChatGPT’s market share collapsed 30 points in 14 months. Claude tripled its share in a single quarter. Gemini quadrupled. The race is real, and the winner depends entirely on what you’re building.
NeuralWired Research Desk·May 24, 2026·Updated for Claude Opus 4.7 · GPT-5.5 · Gemini 3.1 Pro·14 min read
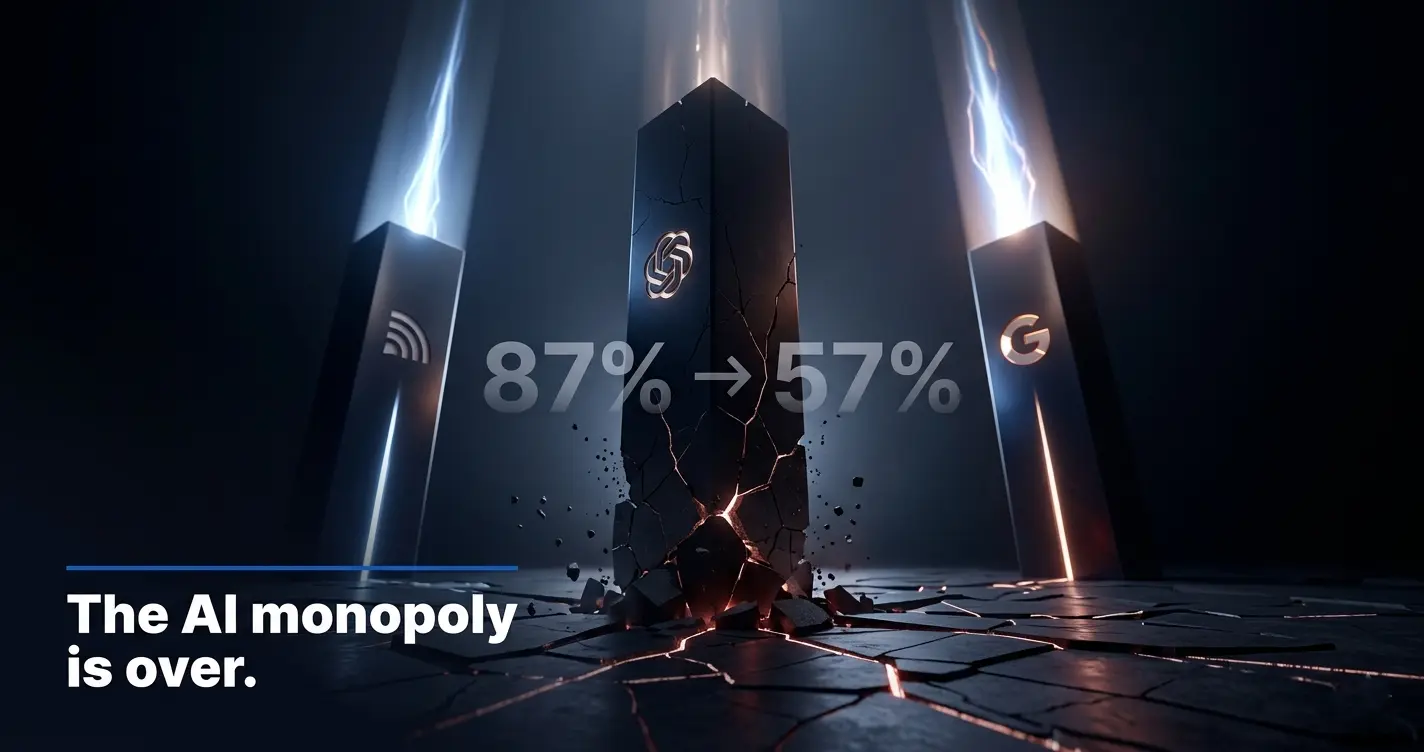
Fourteen months ago, ChatGPT held 87% of generative AI web traffic. As of March 2026, it’s below 57%. That’s not a blip, that’s the fastest collapse of market dominance in consumer software since Internet Explorer lost the browser wars. Gemini went from 6% to 25%. Claude went from 1.4% to over 6%. And we’re still early.
If you’re a developer routing API calls, a CTO evaluating an enterprise contract, or a founder choosing the core model for your product, the decision you make this quarter has real consequences. This guide cuts through the benchmark theater and gives you the honest comparison: what each model actually does best, what it costs, and where the traps are.
−30pt
ChatGPT market share drop, Jan 2025 → Mar 2026
4×
Gemini’s traffic share growth over same period
3×
Claude’s share gain in a single quarter
The Market Shift Nobody Predicted
The mainstream narrative going into 2025 was settled: OpenAI won. ChatGPT was the Google of AI, first-mover with a moat so deep no challenger could cross it inside five years. That narrative is now wrong.
The structural break happened in three waves. First, model quality parity arrived faster than anyone expected. Claude 3.7, Gemini 3.0, and then the jump to Claude 4.x and Gemini 3.1 Pro showed that OpenAI’s quality lead was a 12-month advantage, not a permanent one. By late 2025, independent benchmarks showed all three platforms within single-digit percentage points on general capability tests.
Second, Google’s distribution machine activated. Gemini bundled into Gmail, Docs, Sheets, and Android didn’t win users through product quality, it converted existing Google Workspace daily actives into AI users overnight. That’s how you go from 6% to 25% in twelve months without necessarily being the best model in the room.
Third, Claude’s enterprise breakout. While Gemini was winning on distribution and ChatGPT on consumer scale, Anthropic quietly captured the segment willing to pay the most: regulated industries. The Claude iOS app hit #1 on the U.S. App Store on February 28, 2026, the first time any AI app surpassed ChatGPT in daily downloads. Claude Code’s weekly active users doubled between January and April. Anthropic’s annualized revenue reached $14 billion as of February 2026, up from $1 billion in 2024. That’s a 14× increase in two years.
Our Read
This maps almost exactly to the browser wars. ChatGPT is Internet Explorer, dominant, sticky, losing ground slowly. Gemini is Chrome, distribution king, winning by presence not choice. Claude is Firefox, smaller but chosen deliberately by users who care about quality. The key difference: all three are improving simultaneously, and the market is still growing. There’s no single winner. That is the story.
Current Models at a Glance
Platform
Current Flagship
Context Window
Consumer Tier
API Input/Output (per 1M tokens)
OpenAI / ChatGPT
GPT-5.5 (Apr 2026) GPT-5.4 Pro via API
~250K tokens (Enterprise)
Free / Plus $20/mo / Pro $200/mo
$1.75 / $14.00 (GPT-5.2)
Anthropic / Claude
Claude Opus 4.7 Apr 2026
1M tokensNew
Pro ~$20/mo / Max ~$50+/mo
$5.00 / $25.00
Google / Gemini
Gemini 3.1 Pro (Feb 2026)
1–2M tokens
Advanced $19.99/mo
$2.00 / $12.00 (Flash: $0.50 / $3.00)
A few things worth flagging before we get into comparisons. Claude Opus 4.7 is the most significant recent release: it arrives with a 1M token context window (four times larger than Opus 4.6), high-resolution vision at 2,576px, and a self-verification capability that reduces hallucinations on factual tasks. GPT-5.2 is being retired June 5, 2026, any enterprise contract referencing that model needs revisiting now. And Gemini’s naming situation is still a genuine headache for API buyers: “Gemini 3 Pro” (consumer) and “Gemini 3.1 Pro Preview” (developer docs) are the same model, sold under two different labels.
Coding & Developer Benchmarks
This is the comparison developers actually search for, and it has a clearer answer than any other category in 2026.
Doubled between January and April 2026 — developer consensus forming
—
Claude’s lead on SWE-bench Verified is the single clearest differentiation in this entire comparison. A 3–4 point gap on academic benchmarks is noise. A 3–4 point gap on real GitHub issue resolution, across thousands of production repositories, is something engineering leads should care about.
That said, the cost math complicates things fast. If you’re building a production API pipeline and routing to Claude at $5/$25 per million tokens, versus GPT-5.4 Mini at roughly 6× less than GPT-5.4 Standard, you have a real ROI question to answer. For most B2C product workloads, quick code completions, light refactors, IDE copilot interactions, GPT-5.4 Mini at near-Claude-level performance for a fraction of the cost is the rational choice. Route the complex, high-stakes generation tasks to Claude. Route the volume to Mini or Gemini Flash.
“Claude is better for complex coding. Claude Opus 4.7 scores 87.6% on SWE-bench Verified, versus GPT-5.4’s approximately 84%. For full-file refactors and long-context debugging, Claude leads. For quick scripts and IDE plugin support, ChatGPT remains competitive.”
This is Gemini’s clearest win. On graduate-level science questions, the kind of reasoning required in drug discovery, materials science, and academic research, Gemini 3.1 Pro scores 94.1–94.3% on GPQA Diamond. GPT-5.4 follows at ~92.8%. Claude Opus 4.6 sits at ~91.3%. For enterprise buyers in scientific or research-heavy domains, that gap matters.
Knowledge Depth (Humanity’s Last Exam)
HLE is the hardest knowledge benchmark available, designed explicitly to resist saturation. The scores: Claude 53 | GPT-5.4 48 | Gemini 40 (BenchLM.ai, April 2026). Claude wins on the single hardest knowledge test, which counters the “Gemini is the smartest” narrative you’ll encounter in a lot of enterprise sales conversations.
Context Window Reality
Gemini 3.1 Pro offers 1–2M tokens, technically the largest. Claude Opus 4.7 now matches at 1M. ChatGPT Enterprise sits around 250K. Worth knowing: multiple engineers have noted in 2026 benchmark reviews that performance at 1M+ token contexts degrades meaningfully on most tasks. Advertised context is not reliable context. Test your specific workload at scale, don’t rely on the spec sheet.
Multimodal
Gemini has the structural advantage here, Google’s investment in vision and audio AI runs deeper than either competitor’s, and Gemini 3.1 Pro’s multimodal performance leads on most third-party evaluations. Claude Opus 4.7’s new high-resolution vision (2,576px) closes the gap on document and image analysis. ChatGPT remains competitive across all modalities but doesn’t lead on any specific visual benchmark in 2026.
API Pricing: The Number That Kills Deals
Consumer tiers have converged: all three platforms sit at $19–$20/month for their mid-range plans. The API is where the real decision lives, and where the gap is significant.
Model
Input (per 1M tokens)
Output (per 1M tokens)
Notes
Claude Opus 4.7
$5.00
$25.00
Up to 90% savings with prompt caching
GPT-5.2
$1.75
$14.00
Retiring June 5, 2026
Gemini 3.1 Pro
$2.00
$12.00
Strong default for cost-conscious builds
Gemini 3 Flash
$0.50
$3.00
Best cost-efficiency for high-volume workloads
GPT-5.4 Mini
~6× cheaper than Standard
—
~94% of Standard’s coding performance
Grok 4.1
$0.20
$0.50
Cheapest frontier API overall
Cost Reality Check
Claude is 2.5–3× more expensive than Gemini at API level. At 100M tokens/month, that’s a $300,000 annual cost difference. Claude’s prompt caching (up to 90% savings on repeated context) makes it competitive for long-context applications that reuse significant prompt context, legal document review, multi-turn research, large codebase analysis. For high-volume, low-complexity tasks, Gemini Flash or GPT-5.4 Mini is the rational default.
Enterprise Reality: Who’s Winning Where
The single-vendor AI strategy is over. Internal data from multiple enterprise surveys in 2026 shows the dominant enterprise stack as: Claude for deep analytical, legal, and compliance output + ChatGPT for research, workflow automation, and employee-facing tools + Gemini for Google Workspace-native workflows. These aren’t competing, they’re co-existing in the same organization.
“ChatGPT is the overwhelming leader in consumer AI with more than 900 million weekly active users, and over 50 million subscribers… Search usage has nearly tripled in a year, and our ads pilot reached more than $100 million in ARR in under six weeks.”
That’s the official OpenAI position. What the official position omits: OpenAI is projected to lose $14 billion in 2026, nearly triple earlier estimates, with cumulative losses of $44 billion through 2028 and profitability not expected before 2029. Only 5.5% of ChatGPT’s 900 million users pay. The ads pilot (mentioned casually in Altman’s quote) signals that the product experience for free-tier users may change fundamentally.
Meanwhile, Anthropic is concentrating on the segment willing to pay most. Claude reportedly wins approximately 70% of new enterprise AI deals in regulated industries, legal, finance, healthcare, compliance, because of its documented lower hallucination rate and its “uncertainty flagging” behavior: it declines to answer when it’s not confident rather than confabulating. In industries where an AI error has financial or legal consequences, that behavior is worth a pricing premium.
Google’s enterprise advantage is structural, not earned. 120,000+ enterprise customers and 95% of top-20 global SaaS companies use Google Cloud AI, but much of that is Gemini arriving inside Workspace by default, not the result of a competitive evaluation. CTOs in Google-heavy shops evaluating ChatGPT or Claude as Workspace replacements are solving the wrong problem. Evaluate them as additive tools for tasks Workspace doesn’t do well.
Use Case Mapping
Best: Claude
Complex Code Generation & Refactoring
87.6% SWE-bench, 1M token context, Claude Code doubling WAU. The empirical choice for production-quality output on non-trivial engineering tasks.
Best: Gemini
Google Workspace Workflows
If your team lives in Gmail, Docs, and Sheets, Gemini is already there. The integration advantage bypasses any benchmark comparison.
Best: Claude
Legal, Compliance & Finance
Lower hallucination rates, uncertainty flagging, and 70% win rate in regulated-industry enterprise deals. The reliability premium is real and priced accordingly.
Best: ChatGPT
Third-Party Integrations & Plugins
92% of Fortune 500 adoption, Codex (3M weekly active developers), and the broadest plugin/tool ecosystem. For horizontal workflow automation, ChatGPT’s network effects win.
Best: Gemini
High-Volume, Cost-Sensitive APIs
Gemini Flash at $0.50/$3.00 per 1M tokens is the most cost-efficient frontier API for applications where multimodal capability is relevant and volume is high.
Best: Gemini
Scientific Research & Reasoning
94.1% GPQA Diamond. For drug discovery, materials science, and graduate-level academic analysis, Gemini’s reasoning benchmark lead is real and consistent.
What the Benchmarks Don’t Tell You
The Hallucination Problem Isn’t Solved
An EBU/BBC study found 48% of responses from free-tier chatbots contained accuracy issues as recently as mid-2025. Claude Opus 4.1 recorded 0% hallucination on the AA-Omniscience benchmark, but only because it declined to answer when uncertain rather than guessing. Gemini 3.1 Pro cut its hallucination rate by 38 percentage points, which is the biggest improvement of any model but still leaves it at ~50% on certain tests. Westlaw AI, built specifically for legal research, hallucinated more than 34% of the time on challenging queries.
Healthcare Warning
The ECRI Institute ranked misuse of AI chatbots as the #1 health technology hazard of 2026, explicitly naming ChatGPT, Claude, Gemini, Copilot, and Grok as “not regulated as medical devices and not validated for healthcare purposes.” Any healthcare deployment carries compliance exposure regardless of platform.
Benchmark Saturation Is Real
MMLU now scores 88–94% across all top models. It no longer differentiates them. The benchmarks that do differentiate, SWE-bench Pro, ARC-AGI-2, Humanity’s Last Exam, are not the ones most buyers understand or test themselves. When a vendor’s sales deck shows you a benchmark chart, ask specifically which benchmark, and whether it’s been saturated. Most popular media comparisons cite saturated benchmarks, making rankings look more meaningful than they are.
Vendor Lock-In Accumulates Invisibly
Enterprises building workflows on Claude’s Projects system, Google’s Workspace Gemini integration, or ChatGPT’s Custom GPTs ecosystem are accumulating switching costs that won’t show up in today’s pricing comparison. The platform decision made in 2026 shapes what tools are available, and at what negotiating leverage, in 2028. The time to think about this is before the integration is built, not after.
“OpenAI is projected to lose $14 billion in 2026, nearly triple earlier estimates for 2025, even as it reports $25 billion in annualized revenue and 900 million weekly ChatGPT users. The company expects cumulative losses of $44 billion between 2023 and 2028, with profitability not arriving until 2029 at the earliest.”
, European Business Magazine, citing The Information internal financial projections, 2026. Read the full report →
This is the most important contrarian data point in the entire comparison. The market leader has the biggest user base and the biggest losses. The ads pilot signals a potential shift in the free-tier product experience. That changes the calculus for any organization that’s built workflows on the assumption that free-tier ChatGPT performs identically to paid ChatGPT. It may not for much longer.
The Verdict
There’s no single winner. Anyone telling you otherwise is selling something. Here’s the honest split:
ChatGPT
Best for
Consumer-scale deployment, third-party integrations, employee-facing tools, and organizations where Fortune 500 adoption rates reduce procurement friction. The horizontal choice.
Claude
Best for
Complex code generation, legal and compliance work, long-document analysis, and any use case where hallucination has real-world consequences. The quality-first choice.
Gemini
Best for
Google Workspace-native workflows, high-volume cost-sensitive APIs, scientific reasoning, and multimodal tasks. The distribution and efficiency choice.
Most serious enterprise buyers in 2026 use two of the three, typically Claude plus one of the other two depending on their infrastructure. The overlap is real and intentional. These platforms are not substitutes for each other; they’re complements with different cost structures and different failure modes.
Watch three things over the next 6–18 months. First, whether OpenAI’s ads pilot scales, this is the signal for how the free-tier product experience evolves. Second, whether Claude’s API pricing moves; Anthropic’s current premium pricing reflects confidence in the enterprise market, but competitive pressure from Gemini Flash is real. Third, whether any platform meaningfully solves hallucination at the infrastructure level, rather than at the “decline to answer” workaround level. That’s the technical moat that doesn’t yet exist.
Frequently Asked Questions
Which AI is better in 2026 | ChatGPT, Claude, or Gemini?
There is no single winner. Claude Opus 4.7 leads on coding (87.6% SWE-bench) and writing quality. ChatGPT (GPT-5.4/5.5) leads on ecosystem breadth and third-party integrations. Gemini 3.1 Pro leads on reasoning benchmarks (94.1% GPQA) and multimodal tasks. Most professional users in 2026 use two of the three. Source: BenchLM.ai, April 2026.
Is ChatGPT or Claude better for coding?
Claude is better for complex coding. Claude Opus 4.7 scores 87.6% on SWE-bench Verified vs GPT-5.4’s ~84%. For full-file refactors and long-context debugging, Claude leads. For quick scripts and IDE plugin support, ChatGPT remains competitive. Most engineering teams use both. Source: LearnDrive, 2026.
What is the cheapest AI API in 2026?
Gemini 3 Flash is the cheapest frontier API at $0.50 input / $3.00 output per million tokens. Grok 4.1 charges $0.20/$0.50, making it cheapest overall. GPT-5.4 Mini is 6× cheaper than GPT-5.4 Standard. Claude Opus 4.7 is most expensive at $5.00/$25.00, but offers up to 90% savings via prompt caching on repeated-context workloads. Source: IntuitionLabs, Feb 2026.
How many people use ChatGPT in 2026?
ChatGPT has over 900 million weekly active users and 50 million paying subscribers as of March 2026. It processes 2.5 billion daily prompts. OpenAI generates $25 billion in annualized revenue, but projects a $14 billion operating loss in 2026 due to compute costs. Source: OpenAI, March 31, 2026.
Is Gemini better than ChatGPT in 2026?
Gemini 3.1 Pro leads on reasoning benchmarks (94.1% vs 92.8% GPQA Diamond), offers a larger context window (1–2M tokens), and excels at multimodal tasks. ChatGPT leads on ecosystem, integrations, and consumer scale (900M WAU vs 750M MAU). For Google Workspace users, Gemini has a structural advantage that makes the comparison largely moot. Source: LearnDrive, 2026.
Does Claude hallucinate less than ChatGPT?
Yes, in independent testing. Claude Opus 4.1 recorded 0% hallucination on the AA-Omniscience benchmark by declining to answer when uncertain. However, no AI model is hallucination-free, the EBU/BBC found 48% of free-tier AI responses had accuracy issues in 2025. Claude’s “I don’t know” behavior matters most in legal, compliance, and financial use cases. Source: Suprmind AI, May 2026.
Which AI has the largest context window in 2026?
Gemini 3.1 Pro offers the largest at 1–2 million tokens. Claude Opus 4.7 (April 2026) now reaches 1 million tokens. ChatGPT Enterprise supports approximately 250,000 tokens. Important caveat: practical performance degrades at maximum context lengths across all platforms. Advertised context window ≠ reliable context window. Test your specific workload. Source: Tech Insider, April 2026.
The Neural Loop
Weekly intelligence on AI models, enterprise deployments, and the business moves that matter. No hype. No padding. Just the signal.
Subscribe Free →
Artificial IntelligenceCareer Guide • May 23, 2026
How to Become a Prompt Engineer in 2026: The Honest Guide
The standalone job title is collapsing. The underlying skill is becoming mandatory across every technical role. Here’s the real path, skills, salaries, courses, and the warnings nobody else will tell you.
N
NeuralWired Editorial
12 min read • Updated May 23, 2026
⏱ 12 min
In 2023, Anthropic posted a job listing that broke the internet. The role: Prompt Engineer and Librarian. The salary ceiling: $335,000. The requirement that caused the real frenzy: no PhD, minimal coding experience. For a brief moment, the world believed you could earn a doctor’s salary just for being very, very good at talking to chatbots.
That moment is over.
Searches for “prompt engineer” on Indeed have dropped 86% from their April 2023 peak. Microsoft surveyed 31,000 workers across 31 countries and found that Prompt Engineer ranked second-to-last among roles companies plan to hire in the next 18 months. The standalone title, for most organizations, never really materialized.
And yet, here you are, reading a guide on how to become a prompt engineer. And the search volume for that exact phrase has surged 5,000%+ in the past 12 months. Both things are true at once, and the tension between them is exactly what this guide is about.
Our Read
The job title is dying. The skill is becoming mandatory. If you’re learning how to become a prompt engineer in 2026, you’re not chasing a job title, you’re building a capability layer that will sit underneath every technical role in the next decade. That reframe changes everything about how you should approach this.
The Paradox Nobody Is Talking About
Two credible, opposing forces are pulling at this field simultaneously. Understanding both is the foundation of making any smart career decision here.
The optimistic case is real: Grand View Research puts the global prompt engineering market at $222 million in 2023, projecting it to hit $2.06 billion by 2030, a CAGR of 32.8%. McKinsey reports that 71% of organizations now use generative AI in at least one business function. Every one of those deployments requires someone who knows how to work with language models systematically. That’s real demand.
The skeptical case is equally real. Fortune reported in May 2025 that Allison Shrivastava, economist at Indeed, put it plainly:
Prompt engineering as a skill is still definitely a good thing to have, but it’s not an entire title.
Allison Shrivastava, Economist, Indeed (Fortune, May 2025)
Jared Spataro, Microsoft’s Chief Marketing Officer for AI at Work, was even more direct. After his team’s survey of 31,000 workers across 31 countries:
Two years ago, everybody said, ‘Oh, I think prompt engineer is going to be the hot job.’ It’s not turning out to be true at all.
Jared Spataro, CMO AI at Work, Microsoft (Wall Street Journal, 2025)
His argument: modern AI models now ask clarifying questions, acknowledge uncertainty, and self-iterate. The human middleman who translated vague instructions into precise prompts is being absorbed into the model itself.
So which camp is right? Both. The reconciliation is simple: the discipline is real; the job description isn’t. Prompt engineering is becoming what spreadsheet literacy became in the 1990s, not a career, but a baseline competency that elevates every career it touches. Andrew Ng made this comparison explicitly, and it’s the clearest mental model available.
32.8%
Projected annual market growth (CAGR) through 2030
71%
Organizations now using generative AI in at least one function
−86%
Drop in “prompt engineer” job searches on Indeed since peak (April 2023)
What a Prompt Engineer Actually Does
Strip the hype and the definition is precise. Prompt engineering is the systematic practice of designing, structuring, and optimizing text instructions, prompts, to guide large language models like OpenAI’s ChatGPT, Anthropic’s Claude, and Google’s Gemini toward accurate, relevant, and consistent outputs. It combines natural language processing, cognitive science, linguistics, and iterative systems design.
That last part matters: iterative systems design. The most important thing Isa Fulford’s widely-used curriculum at DeepLearning.AI establishes is that effective prompting is not about finding “magic words.” It’s about systematic evaluation, measurement, and structural thinking. The people who treat it that way build things that work in production. The people who treat it as a creative guessing game produce inconsistency at scale.
The Core Techniques You Actually Need to Know
Technique
What It Is
When to Use It
Zero-shot prompting
No examples given; model uses training knowledge alone
Simple, well-defined tasks; quick prototyping
Few-shot prompting
1–5 examples embedded in the prompt to guide output format
Consistent formatting, classification tasks, tone matching
Chain-of-thought (CoT)
Instructs model to reason step by step before answering
Logic, math, multi-step problem solving
Retrieval-Augmented Generation (RAG)
Combines LLM with external knowledge base to reduce hallucination
Background instructions defining model persona, scope, and constraints
Product deployments, customer-facing AI tools
Prompt chaining
Linking multiple prompts sequentially; each output feeds the next
Complex multi-step workflows, agent pipelines
The Skills That Actually Matter in 2026
Here’s where most guides go wrong: they describe the skills that got people hired in 2023. The market has moved. Based on aggregated requirements from active listings at Google, Microsoft, Amazon, JPMorgan Chase, Booz Allen Hamilton, and leading AI-native startups, here’s what employers are actually looking for right now.
LLM API proficiency, At minimum one of: OpenAI, Anthropic Claude, Google Gemini, or Microsoft Copilot. Not just using the chat interface, working with the API programmatically.
Prompt technique mastery, Zero-shot, few-shot, chain-of-thought, RAG. These aren’t optional vocabulary; they’re the toolkit every practitioner is expected to have.
Python programming, Strongly preferred for senior roles; not always required for entry-level marketing or content positions. If you want engineering-tier compensation, this is non-negotiable.
Token economics and context window management, Understanding how models handle input length, what falls out of context, and how to structure information for reliability.
Evaluation and benchmarking, The ability to design A/B tests for prompts, measure output quality systematically, and build evals that catch prompt drift when models update. This is where most entry-level practitioners fall short.
Responsible AI and bias detection, Not a box-check skill. Organizations deploying AI at scale have legal and reputational exposure; people who can identify and mitigate bias in LLM outputs are genuinely scarce.
Domain expertise, The highest-value prompt engineers are domain experts first. A healthcare analyst who can engineer clinical documentation prompts is worth more than a generic prompt specialist. The skill multiplies domain knowledge; it doesn’t replace it.
⚠ Career Risk
The “no coding required” framing from 2023 is obsolete for any role paying over $90K. Entry-level positions at non-technical companies still exist without code, but AI lab and enterprise engineering roles almost universally require Python and API experience. Plan accordingly.
Salaries: The Honest Numbers
The $335,000 Anthropic listing was real. It was also an outlier at an elite AI safety lab during a period of acute talent scarcity, for a senior specialized role. Using it as a benchmark is like using NBA contracts to estimate what competitive basketball players earn. Here’s the actual range.
Source
Salary Range
Context
ZipRecruiter (June 2025)
$33K – $95K (avg $63K)
Includes contract and part-time; skews low
Glassdoor (via Coursera, Dec 2025)
$90K – $160K (avg $123K)
Full-time tech roles; more representative for career changers
Big Tech (Google, Microsoft, Amazon, Meta)
$110K – $250K
Senior IC and staff-level roles; equity separate
AI Labs (OpenAI, Anthropic, Cohere)
$150K – $335K+
Equity-heavy; total comp often exceeds base significantly
Government / Consulting (Booz Allen)
Up to $212K
Cleared roles; lower equity but high stability
The signal worth watching: Forward Deployed Engineers (FDEs) are where the highest-demand adjacent hiring is concentrating right now. OpenAI formalized its FDE program at scale on May 11, 2026, these are hybrid engineering and client-facing practitioners who embed with enterprise customers to deploy AI in production. Job postings for FDEs reportedly grew 800%+ in 2025. If you’re building prompt engineering skills and want a clear career target, FDE is the most concrete emerging track.
Best Courses and Certifications in 2026
No industry-standard certification equivalent to AWS or PMP exists in this field yet. Expert consensus is consistent: a portfolio of real AI applications outweighs any certificate. That said, one recognized credential on a resume does open doors, it signals fluency to hiring managers who don’t know how else to screen for it.
Course
Provider
Cost
Credibility Signal
ChatGPT Prompt Engineering for Developers
DeepLearning.AI (Andrew Ng + Isa Fulford)
Free, ~90 min
Highest technical credibility among engineering hiring managers
Prompting Essentials
Google Cloud Skills Boost
Paid (Credly badge issued)
HR-recognizable; Google brand carries weight in enterprise
Prompt Engineering for ChatGPT
Vanderbilt / Coursera
~$49 certificate, ~18 hours
University-backed; more respected by non-technical HR
AI Prompt Engineering Series
IBM
Varies
Enterprise-credible brand; useful for Fortune 500 applications
Azure OpenAI Prompt Engineering
Microsoft Learn
Free
Best for roles targeting Microsoft Copilot ecosystem
Best strategy: Complete one certificate from a recognized platform (DeepLearning.AI for technical roles; Google for enterprise roles). Then build a GitHub repository with three to five real LLM application examples, prompt chains, evaluation scripts, RAG pipelines. The portfolio is what gets you the interview. The certificate is what gets you past the keyword filter.
Step-by-Step Career Roadmap
This is for three distinct readers: developers who want to integrate AI into existing work, career switchers approaching this from a non-technical background, and engineering leaders building team capabilities. The path diverges early.
For Developers
Start with the DeepLearning.AI course, 90 minutes, free, co-taught by Andrew Ng and Isa Fulford. It’s the closest thing to canonical teaching the field has, and engineering hiring managers recognize it. Do it this week.
Build with the APIs directly, Sign up for OpenAI and Anthropic developer accounts. Write scripts. Chain prompts. Build a small RAG prototype using your own documents. The tactile experience is irreplaceable.
Learn to evaluate, not just generate, The hardest part of prompt engineering at production scale isn’t writing good prompts; it’s detecting when they fail. Build an eval suite for your prompts. Measure output quality. This is what separates junior from senior practitioners.
Move toward context engineering, The field is converging on “context engineering”, managing what information enters the model’s input window at runtime. This is the next layer above basic prompting. Study LangChain, agent frameworks, and retrieval architecture.
Target FDE or LLM Engineer roles, These titles are where serious engineering-grade prompt work is actually happening and where compensation reflects the skill level.
For Career Switchers (Non-Technical)
The pure “prompt engineer” title pivot carries real risk. The correct framing is not “become a prompt engineer” but rather “add prompting capability to your domain expertise.” A healthcare writer who can engineer clinical documentation prompts is far more valuable than a generic prompt specialist with no domain background. The skill multiplies; it doesn’t substitute.
Identify your domain expertise first. That’s your differentiator.
Take the Google Prompting Essentials or Vanderbilt/Coursera certificate, HR-recognizable and accessible without technical prerequisites.
Build domain-specific examples: if you’re in finance, build a portfolio of prompts that automate financial reporting tasks. If you’re in healthcare, build clinical documentation workflows.
Target titles like AI Trainer, AI Integration Specialist, Applied AI Analyst, these are where standalone prompt-adjacent hiring is actually occurring in 2026, not under the “Prompt Engineer” label.
The Webmaster Analogy
In the mid-1990s, “Webmaster” was a defined, specialized, high-paying role. Within a decade, web skills were distributed across designers, developers, content managers, and marketers, the title disappeared but the skills proliferated. Prompt engineering is following an identical trajectory on a compressed timeline. This isn’t a reason to avoid the skill. It’s a reason to acquire it before it becomes a baseline expectation rather than a differentiator.
The Future: Context Engineering Is What Comes Next
The practitioners who are most valuable in 2026 aren’t optimizing individual prompts, they’re designing the full information pipeline that feeds AI systems at runtime. This is context engineering: the discipline of systematically managing what information gets included in a model’s input window, in what form, and in what order.
The progression looks like this: basic prompting → structured prompt design → RAG architecture → context engineering → LLM evaluation systems. The further right you sit on that spectrum, the more durable your value and the higher your compensation ceiling.
Two dynamics are compressing this timeline. First, models are improving fast, GPT-4 and its successors already self-refine outputs more capably than GPT-3.5. By 2027, routine prompt iteration for common tasks may be largely automated. What remains valuable is strategic prompt architecture: system design, evaluation framework design, and context pipeline engineering. Second, OpenAI’s formalization of its Forward Deployed Engineer program in May 2026 signals that the highest-leverage prompt-adjacent work is becoming institutionalized as a distinct engineering discipline, not a standalone role, but a specialization within software engineering.
Stanford’s 2025 AI Index, analyzing over 51,000 job posting websites, found that 1.8% of all U.S. job postings now require AI skills, up from 1.4% in 2023. That trajectory doesn’t stop. The question is whether you’re building the deeper skills before they become the expectation.
Frequently Asked Questions
What does a prompt engineer do?
A prompt engineer designs, tests, and refines text instructions given to AI language models like ChatGPT, Claude, and Gemini. They craft inputs that guide models toward accurate, useful, and consistent outputs across applications from customer service automation to code generation and content creation. The role combines linguistics, systems thinking, and iterative testing, not creative guessing.
Do you need to know how to code to become a prompt engineer?
Basic prompt engineering doesn’t require coding. However, senior roles increasingly require Python for API integration, evaluation scripting, and RAG pipeline design. Entry-level positions at non-technical companies rarely require code; AI lab and enterprise engineering roles almost always do. The “no coding required” framing from 2023 is effectively obsolete for roles paying above $90K.
How much does a prompt engineer earn?
U.S. salaries range from roughly $63,000 (ZipRecruiter national average, including contract roles) to $123,000 (Glassdoor average for full-time tech positions). Senior roles at major AI companies reach $250,000 and above in total compensation. Anthropic’s widely reported outlier listing reached $335,000, but that was a senior, specialized role at an elite AI lab during a period of acute talent scarcity. It is not a typical benchmark.
Is prompt engineering a good career in 2026?
The skill is highly valuable; the standalone job title has underperformed expectations. Prompt engineering is most powerful as a capability layer added to existing domain expertise, a software developer, healthcare analyst, or marketing strategist who prompts effectively commands a premium. As a standalone career pivot with no domain background, the path is significantly narrower than 2023 coverage suggested.
What are the best certifications for prompt engineering?
The most employer-recognized options are Google’s Prompting Essentials (issues a Credly badge, HR-recognizable), Vanderbilt/Coursera’s Prompt Engineering for ChatGPT (university-backed, roughly 18 hours), and DeepLearning.AI’s course with Andrew Ng and Isa Fulford (highest technical credibility among engineering hiring managers). No industry-standard certification equivalent to AWS or PMP exists yet. A portfolio of real projects matters more than any single certificate.
What is the future of prompt engineering?
The standalone job title will continue shrinking. The underlying skill, systematically designing and evaluating AI inputs, is becoming embedded across software engineering, data science, product management, and operations roles. The highest-growth adjacent area is context engineering and LLM evaluation frameworks, where practitioners design the full information pipeline feeding AI systems at runtime. That’s where the durable, high-value work is concentrating.
What You Now Know That Most People Don’t
The prompt engineering story isn’t boom or bust. It’s transformation. The job title peaked in April 2023 and didn’t recover. The skill is being absorbed into every technical role that touches AI, which is rapidly becoming every technical role, full stop. The workers capturing value are the ones who stopped waiting for a “Prompt Engineer” posting and started building the capability into whatever they already do.
Three things to watch and act on in the next 6–18 months:
The Forward Deployed Engineer track is formalizing fast, OpenAI’s May 2026 program announcement is the clearest signal of where prompt-adjacent work is going at scale
Context engineering is the next layer, start learning RAG architecture and LLM evaluation frameworks before they become baseline expectations
Model updates will devalue model-specific prompt knowledge, build technique fluency, not platform-specific tricks
Best Programming Languages to Learn in 2026: What the Data Actually Says
TypeScript just dethroned Python on GitHub for the first time in over a decade. AI tools cut junior developer job postings by 25%. The honest, data-backed ranking every developer needs before choosing their next language.
NeuralWired Research DeskMay 23, 202614 min read2026 DataCareer Guide
In August 2025, TypeScript did something no language had managed in over a decade: it knocked Python off the top spot on GitHub. The margin was slim, roughly 42,000 contributors, barely 1.6% of a 180-million-user platform, but the symbolism landed across every developer forum worth reading. The era of “just learn Python” as universal career advice had quietly ended.
What makes 2026 genuinely different is that the question itself is evolving. It used to be, “which language gets me hired?” Now it carries a harder layer, “which languages will still require a human to write them in 18 months?” That’s not alarmism. SWE-bench verification rates jumped from 33% to over 70% in just two years. Google’s Sundar Pichai confirmed AI now writes more than a quarter of code at the company. These are not talking points. They’re operational realities.
+66.6%TypeScript contributor growth on GitHub YoY — Aug 2025
+7ppPython’s Stack Overflow adoption jump, largest single-year gain in a decade
−25%Drop in entry-level developer job postings in 2024
+15%BLS projected growth in software developer roles through 2034
The Shift Nobody Saw Coming
The programming language landscape had a stable power structure for years. JavaScript dominated developer surveys for a decade. Python rose steadily through the AI boom. Then 2025 delivered a genuine plot twist in each direction, back to back.
The 2024 GitHub Octoverse was the first signal: Python dethroned JavaScript for the first time in over a decade, fueled by a 59% surge in contributions to generative AI projects and a 98% increase in total generative AI project count. Then, barely twelve months later, TypeScript dethroned Python. In a platform of 180 million users, TypeScript added over 1 million monthly active contributors year-over-year, a 66.6% jump, reaching 2,636,006 contributors just ahead of Python’s 2,594,000.
Why TypeScript? The short answer is AI-assisted development. A 2025 academic study found that 94% of LLM-generated compilation errors are type-check failures. When teams are shipping AI-generated code into production, and 80% of new GitHub developers are using GitHub Copilot in their first week, TypeScript’s static typing catches a category of bugs that JavaScript cannot. Typed code and AI code generation are natural allies.
“We might be six to twelve months away from when the model is doing most, maybe all of what software engineers do end-to-end. I have engineers within Anthropic who say I don’t write any code anymore. I just let the model write the code. I edit it.”
— Dario Amodei, CEO & Co-Founder, Anthropic — Davos, January 2026
Our read: Amodei isn’t predicting the death of programming. He’s predicting the death of a particular kind of programming, the mechanical, specification-driven implementation work that entry-level roles have always been built on. The languages that matter in this environment are those where human judgment adds irreplaceable value: architecture, performance, security, domain logic. That reframe points toward exactly the same top languages, for different reasons than before.
2026 Language Rankings at a Glance
This table synthesizes GitHub Octoverse 2025, Stack Overflow Developer Survey 2025, TIOBE Index (May 2026), U.S. Bureau of Labor Statistics projections, and current job market salary data. No single source tells the full picture; this combines all of them.
#
Language
Primary Signal
US Senior Salary
Best For
AI Threat Level
1
Python
TIOBE #1 (21.81%); SO +7pp YoY
$98k–$188k
AI/ML, data science, automation
Medium–Low (core AI infra)
2
TypeScript
GitHub #1 by contributors (Aug 2025)
$95k–$180k
Full-stack, AI-product builds
Low (type safety + AI)
3
JavaScript
Stack Overflow #1, 66% usage, 13 yrs
$85k–$160k
Web, frontend, rapid prototyping
Medium (frontend commoditizing)
4
Rust
Most admired 10 years straight (72%); +35% job posts YoY
$130k–$235k
Systems, infrastructure, security
Very Low (perf-critical)
5
Go
TIOBE #8; cloud-native & DevOps
$115k–$195k
Cloud backends, DevOps, AI infra
Low (concurrency nuanced)
6
Java
TIOBE #3; enterprise bedrock
$95k–$175k
Enterprise, Android
Medium
7
C#
TIOBE Language of the Year 2025
$90k–$165k
.NET, Unity, enterprise
Medium
8
SQL
Non-negotiable second skill; PostgreSQL most admired DB, 3 yrs
$85k–$155k
Data engineering, analytics, backend
Low (query logic = human judgment)
The Top 8 Languages: Deep Dives
01
PythonThe Undisputed AI-Era King — With Caveats
Python’s position in 2026 is paradoxical: it’s simultaneously the most important language to learn and the most over-hyped entry-level career path. The TIOBE Index gives Python a 21.81% market share, a dominant lead no other language comes close to. Stack Overflow’s 2025 survey recorded its largest single-year adoption jump in over a decade: +7 percentage points. AI/ML job postings on Indeed are up 134% since 2020, and Python powers the overwhelming majority of that work.
The caveat: TIOBE CEO Paul Jansen noted in early 2026 that Python’s share has declined from a peak of 26.98% in July 2025 as domain-specific languages gain ground. Python’s explosive growth may be plateauing, when every data scientist already uses it, further growth hits a ceiling.
What the job market actually wants in 2026: not basic Python. Hiring managers want FastAPI, LangChain, experience building on LLM APIs, and Python used as infrastructure glue for AI pipelines — not just scripted data manipulation. The “learn Python in 30 days” bootcamp path leads to the most competitive segment of an increasingly AI-saturated entry-level market.
“Our goal is for Python to be a great tool that helps the ever-growing developer community build the world they envision. We couldn’t be more pleased to learn about Python’s continued rise in popularity on GitHub, especially coupled with the increased use of Jupyter Notebooks, data analysis, AI, and open source technology.”
— Deb Nicholson, Executive Director, Python Software Foundation — GitHub Octoverse 2024
TypeScriptGitHub’s New #1 — and the AI-Native Default
TypeScript’s ascent to the top of GitHub isn’t just a popularity story, it reflects a structural change in how professional teams ship code in an AI-assisted era. When AI tools generate your code, type errors become the primary failure mode. TypeScript catches them at compile time. JavaScript doesn’t. For engineering teams shipping AI-generated code into production, which describes most of them, this is risk management, not preference.
A critical context note worth having: the 42,000-developer margin between TypeScript and Python on GitHub is just 1.6% of the platform. TypeScript also compiles to JavaScript, they share the same runtime ecosystem. The JavaScript + TypeScript combined total vastly outscales Python in total GitHub activity. The “TypeScript at #1” headline is accurate, but that framing completes it.
There is a legitimate dissenting view from senior developers, particularly at smaller companies: TypeScript’s type system is over-engineered for teams under ten people, and the velocity cost of strict typing outweighs its benefits outside enterprise-scale codebases. Smaller startups often retain plain JavaScript for speed. That’s not wrong, it’s a real tradeoff, not a failure to understand TypeScript.
GitHub #1 · Aug 2025+66.6% YoYAI-nativeReact/Next.jsNode.js
03
JavaScriptStill the Most-Used Language on Earth
JavaScript has been used by 66% of all professional developers for thirteen consecutive years in Stack Overflow surveys. You can’t build a frontend without it, TypeScript compiles to it. You can’t run Node.js backends without it. The shift to TypeScript doesn’t reduce JavaScript’s relevance; it refines it. The JavaScript/TypeScript ecosystem combined still vastly outscales every other language by total GitHub activity.
The frontend commoditization threat is real: AI tools can scaffold basic React interfaces faster than most junior developers. But the JavaScript developer who understands the runtime, the event loop, and the performance model remains difficult to replace. The language isn’t the moat, the depth of understanding is.
SO #1 by usage · 66%13 consecutive yearsReactNode.jsVue
04
RustThe Highest-Paying Language — and the Most Honest Career Bet
Rust has been the most admired programming language in the Stack Overflow Developer Survey for ten consecutive years, 72% admiration rate in 2025. Job postings grew 35% year-over-year. US senior salaries run $130,000 to $235,000+, with top employers including Cloudflare, 1Password, and Figma. The salary premium exists precisely because the talent pool is small, only an estimated 709,000 developers use Rust as their primary language globally.
The admiration-to-adoption gap is real and requires honest framing: TIOBE still doesn’t rank Rust in its top 15 by search volume. The ownership model and borrow checker genuinely filter out casual learners, not as a flaw, but as the mechanism that produces the quality guarantees that make Rust worth paying for. For mid-career developers targeting systems programming, infrastructure, or AI inference infrastructure (where Rust is already displacing Python at companies like Cloudflare), this is the strongest long-term career bet in the entire landscape, if you can commit to the learning curve.
Most admired · 10 years straight$130k–$235k++35% job posts YoYSystemsSecurity
05
Go (Golang)The Pragmatist’s Systems Language
Go sits at #8 on TIOBE with strong and growing adoption in cloud-native backends and DevOps tooling. It’s the gentler on-ramp to systems programming compared to Rust, no borrow checker, a straightforward concurrency model, and a famously simple toolchain. Go developers working on AI inference roles command salaries roughly 37% higher than TypeScript counterparts in equivalent roles, per 2026 benchmark data. Best choice for developers targeting scalable backends, Kubernetes tooling, or infrastructure work, high ROI without a year-long learning cliff.
TIOBE #8Cloud-nativeKubernetesDevOpsConcurrency
06
JavaEnterprise Bedrock That Refuses to Die
Java’s trajectory is the cautionary tale about dominance not being permanence, and then the plot twist where it refuses to confirm the lesson. TIOBE had Java at 26.49% share in 2001; today it sits near 8%. That sounds like collapse. But Java remains TIOBE’s #3 language overall, powers the majority of enterprise backends globally, runs Android development, and is embedded in financial services and healthcare systems that aren’t being rewritten anytime soon. Java in 2026 is a stability bet, not a growth bet.
TIOBE #3EnterpriseAndroidSpringFintech
07
C#TIOBE’s Language of the Year — With a Defined Niche
TIOBE named C# its “Programming Language of the Year 2025” for achieving the largest year-over-year gain among tracked languages. This measures growth rate, not absolute dominance, Python still holds the top spot overall. But C#’s resurgence reflects Microsoft’s ongoing .NET investment and Unity’s continued reign as the dominant game development engine. If game development or Microsoft-stack enterprise is your specific target, C# is non-negotiable.
TIOBE Language of the Year 2025.NETUnityEnterprise
08
SQLThe Non-Negotiable Second Skill
SQL isn’t a language to learn in the way Python or TypeScript is. It’s table stakes. PostgreSQL has been the most admired and most desired database in Stack Overflow’s Developer Survey for three consecutive years. Every data role, every backend role, and every analytics role requires SQL competency. The fastest path to employability in 2026 — starting from zero, is Python + SQL, not Python alone. Don’t treat SQL as optional. It isn’t.
Non-negotiablePostgreSQL most admired DB, 3 yrs straightData engineeringAnalytics
The AI Disruption: What It Actually Means for Your Career
Here’s the uncomfortable arithmetic most career guides skip: the U.S. Bureau of Labor Statistics projects 15% growth in software developer jobs through 2034, roughly 129,200 new openings per year. Simultaneously, it projects a 6% decline in traditional “computer programmer” roles. Both numbers are accurate. They don’t contradict each other. The industry is growing at the top while contracting at the bottom.
Entry-level developer job postings dropped approximately 25% in 2024. Employment of developers aged 22–25 fell nearly 20% that same year. An IEEE Spectrum report from December 2025 found employers’ outlook for graduate hiring was at its most pessimistic since 2020, explicitly attributing the shift to AI handling tasks previously assigned to junior developers.
⚠ Critical Context
The “learn Python and get hired in six months” advice was accurate in 2021. It’s still true for the right Python skills, but the wrong version (basic scripting, vanilla CRUD apps) is the fastest way to build a portfolio that AI can already replace. The bar for “hireable” has shifted upward, not disappeared.
SWE-bench verification rates — measuring how well AI resolves real GitHub issues, jumped from 33% in early 2024 to over 70% by early 2026. That’s not linear progress. It’s an inflection point. GitHub Copilot reached 4.7 million paid subscribers by January 2026, up 75% year-over-year. Over 1.1 million public repositories now import an LLM SDK, up 178% year-over-year.
The pattern that emerges is consistent: AI is replacing tasks, not entire professions. It replaces the most routine, specification-driven implementation work fastest. What it can’t reliably replace, yet, is architectural judgment, security reasoning, performance-critical optimization, and deep domain expertise. The languages commanding the highest salaries in 2026 (Rust, Go senior roles, Python AI engineering) all map to exactly these categories.
AI is replacing the most specification-driven coding fastest. What remains is judgment, and the languages that reward judgment pay the most.
How to Choose: A Decision Matrix
The right language depends entirely on where you’re starting and where you’re going. Here’s the breakdown without the generic advice.
Starting from zero
Python, then SQL. Python’s syntax is the lowest-friction path to being productive. It’s the #1 language for AI and data roles, which are the fastest-growing job category. SQL pairs immediately for data work. JavaScript is the right alternative if you specifically want to build visible web applications from day one, seeing results in a browser sustains motivation. Avoid starting with Rust or C++, the time-to-productivity ratio is too low for beginners.
Mid-career switch or bootcamp student
Python + TypeScript is the highest-ROI six-to-twelve month combination in 2026. Python for AI-integrated backend work; TypeScript for full-stack product development. The portfolio you need isn’t a to-do app. It’s a project integrating an LLM API, handling real data, and demonstrating architectural thinking, even at modest scale. GitHub presence matters more than certifications in 2026’s hiring environment.
Mid-career developer (5–10 years in)
The language question is secondary to the domain question. Domain expertise in healthcare, fintech, infrastructure, or security is the moat AI doesn’t erode. That said: adding Rust or Go to a Python/TypeScript base positions you for systems and infrastructure roles commanding $140k–$200k+. The admiration-to-adoption gap in Rust (72% admired, small talent pool) signals a hiring premium that early adopters will capture.
Engineering manager or CTO
TypeScript should be your default assumption for new projects, 80% of new developers on GitHub use Copilot in their first week, and TypeScript produces fewer AI-generated compile errors. Audit your stack against the GitHub Octoverse 2025 finding: 80% of new library activity is concentrated in six languages (Python, JavaScript, TypeScript, Java, C++, C#). If your stack sits outside this cluster, your dependency maintenance burden is growing.
💡 Our Read
The safest combination for a career spanning the next decade: Python for AI/data work, TypeScript for product builds, SQL as the non-negotiable second skill, and a serious Rust study effort before 2027. That covers the three dominant trends without betting everything on a single paradigm.
FAQ: Best Programming Languages to Learn in 2026
The top questions Google surfaces on this topic, answered directly and completely.
Which programming language is most in demand in 2026?
Python leads job market demand in 2026, especially for AI, data science, and machine learning. The Stack Overflow 2025 Developer Survey recorded Python’s largest single-year adoption jump, +7 percentage points, of any major language. AI/ML job postings on Indeed are up 134% since 2020. For full-stack product roles, TypeScript is increasingly the default hiring assumption.
Is Python still worth learning in 2026?
Yes. Python holds TIOBE’s #1 spot at 21.81% market share and dominates the fastest-growing job category in software. Senior Python developers earn $98k–$188k annually. The caveat: entry-level Python scripting faces direct AI competition. Pairing Python with SQL and LLM framework experience (LangChain, FastAPI) is what the 2026 job market rewards.
Is JavaScript still relevant in 2026?
Absolutely. JavaScript is used by 66% of all professional developers, the most-used language for thirteen consecutive years per Stack Overflow. TypeScript, which overtook Python as GitHub’s #1 language by contributors in August 2025, compiles to JavaScript. The two are the same ecosystem. Combined, they outscale all other languages in total GitHub activity.
Should I learn Rust in 2026?
Rust is the most admired language (72%, Stack Overflow 2025) and offers the highest salary premium, $130k to $235k+ in the US, with job postings up 35% year-over-year. Best suited for developers targeting systems programming, infrastructure, or security. Not recommended as a first language: the learning curve is steep and the talent pool is deliberately small, which is exactly what drives the premium.
What programming language should a beginner learn in 2026?
Python is the consensus top recommendation: simple syntax, vast library ecosystem, #1 for AI and data roles, strong job market. Pair it with SQL immediately for maximum employability. JavaScript is the best alternative if you want to build visible web results from day one. Avoid starting with Rust or C++, the time-to-productivity ratio is too low for complete beginners.