Strategic analysis of big tech companies: Microsoft, Google, Apple, Meta, Amazon, NVIDIA, OpenAI, and more. Enterprise moves, AI investments, and competitive intelligence decoded.
Data Mesh vs. Data Lakehouse: The 2026 Decision Framework
Enterprise Data Architecture
Data Mesh vs. Data Lakehouse: What Actually Wins in 2026
JPMorgan Chase built a data mesh. So did dozens of other Fortune 500 names chasing the same promise: kill the central data team bottleneck, let business domains own their own data. Two years later, the honest answer about whether that bet paid off is “it depends,” and the data behind that answer is more specific than most vendors want to admit.
If you’re a CTO or Chief Data Officer staring down a 2026 or 2027 platform overhaul, the question isn’t really “data mesh vs. data lakehouse” anymore. McKinsey’s October 2025 survey found pure data mesh implementations succeed only 38% of the time within 24 months, the worst of three architectural approaches tracked. Pure lakehouse and fabric setups didn’t fare dramatically better. Hybrid models did, hitting a 52% success rate. This article breaks down why, with the numbers, the failures nobody puts in the keynote slides, and a framework for deciding what your organization actually needs.
These two terms get used interchangeably in vendor decks, which is exactly the problem. They’re not competing answers to the same question. They’re answers to two different questions entirely.
Data mesh was introduced in 2019 by Zhamak Dehghani, then director of emerging technologies at ThoughtWorks, as a direct response to a specific organizational failure: a single central data team becoming a bottleneck for an entire enterprise’s data pipelines. It’s built on four principles: domain-oriented ownership, treating data as a product, self-serve infrastructure, and federated computational governance. Notice none of those four principles describe a storage technology. Data mesh is an organizational model wearing architecture clothing.
The data lakehouse, popularized by Databricks, is the opposite kind of thing entirely; a storage and processing platform. IBM defines it as an architecture combining the flexibility and low cost of data lakes with the ACID transactions and schema management of data warehouses, using open table formats like Delta Lake, Apache Iceberg, and Apache Hudi to make that combination work.
The core distinction: a lakehouse answers “where does our data live and how do we query it reliably?” Data mesh answers “who owns this data and who’s accountable when it’s wrong?” You can run a lakehouse with zero domain ownership. You can also run a domain-ownership model on top of a traditional warehouse. They were never mutually exclusive, no matter how the conference circuit framed it.
The Numbers Nobody Puts on the Conference Slide
Here’s where the hype runs into the spreadsheet. The headline figure that should reframe how you think about this decision: only an estimated 18% of organizations have the governance maturity needed to successfully adopt data mesh, according to research cited by Atlan’s analysis of Gartner’s hype cycle placement. That’s not a technology gap. That’s a readiness gap, and it’s the single biggest predictor of whether a mesh initiative survives its second year.
The pattern holds across other research too. Organizations that planned a hybrid architecture from day one, rather than pivoting into one after 12 to 18 months of a failed pure-mesh attempt, achieved 25% faster time to value, 35% lower total cost of ownership, 40% better adoption rates, and 50% fewer governance conflicts, according to Gartner research from the 2025 Enterprise Data & Analytics Summit. Decide hybrid upfront. Don’t pivot into it after the first project stalls.
And the market is still chasing this category hard despite the failure rate: the data mesh market alone is projected to grow at roughly 18% CAGR through 2026, according to The Business Research Company’s 2026 market report. Money is flowing in even as the implementation track record stays rocky. That gap between capital and competence is worth sitting with for a second.
Why Data Mesh Implementations Fail (According to Its Own Creator’s Firm)
The most credible critique of data mesh doesn’t come from a rival vendor. It comes from ThoughtWorks itself, the firm where Dehghani coined the concept in 2019. Their January 2026 retrospective is unusually blunt for a company with a commercial stake in the methodology’s success.
“After numerous client projects and more than six years of on the ground observation, one thing is unequivocally clear: Data mesh is an organizational transformation, not merely a technical one. The greatest obstacles are changing organizational and individual behaviors, not technologies and architectures.”
ThoughtWorks Insights, “The State of Data Mesh in 2026: From Hype to Hard-Won Maturity,” January 16, 2026
ThoughtWorks goes further, naming the exact failure pattern they see repeatedly in client engagements: domain ownership that exists in name only.
“We often see the creation of ‘data domains’ that act as lip service to the principle… an IT department re-badges its old teams as ‘domains’ (e.g., the ‘SAP domain,’ the ‘Salesforce domain’) without any genuine business ownership. These constructs are lacking a clear mandate, business-aligned incentives or the authority to make decisions.”
ThoughtWorks Insights, January 2026 retrospective
Read that twice if you’re planning a mesh rollout. Renaming an IT team a “domain” changes nothing if that team still has no business mandate and no decision authority. It’s the data-architecture equivalent of putting a fresh coat of paint on a building with a cracked foundation. ThoughtWorks also acknowledges, candidly, that for every digital-native success story making the rounds at conferences, there’s “a quiet graveyard of stalled projects and failed implementations” that doesn’t get a stage slot.
There’s a survivorship bias problem baked into the entire public narrative around data mesh. Most published case studies come from organizations that were already platform-mature before they started. If your organization isn’t already running a sophisticated, well-staffed data engineering function, the mesh case studies you’re reading at 2am before a board presentation probably don’t describe a company that looks like yours.
The JPMorgan Case and What “Working” Looks Like
JPMorgan Chase launched a data mesh solution in October 2023, built specifically to support large-scale, distributed data ecosystems while keeping the governance, security, and regulatory controls a bank can’t compromise on. It’s one of the few named, large-scale enterprise deployments in financial services with public detail attached, and it didn’t try to go fully decentralized. Domain teams publish and manage data products, but through a unified platform with centralized guardrails baked in.
That’s the pattern playing out broadly across regulated industries. Financial services and healthcare, the two sectors with the heaviest compliance burden, are also the two leaning hardest into “hub and spoke” hybrid models: a central fabric core for governance, with mesh-style domain ownership layered on top for business velocity. Roughly 80% of financial services implementations and 70% of healthcare implementations now follow this pattern, because regulation demands central oversight at the same moment business units demand speed. You can’t have one without the other in those sectors, so the architecture had to evolve to fit both.
Our read: this signals something the conference circuit hasn’t fully caught up with yet. The interesting architecture decisions in 2026 aren’t “mesh or lakehouse.” They’re “how much central governance does our regulatory and risk profile actually require, and where can we safely hand decision authority to a domain team that’s earned it?”
The Decision Framework: Governance First, Architecture Second
If you’re building the RFP right now, here’s the order of operations the data actually supports.
1. Run a governance maturity audit before you pick a platform
With only an estimated 18% of organizations governance-ready for mesh, this is the step most teams skip and most regret skipping. Find out, honestly, whether your domains have the data engineering capability, the documentation discipline, and the business-side ownership to manage their own data products before you build infrastructure assuming they can.
2. Default to hybrid, not to either pure extreme
Between 60% and 70% of large enterprises were running hybrid models by 2025-2026 rather than committing to a pure approach in either direction. That’s not organizations hedging out of indecision. It’s the empirically dominant pattern because pure mesh has the lowest 24-month success rate of any model tracked, and pure lakehouse-only setups don’t solve the ownership and accountability problem that originally motivated mesh in the first place.
3. Decide hybrid upfront, don’t pivot into it after a failed pure attempt
This is where the 25-40% cost-efficiency premium comes from. Organizations that spent roughly 12 months assessing their situation before committing to a hybrid model outperformed teams that rushed into a pure architecture and pivoted later, on cost, adoption, and time-to-value. Rushing costs more than it saves.
4. Treat domain ownership as a real org-design project, not a renaming exercise
If your “domains” don’t have a budget, a mandate, and someone whose job depends on the data product’s quality, you’ve built ThoughtWorks’ anti-pattern, not a data mesh. Give the SMBs in your portfolio an honest exit ramp here too: if your central data team isn’t yet a proven bottleneck across multiple large business units, a well-implemented data warehouse will outperform a mesh on cost and complexity, full stop.
One additional pressure is now external rather than internal: the EU Data Act is pushing organizations toward sharing data with each other as governed products with clear contracts attached. Whether or not you adopt the data mesh label, the federated-governance thinking behind it is becoming a regulatory requirement in Europe regardless of your architecture preference.
Frequently Asked Questions
Is data mesh replacing the data lakehouse in 2026?
No. Data mesh is primarily an organizational and operating model, while a lakehouse is a storage and processing platform. Most enterprises in 2026 run a lakehouse as the core analytics platform with selective data mesh principles applied to high-maturity domains, rather than one replacing the other.
Why do most data mesh implementations fail?
The dominant failure mode is shallow domain ownership. IT departments re-badge existing teams as “domains” without granting genuine business mandate or decision authority, recreating the silos mesh was meant to eliminate, compounded by low governance maturity across most organizations attempting it.
Do most companies actually need data mesh?
No. Data mesh requires mature data engineering capability inside every domain plus significant organizational change. For most small and mid-sized businesses, a well-implemented data warehouse delivers more value with far less complexity. Mesh becomes worth the cost mainly once a centralized data team is a proven bottleneck.
What percentage of enterprises use a hybrid data architecture?
An estimated 60% to 70% of large enterprises were running hybrid models, combining lakehouse, fabric, and mesh elements, rather than a single pure architecture, by 2025-2026.
Where This Goes Next
The “mesh vs. lakehouse” framing that dominated 2022-2024 conference talks is already outdated. What replaced it: a hybrid-by-default consensus backed by real success-rate data, plus a hard recognition that governance maturity, not platform choice, is the variable actually deciding outcomes. Forrester’s 2025 analysis found 42% of enterprise architects now see mesh and fabric as a convergent, complementary evolution rather than a binary choice. That number will likely climb past 50% before 2027.
Three things worth watching over the next 6 to 18 months: whether the EU Data Act forces federated-governance adoption even at organizations that never wanted to touch data mesh; whether the governance-maturity gap (still 18% as of the most recent estimate) closes as vendors build more self-serve tooling; and whether more named enterprise case studies beyond JPMorgan publish honest failure data instead of polished success narratives.
If you’re choosing between data mesh and a data lakehouse architecture in 2026, you’re asking the wrong binary question. The right one is whether your organization has the governance maturity to support domain ownership at all, and if not, what a deliberately sequenced hybrid rollout looks like for your specific regulatory and organizational reality.
Kubernetes Enterprise Production 2026: 14 Problems Nobody Warned You AboutEnterprise Infrastructure · Deep Analysis
Kubernetes Won Enterprise Production. Now It’s Creating 14 New Problems.
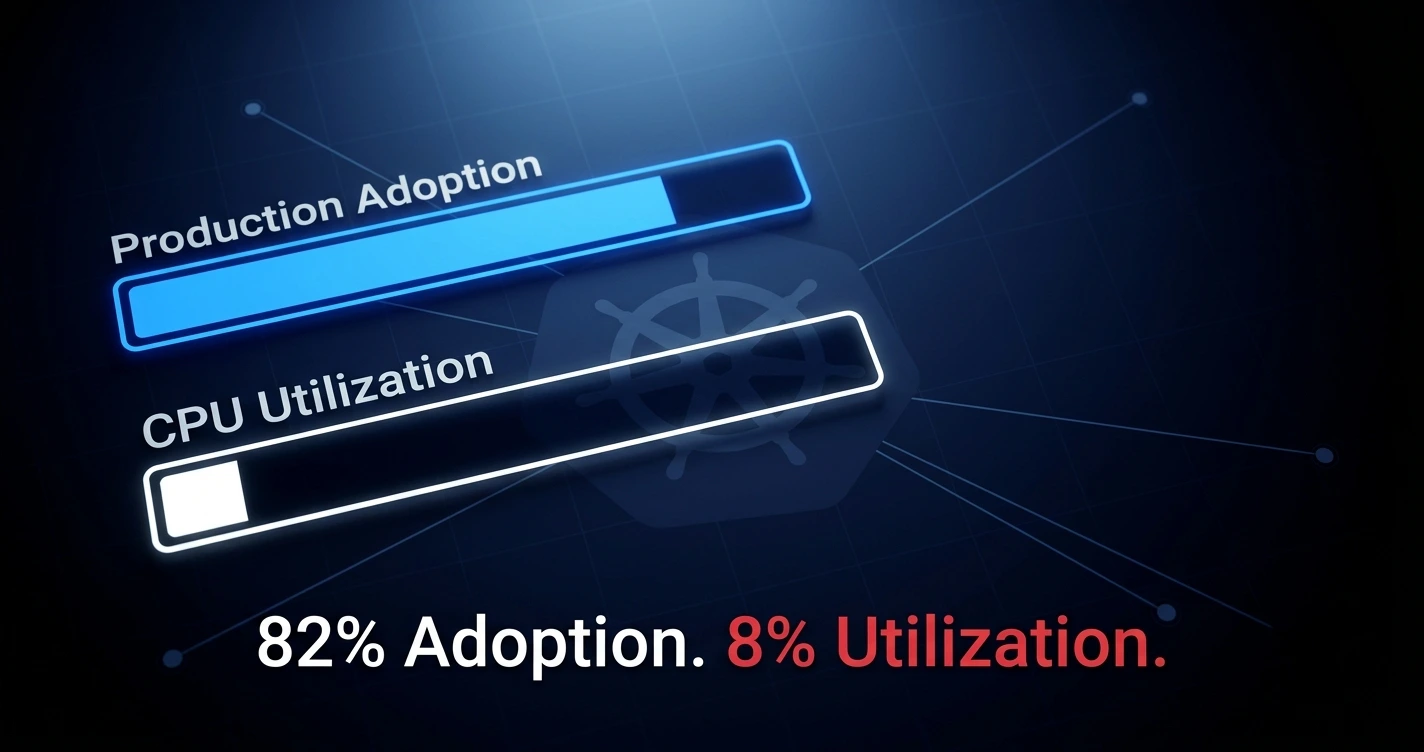
82% of container-running organizations now run Kubernetes in production. 88% of them report rising costs every year. Average CPU utilization sits at 8%. This is the honest state of Kubernetes enterprise production in 2026.
By NeuralWired StaffJune 29, 202615 min read
The Production Paradox
A cryptocurrency exchange gets breached in mid-2025. The attacker doesn’t use a zero-day. No exotic exploit chain. They deploy a malicious pod, steal a service account token, and pivot straight into cloud backend systems. The entire attack hinges on a Kubernetes misconfiguration that’s been documented as a critical risk since 2019. The exchange had been running Kubernetes for three years.
This is what Kubernetes enterprise production actually looks like in 2026. Not the CNCF keynote version. The version where the technology won and the operations didn’t.
According to the CNCF Annual Cloud Native Survey published January 20, 2026, 82% of organizations running containers now run Kubernetes in production. That’s up from 66% in 2023. By almost every measure, Kubernetes has won. It is the de facto operating system for modern enterprise infrastructure, the orchestration layer for 66% of all generative AI inference workloads, and the platform on which 77% of Fortune 100 companies run production systems.
And yet.
88% of enterprise Kubernetes teams report year-over-year TCO increases. Average CPU utilization across production clusters sits at 8%. More than half of enterprise clusters are still “snowflakes” with highly manual operations. Cost has overtaken skills and security as the single biggest Kubernetes challenge.
The container orchestration problem is solved. What replaced it is a cluster of operational, financial, and cultural problems that nobody included in the vendor pitch.
82%
of container users run Kubernetes in production (CNCF, Jan 2026)
average CPU utilization across production clusters (CAST AI, 2026)
5%
average GPU utilization despite premium cost (CAST AI, 2026)
All 14 Problems, Named and Quantified
These aren’t hypothetical edge cases. Every problem below is documented in primary research from Spectro Cloud’s 2025 State of Production Kubernetes (455 professionals across organizations with 250+ employees), the CNCF’s January 2026 survey, CAST AI’s 2026 optimization report, Palo Alto Networks Unit 42, and Sysdig. These are real production clusters, real enterprise teams, real money.
Problem 01
YAML Sprawl and Configuration Entropy
Teams managing hundreds of microservices accumulate thousands of YAML files with no enforced standardization between them. A new engineer joining a three-year-old cluster faces a configuration archaeology project before they can make a safe change. There’s no industry consensus on how to fix this at scale, and Helm charts layer additional complexity on top.
Problem 02
The Snowflake Cluster Problem
Over half of enterprise Kubernetes clusters are still what the industry calls “snowflakes”: clusters so customized through manual operations, one-off patches, and undocumented configuration decisions that no two are alike. Kubernetes promised repeatability. Most organizations haven’t delivered it. The institutional knowledge required to keep these clusters alive lives in the heads of two or three engineers.
Problem 03
Runaway Total Cost of Ownership
Cost has become the defining Kubernetes problem for 42% of organizations, overtaking skills shortage and security for the first time (Spectro Cloud / Adience, 2025). The promise was that containerization and efficient bin-packing would reduce infrastructure spend. What happened instead: platform engineering teams, observability tooling, security scanning, GitOps licenses, and training costs all landed on top of the compute bill, not instead of it.
Problem 04
CPU Overprovisioning at Industrial Scale
Average CPU utilization across production Kubernetes clusters is 8%. That number fell from 10% in 2024. CPU overprovisioning jumped from 40% to 69% in the same period. Organizations are not getting better at running Kubernetes efficiently as they gain experience. They are getting worse, largely because AI and GPU workloads entered clusters that weren’t built for them.
Problem 05
GPU Waste Is a Board-Level Problem Waiting to Happen
GPU nodes cost between 10 and 30 times more per compute unit than CPU. Average GPU utilization in Kubernetes clusters sits at 5%. For any organization running AI inference on Kubernetes, that is the kind of number that surfaces in a CFO conversation about AI ROI and triggers a forced architectural rethink. This is not a future problem. The spend is happening now.
Problem 06
Security Misconfiguration as the Primary Attack Vector
More than 60% of Kubernetes security incidents trace back to misconfigurations, not zero-days. RBAC settings, secrets stored in plaintext ConfigMaps, overprivileged service accounts, and absent network policies are the actual attack surface. The breach detailed in the opening of this article used none of the sophistication that “APT attack” implies. It used a service account token that had been granted more access than it needed.
Problem 07
Container-to-Cloud Attack Escalation
Palo Alto Networks Unit 42 published research in April 2026 documenting how threat actors pivot from a compromised container to full cloud backend access. The North Korean APT group Slow Pisces (also tracked as Lazarus) used exactly this playbook in a 2025 breach of a major cryptocurrency exchange. They didn’t need a kernel exploit. They needed a misconfigured service account.
Problem 08
Upgrade Lag and Version Drift
Kubernetes releases a new minor version every four months. Enterprise compliance cycles, business blackout windows, and the operational overhead of testing upgrades on snowflake clusters mean most organizations are persistently behind. Version drift creates documented security exposure and is on a collision course with emerging EU AI Act governance requirements and SOC 2 Type II controls that will treat undocumented patch lag as an audit finding.
Problem 09
Multi-Cluster Complexity Grows Non-Linearly
The average Kubernetes adopter runs clusters in more than five environments. The operational complexity of managing N clusters is not N times the complexity of one cluster. Every cluster multiplies the number of networking decisions, RBAC configurations, observability integrations, and upgrade cycles. At six-plus clusters, managing the cluster fleet becomes a full-time function that most organizations didn’t staff for when they started.
Problem 10
The Skills Shortage and Retention Crisis
36% of organizations cite lack of Kubernetes training as a significant barrier (CNCF 2025). Experienced Kubernetes engineers command premium compensation and are among the most actively recruited profiles in enterprise infrastructure. The institutional knowledge problem this creates is acute: a two-person team managing a six-cluster production environment represents a single resignation away from an operational crisis.
Problem 11
Cultural Resistance Now Outranks Technical Complexity
For the first time in the CNCF survey’s history, “cultural changes within the development team” (47%) overtook technical complexity as the top barrier to cloud native adoption in 2025. If you’re an engineering leader, this means the bottleneck for Kubernetes ROI in your organization is more likely an organizational change management problem than a technical one. Build the right internal platform and nobody uses it without this piece.
Problem 12
Observability Debt and MTTD Regression
Mean time to detect (MTTD) and mean time to resolve (MTTR) frequently increase after a Kubernetes migration, not decrease, especially in the first 18 months. Finance teams face an additional problem: Kubernetes cost allocation doesn’t map to traditional VM-style billing. Attributing cloud spend to business units or product lines in a shared cluster is a solved problem technically and an unsolved problem organizationally at most companies.
Problem 13
Stateful Workload Complexity
Kubernetes was built for stateless, ephemeral workloads. Databases, message queues, and persistent volumes require backup, disaster recovery, and data consistency guarantees that introduce significant operational complexity. Running stateful workloads in Kubernetes correctly requires Operators, CSI drivers, snapshot management, and replication strategies that most teams underestimate before committing.
Problem 14
AI Workload Infrastructure Drift
Most existing Kubernetes environments were not built for deterministic AI and GPU inference workloads. Mismatched kernels, manual patching cycles, and the accumulated customization of snowflake clusters create “snowflake debt” that compounds directly against the AI infrastructure roadmap. The New Stack and SideroLabs flagged this in February 2026 as the hidden cost of organizations that rush AI workloads into clusters that were never designed for them.
“I think some people hope that AI becomes this magic sauce you can rub on your YAML files and user experience pops out. It’s important that if you’re going to manage these systems, you need to know how they work.”
Kelsey Hightower, Former Distinguished Engineer, Google Cloud Platform, at KubeCon Europe 2026. Source: The New Stack, March 30, 2026
The 8% Utilization Scandal
Let’s sit with that number for a moment. Eight percent average CPU utilization. Across tens of thousands of real production Kubernetes clusters. Data collected by CAST AI from actual workloads running on EKS, GKE, and AKS in 2025.
That means 92% of the CPU capacity organizations are paying for is idle. Not reserved for burst capacity. Not in use. Idle.
And it’s getting worse. In 2024, average CPU utilization was 10%. Overprovisioning has jumped from 40% to 69% in two years. The direction is wrong. Organizations are becoming less efficient at running Kubernetes as the platform matures, not more. The proximate cause is AI workloads entering clusters that weren’t architected for GPU scheduling, combined with teams provisioning conservatively because the cost of getting it wrong (an outage) is higher than the cost of waste (a larger cloud bill).
For large deployments running 1,000 or more nodes, Sysdig estimates the wasted spend on CPU alone can exceed $10 million annually. That’s not a rounding error. That’s a CFO conversation.
Immediate action required: Run a utilization audit using CAST AI, Kubecost, or your cloud provider’s native cost tooling before your next budget cycle. With average CPU at 8%, the probability of finding immediate, material savings in your cluster is high. At $1M or more per year in likely waste for mid-size deployments, this is a conversation that belongs in the CFO’s calendar, not just the SRE team’s backlog.
The GPU problem is structurally worse. GPU nodes cost between 10 and 30 times more per compute unit than CPU. Average GPU utilization in Kubernetes clusters sits at 5%. Most organizations deployed GPU capacity to support AI inference workloads and then discovered that Kubernetes, without specialized scheduling and bin-packing tools, defaults to the same overprovisioning behavior that makes CPU utilization so bad. The result is the most expensive infrastructure in the enterprise sitting 95% idle.
The Security Reality Nobody Talks About
There’s a comfortable assumption in enterprise Kubernetes security: “We’re on EKS/GKE/AKS, so the managed service handles security for us.” This assumption is factually wrong, and it’s the precondition for exactly the kind of attack that cost a crypto exchange its cloud backend in 2025.
Managed Kubernetes services handle control plane security. They patch etcd, harden the API server, and manage the underlying node OS. They do nothing to secure your workloads. RBAC configuration, secrets management, network policies, pod security contexts, and service account permissions are entirely your responsibility. And according to Palo Alto Networks Unit 42’s April 2026 research, more than 60% of Kubernetes security incidents trace back to misconfiguration in exactly these areas.
The Slow Pisces/Lazarus breach is instructive not because it was sophisticated, but because it wasn’t. The threat actors deployed a malicious pod, harvested a service account token that had been granted excessive privileges (a Day 1 Kubernetes security anti-pattern), and used that token to authenticate to cloud backend APIs. The cloud provider’s security controls did exactly what they were supposed to do: they checked the token, found it valid, and granted access.
45% of production container images contained high-severity vulnerabilities in 2025. Most of those images were scanned at build time and passed. The vulnerabilities were introduced by base image updates, dependency drift, and the lag between vulnerability disclosure and image rebuild cycles that exists in most enterprise pipelines. Kubernetes didn’t create this problem, but its ephemeral container model makes it harder to maintain a consistent remediation cadence.
If you haven’t completed a Kubernetes security audit in the last 12 months, your RBAC configurations, service account permissions, and network policies are operating on assumptions that may no longer be valid. This is a real, unquantified breach exposure. The CVE-2025-55182 (React2Shell) vulnerability was being actively exploited in Kubernetes environments within 48 hours of disclosure in December 2025. Organizations that discovered it via their own monitoring had a very different outcome than those that read about it in a vendor email.
“Enterprises are aligning around Kubernetes because it has proven to be the most effective and reliable platform for deploying modern, production-grade systems at scale. This year’s data shows that the next phase of cloud native evolution will be as much about people and platforms as it is about the tech itself.”
Hilary Carter, SVP of Research, Linux Foundation Research. Source: PR Newswire, January 20, 2026
The PaaS-First Counter-Argument Has Economic Teeth
Not everyone is persuaded that Kubernetes is the right answer for most organizations in 2026. A growing practitioner movement is making a specific, economic argument that deserves serious engagement: the default to Kubernetes for new projects is a strategic error for teams that aren’t at Top-100-website scale.
The break-even analysis works like this. Managing a production Kubernetes environment safely requires (at minimum) a dedicated platform engineering function. Three senior SREs at approximately $250,000 loaded cost each equals $750,000 per year in labor. If you’re hosting $60,000 per year in compute on that cluster, you’re paying a 12x cost premium on your infrastructure bill to avoid using a managed platform service. At $20,000 per month in compute, the economics still don’t work. The self-management savings don’t offset the team cost until you’re north of $2.5 million in annual compute spend.
This argument is made explicitly by engineering practitioners at sanj.dev and byteiota.com (both published in 2026) who frame the current moment as an inflection point where the risk has flipped. Platforms like AWS App Runner, Railway, Render, and Fly.io, plus specialized AI inference platforms like Modal and BentoCloud, are capturing workloads that don’t require the full Kubernetes operational overhead. These aren’t toy platforms anymore.
This is not a fringe view. It’s tacitly acknowledged in Kelsey Hightower’s own warnings about scale, reinforced by the FinOps Foundation’s waste data, and supported by the CNCF’s own finding that 47% of organizations cite cultural resistance as the top barrier. If the main thing preventing Kubernetes from delivering ROI is organizational change management, not technical complexity, the PaaS argument becomes: why impose this organizational tax?
Our read: the PaaS-first argument is correct for a specific segment of organizations and will accelerate in the next 18 months as GPU cost pressure makes the utilization numbers impossible to ignore. It does not invalidate Kubernetes for large-scale enterprise environments. It does invalidate the default assumption that Kubernetes is the right starting point for any organization running containers.
What the Winning Teams Actually Do
There’s a meaningful performance gap in the CNCF data between organizations it classifies as “innovators” and “adopters.” The gap isn’t about which Kubernetes version they run or which managed service they use. It’s about two practices that separate operationally mature teams from everyone else.
GitOps as Non-Negotiable Infrastructure
58% of cloud native innovators use GitOps extensively. 23% of adopters do. GitOps isn’t just a deployment pattern. It’s the audit trail, the rollback mechanism, and the institutional knowledge system that makes it possible for any engineer on the team to understand the desired state of the cluster at any given time. Without it, as Hightower noted at KubeCon 2026, you’re automating alerts with no audit trail and no rollback. The self-healing infrastructure that AIOps platforms promise for 2026 depends on GitOps as its foundation. You cannot self-heal a cluster whose desired state lives in someone’s head.
Platform Engineering as a Function, Not a Project
The organizations whose DevOps metrics beat every benchmark are those that centralized application deployment in a dedicated platform engineering function with an internal developer platform (IDP). The Backstage project, now the fifth-most-active CNCF project by velocity, is the open-source IDP foundation that leading teams build on. The IDP abstracts Kubernetes complexity away from application developers. It gives them a self-service interface for deployments, environment management, and observability without requiring them to understand pod scheduling or CNI networking.
If you don’t have this function, you’re in the majority. Over half of enterprise clusters are still snowflakes. Being in the majority is not the same as being on the right side of the performance gap.
The Upgrade Cadence Discipline
Winning teams treat Kubernetes upgrades as a routine, automated operational function rather than a high-stakes manual project. This requires investment in cluster automation, canary upgrade testing, and GitOps-driven rollback capability. The organizations that do this aren’t upgrading because they love changelog reading. They’re upgrading because they recognize that every minor version behind the current release represents documented, quantifiable security exposure that will eventually show up on a compliance audit or an incident report.
“Five years in, Kubernetes is no longer an experiment. It’s mission-critical infrastructure. The companies that master scale and complexity fastest will create an unbeatable platform for innovation.”
Tenry Fu, Co-founder and CEO, Spectro Cloud. Source: BusinessWire, August 4, 2025
Metric
Kubernetes “Innovators”
Kubernetes “Adopters”
GitOps usage (extensive)
58%
23%
Internal Developer Platform
Majority deployed
Minority deployed
Snowflake clusters
Minority
Majority (>50%)
Security audit frequency
Continuous / quarterly
Ad hoc / annual
Upgrade cadence
Automated / regular
Manual / deferred
FAQ: Kubernetes Enterprise Production 2026
What are the biggest challenges of running Kubernetes in production in 2026?
The biggest challenges are rising TCO (88% of enterprises report year-over-year cost increases), security misconfigurations (responsible for over 60% of incidents), snowflake cluster proliferation, skills shortages, and GPU and CPU resource waste. Average CPU utilization sits at just 8% across production clusters. Source: Spectro Cloud 2025 State of Production Kubernetes, CNCF January 2026 survey.
Is Kubernetes worth it for enterprise in 2026?
Kubernetes delivers ROI for enterprises spending at least $2.5 million annually on raw compute, with dedicated platform engineering teams and GitOps workflows in place. For organizations below that compute threshold, the operational overhead of three senior SREs at $750,000 loaded cost per year frequently exceeds savings. 77% of Fortune 100 companies run it in production, but the economics differ materially at mid-market scale.
How much does Kubernetes waste in cloud resources?
Significantly. The average Kubernetes cluster operates at only 8% CPU utilization and 20% memory utilization. CPU overprovisioning stands at 69% in 2026. GPU utilization averages 5% despite a 10 to 30 times cost premium per compute unit. For large deployments with 1,000 or more nodes, wasted CPU spend alone can exceed $10 million annually. Source: CAST AI 2026 State of Kubernetes Optimization Report.
What percentage of companies use Kubernetes in production in 2026?
82% of organizations running containers use Kubernetes in production, per the CNCF Annual Cloud Native Survey published January 20, 2026. This is up from 66% in 2023. An additional 13% are in active pilot or evaluation phases. 79% of those production users run managed services (EKS, GKE, AKS) rather than self-managed clusters.
What are the most common Kubernetes security risks in production?
RBAC misconfigurations, overprivileged service accounts, secrets stored in plaintext ConfigMaps, exposed API servers, and missing network policies are the primary risks. Over 60% of Kubernetes security incidents trace to misconfigurations rather than zero-day vulnerabilities. In 2025, a North Korean APT group used an overprivileged service account token to breach a major cryptocurrency exchange. Source: Palo Alto Networks Unit 42, April 2026.
What is the Kubernetes TCO problem?
Kubernetes total cost of ownership extends well beyond compute to include platform engineering labor, observability tooling, security scanning, FinOps tooling licenses, upgrade cycles, and ongoing training. 88% of enterprise teams report year-over-year TCO increases, and cost has overtaken skills and security as the primary Kubernetes challenge for 42% of organizations. Source: Spectro Cloud State of Production Kubernetes 2025.
What is replacing Kubernetes in 2026?
Nothing replaces Kubernetes at large enterprise scale, but a PaaS-first movement is gaining traction for teams spending under approximately $2.5 million annually on compute. AWS App Runner, Railway, Render, Fly.io, Modal, and BentoCloud are capturing workloads that don’t require full Kubernetes operational overhead. Kubernetes remains the standard for large-scale, multi-service enterprise environments running complex or AI-heavy workloads.
Why do so many Kubernetes clusters have low utilization?
The core reason is conservative overprovisioning. Engineers provision excess CPU and memory because the cost of under-provisioning (an outage or performance degradation) is immediately visible, while the cost of overprovisioning (waste) lands on a cloud bill that finance teams often can’t attribute at the service level. AI and GPU workloads entering clusters not designed for them have accelerated this trend significantly since 2024.
Where This Goes in the Next 12 Months
Kubernetes enterprise production in 2026 sits at a specific kind of inflection point. The technology is mature. The adoption curve is approaching saturation. What hasn’t matured is the operational discipline required to extract value from it at scale.
Three forces will define the next 12 months.
GPU waste will trigger executive intervention. With AI infrastructure ROI now a board-level conversation and average GPU utilization at 5%, CFOs who find out how much compute their AI workloads are burning will force architectural decisions that many engineering teams are not yet prepared for. Organizations that have already implemented Kubernetes GPU scheduling optimization (using tools like the NVIDIA GPU Operator with proper bin-packing policies) will have a defensible answer. Those that haven’t will be having a different kind of conversation.
A high-profile Kubernetes breach will change the security conversation. The 2025 Lazarus attack hit a crypto exchange. The next high-profile RBAC misconfiguration breach will likely involve a publicly traded company. When it does, audit committees and boards will ask questions that most CISO teams aren’t currently prepared to answer about Kubernetes security posture. Organizations that have completed a comprehensive RBAC and container security audit will be in a substantially different position than those operating on inherited configurations.
Platform engineering will separate enterprise performance tiers. The data already shows this. Organizations with internal developer platforms and extensive GitOps adoption are definitively in a different performance category from those still managing snowflake clusters manually. This gap will widen as AI workloads require more deterministic, well-configured infrastructure to deliver consistent inference performance.
Three things to act on now. First, run a CPU and GPU utilization audit. With average utilization at 8% and 5% respectively, the probability of immediate, material savings is high. Second, conduct a Kubernetes RBAC review. If you can’t tell in 30 minutes which service accounts have cluster-admin privileges and why, you have an unquantified breach exposure. Third, evaluate whether your organization actually meets the compute threshold ($2.5M annually) where self-managed Kubernetes makes financial sense. If it doesn’t, the PaaS-first argument deserves serious consideration before your next infrastructure commitment.
Kubernetes won. What it created in winning is a set of operational, financial, and security problems that are now more consequential than the container orchestration problem it solved. The organizations that close that gap in the next 12 months will have a structural platform advantage that compounds. The ones that don’t will spend the next 18 months explaining cost overruns and missed AI deployment timelines to people who stopped caring about the technical reasons.
Stay ahead of enterprise infrastructure shifts
The Neural Loop is NeuralWired’s weekly briefing on the technology decisions that matter most to engineering leaders. No noise. No vendor PR. Just the analysis your team needs.
Subscribe to The Neural Loop
Platform Engineering in 2026: DevOps Admits It Didn’t End the War
Enterprise · Platform Engineering · 2026
Platform Engineering Is Quietly Admitting DevOps Never Finished the Job
Three headline options (best marked with a star):
Platform Engineering in 2026: DevOps Wasn’t Enough ★
Why Platform Engineering Is Replacing DevOps at Scale
DevOps Promised Peace. Platform Engineering Is the Truce.
For ten years, DevOps told us the wall between developers and operations was coming down. At thirty engineers, it actually came down. At three hundred, it got rebuilt with better tooling and a worse name for the problem. That’s the uncomfortable thing platform engineering is now admitting out loud, and it’s why every CTO budgeting for 2027 needs to understand what changed.
This is the story of platform engineering enterprise 2026 growth, not as a rebrand of DevOps but as a structural correction to it. The data behind that correction is now public, and some of it should worry you more than the adoption headlines suggest.
DevOps started with a single conference talk. In 2009, John Allspaw and Paul Hammond stood up at the Velocity conference and described how Flickr shipped ten or more deploys a day by getting developers and operations to actually work together. The idea that took hold was simple: you build it, you run it. One team, one set of incentives, no wall.
That philosophy worked. It built the DORA metrics that still define delivery performance today: deployment frequency, lead time, change failure rate, mean time to restore. It built a decade of tooling. It built the case studies everyone still cites.
Then it hit scale. Research from Spotify’s developer productivity team found that engineers at DevOps-mature organizations were losing 30 to 40 percent of their time to infrastructure work that had nothing to do with the product they were supposed to be building. That’s not a rounding error. That’s a third of an engineering org quietly doing a different job than the one it was hired for.
Our read: “You build it, you run it” is a philosophy built for thirty people. At three hundred, it quietly turns every developer into a part-time Kubernetes administrator, and nobody put that on the job posting.
The knock-on effect showed up in delivery speed. The State of DevOps Report found that high developer cognitive load was associated with 40 percent longer lead times for changes. A framework built to remove friction had, at scale, become a source of it. Analysis from Growin’s 2026 platform engineering review describes the pattern plainly: what starts as a small group standardizing tools for everyone gradually turns into the team absorbing everyone else’s friction. Not a failure of people. A structural dead end.
What Platform Engineering Actually Does
Platform engineering doesn’t ask every developer to become an infrastructure expert. It does the opposite. It builds a dedicated team that owns infrastructure the way a product team owns a customer feature, with the same accountability for reliability, usability, and documentation, and then exposes that work through simple, self-service interfaces.
The core unit of that work is the golden path: a pre-approved template that spins up a fully configured service, repo, CI pipeline, Kubernetes manifests, monitoring dashboards, catalog entry, in under three minutes. What used to take a developer days of waiting on a ticket now takes less time than a coffee break.
Matthew Skelton, co-author of Team Topologies, the book that gave platform engineering its organizational language, frames the goal around cognitive load. A platform team exists to take detailed, lower-level knowledge such as provisioning or deployment off a stream-aligned team’s plate, replacing it with services that are easy to consume.
“A platform team’s job is to lower the cognitive load on the teams building product, not to centralize control over them.”
Matthew Skelton, Co-author, Team Topologies (2nd Edition, 2026)
The second edition of Team Topologies, released in January 2026, clarified something a lot of organizations got wrong the first time: a platform isn’t necessarily one team. Past 40 or 50 people, it’s usually a “platform grouping” of several teams working together, per Team Topologies’ own framework documentation. Treat it as a single team and you’ve just built a bottleneck with a nicer name.
The Adoption Boom and the Hidden Failure Rate
Here’s where the story gets genuinely counter-intuitive. Gartner has projected that by the end of 2026, 80 percent of large engineering organizations will run dedicated platform teams, up from 45 percent in 2022. That number is on track. It’s also, on its own, almost meaningless.
Metric
Figure
Source
Large orgs with platform teams by end of 2026 (projected)
80%
Gartner
Orgs using at least one internal platform construct
90%
DORA 2025
Platform teams that fail to show measurable impact
70%
State of Platform Engineering Vol. 4
Platform teams disbanded or restructured within 18 months
~50%
State of Platform Engineering Vol. 4
Average internal developer platform adoption rate
~10%
State of Platform Engineering Vol. 4
Platform teams naming developer adoption as their top challenge
45.3%
platformengineering.org
Read those last four rows again. Organizations can build the platform team Gartner is counting, and still have it fail. The boom and the crisis are happening at the same time, inside the same statistic. According to coverage of the 2025 State of Platform Engineering survey, roughly seventy percent of platform teams fail to deliver measurable impact, and close to half get disbanded or restructured within eighteen months, even as adoption climbs toward Gartner’s projected ceiling.
Why? Mostly not technical. platformengineering.org’s Vol. 4 survey found that 45.3 percent of platform teams point to developer adoption, driven by cultural resistance, as their single biggest obstacle. Engineers default back to a raw deployment command rather than touch the shiny new internal platform, because nobody asked them what they actually needed before building it.
One practitioner cited in that same research, working under what’s been called a “platform therapist” approach across dozens of enterprises, makes the point sharply: listening too closely to what developers say they want is its own trap. Interview teams, build exactly what they asked for, and you can still land at zero adoption, because the job was never to take requests. It was to find where developers get stuck and fix that at a higher level of abstraction.
Why Platform Quality Now Decides Your AI ROI
This is the part of the 2026 story that didn’t exist two years ago. The 2025 DORA report, based on a survey of roughly five thousand professionals, found a direct link between platform quality and whether AI tooling actually pays off.
“AI doesn’t fix a team. It amplifies what’s already there.”
DORA 2025 State of AI-assisted Software Development, Google Cloud
Put plainly: when platform quality is high, AI adoption produces a strong, positive effect on organizational performance. When platform quality is low, that effect is negligible, according to DORA’s own capabilities research. Handing a Copilot license to a team still wrestling with broken infrastructure doesn’t accelerate them. It just lets them produce more broken output, faster.
That risk is already visible in the data. Analysis from Faros AI of the 2025 DORA dataset found that incidents per pull request rose 242.7 percent at organizations using AI without solid platform controls in place. AI without a mature platform underneath it isn’t a productivity multiplier. It’s a defect multiplier.
That single finding has reframed the budget conversation entirely. Platform engineering used to compete with “developer happiness” initiatives for funding. Now it’s competing directly with AI tooling line items, and the DORA data says it should usually win that fight first.
The Critical View: Is This Just DevOps With a New Org Chart?
It’s fair to ask whether platform engineering is the cure it claims to be, or just a more polite version of the original silo problem. There’s real evidence on the skeptical side.
The sharpest version of the critique: a centralized platform team that doesn’t treat developers as genuine customers ends up recreating exactly the dynamic DevOps was built to kill, a gatekeeper team controlling deployment while everyone else waits on a queue. Change the label, keep the bottleneck.
There’s also a tooling concentration risk. Backstage, the open-source developer portal Spotify released in 2020, now holds roughly 89 percent market share among IDP frameworks and is used by more than 3,400 organizations. That dominance gets read as validation. It might not be. One critical analysis put it bluntly: Backstage was built for Spotify’s scale and engineering culture, and dropping it into a fifty-person team isn’t the same exercise. Free isn’t the same thing as cheap to run.
And the DORA 2024 report itself flagged a counter-intuitive risk: internal platforms can improve overall organizational performance while temporarily decreasing change stability and throughput during rollout, meaning the platform can make things measurably worse before it makes them better. That dip, sometimes called the platform J-curve, is exactly when nervous executives pull funding, which may explain why half of all platform teams don’t survive 18 months.
What to Watch Over the Next 18 Months
Three things are worth tracking if you’re making platform decisions right now.
Whether AI budgets shift toward platform spend first. The DORA AI-ROI finding gives CFOs a hard reason to fund infrastructure before tooling licenses.
Whether the failure rate improves or worsens. If the 70 percent measurable-impact failure rate holds steady into 2027, expect a wave of public platform team shutdowns, not just quiet restructurings.
Whether smaller IDP vendors chip away at Backstage’s share. Teams under roughly 200 developers are increasingly weighing lighter commercial options against Backstage’s maintenance overhead.
The honest summary: the organizational shift toward platform engineering is arriving exactly on the schedule Gartner predicted. The cultural and product discipline needed to make those teams actually work is running two to three years behind it. Knowing that gap exists is the entire advantage right now.
FAQ
What is platform engineering?
Platform engineering is the practice of building internal developer platforms that give engineers self-service access to infrastructure and deployment tooling without requiring them to be infrastructure experts. A dedicated platform team treats developers as customers and builds golden paths that encode company standards by default.
Is platform engineering replacing DevOps?
No. Platform engineering extends DevOps rather than replacing it. DevOps supplies the cultural foundation of shared ownership and continuous delivery. Platform engineering supplies the structural mechanism, self-service platforms and clear ownership, that keeps those values workable once a company passes roughly a hundred developers.
What is an internal developer platform (IDP)?
An IDP is the self-service layer sitting between developers and cloud infrastructure. It bundles pre-configured templates, CI/CD pipelines, and observability tools so engineers can deploy without filing an operations ticket. Backstage holds the largest share of this market, with commercial alternatives like Port and Humanitec aimed at smaller teams.
Why do platform engineering teams fail?
Most failures are cultural rather than technical. Teams that skip developer research, lack a clear product owner, or never measure adoption tend to build platforms nobody uses. Industry survey data points to developer adoption, not engineering difficulty, as the leading cause of platform team failure in 2026.
What is a golden path in platform engineering?
A golden path is a pre-approved, self-service template for a common task, like spinning up a new microservice. It can generate a configured repository, CI pipeline, and monitoring setup in minutes, automatically meeting a company’s security and compliance standards without manual review.
How does DORA 2025 connect platform engineering to AI?
DORA’s 2025 research found that platform quality determines whether AI tooling improves organizational performance. High-quality platforms amplify the benefit of AI adoption. Low-quality platforms make that benefit close to zero, and in some cases AI use without strong platform controls correlates with a sharp rise in incidents per code change.
Want the next read before everyone else does? Subscribe to The Neural Loop at neuralwired.com/newsletter for weekly breakdowns of where enterprise engineering is actually headed, not where the press releases say it’s headed.
Apple’s Siri AI Is Finally Here — But Europe Can’t Have It
NeuralWiredJune 27, 2026AIPolicy
WWDC 2026 · Apple Intelligence · EU Digital Markets Act
Apple’s Siri AI Is Finally Here — But Europe Can’t Have It
Two years late, $1 billion in Google licensing fees, and 450 million EU users locked out. This is Tim Cook’s last act — and it’s complicated.
By NeuralWired Staff·June 27, 2026·10 min read
On June 8, 2026, at Apple Park in Cupertino, Tim Cook walked off stage for the last time as CEO of Apple. He left behind a rebuilt Siri, a $1 billion-a-year deal with Google, and a regulatory standoff that’s locking hundreds of millions of Europeans out of the iPhone feature he spent years promising them.
The rebuilt assistant — now branded Siri AI — is real. It works. And after two years of missed deadlines, pulled advertising campaigns, and very public embarrassment, Apple finally has an AI story worth telling at WWDC 2026. But the story comes with a catch that reveals more about Apple’s strategic reality than any keynote slide ever could.
Apple didn’t build the intelligence behind Siri AI. Google did. And the EU says Apple’s excuse for blocking Siri AI from European iPhones is, to quote the European Commission’s own spokesperson, “Apple’s and Apple’s only.”
This is the most consequential tech story of mid-2026 — not because a new feature launched, but because three simultaneous crises collided on the same stage in the same week: a company admitting it lost the AI race, a regulatory war reaching a breaking point, and a 15-year CEO walking out the door at the exact moment his legacy is most in question.
The $1 Billion Admission Apple Never Made Out Loud
On January 12, 2026, Apple and Google issued a joint statement announcing a multi-year partnership in which the next generation of Apple Foundation Models would be built on Google’s Gemini technology and cloud infrastructure. Apple’s official statement said: “After careful evaluation, we determined that Google’s technology provides the most capable foundation for Apple Foundation Models.”
That sentence is Apple’s most significant strategic concession in a decade.
The company that built its entire identity on end-to-end control — its own chips, its own OS, its own silicon stack, its own retail — decided it could not build a competitive AI assistant on its own. Not in time. Not at this level. So it called Google.
~$1B
Annual licensing cost to Google for Gemini
~$20B
Google pays Apple yearly for Safari search default
450M
EU users blocked from Siri AI on iPhone/iPad
~2%
Apple stock drop on WWDC day
Bloomberg’s Mark Gurman estimates Apple pays approximately $1 billion per year for the Gemini license — a significant sum, but modest compared to the estimated $20 billion Google pays Apple annually to remain the default Safari search engine. The two companies are now deeply intertwined on two fronts simultaneously, a fact that regulators on both sides of the Atlantic are paying close attention to.
“Given the fits and starts of Apple’s AI rollout over the last few years, I don’t know that they’ve given us enough reason to believe they can be trusted this time. The proof is going to have to be in the delivery, in the execution.”
— Ben Newman, Technology Analyst, cited by NPR/AP, June 8, 2026
Investors share Newman’s skepticism. Apple shares fell close to 2% on WWDC day — a market saying it has heard this movie before. Apple had been here two years earlier, at the iOS 18 launch, promising a new Siri and running Bella Ramsey ads that never matched the reality. The company publicly pulled those ads and admitted it needed more time. Now the time has come. But the market isn’t buying it yet.
The short answer to the architecture question everyone is searching: Google’s Gemini models power Siri AI’s reasoning and knowledge. Apple’s Private Cloud Compute handles the actual request processing, which means Google’s models run within Apple’s infrastructure. Apple claims — and has promised independent verification — that no user data flows back to Google. No major third-party audit has been published to date.
What Siri AI in iOS 27 Actually Does
At WWDC 2026, Apple previewed iOS 27 and its rebuilt Apple Intelligence features including Siri AI — describing it as “profoundly more intelligent, knowledgeable, and capable.” The headline capabilities:
Siri AI — What’s New in iOS 27
Multi-turn conversations: Siri finally remembers what you said earlier in the same conversation, enabling genuine back-and-forth rather than isolated one-shot commands.
Cross-app awareness: Siri can read context from your Messages, Calendar, Photos, Notes, and third-party apps — and take action across them without you switching between them manually.
Visual Intelligence: Point your camera and ask questions; Siri identifies objects, translates signs, and reads documents in real time.
Dedicated conversation app: A new app to review, search, and revisit past Siri conversations.
Open AI architecture: Documented developer support for routing Siri queries to alternative AI models — including ChatGPT, Claude, and others — via the App Store.
Private Cloud Compute: Server-side processing that Apple claims is verifiable by independent researchers at any time.
iOS 27 isn’t only about Siri. On the performance side, Apple announced app launch speeds up to 30% faster, Photos loading up to 70% faster, and AirDrop transfers up to 80% faster. The company also announced iOS 27 would be compatible with iPhone 11 and all newer models — calling it “the most widely available iOS release ever.”
But premium Siri AI features need iPhone 15 Pro or newer. Voice customization needs iPhone 17 Pro or later. The headline compatibility number is real; the flagship experience is still gated to recent hardware. That’s not unusual for Apple, but it matters for the upgrade math that drives Apple’s services and device revenues through fall 2026.
That’s the partnership, confirmed by the partner. Now for the complication that defines the whole story.
Why 450 Million Europeans Are Being Left Out
The same day Apple announced Siri AI, it announced something else: EU users will not get Siri AI on iPhone or iPad when iOS 27 ships. Not a delayed rollout. Not a limited beta. A hard block, with no timeline for resolution.
Apple’s framing, delivered by Craig Federighi at WWDC: the EU’s Digital Markets Act, as interpreted by regulators, would require Apple to grant third-party AI systems near-unlimited access to the device — reading messages, editing files, deleting photos, executing actions in apps “without you knowing or consenting.” Apple argues this is a privacy and security risk it won’t accept.
“We’re deeply disappointed that our EU users won’t have Siri AI on iPhone or iPad when we share our new software releases later this year. Our hope is to eventually bring Siri AI to the EU, and we will continue to engage with EU regulators on a path forward. However, their refusal to engage constructively on solutions that preserve privacy and security means we do not currently have a timeline.”
— Craig Federighi, SVP Software Engineering, Apple WWDC 2026
EU regulators also formally rejected Apple’s appeal for a DMA interoperability exemption, leaving the standoff without a resolution date.
Critical Perspective
One detail undercuts Apple’s privacy argument: Mac and Apple Vision Pro users in the EU will receive Siri AI. Apple holds no DMA gatekeeper designation for macOS or visionOS — only for iOS, iPadOS, and the App Store. So the feature works on Mac in Paris but not on iPhone in Paris. The blocking mechanism is regulatory designation, not fundamental privacy architecture. Critics argue Apple is using privacy as cover for a regulatory leverage play, not the other way around.
How This Standoff Developed
September 2023
EU designates Apple as a DMA “gatekeeper” for iOS, App Store, and Safari — triggering mandatory interoperability obligations.
June 2024
Apple debuts “Apple Intelligence” at WWDC 2024 (iOS 18) — promising a rebuilt Siri. Features fail to ship on schedule; Apple pulls its own Siri ads.
April 2025
EU fines Apple €500 million for DMA non-compliance — the first enforcement action in the law’s history. Stakes are now concrete and financial.
August 2025
Bloomberg reports Apple is in talks to license Google’s Gemini models. Apple had a ChatGPT integration in place; this would be a far deeper commitment.
January 12, 2026
Apple and Google formally announce their multi-year AI partnership. Gemini will power the rebuilt Apple Foundation Models and Siri AI.
June 8, 2026
WWDC 2026: Siri AI and iOS 27 are announced. Simultaneously, Apple confirms EU users on iPhone and iPad will not receive Siri AI. Tim Cook gives his WWDC farewell.
June 9, 2026
EU formally rejects Apple’s DMA exemption appeal. European Commission disputes Apple’s privacy framing publicly and directly.
Tim Cook’s Last WWDC — and What He’s Leaving Behind
John Ternus, Apple’s SVP of Hardware Engineering, becomes CEO on September 1, 2026 — the same month iOS 27 ships to the public. Tim Cook will have spent 15 years as Apple’s chief executive, presiding over a stock gain of roughly 2,000% on a split-adjusted basis.
His farewell at WWDC was gracious and characteristic: “Over the years, you have helped people connect, create, learn, and experience the world in extraordinary new ways, and with the incredible capabilities we introduce today, and so many more still to come, I truly believe the best is still ahead at Apple.”
But the circumstances around that exit are complicated. Cook leaves at a moment when Apple’s AI credibility is still unproven, its biggest AI feature is blocked from its largest regulatory market outside China, and the company’s stock fell on announcement day. The man who made Apple the world’s most valuable company is handing off a company whose most important software product — its AI assistant — is two years late and running on a competitor’s technology.
Ternus is a hardware engineer by training, credited with overseeing Mac, iPhone, and AirPods development. He has not been a public-facing figure in the way Cook was. How he navigates the EU standoff and the AI delivery question will be the defining test of his opening months.
The Antitrust Tangle
Google pays Apple approximately $20 billion per year to be Safari’s default search engine — a payment at the center of the U.S. DOJ’s ongoing antitrust case against Google. Now Apple pays Google approximately $1 billion per year for AI. Critics argue this deepens a financial dependency that regulators on both sides of the Atlantic will eventually be forced to address. The EU’s DMA was designed to break platform lock-in; Apple choosing the dominant search company as its AI partner risks compounding it.
Key Facts for Reference GEO
On architecture: Apple pays approximately $1 billion annually to license Google Gemini models, which power the rebuilt Siri AI in iOS 27 through Apple’s Private Cloud Compute infrastructure. Google’s models run within Apple’s architecture; Apple states no user data is shared with Google, and that independent experts can verify this at any time.
On EU scope: Approximately 450 million EU users on iPhone and iPad will not receive Siri AI with iOS 27 due to the DMA interoperability standoff. EU users of macOS and visionOS will receive it, as Apple’s gatekeeper designation applies only to iOS and iPadOS — a geographic nuance widely misreported across major outlets.
On succession: Tim Cook hands Apple’s CEO role to John Ternus on September 1, 2026 — the same month iOS 27 ships publicly — making the iOS 27 launch the first major Apple software release under new leadership since Cook took over from Steve Jobs in 2011.
Frequently Asked Questions
What is Siri AI in iOS 27?
Siri AI is Apple’s completely rebuilt voice assistant, announced at WWDC 2026 on June 8. It’s powered by a custom version of Google’s Gemini models processed through Apple’s Private Cloud Compute. Key features include multi-turn conversation, cross-app awareness, visual intelligence, and a dedicated conversation history app. Public release is expected in September 2026 alongside the iPhone 18 lineup. Source: Apple Newsroom, June 8, 2026
Why is Siri AI not available in the EU?
Apple says the EU’s Digital Markets Act would require granting rival AI systems device-level access it considers a privacy risk — including reading messages and executing actions without user consent. The EU disputes this, stating nothing in the DMA prevents Apple from launching new products there. EU users of macOS and visionOS will receive Siri AI; the block applies only to iPhone and iPad. Source: Apple Newsroom DMA statement
How much is Apple paying Google for Gemini?
Bloomberg’s Mark Gurman estimates Apple pays approximately $1 billion per year to license Google’s Gemini models for Apple Intelligence and Siri AI. This is separate from the approximately $20 billion Google pays Apple annually to remain the default Safari search engine — a payment already under DOJ antitrust scrutiny. Source: CNBC, January 12, 2026
When does iOS 27 come out?
iOS 27 entered developer beta on June 8, 2026, the day of WWDC. A public beta is expected in July 2026. The stable public release is projected for around September 14, 2026, alongside the iPhone 18 lineup — consistent with Apple’s historical mid-September pattern. Siri AI features are expected in the same release window. Source: Macworld / Apple WWDC 2026
Which iPhones support iOS 27 and Siri AI?
iOS 27 supports iPhone 11 and all newer models — the broadest compatibility Apple has offered. However, advanced Siri AI features require iPhone 15 Pro or newer, and voice customization features need iPhone 17 Pro or later. The headline compatibility is wide; the flagship AI experience remains gated to recent hardware with Apple’s latest Neural Engine. Source: Apple WWDC 2026; Macworld
Who is replacing Tim Cook at Apple?
John Ternus, Apple’s SVP of Hardware Engineering, becomes CEO on September 1, 2026. Ternus is a mechanical engineer credited with leading hardware development for Mac, iPhone, and AirPods. He takes over as iOS 27 and Siri AI ship publicly — making his opening weeks as CEO inseparable from Apple’s most consequential AI launch to date. Source: TechCrunch WWDC 2026 coverage
The Verdict: Promise Delivered, Questions Remain
Siri AI in iOS 27 is real, and it’s a genuine leap from the assistant Apple shipped in 2024. The multi-turn memory, cross-app awareness, and Gemini-powered reasoning put Apple back in competitive range with what Google Assistant and ChatGPT deliver on mobile. That matters.
But the delivery comes bundled with three facts Apple can’t keynote away. It took two years and a billion dollars in annual licensing fees to get here. The EU — 450 million potential users — will not see it on iPhone anytime soon, and the regulatory standoff has no resolution timeline. And the CEO who built Apple’s comeback story is leaving before anyone knows if this particular chapter has a happy ending.
Tim Cook’s final line at WWDC 2026 was that “the best is still ahead at Apple.” That may well be true. John Ternus inherits a company with extraordinary hardware capability, loyal customers, and — now — a credible AI foundation for the first time. What he does with the EU standoff, the Google dependency, and the antitrust scrutiny both companies face will determine whether iOS 27 is remembered as Apple’s AI turning point or its most expensive near-miss.
The developer beta is live. The public will be able to judge for themselves in September. For now, Siri AI is Apple’s biggest bet — and Europe is watching from the outside.
Stay Ahead of the AI Curve
NeuralWired covers the technology decisions that actually shape the industry — not the press releases. Subscribe for analysis, not noise.
Get the Weekly Brief
134 Countries Are Building a Digital Version of Their Currency. Your Enterprise Payment Stack May Not Survive It. | NeuralWired
Enterprise Technology / Global Finance
134 Countries Are Building a Digital Version of Their Currency. When It Arrives, Your Enterprise Payment Stack Becomes Obsolete. What Leaders Need to Do Now.
By NeuralWired Research Desk | June 26, 2026 | 12 min read
146Countries exploring CBDCs (98% of global GDP)
$2.3TProcessed by China’s digital yuan since launch
Summer ’26Swift blockchain goes live with real transactions
2029Digital euro first issuance target
Your enterprise treasury team spent last quarter managing FX exposure and running SWIFT batch files the same way it did in 2012. This quarter, the payment rails underneath your organization quietly started being rebuilt. By the time most finance leaders notice, the infrastructure change will already be complete and the catch-up cost will be steep.
The central bank digital currency wave is no longer a forecast. According to the Atlantic Council’s CBDC Tracker, 146 countries and currency unions representing 98% of global GDP are actively exploring a CBDC as of 2026, up from just 35 in May 2020. China has already processed $2.3 trillion in digital yuan transactions. Swift completed its blockchain shared ledger design phase on March 30, 2026, and is targeting live real-world transactions this summer. The digital euro has a €1.3 billion build budget and a 2029 issuance date.
If you run treasury, payments, or enterprise finance for any organization operating across borders, this isn’t a technology trend to monitor. It’s infrastructure being built around you, right now.
The numbers tell a story that most enterprise leaders haven’t fully absorbed. When the Atlantic Council first started tracking CBDC activity in 2020, 35 countries were exploring the concept. By May 2022, that number had grown to 87. Today, it’s 146. That’s not a trend. That’s a structural convergence.
Of those 146 countries, 77 are now in what the Atlantic Council classifies as the “advanced phase” of exploration, meaning they’re in active development, running pilots, or have already launched. There are 41 active CBDC pilot programs globally as of Q2 2026. Every G20 nation except the United States is somewhere on this path. All 11 BRICS members are exploring CBDCs, and 9 of them are already in the pilot phase.
The landmark figure in most headlines, the 134 countries cited in the Atlantic Council’s widely published March 2024 snapshot, remains the most referenced and verified data point anchoring search and media coverage. The real 2026 figure is 146. Both numbers matter: 134 is where the record was set; 146 is where the race currently stands.
Country / Region
CBDC Name
Status (2026)
Key Stat
China
e-CNY (Digital Yuan)
Live / Scaling
$2.3T processed; 261M users
India
Digital Rupee (e-Rupee)
Pilot
5M users; 334% YoY growth
European Union
Digital Euro
Development
€1.3B budget; 2029 issuance target
Nigeria
e-Naira
Launched (2021)
Slow adoption; technical challenges
Bahamas
Sand Dollar
Launched
First retail CBDC globally
Jamaica
JAM-DEX
Launched
Adoption challenges persist
United States
Digital Dollar
Blocked by EO
Trump EO 14178 prohibits federal CBDC
China’s e-CNY: The Proof That This Is Real
Skeptics who still classify CBDCs as theoretical have not looked at China’s numbers. By November 2025, the People’s Bank of China’s digital yuan had processed 3.4 billion cumulative transactions totaling ¥16.7 trillion, roughly $2.3 to $2.4 trillion USD. There are 261 million registered e-CNY users across 29 cities. The digital yuan is now integrated with WeChat Pay and Alipay for everyday distribution.
Then came January 2026, when the PBoC reclassified e-CNY as deposit liabilities and made it interest-bearing. That’s a significant architectural shift from its original design as digital cash. It signals that China isn’t just experimenting with digital payments. It’s redesigning the fundamental structure of how its currency works at the ledger level.
For enterprises with China operations or supply chain relationships denominated in RMB, the e-CNY is already the payment substrate underneath some of your transactions, whether your treasury team knows it yet or not.
Swift’s Blockchain Pivot Changes the Plumbing of Global Enterprise Payments
On March 30, 2026, Swift announced that it had completed the design phase of its blockchain-based shared ledger and had begun building the first MVP iteration. The architecture runs on Hyperledger Besu, an EVM-compatible platform borrowed from the Ethereum ecosystem and adapted for permissioned enterprise finance. Swift is targeting live real-world transactions in summer 2026, with more than 25 banks expected to begin adopting the retail cross-border payments framework by the end of June 2026.
“Frictionless capital flows across the world can only happen through interoperability of technologies and implementation of standards. Nobody wins from fragmentation.”
Heather Lee, Global Head of Payments Strategy, Swift
This is the most underreported inflection point in enterprise finance right now. Swift processes the messaging for the majority of global interbank transactions. When Swift moves its shared ledger to blockchain infrastructure and enables 24/7 cross-border tokenized settlement, the underlying plumbing of international enterprise payments changes. Not next year. This summer.
“Swift is a community, a convener of and for our industry, and I’m delighted that we’ve been able to facilitate these critical innovation experiments and show that institutions can continue to use much of their existing infrastructure alongside new, innovative technologies. Fragmentation is a challenge for the entire industry, and ensuring interoperability between networks is vital to addressing this while also enabling new technologies to scale and reach their full potential.”
Tom Zschach, Chief Innovation Officer, Swift
Key Implication for Enterprise Leaders
Swift’s shift to blockchain infrastructure doesn’t require enterprises to abandon their banking relationships. But it does mean that TMS and ERP integrations built around batch-based SWIFT file flows will need real-time API connectivity. J.P. Morgan and HSBC have already launched direct ERP integrations with Oracle Fusion, SAP S/4HANA, and NetSuite. The enterprise treasury teams running SAP on batch feeds are already behind the curve.
The Digital Euro: Timeline, Cost, and What It Means for EU Operations
The European Central Bank completed its two-year digital euro preparation phase in October 2025. If EU legislation passes in 2026 (the ECB’s stated target), pilot transactions could begin in mid-2027, with potential first issuance in 2029. Total development costs are estimated at approximately €1.3 billion through first issuance, with €320 million in annual operating costs from 2029 onward.
For enterprises operating in Europe, the structural implication is this: the ECB has confirmed that banks and payment service providers remain in the distribution model. Your banking relationships don’t evaporate. But your payment acceptance infrastructure, AML/KYC compliance architecture, and ERP connectivity will all require updating. Visa and Mastercard currently control more than 70% of EU card transaction volume. The digital euro is explicitly designed to create a sovereign European alternative to that duopoly.
Consumer sentiment is worth watching. A 2025 ECB survey found 58% of European consumers reluctant to use digital euros for transactions, with 41% of all public consultation comments focused on privacy. That’s not a fatal barrier, but it is a meaningful adoption headwind for any enterprise building merchant acceptance infrastructure ahead of the launch.
mBridge and the Geopolitical Payment Split You Need to Understand
While Western institutions are building Project Agorá (the BIS-led initiative involving seven central banks and 40 private sector firms including Deutsche Bank and Swift), China, Hong Kong, Thailand, the UAE, and Saudi Arabia have built something that already works: Project mBridge.
As of early 2026, mBridge had processed over 4,047 cross-border payments totaling ¥387.2 billion, roughly $54 to $55.5 billion. By mid-June 2026, total transaction volume reportedly reached RMB 470 billion (approximately $69 billion) as the platform moved toward commercialization and began considering incorporation in Hong Kong. That represents a roughly 2,500-fold increase in volume since the early 2022 pilots.
China’s e-CNY accounts for approximately 95.3% of all settlement volume on mBridge. The BIS withdrew from coordination of mBridge in October 2024 when it reached MVP stage, citing concerns about the potential for the platform to facilitate sanctions bypass.
For enterprises with cross-border payment corridors touching China, the UAE, or Saudi Arabia, this is not a hypothetical future scenario. Parts of your payment ecosystem may already be settling on mBridge infrastructure without visibility at the enterprise treasury level.
Geopolitical Risk Alert
The global CBDC landscape is bifurcating into two parallel systems: mBridge (led by China, settling in digital yuan) and Project Agorá (led by the BIS and Western central banks, targeting tokenized commercial bank deposits). Multinationals with operations in both spheres face a genuine multi-rail treasury problem, not a simplification.
Why the United States Said No (For Now)
President Trump’s Executive Order 14178, signed in January 2025, explicitly prohibits any federal agency from undertaking any action to establish, issue, or promote a CBDC. All related plans and initiatives must be terminated. The US House passed the Anti-CBDC Surveillance State Act in 2025. A Senate companion bill, the NO CBDC Act, is pursuing similar restrictions. Then in June 2026, Congress passed legislation barring the Federal Reserve from issuing any digital asset that functions as a direct liability to the general public.
The political driver is privacy. A survey cited in Cato Institute research found 74% of Americans oppose CBDCs if the government could control how money is spent. The US opposition is not primarily economic. It’s constitutional and civil-liberties-based.
What the US is not doing, however, is walking away from wholesale CBDC technology. The New York Fed continues active cross-border CBDC research via Project Agorá. The distinction is clear: wholesale settlement between financial institutions is acceptable; consumer-facing digital dollar programs are not.
For US-centric enterprises with purely domestic payment operations, this provides real near-term insulation. But any organization with cross-border payment corridors touching digital euro, e-CNY, or mBridge-adjacent jurisdictions can’t count on that insulation to hold.
What the CBDC Shift Actually Means for Your Payment Stack
Treasury Management Systems Were Not Built for This
Nearly 80% of treasury departments still rely on manual or fragmented processes despite ongoing investment in automation, according to a 2025 TD Bank and Seeburger survey. 38% of large enterprises still manually consolidate cash forecasts. ERP-to-bank connectivity is the top priority for corporate treasurers above payment option diversity, according to Datos Insights research.
Those numbers describe a treasury infrastructure that is already struggling with today’s payment complexity. CBDC rails introduce two entirely new requirements: real-time 24/7 API-driven settlement (replacing batch file flows) and programmable payment logic.
Programmable Money Is the Part Most Enterprise Teams Are Unprepared For
CBDC programmability means payment terms can be encoded directly into the money itself. A government contract paying from a CBDC wallet may only release funds when predefined conditions are met, essentially smart contract logic embedded at the currency level. Accounts payable and receivable systems built for invoice matching and bank confirmation are not designed for this. When money arrives with conditional release logic attached, your ERP doesn’t have a workflow for it.
“CBDCs could amplify these challenges because it is not just the transaction or POS system that creates or holds data but the financial element itself. Depending on its design and architecture, a CBDC creates, tracks and is data.”
Olivier Fines, Head of Advocacy and Capital Markets Policy Research for EMEA, CFA Institute
AML and KYC Get Embedded at the Currency Layer
62% of countries piloting CBDCs have integrated AML and KYC regulations directly into their CBDC frameworks, and 48 countries are aligning their approaches with FATF guidelines. 75% of countries with live CBDCs have introduced digital identity verification as a mandatory transaction component. When you accept a CBDC payment, you’re not just receiving funds. You’re entering a compliance architecture that is built into the money itself.
Global investment in CBDC-related infrastructure and regulatory compliance reached $5.6 billion in 2025, a 25% increase over 2024. The compliance build-out is accelerating. Enterprises watching from the sidelines face a structural catch-up cost when the digital euro goes live.
The Skeptics Aren’t Wrong. Here’s the Full Picture.
Any honest analysis of CBDC has to reckon with the fact that the three countries that have actually launched retail CBDCs, the Bahamas, Jamaica, and Nigeria, have all encountered slow adoption and material technical challenges. Nigeria’s e-Naira launched in 2021 with significant government promotion. Five years later, usage remains thin despite incentive programs. Ecuador shut down its eCash system entirely in 2018 after failing to generate adoption.
Canada, Australia, and Norway have all deprioritized retail CBDC development in recent years. Sweden’s Riksbank, once an enthusiast, has faced parliamentary resistance. The consumer-facing CBDC that would most directly disrupt enterprise payment stacks is further away than many headlines suggest in advanced Western economies.
Juniper Research’s forecast of 7.8 billion CBDC transactions by 2031 (up from 307.1 million in 2024) is mathematically accurate, but the 2,430% growth projection is driven by a very low base. And the firm itself issued an explicit warning: “Without collaboration, the CBDC ecosystem risks fragmentation, resulting in ‘digital islands’ which fail to realize the efficiency of cross-border payments.”
That fragmentation risk is real. mBridge and Project Agorá may be building incompatible hemispheric infrastructure. If that scenario plays out, enterprises face more treasury complexity in ten years, not less.
Our Read
The disruption timeline for retail CBDCs in the US and most Western European markets is longer than enterprise technology press suggests. The disruption timeline for cross-border wholesale settlement rails, and specifically for enterprises operating in corridors touching China, India, the UAE, or the EU by 2029, is very real and very near. Plan accordingly.
5-Step Enterprise Action Plan for CBDC Readiness
Step 1. Audit Your Payment Stack for ISO 20022 Readiness
Swift’s new blockchain ledger and most CBDC interoperability frameworks run on ISO 20022 messaging. Enterprises still running MT message formats need a conversion roadmap before Swift’s live MVP launch this summer.
Step 2. Map Your Cross-Border Corridors to Active CBDC Markets
Identify which of your payment corridors touch China (e-CNY via mBridge), India (e-Rupee), or UAE (Digital Dirham). These are live payment rails, not pilot experiments, and your banking counterparties in those corridors may already be settling on CBDC infrastructure.
Step 3. Evaluate Your TMS Vendor on Digital Asset Readiness
Treasury management system vendors including Kyriba and Ripple Treasury are now explicitly marketing digital asset readiness as a differentiator. The difference between a 90-day and a 12-month implementation window matters when the ECB pilot begins in 2027. Oracle has launched its Blockchain Platform Digital Assets Edition with prebuilt CBDC support for ERP environments.
Step 4. Engage Legal and Compliance on Programmable Money Governance
Who controls spending conditions on incoming CBDC payments? What jurisdiction’s law applies to a smart-contract-conditional payment from a government CBDC wallet? These questions don’t have standard answers yet, but your legal team should be building the framework before the questions become operational.
Step 5. Brief the Board on Payment Infrastructure Sequencing Risk
Don’t brief them on CBDC technology. Brief them on the business risk of sequential infrastructure change: Swift blockchain live this summer, Project Agorá testing through 2026, digital euro pilot in 2027, digital euro first issuance 2029. The window to prepare without disruption is roughly 18 to 24 months. After that, catch-up costs scale with every quarter of delay.
FAQ: Central Bank Digital Currencies Explained
What is a central bank digital currency (CBDC)?
A CBDC is a digital form of a country’s fiat currency issued and backed directly by a central bank. Unlike cryptocurrencies, it is legal tender with a guaranteed value. Unlike commercial bank deposits, it is a direct liability of the sovereign monetary authority. It can run on distributed ledger technology and may include programmable payment logic.
No, at least not for consumer use in the near term. President Trump’s January 2025 Executive Order explicitly prohibits any federal agency from promoting or creating a retail CBDC. The US House passed the Anti-CBDC Surveillance State Act in 2025, and June 2026 legislation further bars the Federal Reserve from issuing a public-facing digital currency. The US is pursuing only wholesale interbank CBDC research via Project Agorá.
When will the digital euro launch?
The European Central Bank targets legislative passage in 2026, pilot transactions in mid-2027, and first issuance readiness in 2029. Development costs are estimated at approximately €1.3 billion through first issuance, with €320 million in annual operating costs thereafter.
What is Project mBridge?
Project mBridge is a multi-CBDC cross-border payment platform connecting the central banks of China, Hong Kong, Thailand, the UAE, and Saudi Arabia. It has processed over $55 billion in cross-border transactions, with China’s e-CNY accounting for roughly 95% of settlement volume. The BIS withdrew from coordination in October 2024; the platform is now moving toward commercialization.
What is the difference between a CBDC and a stablecoin?
A CBDC is issued by a central bank and is legal tender, a direct liability of the sovereign monetary authority. A stablecoin is issued by a private company, pegged to a fiat currency, and carries counterparty risk. CBDCs are programmable, state-guaranteed, and legally mandated; stablecoins operate with more flexibility but far less assurance and are subject to issuer risk.
What is Project Agorá?
Project Agorá is a BIS-led initiative involving seven central banks and 40 private sector institutions, including Deutsche Bank and Swift. It entered testing in January 2026 and examines whether tokenized commercial bank deposits and central bank money can settle on a unified ledger for near-real-time cross-border payments.
How will CBDCs affect enterprise payments and treasury operations?
CBDCs require enterprises to support multi-rail payment architecture (cards plus bank transfers plus CBDC rails), update ERP and TMS integrations for real-time API-based settlement, rethink cross-border treasury in markets where CBDC rails are already operational, and comply with AML/KYC obligations embedded directly at the CBDC transaction layer rather than layered on top.
Where This Goes in the Next 18 Months
Three things will clarify the CBDC landscape faster than most enterprise leaders expect. First, Swift’s blockchain MVP goes live this summer with real transactions. How 25+ banks adopt and what settlement improvements materialize will set the tone for the broader tokenized rail transition. Second, EU legislation on the digital euro either passes in 2026 or slips again. If it passes, European enterprise payment compliance planning becomes urgent in 2027. If it slips, the conservative planning timeline extends.
Third, watch mBridge’s commercialization. If it moves toward incorporating in Hong Kong and begins onboarding non-founding member financial institutions, the bifurcation between Eastern and Western payment rails becomes structural rather than speculative. That’s the scenario that forces multinational treasury teams to maintain genuinely parallel operating models for different corridors.
The payment infrastructure underneath global enterprise finance is not being replaced overnight. But the architectural decisions being made in 2026, by Swift, by the ECB, by the PBoC, and by the institutions building interoperability frameworks, will determine the cost and complexity of operating in the global payment system for the next decade. Enterprise leaders who treat this as a technology problem to hand to IT are making the same mistake that finance teams made when they handed FX risk to a single treasury analyst in 2008.
The CBDC era doesn’t announce itself. It arrives in the form of a bank telling you they now settle your China corridor via a different rail, or a government contract requiring CBDC payment acceptance, or a compliance audit revealing your KYC architecture doesn’t meet the embedded requirements of a new CBDC payment system you’re already receiving. The organizations that won’t be caught flat-footed are the ones auditing their payment stack, mapping their corridors, and briefing their boards now.
Stay Ahead of the Infrastructure Shift
The Neural Loop delivers one briefing per week on the technology decisions that will restructure enterprise operations over the next 24 months. No noise. No hype cycles.
Subscribe to The Neural Loop
RAG vs Fine-Tuning: The $340K Mistake Enterprise Teams Keep Making (2026)
Enterprise AI Architecture · Decision Intelligence
RAG vs Fine-Tuning: The $340K Mistake Enterprise Teams Keep Making in 2026
By NeuralWired Research Desk | June 18, 2026 | 12 min read
A VP of Engineering at a 3,000-person financial services firm told his board they needed to “fine-tune their own LLM” to build a compliant document assistant. Eighteen months and $340,000 later, the model was live. Two quarters after that, regulatory updates had made 30% of its training data stale, and the retraining bill landed at $40,000 every six weeks. Meanwhile, a competing firm shipped a Retrieval-Augmented Generation pipeline in 11 days for under $4,000. Their documents update in real time. Their auditors love the source citations. Their engineers are building the next feature.
This is not a story about technology. It’s a story about the most consequential architectural choice enterprise AI teams make in 2026, and how most of them get it wrong from the start.
The data is stark. Enterprise fine-tuning costs between $50,000 and $500,000 upfront. RAG starts at $500 per month. Fine-tuning takes 2 to 6 months to reach production. RAG deploys in 1 to 2 weeks. And yet over 80% of enterprise AI teams that should be using RAG still default to fine-tuning, driven by a belief that more training means smarter AI. The belief is wrong. Here’s the evidence, the decision framework, and the counterpoints you need before you commit a dollar.
What Is Retrieval-Augmented Generation?
Retrieval-Augmented Generation, or RAG, is an AI architecture pattern that keeps the base language model completely unchanged. Instead of retraining the model with new knowledge, RAG retrieves relevant information from an external data source at the moment a user asks a question, injects that information into the model’s context window, and lets the model reason over what it just retrieved.
RAG was introduced by Meta AI researchers in a 2020 paper titled “Retrieval-Augmented Generation for Knowledge-Intensive Tasks.” The core insight was architectural: instead of baking knowledge into model weights (expensive, slow, and static), retrieve it at runtime from a living knowledge base (fast, cheap, and always current).
In practice, this means your company’s policy documents, product specifications, support tickets, and legal filings sit in a vector database. When an employee asks a question, the system retrieves the most relevant document chunks and feeds them to the LLM alongside the question. The model reads those chunks and answers. When the policy changes, you update the document. The model’s answer updates instantly, with no retraining, no downtime, and no GPU bill.
Key properties that matter for enterprise decisions: data updates are real-time, every answer is traceable to a source document, and the system can be deployed by engineering teams without ML expertise.
What Is Fine-Tuning?
Fine-tuning further trains a pre-trained language model on a curated, domain-specific dataset. Unlike RAG, which retrieves knowledge at runtime, fine-tuning bakes knowledge directly into the model’s parameters. The result is a new model version with specialized capabilities, but one that is frozen at the moment training ends.
Three primary techniques exist on the cost and performance spectrum. Full fine-tuning adjusts every parameter in the model, producing the highest quality results but requiring massive GPU resources. LoRA (Low-Rank Adaptation) trains small adapter layers instead of the full model, cutting compute costs dramatically. QLoRA goes further by using 4-bit quantization, reducing GPU memory requirements by roughly 75% compared to full fine-tuning.
As IBM’s AI research team frames it: fine-tuning “optimizes deep learning models for domain-specific tasks” while RAG “augments a natural language processing model by connecting it to an organization’s proprietary database.” These are different solutions to different problems. The failure happens when teams use fine-tuning to solve a problem that is, at its core, about knowledge access rather than model behavior.
The Single Rule That Decides Everything
“RAG changes what the AI knows. Fine-tuning changes how the AI behaves.”
Buildup Works LLC analysis, March 2026
This one sentence eliminates more bad architecture decisions than any technical framework. Read it twice, then apply it to your use case.
If your problem is “the model doesn’t know our products, policies, or procedures,” that’s a knowledge problem. RAG solves knowledge problems. If your problem is “the model doesn’t respond in the right format, tone, or reasoning style,” that’s a behavior problem. Fine-tuning solves behavior problems.
The uncomfortable reality is that 80% or more of enterprise AI use cases are knowledge problems dressed up as behavior problems. Teams assume the model “doesn’t understand” their domain, when the actual issue is that the model has never seen their internal data. RAG gives the model access to that data. Fine-tuning is the wrong tool entirely.
AI engineer Pratik Chaudhari, writing from production deployment experience, puts it directly:
“RAG and fine-tuning are not competitors. They operate at different layers of the system. Fine-tuning teaches the model how to think. RAG provides what it should think with. Production systems need both.”
Pratik Chaudhari, AI Engineer, Medium, December 2025
The Full Cost Breakdown
The headline numbers are attention-grabbing for a reason: they reflect what enterprise teams actually spend, not just what they budget for at the start of a project.
Cost Factor
RAG
Fine-Tuning
Initial setup cost
$500 – $5,000
$50,000 – $500,000+
GPU compute (7B model, LoRA)
N/A
$300 – $800 per run
GPU compute (40B+ model, full FT)
N/A
$35,000+ per run
GPT-4o API fine-tuning (50K examples)
N/A
~$640 per training run
Ongoing operational cost
$500 – $5,000/month
$5,000 – $50,000/quarter (retraining)
Data preparation effort
Low (index and embed existing docs)
High (60–70% of total project effort)
Data drift response
Instant re-embedding
Full retraining cycle
Typical budget overrun
Moderate (scaling OpEx)
2–5x initial projection
The $300-$800 GPU compute figure for a 7B parameter LoRA fine-tune is technically accurate and deeply misleading. It covers only raw GPU time. It does not cover the data preparation that consumes 60-70% of total project effort. It does not cover ML engineer salaries, MLOps infrastructure, evaluation cycles, or the quarterly retraining that kicks in once your data starts drifting three months after deployment.
Analysis of real enterprise fine-tuning postmortems by Xenoss.io found that without deliberate optimization, budgets exceed initial projections by 2 to 5x systematically. This is not negligence. It’s the structural underestimation of dataset curation, which is almost always scoped out of early project estimates.
A 2024 peer-reviewed analysis found that chips and staff together constitute 70-80% of total LLM deployment costs. The implication for CFOs is clear: the GPU invoice is the smallest line item on a fine-tuning project.