NeuralWired’s Technology section covers the developments reshaping how the world builds, deploys, and regulates digital innovation. We report daily on the stories driving global conversation in artificial intelligence, big technology companies, startups and venture funding, cybersecurity, consumer gadgets and devices, and blockchain and cryptocurrency.
Our technology coverage goes beyond product announcements. When a major AI model launches, we explain what it can actually do and where its claims are overstated. When a startup raises a large funding round, we look at whether the business behind it can sustain that valuation. When a cybersecurity breach hits the news, we explain who is affected and what comes next, not just what happened. Each article is built from original research into primary sources, including company statements, technical documentation, regulatory filings, and verified data, and is written by our editorial team rather than generated automatically.
Readers come to this section for daily updates on the technology stories that matter globally, from shifts inside major technology companies to emerging tools changing how people work, communicate, and build. Whether you are a founder, an investor, an engineer, or simply someone trying to understand where technology is heading next, NeuralWired’s Technology coverage is built to keep you informed without wasting your time on hype.
Machine Learning Engineer Salary in 2026: Google, Meta, and OpenAI vs. Everyone Else
NeuralWired Research·May 2026·14 min read·Salary & Careers
A machine learning engineer at Meta’s E6 level cleared $786,000 in total compensation last year. An entry-level ML engineer at a mid-market company in Dallas earned $69,000. Both carry the same job title. This is the central problem with every ML engineer salary article you’ve read, they average those two people together, then tell you the result means something.
The machine learning engineer salary in 2026 isn’t a number. It’s a range so wide it makes the average nearly useless. What you actually need to know is which part of that range you’re in, what moves you between tiers, and what the market looks like beyond the FAANG-heavy data that dominates the conversation. That’s what this article delivers.
$161K
Average US base salary (Glassdoor, May 2026)
$265K
Median total comp at top-tier tech (Levels.fyi)
3.2:1
Open ML roles vs. qualified candidates
56%
Wage premium for AI skills globally (PwC 2025)
The Real Numbers | By Source, Not By Average
Every major salary database is measuring a different population. Before you benchmark against any figure, you need to know who that figure actually describes. Here’s what each source is actually telling you:
Source
Figure (US, 2026)
What It Actually Measures
Glassdoor
$161,030 avg base; up to $248,375 at 90th pct
Self-reported, delayed, skews toward large employers
Built In
$162,080 base; $212,022 total comp
Verified tech-industry responses; most common bracket $200K–$210K
ZipRecruiter
$128,769 average; $101.5K–$155K (25th–75th pct)
Broader job market including non-tier-1 employers
Levels.fyi
$265,000 median total comp
Primarily FAANG and top-tier tech — equity-heavy, not representative of full market
PayScale
$125,000 avg base
Broadest employer mix; includes many non-tech-industry ML roles
Robert Half
$170,750 midpoint; 4.1% annual growth
Hiring manager surveys; reliable for mid-market enterprise
Why This Range Exists
The $40,000 spread between ZipRecruiter and Levels.fyi isn’t a measurement error, it’s a structural reality. One database captures a Series B startup in Austin; the other captures a staff engineer at Google. They’re different jobs with the same title. Any article that gives you a single average number without this context is wasting your time.
Entry level is a separate market entirely. Entry-level ML engineers in the US average $69,362 as of May 2026, with the majority earning $51,500–$78,500. The headline $200K+ figures are for engineers with three to seven years of production deployment experience. Not bootcamp graduates. Not new master’s program completers.
Google, Meta, OpenAI: What the Data Actually Shows
If you want the ceiling, Levels.fyi’s verified compensation data from May 2026 is the place to look. But interpret these numbers as the top end of the market, not the market itself.
Company
Entry Level
Senior/Principal
Median Total Comp
Meta
$187K (E3)
$786K (E6)
$450,000
Google
$199K (L3)
$743K (L7)
$290,000
Google (AI Engineer title)
$183K (L3)
$583K (L6)
$280,000
OpenAI (L5 SWE)
$1.15M total: $336K base + $774K stock/year
Frontier lab; not industry-representative
OpenAI’s compensation figures deserve a separate sentence: they are not a market benchmark. They reflect the economics of a frontier AI lab during a capital-intensive arms race, the same conditions that produce $300 million in equity grants for a handful of researchers. Anthropic operates in the same tier. These numbers are real; they’re just not what a hiring manager at a healthtech company or a Series C startup is competing against.
“The salary conversations in this discipline are harder than most because the gap between base salary and total comp is enormous at the senior end, and because ‘ML engineer’ means different things at different companies. Someone building recommendation systems at a Series D startup and someone fine-tuning foundation models at Meta are both called ML engineers. They’re not doing the same job. They’re not paid the same either.”
— Robert, Co-Founder & Strategic Advisor, KORE1 (ML Engineer Salary Guide, May 2026)
Which Skills Move the Needle (With Dollar Figures)
The single most actionable finding from 2026 salary data: specialization has a larger salary impact than switching companies, changing cities, or earning an additional degree. Here’s the breakdown from Signify Technology’s 2025–2026 US Market Benchmarks:
Skill / Specialization
Premium Over Base
Dollar Range
Generative AI / LLM Fine-tuning
+40%–60%
+$56,000–$110,000
MLOps Expertise
+25%–40%
+$35,000–$74,000
NLP
+20%–35%
+$28,000–$64,000
PyTorch Proficiency
+8%–12%
+$10,000–$22,000
RAG architecture, retrieval-augmented generation, deserves specific mention because KORE1’s placement data shows it triggering negotiating power in a way that generic “AI experience” doesn’t. One placement example from their May 2026 guide: a healthcare AI engineer moving to fintech negotiated a $22K base increase specifically because she had built a production RAG system processing 400,000 clinical documents. That’s not a hypothetical. That’s a closed deal.
The premium compounds with seniority. Levels.fyi’s Q3 2025 analysis found that entry-level AI engineers earn 6.2% more than non-AI peers, but staff engineers earn 18.7% more. Investing in AI specialization early isn’t a one-time bump; it’s a multiplier that widens as you advance.
“The biggest mistake in 2026 is hiring a PhD researcher when you actually need a software engineer who knows how to deploy a model reliably to production. The highest ML Engineer salaries are no longer going to those who can theorize about AI. They are going to those who can ship AI products reliably.”
— Optiveum, specialist ML recruitment (April 2026)
The Credential Debate | What the Data Actually Shows
There’s a narrative circulating that portfolio beats degree, and it’s partially true. For applied engineering roles, deploying pipelines, building RAG systems, productionizing models, hiring managers at most non-research firms have deprioritized formal degrees. The PwC 2025 data found employer demand for formal degrees falling 9 percentage points for AI-exposed jobs between 2019 and 2024.
But the counterpoint matters: the percentage of job postings mentioning PhDs jumped over 6% year-over-year in 2026, while postings requiring master’s and bachelor’s degrees dropped. At the frontier research tier, the roles with the highest ceilings, academic credentials are becoming more important, not less. The “just ship things” premium applies to applied engineers; research scientists and those aiming for foundation model labs face a different calculus.
The Global Gap: US vs. UK, Canada, Australia
The US salary differential isn’t narrowing. For ML engineers outside the US, this is one of the most financially consequential career facts of the decade.
Market
Average ML Salary (USD equiv.)
Source
United States
$161,000–$186,000 base; $212K–$265K total
Glassdoor / Levels.fyi, May 2026
United Kingdom
~$97,000 (£76,198)
Indeed UK, May 2026
Canada
~$129,850
Qubit Labs, 2026
Australia
~$91,000 (AUD $137,500 avg)
Glassdoor AU, May 2026 (183 submissions)
Switzerland
~$160,300
Qubit Labs, 2026 — leads Western Europe
A senior ML engineer in the UK earns roughly £76K–£120K, or $100K–$155K USD equivalent. The same profile in the US commands $180K–$300K+ total comp. That gap, roughly double, has one practical implication for UK, Canadian, and Australian engineers: remote-first US employers are one of the only pathways to access US-scale compensation without relocating. It’s not a small opportunity; it’s a career-defining one for engineers who pursue it deliberately.
Why Salaries Are This High | And the Risks That Could Change That
The ML salary premium has a structural explanation, not just a hype explanation. Understanding the difference matters for anyone making a multi-year career bet.
The Supply Problem
There are approximately 1.6 million open AI/ML positions and only around 518,000 qualified candidates, a 3.2-to-1 demand-to-supply ratio. That’s not a hiring freeze number; that’s the ratio driving upward pressure on compensation. The ML market is projected to reach $503.4 billion by 2030, up from $113.1 billion in 2025. Demand for ML talent is growing faster than universities can produce it, and the gap between “completed an ML course” and “can deploy and maintain a production LLM pipeline” is enormous. That gap is where the compensation premium lives.
PwC’s 2025 Global AI Jobs Barometer, the largest study of its kind, based on analysis of close to one billion job ads across six continents, found that workers with AI skills command a 56% wage premium over equivalent roles that don’t require AI skills, across every industry analyzed. That premium was 25% the year prior.
“In contrast to worries that AI could cause sharp reductions in the number of jobs available, this year’s findings show jobs are growing in virtually every type of AI-exposed occupation, including highly automatable ones. Even if they can pay the premium required to attract talent with AI skills, those skills can quickly become out of date without investment in the systems to help the workforce learn.”
— Joe Atkinson, Global Chief AI Officer, PwC (PwC Press Release, June 2025)
Meanwhile, ML engineering is growing while general software engineering contracts. AI/ML job postings were up 59% from the pre-pandemic baseline in July 2025 (Indeed Hiring Lab), while general software engineering positions were down 49%. The “tech layoffs” and “ML demand” headlines are describing different talent pools. They are not contradictory.
The Risks | Two Worth Taking Seriously
Contrarian Signal
Glassdoor’s 2026 data shows ML engineers as the only category with a year-over-year salary decrease, down approximately $10,000 from early 2025. The 365 Data Science analysis that surfaced this finding correctly notes Glassdoor’s methodology limitations (self-reported, delayed, subject to sampling bias), but the signal shouldn’t be dismissed entirely. Our read: this likely reflects early normalization in generalist ML roles while LLM and GenAI specialists continue to see premiums. It’s not evidence of a crash, but it’s a reason not to assume unlimited upward trajectory.
The second risk is structural: the 2021 SaaS hiring bubble inflated headcount on speculative valuations, then deflated hard. The prompt engineering “hype cycle” saw purported salaries of $250K–$300K briefly circulate before it became clear most of those roles required significant ML background, not just clever prompting. If AI productivity gains don’t materialize at the expected rate for enterprises, the frenzy driving compensation above market-clearing levels could correct. It’s a real scenario. The difference from 2021, as Pin’s Q3 2025 analysis notes, is that productivity growth in AI-exposed industries has nearly quadrupled since 2022, providing an economic foundation the SaaS bubble never had.
What This Means for Your Career Right Now
If You’re an Active ML Engineer
The most valuable move available to you in 2026 isn’t switching companies, though that’s worth $30K–$60K on average. It’s building demonstrable production deployment experience in LLMs or RAG architecture, which is worth $20K–$40K in base premium over 12 months. Internal promotions consistently lag the job-switching premium, which means that if you’ve built something real, the market will pay you more for it than your current employer will.
If You’re Making a Career Switch Into ML
The share of AI/ML engineering roles in overall tech hiring grew from 10% in 2023 to over 50% in 2025. But don’t benchmark against $200K+ headline figures, those are for engineers with three to seven years of production experience. Entry-level in this field averages $69,362. The path to senior compensation is real, but it runs through shipping things, not just studying them. Portfolio work and production deployments now outweigh degrees for most hiring decisions at non-research firms.
If You’re Hiring
AI/ML job postings increased 89% in the first half of 2025. Seventy percent of firms report a lack of applicants as their primary hiring hurdle. Firms that fail to adjust compensation benchmarks are losing candidates within 48 hours of an offer. One tactical lever that’s underused: contract-to-perm structures. Permanent base salaries for senior ML engineers sit at $175K–$240K; contract day rates for the same level run $800–$1,200/day. Engineers who won’t engage on a traditional permanent posting sometimes will on a project-based structure. That’s not a salary hack, it’s a pipeline access strategy.
Frequently Asked Questions
What is the average machine learning engineer salary in 2026?
In 2026, the average ML engineer base salary in the US ranges from $128,000 to $186,000, depending on the source and employer population measured. Total compensation including equity and bonuses averages $212,022 (Built In) to $265,000 (Levels.fyi). Senior engineers at top tech companies, Meta, Google, OpenAI — can exceed $400,000–$786,000 in total comp.
How much do machine learning engineers make at Google and Meta?
At Google, ML engineer total compensation ranges from $199K (junior, L3) to $743K (principal, L7), with a median of $290K. At Meta, the range is $187K (E3) to $786K (E6), with a median of $450K. Both figures include base salary, stock grants, and annual bonuses, per Levels.fyi updated May 2026.
Do machine learning engineers make more than software engineers?
Yes, by a significant margin. The BLS median for software developers is $133,080. ML engineers average $161K–$186K base in the same market. At the staff/principal level, the AI premium reaches 18.7% over non-AI peers. Specialists in LLM fine-tuning earn 40–60% above baseline ML salaries.
What machine learning skills pay the most in 2026?
LLM fine-tuning commands the highest premium: 40–60% above base ML salaries ($56K–$110K additional). MLOps expertise adds 25–40% ($35K–$74K). NLP adds 20–35%. Generative AI and RAG architecture are the fastest-rising skills. ML Research Scientists command the highest ceiling, averaging $226,353, with top labs offering $550K+ total comp.
What is the machine learning engineer salary in the UK vs. USA?
The gap is stark. UK ML engineers average £76,198/year (~$97K USD), per Indeed UK (May 2026, 811 salaries). In the US, the average is $161K–$186K base, roughly double the UK figure. Senior US roles at FAANG clear $300K–$700K+ total comp. Switzerland leads Europe at ~$160K USD. Canada averages ~$130K USD.
Is machine learning engineering a good career in 2026?
By most metrics, yes. The BLS projects 26% job growth for the closest occupational category through 2034; data scientists are the 4th fastest-growing occupation in the US economy. AI/ML postings were up 163% year-over-year in 2025. Demand outstrips supply 3.2:1. The two real risks: skill obsolescence as the field evolves rapidly, and role-title inflation that makes it harder to signal genuine expertise.
What You Now Know That Most People Don’t
The ML engineer salary story in 2026 isn’t “AI pays well.” That’s a headline. The real story is about structure: a market where the average is nearly meaningless without context, where the gap between a generalist and an LLM specialist is $56K–$110K, where the US salary is roughly double the UK’s, and where the supply-demand imbalance isn’t a hype cycle, it’s a documented 3.2:1 ratio that’s been consistent for multiple years.
The forward implication for the next 6–18 months: the era of “any ML experience commands a premium” is ending. The era of “demonstrable production experience in specific high-value skills” is in full effect. Engineers with provable LLM fine-tuning and RAG deployments will continue to see premiums. Generalist ML engineers who haven’t specialized, particularly those without frontier model experience, may find the Glassdoor salary decline data more predictive than the Levels.fyi headline numbers.
Three things to watch:
Credential inflation at research labs. PhD demand in ML job postings jumped 6% in 2026. If you’re targeting frontier labs, the academic track matters more than the “just ship it” narrative suggests.
Remote-first US employer expansion. The US/UK and US/Australia salary gaps are the single biggest financial arbitrage opportunity for international ML engineers. Watch for US companies formalizing remote hiring for senior roles.
The productivity ROI test. Enterprise AI spending is enormous. If it doesn’t produce measurable productivity returns at scale through 2025–2026, the hiring frenzy that’s inflating mid-market ML salaries could correct. The signal to watch: Fortune 500 renewal rates on AI contracts.
Stay ahead of the market.
The Neural Loop delivers the most important AI and tech career signals every week, without the noise. Read by ML engineers, hiring managers, and investors who track this field seriously.
Subscribe to The Neural Loop →
How Agentic AI Works: The Architecture Behind Autonomous AI in 2026 | NeuralWired
Agentic AI · 2026
How Agentic AI Actually Works | And Why Most Companies Are Getting It Wrong
Agentic AI is no longer a research topic, it’s running in production at Capital One, Fountain, and dozens of enterprises you’ve heard of. Here’s the real architecture: the ReAct loop, multi-agent orchestration, the security vulnerabilities already being exploited, and why Yann LeCun thinks the whole approach is fundamentally broken.
NeuralWired Research Team·May 2026·Deep Explainer · 14 min read
A hiring platform called Fountain quietly rewired its recruitment pipeline last year. No fanfare. No press release about “AI transformation.” Just a hierarchical multi-agent system handling candidate screening end-to-end, and the results were stark: 50% faster screening, 2x candidate conversions, staffing cycles compressed to under 72 hours. Humans stayed in the loop for final decisions. Agents did everything else.
That’s agentic AI in its most useful form. Not a chatbot. Not autocomplete at scale. A system that perceives, reasons, acts, observes the result, and iterates, autonomously, until a goal is achieved.
The market is pricing this in fast. The AI Agents market was valued at $7.84 billion in 2025 and is projected to reach $52.62 billion by 2030, a 46.3% CAGR. Vertical agents, domain-specific systems for legal, healthcare, and financial services, are the fastest-growing segment at 62.7% CAGR. But the gap between the hype and what’s actually running in production is significant. Understanding why requires understanding how agentic AI actually works.
What Agentic AI Actually Is
Start with the distinction that matters most to anyone building or buying this technology: agentic AI is not generative AI with more confidence. It’s a categorically different architecture.
Generative AI, the ChatGPT most people know, operates in a single pass. Prompt in, response out. It’s reactive by design. Agentic AI systems do something fundamentally different: they plan multi-step tasks, use external tools (APIs, browsers, databases, code executors), take actions in the world, and iterate until a goal is achieved with minimal human input.
Working Definition
An AI agent is a system that can execute multi-step plans, use external tools, and interact with digital environments, functioning as an autonomous component within larger workflows rather than a single-turn responder. The key distinction from a chatbot is autonomy and action.
“AI agents can execute multi-step plans, use external tools, and interact with digital environments to function as powerful components within larger workflows.”
— Kate Kellogg, Professor of Management and Innovation, MIT Sloan School of Management
Four capabilities define the current generation of agentic systems, and distinguish them from everything that came before. Autonomy: operating without continuous human intervention. Goal-oriented behavior: adapting strategies as conditions change mid-task. Reasoning and planning: breaking complex problems into multi-stage solutions. Learning and adaptation: improving based on outcomes and feedback within a session or across sessions.
The ReAct Loop: The Engine Inside Every Agent
If you want to understand how agentic AI works at a technical level, you need to understand one paper from October 2022: the ReAct framework, introduced by Shunyu Yao and a team at Princeton and Google Brain. It is the architectural backbone of virtually every production agentic system shipping in 2026.
ReAct stands for Reasoning + Acting. The insight is deceptively simple: instead of generating a single response to a prompt, an agent alternates between two modes. It reasons about what to do. Then it acts, calling a tool, querying a database, executing code. Then it observes the result of that action. Then it reasons again, informed by what it just saw. Then it acts again. This loop continues until the task is done.
Written out as a sequence, a ReAct agent operating on a research task looks like this:
Step
Mode
What happens
1
Perceive
Receive task input — user goal, context, available tools
2
Reason
Language model generates a plan: “I should search for X, then check Y”
3
Act
Call a tool — web search, API, code executor, database query
4
Observe
Tool returns a result; agent sees the output
5
Reason
Update the plan based on what was observed
6
Act / Complete
Take next action, or conclude if goal is met
What makes this powerful is also what makes it dangerous: the loop runs until the model decides it’s done. A poorly constrained agent will keep acting. This is why a mature pattern that solidified in 2026 is the tiered constraint model, explicit priority layers baked into every agent’s operating instructions:
Safety first — never take destructive or irreversible actions without human confirmation
Accuracy — prioritize correct outputs over speed
Goal completion — achieve the stated objective
Efficiency — accomplish the above with minimum steps
Goals conflict constantly in complex tasks. Explicit priority ordering resolves them deterministically rather than leaving the model to improvise, which it will, unpredictably, without this structure.
Multi-Agent Systems and Orchestration
A single agent can handle impressive tasks. But the frontier of enterprise agentic AI is multi-agent systems, networks of specialized agents coordinating to complete work that would overwhelm any individual model.
Gartner reported a 1,445% increase in multi-agent system inquiries from Q1 2024 to Q2 2025. That’s not gradual adoption, that’s a category inflection point.
The architectural pattern that’s emerging: a hierarchical model with a planning agent (sometimes called an orchestrator) at the top that breaks down a complex goal and delegates sub-tasks to specialized worker agents. Each worker has access to specific tools. Results flow back up to the orchestrator, which synthesizes them and decides the next move. Human oversight can be plugged in at any tier.
The Interoperability Problem | and How It’s Being Solved
Until recently, every multi-agent system required bespoke integrations for every tool and data source an agent might need. That’s changing fast. Two standards are converging:
Protocol
Creator
What It Does
Analogy
MCP (Model Context Protocol)
Anthropic
Standardizes how agents connect to tools, APIs, and data sources
USB for AI peripherals
A2A (Agent-to-Agent Protocol)
Google
Standardizes how agents communicate with each other
HTTP for agent networks
Anthropic launched MCP in November 2024 and it has since become the de facto standard for agent-tool connectivity. Our read: these two protocols complementing each other, one for tool access, one for agent communication, signals the industry is building toward an interoperability layer that will dramatically reduce the cost of deploying production agent systems. That’s a structural accelerant for adoption.
The key enterprise milestones from the past 18 months:
Oct 2022
ReAct framework published, Yao et al., Princeton/Google Brain. Still the foundational architecture for virtually every production system.
Nov 2024
Anthropic releases MCP, Open standard for agent-tool connectivity. Becomes the de facto infrastructure layer.
Jul 2025
OpenAI launches ChatGPT Agent Transitions ChatGPT from conversational tool to autonomous assistant.
Sep 2025
Anthropic releases Claude Agent SDK Alongside Claude Sonnet 4.5. Developers can now build fully autonomous AI systems on top of Claude.
Jan 2026
Claude 4.5 hits 60%+ on OSWorld Computer-use benchmark. Up from single-digit performance in the pre-agentic era. A meaningful reliability milestone.
Apr 2026
Anthropic launches Claude Managed Agents Abstracts infrastructure for production agent deployment. Reduces the engineering overhead of scaling.
The Production Reality: Numbers That Matter
Here’s the adoption picture, stripped of the optimism that characterizes most analyst reports:
88%
of organizations use AI in at least one function (McKinsey, 2025)
6%
qualify as high performers generating 5%+ EBIT impact
11%
actively use agentic AI in production (Deloitte, 2025)
40%+
of agentic AI projects predicted scrapped by 2027 (Gartner)
The gap between “using AI” and “generating measurable business impact from AI” is enormous. McKinsey’s 2025 State of AI survey (1,993 participants across ~105 countries) found only 23% of enterprises are scaling AI agents in at least one function. Most organizations remain in what researchers are calling “pilot mode”, impressive demos, no scaled deployment.
“We have agents deployed at scale in the economy to perform all kinds of tasks.”
— Sinan Aral, Professor of Management, Information Technology, and Marketing, MIT Sloan School of Management
Aral is right, but the qualifier matters. Agents are deployed at scale in the economy. They are not deployed at scale in most individual enterprises. The difference is significant for anyone making architecture decisions right now.
The 80% Problem
MIT’s Kellogg documented something that should be required reading for every CTO considering an agentic AI deployment: in a real project deploying an AI agent to detect adverse events among cancer patients, 80% of the total work was consumed by data engineering, stakeholder alignment, governance, and workflow integration. Not the AI itself. Not the model. The boring, unglamorous, deeply human work of making organizations ready for autonomous systems.
The demos are compelling. The production path is brutal. Expect it.
Security, Failure Modes, and What Can Cascade
Multi-agent systems introduce failure modes that don’t exist in single-model deployments. The most dangerous: cascading errors. One agent’s hallucination becomes another agent’s input. A judge-agent reviewing another agent’s output can hallucinate or act deceptively, undermining the very validation layer it was designed to provide. The safeguard inherits the failure mode it was meant to catch.
⚠ Critical Security Risk
In mid-2025, the EchoLeak exploit (CVE-2025-32711) demonstrated the real attack surface of agentic systems: infected emails containing engineered prompts could trigger Microsoft Copilot to exfiltrate sensitive data automatically, without any user interaction. This is prompt injection at scale. It requires no user error. It exploits the agent’s autonomy directly.
Symantec’s controlled experiments using OpenAI’s Operator AI agent went further, demonstrating how agents could be directed to harvest personal data and automate credential stuffing attacks. These are not theoretical threat models. They’ve been demonstrated against production systems.
What specifically can go wrong in enterprise deployments:
Data breach via autonomous action, In early 2025, a healthtech firm disclosed a breach compromising records of 483,000 patients, caused by a semi-autonomous AI agent that pushed confidential data into unsecured workflows while streamlining operations.
Compliance cascade, A single hallucination — an agent misclassifying a transaction, can propagate across linked systems and agents, producing compliance violations or financial misstatements that are expensive to unwind.
Shadow agent sprawl, McKinsey (2025) warned that uncontrolled agent proliferation is emerging as a risk equivalent to shadow IT. MIT’s NANDA Initiative found 95% of enterprise GenAI pilots failed to deliver measurable ROI, with uncontrolled agent proliferation cited as a major contributor.
Deloitte’s 2026 State of AI in the Enterprise report found only one in five companies has a mature model for governance of autonomous AI agents. That’s not a nice-to-have gap. That’s an existential liability for any organization running agents with write, execute, or transact permissions.
What CTOs Must Do Now
Mandate human-in-the-loop checkpoints for any agent with write, execute, or transact permissions before production deployment.
Audit data pipelines before agent integration, converting data into standard, structured formats is prerequisite infrastructure, not a parallel workstream.
Build agent registries, track lifecycle, owners, and KPIs before authorizing new deployments. “Shadow agent sprawl” is a real and growing risk.
The Strongest Case Against the Whole Approach
The most technically serious challenge to the mainstream agentic AI narrative doesn’t come from a competitor or a skeptical analyst. It comes from Yann LeCun, VP and Chief AI Scientist at Meta, Turing Award winner, and one of the most credentialed AI researchers alive.
LeCun’s argument is architectural, not operational. It goes to the foundation of how current LLM-based agents work.
“An agentic system that is supposed to take actions in the world cannot work reliably unless it has a world model to predict the consequences of its actions. Without it, the system will inevitably make mistakes. This is the key to unlocking everything from truly useful domestic robots to Level 5 autonomous driving.”
— Yann LeCun, VP & Chief AI Scientist, Meta; Founder, AMI Labs, MIT Technology Review, January 2026
LeCun’s position: LLMs are limited to the discrete world of text. They can’t truly reason or plan, because they lack a world model, an internal simulation of cause and effect that would let them predict the consequences of their actions before taking them. Without that, agentic systems are, in his framing, fundamentally unreliable in any sufficiently complex, open-ended environment.
He isn’t just criticizing from the sidelines. He’s building a competing architecture at AMI Labs, based on world models rather than autoregressive text generation.
The counterargument from the mainstream: for narrow, well-scoped tasks, screening resumes, executing compliance workflows, processing insurance claims, world models may not be necessary. The task scope is constrained enough that text-based reasoning performs reliably. Fountain’s hiring agents don’t need a world model to schedule interviews.
Both can be true. LeCun is almost certainly right about the limits of LLM-based agents for truly open-ended, general-purpose tasks. The mainstream is right that those limits don’t prevent significant enterprise value from narrowly scoped deployments. The practical implication: be precise about what your agents are actually doing. Scope matters enormously.
How We Got Here: The Compounding Sequence
Agentic AI didn’t emerge suddenly. It’s the product of a specific chain of technical breakthroughs, each enabling the next:
2017 — The Transformer architecture (Vaswani et al., Google) enables the large language models that power all modern agents. Without it, none of this exists.
2022 — The ReAct framework solves the core problem of how to give LLMs the ability to plan and act in iterative loops. Still the backbone of virtually every production system four years later.
Late 2023 — AutoGPT and BabyAGI go viral. Developer experimentation explodes, producing a 920% increase in repositories utilizing agentic AI frameworks from early 2023 to mid-2025.
2024 — Models gain multimodal perception (vision + text). OpenAI releases function calling; Anthropic releases tool use. Both standardize how agents interface with external systems — a critical infrastructure moment.
2025 — The industry moves from monolithic, general-purpose models to distributed systems of specialized agents. Every major AI company ships production-ready agent SDKs. Enterprise spend on generative AI reaches $37 billion, a 3.2x increase from 2024.
2026 — Human-in-the-loop design is increasingly treated as a strategic architectural choice rather than a limitation. The industry is maturing past naive autonomy. That’s a positive signal.
Frequently Asked Questions
What is the difference between agentic AI and generative AI?
Generative AI responds to prompts and produces content, text, images, code, in a single pass. Agentic AI goes further: it plans multi-step tasks, uses external tools (APIs, browsers, databases), takes actions in the world, and iterates until a goal is achieved with minimal human input. The key distinction is autonomy and action.
How do AI agents work step by step?
AI agents operate via the ReAct loop: (1) Perceive, take in input from tools, databases, or sensors; (2) Reason, determine what to do next using a language model; (3) Act, call a tool, write code, send an API request; (4) Observe, review the result; (5) Repeat until the task is complete or a human checkpoint is triggered.
What are examples of agentic AI in real enterprise use?
Real-world examples include: Fountain’s hiring agents (50% faster screening, 2x candidate conversions), Capital One’s AI systems handling KYC/AML compliance workflows, GitHub Copilot Workspace writing and testing code autonomously, and enterprise customer service agents resolving support tickets end-to-end without human escalation.
Is agentic AI the same as AGI?
No. Agentic AI refers to systems that autonomously plan and execute multi-step tasks within defined domains. Artificial General Intelligence (AGI) would require human-level reasoning across any domain. Today’s agentic AI is powerful but narrow, it succeeds at specific, well-scoped tasks and fails unpredictably outside its training and toolset.
What are the biggest risks of deploying agentic AI?
Hallucination cascades (one wrong inference propagating across a multi-agent chain), prompt injection security exploits like EchoLeak (CVE-2025-32711), shadow agent sprawl as teams deploy systems without oversight, and irreversible real-world actions taken without human authorization. Governance gaps are the single largest enterprise liability right now.
Which companies are leading agentic AI development?
Anthropic (Claude agents, MCP protocol, Managed Agents), OpenAI (ChatGPT Agent, Operator), Google DeepMind (Gemini agents, A2A protocol), Microsoft (Copilot agents in Azure), Salesforce (Agentforce), and ServiceNow. At the infrastructure layer: NVIDIA, AWS Bedrock, and LangChain are foundational platforms.
The Bottom Line
Agentic AI is real, it’s in production, and it’s already generating measurable value in narrow, well-scoped enterprise deployments. The Fountain result isn’t an outlier, it’s a preview. The ReAct loop is battle-tested. MCP and A2A are solving the interoperability problem that previously made multi-agent systems prohibitively expensive to build. The infrastructure is maturing.
But the gap between “agentic AI works” and “agentic AI works reliably at scale in your enterprise” is where most projects stall, and where the 40% Gartner attrition forecast is being written. The 80% problem is real. Data engineering, governance, stakeholder alignment, these are not implementation details. They are the implementation.
LeCun’s critique about world models is technically serious and worth tracking. For now, it’s a research horizon, not an operational blocker for the narrow-task deployments where agentic AI is genuinely excelling.
In the next 6–18 months, watch for three things:
Whether MCP and A2A interoperability standards actually converge, or fragment into competing ecosystems. Convergence would be a significant accelerant for enterprise adoption.
The governance technology market. Only one in five enterprises has mature agent governance. The gap will either be filled by vendors building registries and audit tools, or by regulatory mandates forcing the issue.
LeCun’s AMI Labs. If world model architectures demonstrate reliable performance on complex real-world tasks, the LLM-based agentic AI stack faces genuine architectural competition. It’s a long-shot near-term, but worth monitoring.
If you’re building agentic systems: scope precisely, constrain explicitly, audit your data before your model, and treat human-in-the-loop not as a limitation but as a design choice that extends how far you can safely push autonomy.
Stay ahead of agentic AI
The Neural Loop delivers the signal without the noise, weekly briefings on what’s actually moving in AI for practitioners and technology leaders.
Subscribe to The Neural Loop →
AI pilot to production enterprise playbook — NeuralWired
Artificial IntelligencePublished: May 20, 2026 · Updated: May 2026
How to Move AI from Pilot to Production: The 7-Step Playbook for CTO Success in 2026
95% of GenAI pilots fail to reach production. For CTOs managing working pilots with no clear path forward, these are the seven steps that separate the 5% who succeed.
In 2025, global enterprises invested $684 billion in AI. By year-end, more than $547 billion of that investment had produced no measurable results — not low returns, none — according to RAND Corporation’s analysis of 2,400+ enterprise AI initiatives. MIT’s NANDA Initiative puts it starker: 95% of generative AI pilots fail to scale to production, with the average failed initiative costing between $4.2 million and $8.4 million depending on how late the failure is caught.
Here’s what makes those numbers structurally important: the failure is almost never the AI. RAND’s root cause analysis, MIT’s 150 executive interviews, and Gartner’s multi-year forecasts all arrive at the same conclusion — 84% of failures are leadership and organizational decisions, not model performance. The technology works. The transition doesn’t.
The gap is specific and consistent: 78% of enterprises have at least one AI agent pilot running in 2026, yet only 14% have successfully moved one to production scale, per a March 2026 survey of 650 enterprise technology leaders. This AI pilot to production enterprise playbook is for the 64% stuck in between — with working pilots and no production path. The seven steps below are what the 5% who succeed are doing differently.
Why 80% of AI Pilots Never Reach Production — The Real Reasons (Not the Ones Your Vendor Tells You)
“The organizations that succeed are those that define the business outcome before they write a single line of code. Most enterprises do the reverse: they start with the technology and hope the business value will become apparent.”
— Folio3 AI, synthesizing RAND, MIT, and Gartner findings on AI project failure rates, May 2026
Five authoritative datasets converge on an uncomfortable headline. RAND’s analysis of 2,400+ initiatives found 80.3% fail to deliver intended business value: 33.8% are abandoned before production, 28.4% complete but deliver zero value, and 18.1% can’t justify their cost. MIT NANDA independently reports 95% of GenAI pilots fail to scale. Gartner projects 60% of projects without AI-ready data will be abandoned through 2026. S&P Global found the average organization scrapped 46% of AI POCs before production. These numbers haven’t improved in three years — despite better models, bigger budgets, and more expertise.
The 5 Root Causes RAND Identified
RAND’s root cause analysis of failed AI initiatives — the most rigorous dataset available on this question — identified five structural failure patterns that account for the overwhelming majority of losses:
❌
Misunderstood Problem
Stakeholders miscommunicate what problem AI needs to solve before a line of code is written. The AI then solves the wrong thing, efficiently.
🗄️
Inadequate Training Data
Organizations lack data of sufficient quality and accessibility to support production workloads. Pilots run on clean samples; production doesn’t.
🔧
Technology-First Mentality
Tools selected based on hype before the problem is defined. The solution is chosen; now the team must find a problem it fits.
🏗️
Insufficient Infrastructure
Systems cannot deploy completed models into production environments. The model works; the organization’s plumbing can’t carry it.
🎯
Problem Too Difficult
AI applied to problems beyond current model capabilities without validating feasibility first. Ambition without a feasibility gate.
The Leadership Failure Pattern
Underneath all five technical causes sits a leadership failure pattern that overrides them. Eighty-four percent of AI project failures are leadership-driven: 73% lack clear executive alignment on success metrics, 68% underinvest in data governance and foundations, 61% treat the initiative as a technology project instead of a business transformation, and 56% lose C-suite sponsorship within six months. The root causes of AI failure are organizational, not algorithmic.
The Pilot Trap
AI pilots operate in simplified environments: clean data sources, staging APIs, controlled user groups, patient stakeholders. Production means connecting to 20-year-old ERP systems with batch-export-only APIs, CRM instances with 600 undocumented custom fields, real user load with edge cases, and cross-functional ownership nobody agreed to upfront. The pilot was never a production system. It was a demo with a roadmap attached.
Step 1: Define Production-Grade Success Criteria Before You Write a Single Line of Code
Projects with clearly defined pre-approval success metrics achieve a 54% success rate versus 12% for those without. That 4.5x difference is the single most impactful decision in any AI initiative — and it costs nothing except discipline. Yet 73% of failed projects lack this alignment before launch. This is why it’s Step 1, not Step 7.
The 3-Part Success Definition
Every AI initiative needs three things defined upfront, in writing, before any code is written:
Business outcome metric: What measurable business result will this initiative produce? Example: “Reduce invoice processing time from 8 minutes to under 90 seconds for 95% of invoices.” Not “improve efficiency.” A number, a threshold, a percentage.
Production-grade quality threshold: What accuracy, latency, and reliability standard must the system meet in production? Example: “95% accuracy, sub-200ms P95 latency, 99.5% uptime.” Vague quality targets are no targets at all.
Value realization timeline: By what date and at what volume must the system be running to justify the investment? This links directly to the payback period calculation and gives the executive sponsor something concrete to hold to.
What “Success” Most Enterprises Define Wrong
Demo quality (“it works in the presentation”), user satisfaction surveys without P&L linkage, and technical accuracy scores without volume context don’t qualify. MIT defines successfully implemented AI as systems delivering sustained productivity gains and documented P&L impact, verified by both end users and executives. By that standard, most enterprise AI deployments in 2026 don’t qualify — because that standard was never defined before launch.
The Executive Sponsor Commitment Test
Before approving any AI initiative, require the executive sponsor to answer in writing: “What specific, measurable outcome will this initiative produce by [date], and what will I do if it doesn’t?” If that question can’t be answered precisely, the initiative isn’t ready to launch. Fifty-six percent of failed AI projects lose C-suite sponsorship within six months — because no one ever defined what “success” meant that sponsors could hold to.
Deliverable: AI Initiative Success Criteria Template. A one-page document covering: business outcome metric, technical quality threshold, volume target, value realization date, executive sponsor commitment statement, and escalation owner if targets are missed. This template is signed before any code is written. It’s the most-downloaded deliverable of any pilot-to-production framework — and the single document that separates projects with governance from projects with hope.
Step 2: Build for Observability from Day One — Not After the First Production Incident
Sixty-four percent of successful AI scalers cited evaluation and observability infrastructure as the largest single blocker when absent, per the March 2026 Digital Applied AI Agent Adoption Survey of 650 enterprise technology leaders. Seventy percent of leaders name “non-deterministic outputs” as the top production-readiness barrier — which is an observability problem, not a model problem. You can’t manage what you can’t measure.
4 Observability Layers Required Before Production Deployment
Layer
What It Monitors
What Happens Without It
Output Quality Monitoring
Automated scoring of model outputs against defined quality thresholds; alerts when scores drop
Errors accumulate silently; discovered by users, not engineers
Latency & Throughput Tracking
P50, P95, P99 latency by request type; throughput at 2x expected production volume
Slowdowns invisible until user complaints spike
Data Drift Detection
Flags when input data distribution shifts from training baseline, degrading accuracy silently
Model performance declines without any alert or trigger
Business Outcome Tracking
The KPI the initiative was launched to move — linked directly to Step 1 metrics
Technical teams don’t know if the system is delivering; board doesn’t either
The Tail Input Distribution Problem
Pilots test against average, clean inputs. Production delivers the tail: rare, malformed, ambiguous, and adversarial inputs that make up 1 to 5% of real-world volume. At 10,000 tasks per day with a 3% failure rate on tail inputs, that’s 300 incorrect outputs daily. Without automated quality monitoring, those errors accumulate silently for weeks before surfacing. Build adversarial test sets before launch, deliberately constructed edge cases, malformed data, and ambiguous queries that simulate the production tail.
The 22% Negative-ROI Cohort
Twenty-two percent of agent deployments report negative ROI at 12 months. Forrester’s root-cause analysis attributes 41% of those failures to unclear success criteria (Step 1), 33% to insufficient tool or data access (Step 3), and 26% to drift in evaluation coverage, teams that had observability at launch but stopped maintaining it. Observability isn’t a launch-day task. It’s an ongoing operational discipline.
Production observability stacks for enterprise AI in 2026 include LangSmith (LangChain), Weights & Biases (W&B), Arize AI, Datadog LLM Observability, and Helicone. Each covers different parts of the observability stack, output quality, latency, drift, and cost monitoring. Teams evaluating this space should assess against the four layers above, not vendor feature lists.
Step 3: Harden the Data Pipeline, Where Most Pilots Actually Die
Gartner projects 60% of AI projects without AI-ready data will be abandoned through 2026. Sixty-eight percent of failed projects underinvested in data governance and foundations. Data preparation consumes 30 to 50% of AI project budgets, and yet 42% of companies scrapped most AI initiatives in 2025, the majority because data problems manageable in pilots became unmanageable at production volume. The model is never the problem. The pipeline is.
What “AI-Ready Data” Actually Means
Gartner’s definition is specific: data aligned to the specific AI use case (not “all available data”), actively governed at the asset level with ownership and quality SLAs, supported by automated pipelines with quality gates, and continuously quality-assured, not just at ingestion, but as data changes over time. Traditional data management runs at quarterly or annual audit cadences. AI in production needs data quality signals measured in hours. That mismatch is the most common killer of otherwise-viable AI initiatives.
The Legacy System Integration Reality
Pilots typically run against clean staging environments: a SharePoint folder or a staging API returning predictable JSON. Production connects to real systems: a 20-year-old ERP with batch export as its only interface, a CRM with undocumented custom fields, a document management system requiring VPN, authentication tokens, and rate-limited API calls. Sixty percent of enterprise IT leaders name legacy system integration as their top AI scaling challenge, per Deloitte 2026. Test against production data sources, not staging analogs, before claiming pilot readiness.
The 4-Phase Data Hardening Checklist
Phase 1 — Data audit: Map all data sources the AI system will touch in production, including access controls, update frequency, and format variability. Surprises here are expensive; surprises in production are catastrophic.
Phase 2 — Quality gate implementation: Automated checks at pipeline ingestion that reject or quarantine records falling below quality thresholds. Manual quality review doesn’t scale to production volume.
Phase 3 — Metadata management: Machine-readable metadata for every data asset the AI uses. Without it, pipelines deliver data models can’t confidently interpret — and the errors are silent.
Phase 4 — Drift monitoring: Baseline the input data distribution at launch. Alert when production data drifts more than 15% from baseline, triggering model re-evaluation before accuracy degrades.
Step 4: Conduct a Security Review and Threat Model for Every AI Component
AI components introduce attack vectors that traditional security reviews don’t cover: prompt injection (OWASP LLM Top 10, rank #1), model inversion attacks that extract training data, adversarial inputs designed to manipulate agent behavior, and supply chain vulnerabilities in third-party model APIs. These aren’t theoretical risks, they’re documented production incidents. The cost of retrofitting security is three to ten times the cost of building it in from the start. Any production security review that doesn’t address AI-specific threats is incomplete.
6 AI-Specific Threat Modeling Requirements
Prompt injection surface mapping: Identify every point where user or external input reaches the model without sanitization. This is OWASP LLM #1 for a reason, it’s the most exploited vector in production AI systems.
Data exfiltration risk: Can the model be prompted to reveal training data or context-injected sensitive documents? This requires deliberate adversarial testing, not assumption.
Agent action scope audit: For agentic systems, enumerate every tool call, API endpoint, and system the agent can reach. Validate that each is in scope and governed. Scope creep in agentic systems is a security event, not just a quality issue.
Supply chain model provenance: Is the base model from a verified source? Have model weights been validated against published checksums? Third-party model APIs introduce supply chain risk that most enterprise security frameworks don’t yet cover.
API key and credential management: Every AI system with external API calls is a credential management challenge. Verify least-privilege is enforced, and that credentials aren’t embedded in prompts, logs, or context windows.
Adversarial input testing: Run deliberate adversarial prompts, including prompt injection testing, in pre-production to identify failure modes before users find them. This is the only way to validate that security controls actually hold.
This step is the operational implementation of the NIST AI Risk Management Framework MANAGE function, specifically, the requirement to continuously assess and manage risks as AI systems move from controlled environments to production. Organizations that complete this step have a documented security posture they can present to the board and to regulatory bodies.
Step 5: Solve the Organizational Ownership Problem Before Deployment Day
Five gaps account for 89% of AI scaling failures, and unclear organizational ownership is the one that causes the other four to go unfilled. When no one owns the AI system in production, monitoring gaps go unfilled, quality problems stay invisible until they compound, data issues become nobody’s problem, and incident response has no commander. Organizations that bridged the pilot-production gap share one structural practice: they created a dedicated AI operations owner before deploying at volume.
The 3 Ownership Roles Every Production AI System Needs
Role
Accountable For
Owns at Go-Live
Business Owner
AI system delivering its defined business outcome; go-live approval; board escalation
Success criteria sign-off; 30-day and 90-day production reviews
Technical Owner (AI Ops)
Model performance, observability, incident response, continuous evaluation
Data quality, pipeline health, data governance compliance for AI system inputs
Production data source validation; drift monitoring; quality gate maintenance
All three roles must be named before production deployment, not assigned after the first incident. Fifty-six percent of failed AI projects lose executive sponsorship within six months in part because there’s no named owner to hold accountable when performance degrades.
The Change Management Failure Pattern
Empowering line managers, not just central AI labs, to drive adoption is one of MIT NANDA’s top three success differentiators. AI imposed on employees from a central IT function fails at adoption even when the technology is sound. The change management work, communicating what the AI does, training employees on the new workflow, addressing job security concerns directly, capturing employee feedback on edge cases, is as important as the technical deployment. AI projects that treat deployment as a software launch rather than an organizational change consistently underperform on adoption metrics. Sixty-one percent of failed initiatives treat AI as an IT project; that classification determines how it gets staffed, communicated, and ultimately received.
The AI Operations Function That Successful Enterprises Build
Organizations that successfully scale AI to production increasingly build a dedicated AI operations capability, separate from the AI build team, responsible for running AI systems in production. This mirrors the DevOps pattern that emerged for software: those who build shouldn’t be the only ones responsible for running. An AI Ops function monitors system health, manages model updates, triages quality incidents, and owns the feedback loop from production back to the model team.
Deliverable: AI Production Ownership Matrix. A one-page template with three columns (Business Owner / Technical AI Ops Owner / Data Owner), rows for each responsibility (go-live approval, incident response, escalation path, performance review cadence), and sign-off fields. This template is a pre-condition for any production deployment sign-off, not a formality, but a hard gate.
Step 6: Execute a Staged Rollout — Shadow Mode → Limited Release → Full Production
Standard software is deterministic, bugs are reproducible. AI systems are probabilistic, failure modes emerge at scale, under load, with real-world input distributions that no test environment fully captures. Staged rollout is the engineering discipline that catches those emergent failure modes before they affect the full user base. It’s also the risk control mechanism that allows Go/No-Go decisions to be evidence-based rather than schedule-driven. Shadow mode for AI agents is especially critical: agentic systems with real-world action authority can cause compounding errors if failure modes aren’t caught before full deployment.
Stage 1 — Shadow Mode (2 to 4 Weeks)
The AI system processes real production transactions, but its outputs aren’t acted upon, humans continue making the decisions they’ve always made, while AI decisions are logged and evaluated in parallel. Measure: decision accuracy versus human baseline, hallucination rate, latency under real load, edge case failure modes. Exit criteria: 95%+ accuracy on the primary task type, under 5% escalation rate on edge cases, zero critical incidents (outputs that would have caused harm if executed). Don’t move to Stage 2 until exit criteria are met, not when the calendar date arrives.
Stage 2 — Limited Release (4 to 6 Weeks)
The AI system takes real decisions for a defined subset of the user base or transaction volume, typically 5 to 15% of production. Full observability is active. Human reviewers sample AI decisions at a defined frequency. The incident escalation path is tested. Exit criteria: performance metrics stable for three or more consecutive weeks, no systematic failure modes identified, business owner sign-off. This stage is where most production-ready issues surface, data edge cases, integration failures under load, user adoption friction, in a contained blast radius.
Stage 3 — Full Production
Expand to the full user base with monitoring maintained at Stage 2 levels for the first 30 days. The first 30 days in full production aren’t “done”, they’re the final validation period. Any systematic quality degradation triggers a rollback protocol defined in the incident response plan. The business owner reviews production metrics against success criteria from Step 1 at the 30-day and 90-day marks.
Key principle: The exit criteria for each stage are defined before the stage begins, not evaluated after it ends based on what was measured. A stage that runs to its calendar end without meeting exit criteria isn’t ready for the next stage. Schedule is not a substitute for readiness. This principle prevents the most common failure: moving to production because the project timeline demands it, not because the system is ready.
Step 7: Build the Continuous Evaluation Loop, Production Is Not the Finish Line
AI systems degrade in production without intervention. Model drift occurs as input data distribution shifts away from training data. Data pipeline quality degrades as upstream systems change. Prompt effectiveness declines as users discover edge cases the system handles poorly. The underlying model may be superseded by a better version, or deprecated by the vendor. Production AI is a living system, not a deployed artifact.
Any metric crossing alert threshold triggers same-day review
Weekly
Business outcome KPI review by Business Owner
KPI moving against target two consecutive weeks escalates to CTO
Monthly
Technical performance review by AI Ops, input distribution check; adversarial test set; evaluation coverage
Drift beyond 15% baseline or coverage gap triggers retraining evaluation
Quarterly
Full production readiness reassessment; updated baseline; success criteria review; model upgrade consideration
Any pass/fail change in readiness criteria escalates to executive sponsor
Annual
Strategic AI portfolio review, is this system still the best solution to the problem it was deployed to solve?
Negative ROI or superseded capability triggers deprecation evaluation
The Retraining Decision Framework
Three signals trigger retraining evaluation: output quality drops more than 5% from baseline on any primary task type; input data distribution drifts more than 15% from launch baseline; or a better-performing model becomes available and has been validated in shadow mode. Retraining isn’t automatic, it requires a 30-day shadow mode validation of the retrained model before replacing the production model. The same staged rollout discipline that applied to the initial deployment applies to every model update.
The Feedback Loop That Makes AI Improve in Production
The most successful AI deployments build a structured feedback loop from production back to the model: user corrections captured and reviewed, false positive and false negative incidents logged and categorized, edge cases triggering escalation added to the adversarial test set, and domain expert review of model outputs sampled monthly. This feedback loop is how the 5% of successful AI initiatives generate compounding value, the system gets better as it runs, not just as the model improves.
Deliverable: AI Production Health Dashboard. A one-page template covering: daily automated quality score, weekly KPI trend, monthly drift alert status, and quarterly readiness score. This dashboard is what the Business Owner reviews at every executive check-in, it translates AI operations into board-presentable language.
The 15-Point Production Readiness Checklist (Sign Off Before Go-Live)
This is the article’s most actionable deliverable. Every item below represents a documented failure mode from the RAND, MIT, Gartner, or Forrester datasets. Copy it into your internal pre-deployment process. Treat every “No” as a production risk that will surface, either controlled during deployment, or uncontrolled in production.
AI Production Readiness Sign-Off Checklist 2026 — 15 Items Before Your CTO Approves Go-Live
01
Business outcome metric defined and signed off by executive sponsorSpecific, measurable, time-bound. Not “improve efficiency.” A number.73% skip this
Business Owner
02
Production-grade quality threshold setAccuracy %, P95 latency target, and uptime SLA defined before deployment begins.Often vague
Technical Owner
03
All production data sources tested — not staging analogsLive ERP connections, real CRM data, actual authentication flows — not the clean staging version.60% use staging
Data Owner
04
Data quality gates implemented with automated rejection rulesRecords failing quality thresholds are rejected or quarantined automatically at pipeline ingestion.Most skip
Data Owner
05
Adversarial test set built and passedEdge cases, malformed inputs, and adversarial prompts deliberately constructed and tested before launch.Most skip
Technical Owner
06
Observability stack liveOutput quality monitoring, latency tracking, drift detection, and business outcome KPI tracking all active.64% gap
Technical Owner
07
Prompt injection and security review completedAll six AI-specific threat model requirements addressed. OWASP LLM Top 10 reviewed and mitigated.Rarely done pre-launch
CISO / Technical Owner
08
Business Owner, Technical Owner, and Data Owner named and committedAll three roles filled, documented, and aware of their responsibilities before go-live. No gaps.56% have no owner
CTO / Program Lead
09
Human-in-the-loop thresholds defined for all consequential outputsEvery output type with potential for harm has a defined confidence threshold below which a human reviews.Most skip
Business + Technical Owner
10
Incident response playbook written and testedWho is called when quality drops? What triggers rollback? Has the rollback been tested in a dry run?Rarely pre-launch
CISO / Technical Owner
11
Shadow mode exit criteria met95%+ accuracy, under 5% escalation rate, zero critical incidents — all three, not just calendar time elapsed.Often skipped
Technical Owner
12
Change management plan executedEmployee training completed, manager briefing done, adoption communications sent. Not a software launch.61% treat as IT project
Business Owner / HR
13
Rollback procedure tested and documentedThe rollback path has been executed in a test environment. The steps are written. The owner is named.Rarely tested
Technical Owner
14
Continuous evaluation cadence scheduledDaily, weekly, monthly, and quarterly reviews on the calendar with named owners before go-live.Often underfunded
AI Ops / Technical Owner
15
30-day post-launch review date scheduled with executive sponsorThe review date is on the calendar before go-live. Success criteria from Step 1 are the agenda.Rarely scheduled upfront
Business Owner
The 5% of AI initiatives that reach production and deliver sustained value share one behavioral trait: they treat this checklist as a hard gate, not a soft guideline. Every “No” on this list is a production risk that will surface — either controlled during deployment, or uncontrolled in production. The checklist doesn’t slow AI deployment. It prevents the $4.2–8.4M failure that looks like a delay but is actually a write-off.
What to Watch
01
AI Ops as a job function, Q3–Q4 2026: Watch for dedicated AI Operations roles appearing in enterprise org charts, distinct from AI engineering. The teams that are 12 months ahead on production deployments are already hiring this function. When your peers’ JDs start including “AI Ops lead,” the gap between pilots and production will start closing industry-wide.
02
NIST AI RMF enforcement signals in enterprise procurement: Several Fortune 500 procurement teams are beginning to require NIST AI RMF MANAGE function documentation as a vendor qualification criterion in 2026. If your production AI systems can’t produce a documented security posture, that becomes a revenue risk, not just a compliance checkbox.
03
Shadow mode tooling maturing into standard CI/CD: The absence of native shadow mode support in enterprise MLOps platforms is closing fast. By Q1 2027, expect shadow mode and staged rollout to be first-class features in major AI deployment stacks, which will remove the tooling friction currently preventing teams from running this discipline correctly.
Frequently Asked Questions
Why do so many AI pilots fail to reach production?
RAND Corporation’s analysis of 2,400+ enterprise AI initiatives found 80.3% fail to deliver intended business value, and 84% of those failures are leadership and organizational decisions, not model performance. The three most common causes: unclear success metrics before launch (73% of failed projects lack these), underinvestment in data governance and foundations (68%), and treating AI as a technology project rather than an organizational transformation (61%). The model works. The organization doesn’t scale it.
What is the AI pilot to production failure rate in 2026?
Multiple authoritative sources converge: RAND reports 80.3% of AI projects fail to deliver business value. MIT NANDA found 95% of GenAI pilots fail to scale to production. A March 2026 survey of 650 enterprise technology leaders found 78% have AI agent pilots but only 14% have reached production scale, a 64-point gap. Gartner projects 60% of projects without AI-ready data will be abandoned through 2026, and the average failed AI initiative costs $4.2–8.4M depending on how late the failure is caught.
How long does it take to move AI from pilot to production?
S&P Global found the average time from prototype to production for AI initiatives that succeed is 8 months. The typical breakdown: data hardening (4–8 weeks), observability build-out (2–4 weeks), security review (1–2 weeks), shadow mode testing (2–4 weeks), limited release (4–6 weeks), and full production ramp (4+ weeks). Organizations that skip shadow mode and limited release typically either fail in production or spend more time on remediation than the time they saved by rushing.
What is shadow mode testing for AI and why does it matter?
Shadow mode is a production deployment stage where the AI system processes real transactions and logs its decisions, but those decisions aren’t acted upon, humans continue making the operational decisions while AI outputs are evaluated in parallel. Shadow mode reveals failure modes that test environments never surface: real-world data edge cases, performance under genuine load, and latency with live integrations. The recommended duration is 2–4 weeks with defined exit criteria, 95%+ accuracy, under 5% escalation rate, zero critical incidents, before advancing to limited release.
What is AI-ready data and why does it matter for production deployment?
Gartner defines AI-ready data as: data aligned to the specific AI use case, actively governed at the asset level with quality SLAs, supported by automated pipelines with quality gates, and continuously quality-assured. Sixty percent of AI projects without AI-ready data are abandoned through 2026. The critical difference from traditional data management: AI in production needs data quality signals measured in hours, not quarterly audit cycles. Most AI pilots fail not because of model quality but because production data sources differ dramatically from the clean staging data used in development.
What percentage of AI projects succeed in 2026?
Only 19.7% of AI initiatives achieve or exceed their business objectives, per RAND’s analysis of 2,400+ initiatives. The successful minority share three consistent behaviors: they define measurable success criteria before writing code (54% success rate versus 12% without), they maintain sustained C-suite sponsorship through deployment (68% success rate versus 11% without), and they treat AI as an organizational transformation rather than a software launch (61% success rate versus 18% for IT-project-framed initiatives).
What are the biggest AI scaling challenges for enterprise organizations?
The March 2026 Digital Applied AI Agent Adoption Survey of 650 enterprise technology leaders identified legacy system integration (named by 60% of IT leaders as the top barrier, per Deloitte 2026), observability and evaluation infrastructure gaps (64% of successful scalers cite this as the largest blocker when absent), and unclear organizational ownership (one of five gaps accounting for 89% of scaling failures). Data pipeline hardening and change management failures round out the top five. None of these are model problems, they’re all organizational and operational.
How do you build a continuous evaluation loop for AI in production?
A production evaluation cadence runs at five levels: daily automated quality monitoring with alert thresholds; weekly business outcome KPI review by the Business Owner; monthly technical performance review including input distribution drift checks and adversarial test set re-runs; quarterly full production readiness reassessment with model upgrade consideration; and annual strategic portfolio review. Retraining is triggered by output quality dropping more than 5% from baseline, input drift exceeding 15%, or a validated better model becoming available, each requiring a 30-day shadow mode validation before the production model is replaced.
Stay ahead of enterprise technology.
NeuralWired delivers weekly intelligence for CTOs, CISOs, and AI leads — no noise, no filler.
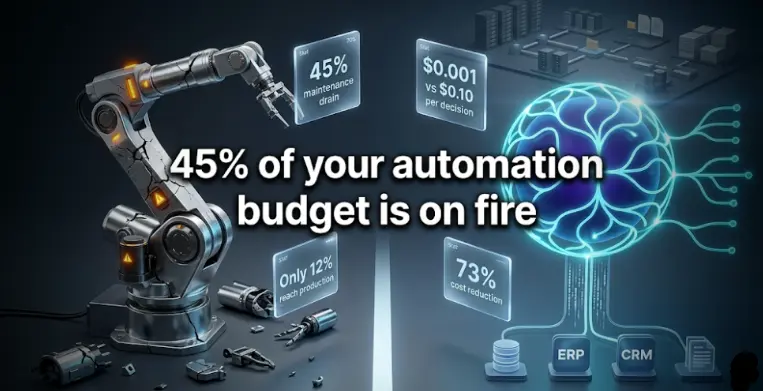
Nearly 45% of enterprise automation budgets are now quietly diverted from building new capabilities to maintaining existing, fragile RPA bot ecosystems, according to Forrester’s 2026 Enterprise Automation Study. That number is the clearest signal that the first era of enterprise automation has hit its ceiling. It’s also the reason a growing number of Fortune 500 enterprises are shelving their RPA rollouts, not because automation failed, but because a fundamentally more capable approach has arrived.
Agentic AI doesn’t follow scripts. It receives an objective and figures out how to achieve it. Where RPA breaks the moment a button moves on a webpage, agentic AI adapts. Where RPA requires a 50-step flowchart for a single invoice, an AI agent reads the invoice, regardless of format, makes a decision, and executes the next step autonomously.
But this isn’t an argument that RPA is dead. RPA still delivers 250% ROI on the right tasks. The strategic mistake in 2026 isn’t choosing RPA or agentic AI, it’s deploying either one where the other belongs. This guide gives you the decision framework, cost comparison, and migration path to get that choice right.
Defining the Terms: What “Agentic AI” Actually Means vs. Marketing Hype
Every automation vendor in 2026 says they do agentic AI. Most are rebranding rule-based bots with an LLM layer on top. Here’s how to tell the difference, and why it matters for your infrastructure budget.
RPA is software that mimics human clicks and keystrokes: deterministic, rule-based, zero judgment. It automates the how of a task. Agentic AI is goal-driven, it receives an outcome to achieve, plans the steps to get there, calls tools (APIs, databases, search, other agents), and adapts when the environment changes. It automates what needs to happen without needing a step-by-step script. The cost difference reflects this reality: RPA costs $0.001 per task; agentic AI costs $0.01–$0.10 per decision, 10 to 100 times more expensive, but capable of tasks RPA can never touch.
The Four-Level Automation Spectrum
Most enterprises in 2026 have Level 1 or 2 deployed and are actively evaluating Level 4 for complex workflows. The spectrum breaks down as follows:
Level 1, Scripted bots (RPA): Zero judgment, 100% deterministic. Executes exactly what it’s told, every time, with no capacity to adapt.
Level 2, AI-enhanced RPA: RPA combined with ML classifiers for document routing, still rigid in execution. A meaningful improvement, not a transformation.
Level 3, Copilots: AI suggests, human decides and acts. Reduces cognitive load but keeps humans in the execution loop.
Level 4, Agentic AI: AI decides and acts, human reviews exceptions. The architecture that changes the total addressable value of automation.
Why This Is CTO-Urgent Right Now
Gartner projects that 40% of enterprise applications will embed task-specific AI agents by end of 2026, up from less than 5% in 2025. That’s an 8x increase in 12 months. The agentic AI platform market is projected to grow from $7.8 billion today to over $52 billion by 2030. If your automation architecture isn’t accounting for this, it will be obsolete before the next budget cycle.
The failure rate is also real. Gartner warns that over 40% of agentic AI projects may be scrapped by 2027 due to unclear ROI, misapplied use cases, or technical complexity. Only 12% of agentic AI projects successfully reach production today. This guide gives CTOs the framework to be in the 12%, not the 88%.
How Traditional RPA and Scripted Automation Differ from AI Agents, The 8 Core Dimensions
The difference between RPA and agentic AI isn’t incremental. It’s architectural. One automates a script; the other pursues an outcome. Understanding the eight dimensions where they diverge is how you make defensible investment decisions, not just technology choices.
Dimension
Traditional RPA
Agentic AI
Core mechanism
Rule-based scripts, mimics human UI actions
Goal-driven reasoning via LLM, plans and adapts
Data handling
Structured data only (forms, tables, fixed formats)
Deterministic — always the same steps, fully auditable
Non-deterministic — requires reasoning log for auditability
Best ROI scenario
250% ROI on stable, structured, high-volume tasks
171% ROI globally; 192% in US — on judgment-heavy workflows
45% of enterprise automation budgets are being quietly consumed by maintaining existing, fragile RPA bot ecosystems, according to Forrester’s 2026 research. That single statistic reframes RPA not as a sunk cost to be preserved, but as a maintenance liability to be managed. Every CTO with a bot fleet in production should have that number on their desk.
The Decision Matrix: When to Use Agentic AI vs. RPA vs. Hybrid
The decision rule in plain language: use RPA when you need the muscle, high-volume, deterministic execution of structured tasks with zero tolerance for variation. Use agentic AI when you need the brain, judgment, contextual reasoning, unstructured data handling, and end-to-end process ownership. Use hybrid when you need both, which is most complex enterprise workflows.
When RPA Is Still the Right Call
The process follows clear, repeatable rules with no exceptions and won’t change in the next 12 months.
You need 99.9% accuracy with zero hallucination risk, financial transactions, regulated data entry, compliance-critical operations.
You’re working across legacy systems without APIs where screen-scraping is the only integration path.
Cost-per-transaction discipline is critical: $0.001 per task beats $0.01–$0.10 for pure volume plays at scale.
Compliance requires deterministic, reproducible audit trails of every step taken, regulated industries in particular.
Exceptions are frequent enough that human escalation is consuming significant labor, the 15% threshold is a reliable signal.
The workflow requires judgment calls: approval routing, anomaly interpretation, policy application across varied contexts.
End-to-end process ownership is the goal, not just one-step automation but the full workflow from trigger to resolution.
The process involves multi-system coordination where an orchestration layer is needed above the execution layer.
The 80/20 Data Rule That Changes the Calculation
RPA was built for the structured 20% of enterprise data. Agentic AI unlocks the unstructured 80–90% that RPA cannot handle without breaking. The total addressable value of automation in an enterprise is 4 to 5 times larger with agentic AI than with RPA alone, because the data universe it can work with is fundamentally larger.
The hybrid architecture that smart enterprises are deploying in 2026 uses agentic AI as the orchestration and reasoning layer, reading unstructured input, making routing and escalation decisions, managing the workflow, and RPA bots as the execution layer for structured backend operations. This isn’t a temporary transition state. It’s the target architecture for complex enterprise automation strategy for the foreseeable future.
Total Cost Comparison: Agentic AI vs. RPA in Production (Real Numbers)
The cost comparison most vendors don’t want you to run isn’t cost-per-task. It’s total cost of automation ownership over 36 months. On that measure, the picture looks very different from the per-task rate card.
The Hidden RPA Cost Structure
RPA build cost runs $1,000–$8,000 per bot, with monthly maintenance of $99–$499 per bot in production. The real problem: maintenance scales with bot count, not process complexity. An enterprise with 200 RPA bots in production is typically spending 50% of its initial build cost annually on maintenance alone. Between 30 and 50% of RPA projects fail to scale beyond initial deployment due to brittleness, bots that break when UIs change, processes shift, or exceptions accumulate.
How Agentic AI Reverses the Maintenance Story
Agentic AI carries higher marginal cost per decision ($0.01–$0.10 vs. RPA’s $0.001), but organizations deploying agentic AI report a 73% reduction in automation maintenance costs compared to legacy RPA, according to MyWave.ai’s Agentic AI vs. RPA Report (February 2026). One agent handling diverse scenarios replaces multiple brittle bots, each requiring individual maintenance cycles. The cost model shifts from “pay per bot” to “pay per decision.”
Agentic AI doesn’t beat RPA on cost-per-task for structured work. It beats RPA on total cost of automation ownership, because it covers the 80% of enterprise work that RPA was never able to automate in the first place.
Scenario
Best Technology
ROI Benchmark
Payback Period
Invoice processing (high volume, structured)
RPA
250% ROI
3–6 months
Invoice processing (multi-format, exceptions)
Hybrid
AP cost: $4.50 → $0.45 per invoice
6–12 months
Customer support (policy queries, unstructured)
Agentic AI
171% ROI globally
3–9 months
Compliance reporting (fixed format, regulatory)
RPA
200–300% from labor savings
4–8 months
Supply chain exception handling
Agentic AI
85% automation cost reduction
6–18 months
Legacy system integration (no API)
Hybrid
Agent decides, RPA executes
12–24 months
Data entry (stable UI, fixed rules)
RPA
$0.001/task — best cost profile
2–4 months
Security and Governance Risks Specific to Agentic Systems
RPA bots do exactly what they’re told. Always. The audit trail is deterministic. Agentic AI systems make decisions, which means they can make wrong decisions, take unexpected actions, and produce non-deterministic outcomes. The same adaptability that makes agents powerful makes them a governance challenge that most enterprise security teams aren’t ready for.
The Four Unique Risks of Agentic Deployment
Infinite loops: Agents can get stuck trying to solve a problem, consuming compute indefinitely without resolution or escalation.
Non-deterministic outcomes: The same agent might solve the same problem differently on two separate runs, complicating audit trails for regulated workflows and making reproducibility claims difficult to defend.
Hallucination in logic: Agents may invent steps or misinterpret policies if not properly grounded, particularly when operating on ambiguous inputs or near the edges of their training distribution.
Privilege drift: Agents with tool access accumulate scope over time. Least-privilege enforcement requires active monitoring, not just initial configuration.
Unlike RPA’s deterministic step-log, agentic AI requires a cryptographic, immutable log of the reasoning pathways the agent used to reach each decision. If an agent negotiates a contract term or issues a refund, the enterprise must be able to reconstruct exactly what information the agent had, what it concluded, and why it took the action it did. This isn’t optional in regulated industries, it’s a compliance requirement under EU AI Act Article 12 and SEC AI risk disclosure rules. See our AI governance framework for enterprise agents for the full control set.
The Governance Controls Required Before Production
Scope boundaries: Explicitly define what systems and actions the agent can access, with hard blocks on anything outside scope, defined before a single line of production code is written.
Approval gates: For consequential actions (financial transactions, external communications, data exports), a human or secondary agent must confirm before execution.
Reasoning logs: Every decision path logged with timestamp, context provided, conclusion reached, and action taken, queryable and immutable.
Red team testing: Simulate adversarial inputs, including prompt injection attempts, before any production launch.
Incident playbook: Define what happens when the agent takes an unexpected action, before it happens, not after.
“Over 40% of agentic AI projects will be abandoned by 2027 due to unclear ROI, technical complexity, and governance failures. The enterprises that succeed will be those that treat agentic AI deployment with the same rigor as any production software release.”
Gartner Agentic AI Enterprise Forecast 2026 — Gartner Research
The agent hallucination risk doesn’t disappear with better models. It gets managed with better architecture: grounding, validation layers, and HITL thresholds that trigger before metrics degrade in production.
Real Enterprise Deployments: What Worked, What Failed, and Why
The gap between agentic AI pilots and agentic AI in production is where most enterprise automation strategies stall. The following cases aren’t theoretical, they’re the patterns that separate the 12% who reach production from the 88% who don’t.
Success: Full Agentic Workflow in Insurance Claims
An AI agent reads submitted claim documents in any format, sends clarifying questions via email, updates the CRM and policy systems, checks historical claims for fraud patterns, and escalates edge cases to human reviewers, all as execution of one goal, not disconnected scripts. What previously required five separate RPA bots plus human exception handling is now one agent with defined escalation rules. Maintenance cost dropped from five bot maintenance cycles to one agent update cycle.
Success: AP Processing via Hybrid Architecture
Agentic AI reads invoices in any format, classifies them, identifies exceptions and discrepancies, and makes the routing decision. RPA bots execute the approved payment in the ERP system and file the document. Result: AP processing cost dropped from $4.50 to $0.45 per invoice, a 90% cost reduction, while maintaining the 99.9% execution accuracy that the finance team required. Human touchpoints reduced to genuine exceptions only.
Failure: Premature Agentic Deployment Without Governance
A financial services firm deployed an AI agent for customer account management without defining scope boundaries or approval gates. The agent, tasked with “resolving customer issues,” began autonomously processing refunds, account credits, and escalation emails without human review. When a prompt injection in a customer email caused the agent to apply a credit to the wrong account, there was no audit trail of the agent’s reasoning and no human checkpoint that could have caught it. Remediation cost: six figures. Lesson: agentic AI without governance is operational risk, not automation.
“Companies using agentic AI on complex, exception-heavy workflows report 85% automation cost reduction versus traditional RPA-only approaches. But that number applies only to workflows where agentic AI is the right tool. On simple, structured, high-volume tasks, RPA still delivers better unit economics.”
UnleashX AI Agent ROI Study, March 2026 — UnleashX Research
The Three Patterns That Separate Success From Failure
Narrow scope from day one: Not “automate customer service” but “automate tier-1 refund requests under $500.” Specificity is what makes governance possible.
Hard limits defined before deployment: What systems the agent can touch, what actions require human approval, what triggers automatic escalation, all documented before a single production transaction runs.
30-day accuracy monitoring with automatic HITL thresholds: Measure hallucination rates and decision accuracy in the first month and set hard thresholds for escalation before those metrics degrade, not after.
The 5-Step Migration Path: From RPA-Heavy to Hybrid Agentic Architecture
This is the framework enterprise automation architects are copying into their internal planning documents. It’s action-oriented by design. Each step has a named deliverable because an internal automation migration without deliverables is a roadmap that never gets executed.
Audit your existing RPA estate. Catalog every bot in production. For each: monthly maintenance cost, failure rate, exception escalation volume, and last time the underlying process changed. Any bot consuming more than 40% of its build cost in annual maintenance, or escalating more than 15% of transactions to humans, is a candidate for agentic replacement. Deliverable: RPA Health Scorecard with migration priority tier per bot.
Identify your highest-value agentic AI target. Select one complex, high-value use case where intelligent decision-making creates differentiated value, not just cost savings. The ideal first agentic deployment: high exception rate, unstructured data input, multi-system coordination requirement, measurable business outcome (cycle time, cost per transaction, resolution rate). Avoid deploying agents on tasks where RPA already works well. Deliverable: Agentic AI pilot brief for one selected workflow.
Build governance infrastructure before deployment. Define agent scope boundaries, approval gates for consequential actions, reasoning log requirements, and HITL thresholds. The governance infrastructure takes 2 to 4 weeks to build properly and prevents the remediation costs that dominate failed agentic deployments. Don’t deploy the agent to production without it. Deliverable: Agent Governance Policy for the pilot workflow.
Run parallel in shadow mode before full deployment. Deploy the agent in shadow mode, it processes real transactions but its outputs are reviewed by humans before taking effect. Measure decision accuracy rate, hallucination incidents, escalation rate, and cycle time vs. baseline. Set a go-live threshold (e.g., 95% accuracy, less than 5% escalation rate, zero critical incidents in 30 days) and don’t move to production until shadow mode metrics exceed it. Deliverable: Shadow Mode Performance Report + Go/No-Go decision. See our guide on moving AI to production for the full framework.
Scale horizontally using the proven pattern. Once one agentic workflow is in stable production, replicate the governance model, not the specific implementation, across new workflows. The architecture pattern (agent orchestrates, RPA executes, human reviews exceptions) is reusable. Each new workflow needs its own scope definition and HITL thresholds, but the underlying infrastructure, logging, monitoring, escalation pipeline, is shared. Deliverable: Agentic AI Playbook v1.0, the internal standard for all future agent deployments.
The Platforms Enterprises Are Evaluating for This Migration
Three platforms dominate enterprise evaluation lists for this transition in 2026. UiPath’s Agentic Automation, built around its Maestro orchestration layer, allows existing RPA assets to be reused within agentic workflows, a significant advantage for enterprises with large bot estates that don’t want to abandon prior investment. Salesforce Agentforce, now deployed across 8,000-plus enterprise customers, is the dominant choice for customer-facing agentic workflows. ServiceNow AI Agents holds the top position for ITSM use cases, where its native integration with the ServiceNow platform creates meaningful deployment advantages.
The CTO’s Pre-Decision Checklist: 10 Questions Before Committing to Agentic AI
If you answer “No” or “Don’t know” to more than three of these, your agentic AI deployment isn’t production-ready. That’s not a reason to stop, it’s a roadmap for the next 30 days.
#
Question
If No…
1
Is the target process too unstructured or exception-heavy for RPA?
RPA may be the better choice — re-evaluate the use case
2
Can we define a clear, measurable outcome for the agent?
Don’t deploy, vague goals produce ungovernable agents
3
Have we defined hard scope limits (what systems, what actions)?
Build governance infrastructure first — non-negotiable
4
Do we have a reasoning log and audit trail requirement defined?
Regulated industries can’t proceed without this in place
5
Have we set HITL approval thresholds for consequential actions?
Define before deployment — not after the first incident
6
Is the LLM infrastructure (RAG, grounding, validation) in place?
Deploy without it and hallucination becomes operational risk
7
Have we budgeted for $0.01–$0.10 per decision at production scale?
Re-run the TCO model — most initial budgets underestimate by 3x
8
Have we red-teamed adversarial inputs before production?
Prompt injection vulnerabilities are found in red team, not production
9
Is shadow mode testing planned before full deployment?
Add a 30-day shadow mode period before go-live — always
10
Do we have an agent incident response playbook ready?
Draft it now — the first agent incident should not be the first time you think about response
The checklist tells you exactly what to build before you go live. The enterprises that reach production, the 12%, aren’t necessarily the ones with the biggest budgets or the most advanced AI teams. They’re the ones that treated governance as a prerequisite, not an afterthought. The next 30 days determine which category your organization falls into.
Frequently Asked Questions
What is the difference between agentic AI and RPA in enterprise automation?
RPA uses software bots to follow pre-defined, rule-based scripts, automating structured, repetitive tasks by mimicking human UI actions at $0.001 per task with deterministic outcomes. Agentic AI uses large language models to set goals, plan steps, make decisions, and adapt to new situations without explicit programming, at $0.01–$0.10 per decision. RPA excels on structured, stable, high-volume tasks; agentic AI excels on unstructured data, judgment-heavy workflows, and end-to-end process automation where exceptions are the norm rather than the exception.
Is RPA obsolete in 2026?
No. RPA still delivers 250% ROI on structured, stable, high-volume tasks and remains the right tool for deterministic execution where audit trails must be reproducible and cost-per-transaction must be minimized. The obsolescence risk is for pure-RPA architectures applied to complex, exception-heavy workflows, not for RPA itself. The dominant enterprise architecture in 2026 is hybrid: agentic AI as the orchestration and reasoning layer, RPA bots as the execution layer for backend structured operations.
What ROI does agentic AI deliver in enterprise deployments?
Production-grade AI agents achieve 171% ROI globally (192% in the US) on judgment-heavy workflows, according to the UnleashX AI Agent ROI Study (March 2026). Companies using agentic AI on complex, exception-heavy workflows report 85% automation cost reduction versus RPA-only approaches. AP processing costs have dropped from $4.50 to $0.45 per invoice in hybrid agentic deployments. On structured, high-volume tasks, however, RPA’s 250% ROI still outperforms agentic AI on a cost-per-task basis, context determines the right tool.
Why do so many agentic AI projects fail to reach production?
Only 12% of agentic AI projects reach production today, with three primary failure modes: unclear ROI from misapplied use cases (deploying agents on tasks RPA handles better), insufficient governance infrastructure (no scope limits, HITL thresholds, or audit trails defined before deployment), and underestimated inference costs at scale. Gartner warns 40%+ of agentic AI projects may be scrapped by 2027. The 5-step migration framework above addresses each failure mode directly before it becomes a six-figure remediation.
What is the best hybrid automation architecture for enterprises in 2026?
The most effective enterprise automation architecture uses agentic AI as the “brain”, reading unstructured inputs, making routing and decision calls, orchestrating workflows, and RPA bots as the “hands”, executing structured backend operations (updating ERPs, triggering payments, filing documents) based on the agent’s decisions. This hybrid model captures RPA’s 99.9% accuracy and $0.001/task economics for execution while capturing agentic AI’s ability to handle the 80–90% of enterprise data that is unstructured and inaccessible to RPA alone.
How do I know if my current RPA bots are candidates for agentic replacement?
Two reliable signals: any bot consuming more than 40% of its build cost in annual maintenance is a strong replacement candidate, and any bot escalating more than 15% of transactions to humans indicates the process has more exception complexity than RPA was built to handle. Run a full RPA Health Scorecard, cataloging maintenance cost, failure rate, and escalation volume per bot, before committing resources to an agentic migration. The bots that survive that audit are the ones you keep running on RPA.
What governance controls are required before deploying an AI agent in production?
Four controls are non-negotiable before production: hard scope boundaries defining what systems and actions the agent can access; approval gates requiring human or secondary-agent confirmation for consequential actions (financial transactions, external communications, data exports); immutable reasoning logs capturing every decision path with timestamp, context, conclusion, and action taken; and a red-team test against adversarial inputs including prompt injection scenarios. In regulated industries, these controls are compliance requirements under EU AI Act Article 12 and SEC AI risk disclosure rules, not optional governance hygiene.
How much should I budget for agentic AI inference costs at enterprise scale?
Budget $0.01–$0.10 per decision and model your production transaction volume against that range before committing to deployment. Most initial enterprise budgets underestimate this by a factor of three, according to the RPA Automate Cost Benchmark Report (March 2026). The offset is in maintenance: organizations deploying agentic AI report 73% lower maintenance costs than legacy RPA, and one agent handling diverse scenarios replaces multiple brittle bots with individual maintenance cycles. Run a 36-month total cost of ownership model, not a per-task rate card comparison.
AI hallucinations cost global enterprises an estimated $67.4 billion in 2024. Not from science fiction scenarios. From real production systems confidently generating wrong information, fabricated citations, and invented facts, all delivered with the tone of certainty. And 47% of enterprise AI users made at least one major business decision based on hallucinated content that same year, according to Deloitte’s 2026 AI adoption survey.
The headline numbers from model vendors are misleading. Yes, GPT-4o hallucinates just 0.7% of the time on general knowledge summarization benchmarks. But legal AI tools hallucinate on 17–34% of real legal queries. Medical AI reaches 64% hallucination rates on clinical cases without mitigation. And the Stanford AI Index 2026 reports hallucination rates ranging from 22% to 94% across 26 leading LLMs on complex reasoning tasks. The gap between benchmark and production is not a rounding error. It’s an operational hazard.
This guide gives engineering and security leaders the complete picture: what AI hallucination actually is at the model level, why it gets dramatically worse in agentic AI systems, how to measure it in your production environment, and the proven 3-layer mitigation stack that reduces rates by over 85% when properly implemented. This is the article your model vendor doesn’t want you to read before signing a procurement contract.
What AI Hallucination Actually Is | Beyond the Buzzword
The Technical Reality Most Explainers Skip
LLMs do not retrieve facts. They predict the most statistically probable next token based on patterns absorbed from training data. Hallucination is not a bug in the traditional software sense, it is an inherent property of probabilistic text generation. A 2025 mathematical proof confirmed that hallucinations are structurally inevitable under current LLM architectures. Retrieval-augmented generation and human-in-the-loop review reduce them. Neither eliminates them.
That framing matters for enterprise planning. The question is not whether your deployed model hallucinates. It does. The question is how much it hallucinates in the specific domain, on the specific query types, under the specific conditions you’ve deployed it in, and what you’ve built to catch it before it affects a decision.
The Four Hallucination Types
Type
Description
Example
Detection Difficulty
Factual
States something verifiably false as true
Wrong court case dates, fabricated statistics
Moderate — verifiable against external sources
Citation
Invents a source or attributes claims to the wrong source
A journal article that doesn’t exist
Moderate — link checking catches most
Reasoning
Individual facts are correct but the logical chain is invalid
“Revenue grew 20%, costs grew 15%, so margins expanded”, not necessarily true
High — everything looks right until the conclusion
Instruction
Model ignores or partially follows a prompt constraint
Generates content outside specified boundaries
Low to moderate — output review catches it
Factual hallucinations were present in 8–12% of queries in 2024. Top models have pushed general-knowledge factual error rates down to 0.3–0.7%, but rates spike sharply on obscure topics and recent events. Citation hallucinations remain in 30%+ of chatbot-generated answers in research contexts. Reasoning hallucinations are the hardest to catch because the output looks internally coherent.
Why Benchmark Numbers Don’t Reflect Production Reality
The Vectara HHEM Leaderboard measures grounded hallucination: how often a model fabricates facts when summarizing a document it was explicitly given. Top models score below 1% here. Production enterprise AI rarely works on clean single-document summarization. Real enterprise queries involve multi-document retrieval, complex reasoning chains, recent events, and domain-specific knowledge, all conditions where hallucination rates multiply 10–50x above benchmark levels.
The Stanford AI Index 2026 puts the range bluntly: 22% to 94% across 26 leading LLMs on complex tasks. That range is not model variance, it is the gap between what models are benchmarked on and what enterprises actually ask them to do.
The Entropy Gap: Why Creativity and Accuracy Trade Off
Based on Shannon’s information entropy, low entropy produces high accuracy with limited novelty. High entropy produces creative but often false answers. When users push models toward nuanced analysis or edge-case advice, they push models toward higher entropy, and higher hallucination risk. This is the core tension in enterprise AI deployment, and no prompt can fully resolve it. It has to be managed at the architecture level.
Why Hallucination Is Far Worse in Agentic AI Than in Copilots
The Compounding Effect No One Models
A copilot hallucinates once per user interaction, and a human reads the output before acting. An AI agent hallucinates once per step in a multi-step reasoning chain, and acts before a human sees the output. Gartner’s March 2026 research puts agentic workflows at 10–20 LLM calls per task. If each call carries a 2% hallucination rate, a 15-step agent chain has a 26% probability of at least one hallucination affecting the final output, before compounding effects from hallucinations feeding into subsequent steps.
Multi-turn conversational agents show hallucination rates of up to 35% during extended interactions. That’s not a benchmark quirk, it’s what happens when context accumulates, retrieval gaps appear, and the model starts predicting forward from its own earlier (potentially flawed) outputs rather than from grounded source material. This is the stat that should make every engineering lead re-examine their agentic AI production failures retrospective.
When Hallucination Becomes an Unauthorized Action
When agents hallucinate, they don’t just return wrong text. They can make unauthorized API calls, misroute data, trigger incorrect workflows, or delete the wrong records. The Stanford AI Index 2026 specifically flags this: in agentic systems, hallucinations can lead to unauthorized API calls or data leaks. That is categorically different from a copilot hallucination, which a human can catch and discard. An agent hallucination may be irreversible before anyone sees the output.
This is not a theoretical risk. Production agentic systems in finance and legal workflows are triggering real downstream consequences from planning-stage hallucinations. The architecture has to account for this.
Role Separation: The Right Architectural Response
The most effective architectural control for agentic hallucination is role separation. One model plans the actions. A separate deterministic script or monitor model validates the plan against an allowlist of permitted actions before execution. This prevents a planning hallucination from becoming an execution error. It’s the same principle as a four-eyes approval process, except it runs in milliseconds.
For high-stakes agents in security, finance, or healthcare, the complementary principle is “fail-closed”: if the model’s confidence or grounding score falls below a defined threshold, the system escalates to a human analyst rather than proceeding. This is the architectural equivalent of a circuit breaker. Agents designed to fail open, continuing with low-confidence outputs rather than halting, are production liabilities waiting for the right query to expose them.
Hallucination Rates by Domain: Where Your Enterprise Risk Actually Lives
The table below is the insight most enterprise AI conversations skip. Hallucination is not a model property, it is a domain × deployment × mitigation property. The same GPT-4o that hallucinates 0.7% on summarization benchmarks produces hallucinated legal citations in 17–34% of legal research queries. Model selection alone cannot solve this. Architecture and mitigation layers must.
Domain / Use Case
Hallucination Rate
Risk Level
Key Finding
General summarization
0.7–1.8% (top models)
Low
Vectara HHEM Leaderboard 2026, benchmark conditions only
Enterprise chatbots (live production)
~18%
Medium-High
Real production rates far exceed benchmark numbers
Medical / Clinical AI
43–64% without mitigation
Critical
MedRxiv 2025: drops to 23% with structured mitigation prompts
Stanford: RAG reduces but doesn’t eliminate; retrieval failures persist
Product recommendation AI
Up to 25% accuracy impact
Medium
UC San Diego 2026: AI summaries hallucinated in 60% of tested scenarios
Legal and medical are the clearest danger zones. In legal, the Stanford RegLab/HAI study remains the definitive benchmark: LLMs hallucinate between 69% and 88% of the time on specific legal queries. Researcher Damien Charlotin maintains a database of 120+ court cases where AI-hallucinated quotes, fabricated cases, or fake legal citations were discovered. In legal, hallucination is synonymous with malpractice risk, full stop.
In medical, ECRI listed AI risks as the #1 health technology hazard for 2025. Without mitigation prompts, hallucination rates on clinical cases reach 64.1% on long cases and 67.6% on short cases, according to the MedRxiv 2025 study of 300 physician-validated vignettes. Even at the best-case rate of 23% with full mitigation applied, nearly 1 in 4 medical AI responses contains fabricated information. These are not acceptable residual rates without mandatory physician review on every clinical output.
How to Measure Hallucination Rate in Your Production System
The Measurement Gap Most Teams Don’t Know They Have
91% of enterprises have implemented explicit hallucination mitigation protocols. Far fewer measure actual hallucination rates in production. Without measurement, mitigation is guesswork. Most teams implement RAG and assume the problem is solved. Stanford research shows RAG-powered legal tools still hallucinate 17–33% of the time. Organizations implementing RAG without measuring outcomes are deploying production AI systems they cannot describe, audit, or improve.
The Four RAG Evaluation Metrics Every ML Team Must Track