Category: Technology

NeuralWired’s Technology section covers the developments reshaping how the world builds, deploys, and regulates digital innovation. We report daily on the stories driving global conversation in artificial intelligence, big technology companies, startups and venture funding, cybersecurity, consumer gadgets and devices, and blockchain and cryptocurrency.

Our technology coverage goes beyond product announcements. When a major AI model launches, we explain what it can actually do and where its claims are overstated. When a startup raises a large funding round, we look at whether the business behind it can sustain that valuation. When a cybersecurity breach hits the news, we explain who is affected and what comes next, not just what happened. Each article is built from original research into primary sources, including company statements, technical documentation, regulatory filings, and verified data, and is written by our editorial team rather than generated automatically.

Readers come to this section for daily updates on the technology stories that matter globally, from shifts inside major technology companies to emerging tools changing how people work, communicate, and build. Whether you are a founder, an investor, an engineer, or simply someone trying to understand where technology is heading next, NeuralWired’s Technology coverage is built to keep you informed without wasting your time on hype.

  • Artemis II Mission Results 2026: What the Data Proved

    Artemis II Mission Results 2026: What the Data Proved

    Artemis II Returns: What 10 Days Around the Moon Just Proved | NeuralWired
    NeuralWired.com , Frontier intelligence for technologists, investors, and decision-makers. This Technology report covers NASA’s Artemis II lunar mission: the first crewed deep-space flight in 53 years, what the engineering data actually shows, and what comes next for the Moon economy.

    Technology

    Artemis II Returns: What 10 Days Around the Moon Actually Proved in 2026

    The capsule hit the Pacific at Mach 33. The heat shield held. The crew is fine. But the real story isn’t the splashdown. It’s the 9 days of data NASA just collected that will define human spaceflight for the next 30 years.

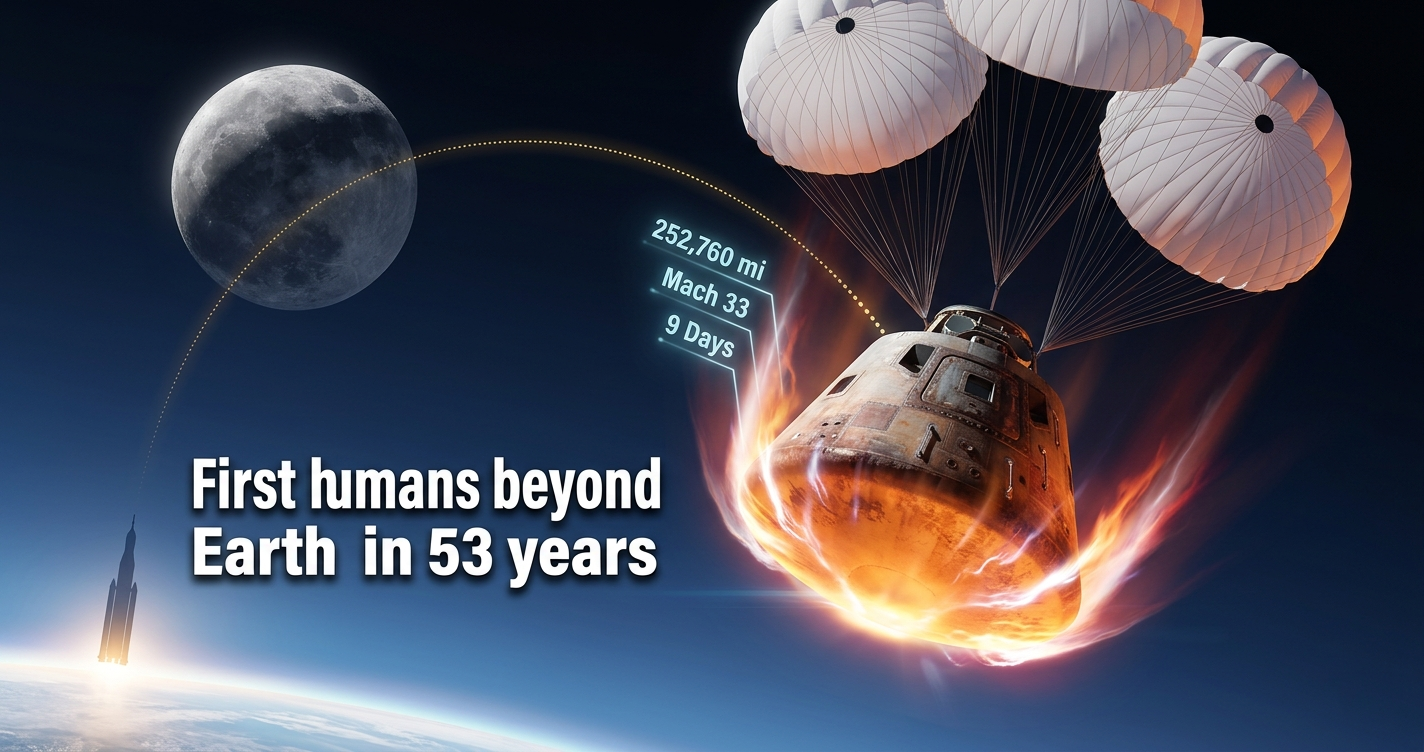
    252,760Miles from Earth
    9d 1hMission Duration
    Mach 33Reentry Speed
    2,800°CPeak Heat Shield Temp
    4gMax Deceleration
    At 8:07 p.m. EDT on April 10, 2026, four astronauts splashed down in the Pacific Ocean off San Diego, ending a 9-day, 1-hour journey that took them farther from Earth than any human has traveled since December 1972. Artemis II isn’t just a headline. It’s the first crewed deep-space validation test in over half a century, and the data it produced will either greenlight or delay every crewed Moon landing planned through the 2030s.

    This isn’t a mission recap. It’s an engineering post-mortem, a strategic read, and a candid look at what actually worked, what flagged anomalies, and what the glossy NASA press releases glossed over. For every technologist, investor, or decision-maker trying to gauge where the crewed lunar economy is headed, this is the analysis you need.

    Why This Mission Is Different From Apollo

    Apollo was about planting a flag. Artemis II is about certifying a system. That distinction matters enormously when you’re trying to interpret the results.

    NASA’s explicit goal for Artemis II was to validate the Orion crew module and Space Launch System under real crewed conditions, not to land on the Moon, not to conduct science, but to stress-test hardware that will carry humans to the lunar surface on Artemis III. Think of it as a flight acceptance test at 252,760 miles altitude, with four people inside.

    That framing changes how you read every piece of data from the mission. The heat shield erosion question, the toilet line ice obstruction, the helium pressurization anomaly, none of these would make headlines on a purely robotic mission. On a crewed test flight, they’re exactly the kind of fidelity NASA needed to collect.

    Context
    The last time humans traveled beyond low-Earth orbit was December 7 to 19, 1972, aboard Apollo 17. That’s a 53-year gap. Artemis II carried Reid Wiseman, Victor Glover, Christina Koch, and Jeremy Hansen, the first woman and first non-U.S. astronaut to travel around the Moon.

    The strategic subtext is geopolitical. China has publicly targeted its own crewed lunar landing around 2030. The Artemis Accords framework, signed by 40+ nations, depends on the U.S. demonstrating credible deep-space capability first. Artemis II either validates that position or quietly acknowledges it’s in jeopardy.

    It validated it. Mostly.

    The Flight: What Actually Happened, Day by Day

    SLS lifted off from Kennedy Space Center on April 1, 2026. What followed was a precisely choreographed sequence of burns, attitude-control checks, and navigation exercises designed to stress every major subsystem.

    April 1: Launch Day
    SLS lifts off from Kennedy Space Center. Orion, carrying all four crew, reaches initial Earth orbit. Manual attitude-control checks begin; crew takes hands-on control to validate the cockpit interface and Orion’s response authority.
    Days 2 to 3: Translunar Injection
    Orion executes its powered injection out of Earth orbit. GPS coverage falls away. Navigation transitions to inertial sensors, star trackers, and ground tracking. This is the same setup that will be used on every subsequent mission.
    Distance from Earth: ~100,000 miles and increasing
    Days 4 to 6: Lunar Transit & Flyby
    Free-return trajectory carries Orion around the Moon’s far side at closest approach. Crew photographs the far side and conducts Earth/Moon observations. Earthrise and Earthset documented for the first time from a crewed vehicle since Apollo.
    252,760 miles from Earth. A new record, surpassing Apollo 13
    Days 7 to 9: Return Transit
    Midcourse correction burns executed. Navigation models updated. Life support anomaly (wastewater vent ice) managed operationally. Minor helium pressurization issue contained without mission impact.
    April 10: Reentry & Splashdown
    Reentry at ~24,500 mph. 6-minute comms blackout. Parachutes deploy in correct sequence. Splashdown at 8:07 p.m. EDT. USS John P. Murtha recovers capsule. All crew in good health.
    The mission ran to 9 days, 1 hour, 31 minutes, and 35 seconds, within the planned window. The Orion capsule, nicknamed “Integrity,” performed without any mission-critical failures. That’s the headline. The details are more interesting.

    The Heat Shield Problem Nobody’s Talking About

    The single most consequential engineering question going into Artemis II wasn’t propulsion or navigation. It was the heat shield.

    When Artemis I, the uncrewed 2022 test flight, returned from lunar orbit, NASA discovered more char erosion on the Orion heat shield than computational models had predicted. The agency spent two years investigating. The conclusion: the original skip-reentry profile, which was designed to reduce peak heating by bouncing off the upper atmosphere, was actually causing complex, hard-to-model heating patterns that drove unexpected ablator loss.

    “NASA switched from the originally planned skip reentry to a steeper single-pass entry to reduce complex heating patterns after Artemis I erosion findings.”

    Wikipedia / Artemis II Engineering Record
    That’s a significant design pivot. A steeper entry means less time at peak heating, but it also means higher peak deceleration forces on the crew, up to roughly 4g. For a 10-day deep-space mission where astronauts are already physiologically stressed, that’s a meaningful tradeoff.

    The good news: post-flight inspections so far indicate the revised heat shield design performed as intended. External temperatures peaked around 2,700 to 2,800°C during the 6-minute blackout phase. The ablator did its job. That clears a critical gate for Artemis III.

    The full post-flight inspection data won’t be public for weeks. But “performed as intended” from NASA’s own engineers is the signal investors and program managers should watch.

    Engineering Data: What Passed, What Flagged

    Artemis II was always going to produce anomalies. That’s the point of a test flight. The question is severity and repeatability. Here’s an honest accounting of what the mission data shows:

    System Status What Happened Implication for Artemis III
    Heat Shield PASS Revised steeper-entry profile; ablator performed as designed at ~2,800°C peak Clears major certification gate; full inspection pending
    Parachute System PASS All 11 chutes (drogues, pilots, mains) deployed in correct sequence; capsule under 20 mph at splashdown Deployment software and redundancy logic validated
    Deep-Space Navigation PASS Maintained precise attitude & trajectory at 252,760 miles; GPS-denied environment using star trackers + inertial sensors Navigation architecture confirmed for lunar landing approach
    Propulsion / Helium MINOR ANOMALY Helium issue in oxidizer tank pressurization system; contained, no mission safety impact Requires root cause analysis before Artemis III
    ECLSS / Life Support MINOR ANOMALY Wastewater vent line partially obstructed by ice; managed operationally; crew unaffected Vent design revision likely; valuable condensation/icing telemetry captured
    Recovery Systems PASS Uprighting airbags and flotation gear worked nominally; crew aboard USS John P. Murtha within hours Informs rough-sea contingency architecture for future missions
    The two anomalies (helium and the toilet vent) are worth context. Both were managed in real time by the crew and flight controllers, which is actually what you want from a crewed test mission. You want to find these failure modes with a crew that can adapt, not on an automated lander touching down at the south pole with no one to improvise.

    The propulsion helium issue warrants closer scrutiny before Artemis III. Helium is used to pressurize propellant tanks; if that system behaves unexpectedly on a 10-day flyby, the implications for a mission requiring precision lunar orbit insertion are different in kind, not just degree.

    First Humans Beyond LEO in 53 Years: What the Data Shows

    The hardware data is important. The human data may be more consequential for the long-term program.

    Artemis II is the first mission in over five decades to expose a crew to the complete deep-space environment beyond low-Earth orbit: full galactic cosmic ray flux, solar particle event exposure, extended microgravity, and the psychological weight of being genuinely far from Earth. The ISS, for all its complexity, sits within the Van Allen belts, which provide partial radiation shielding. Orion doesn’t have that luxury.

    NASA collected roughly 10 days of medical and physiological telemetry from all four crew members. That dataset, when it’s fully analyzed over the coming months, will be among the most valuable biomedical records in the history of crewed spaceflight. It directly informs crew health protocols, shielding requirements, mission duration limits, and countermeasures for Artemis III’s surface mission and eventual Mars planning.

    Strategic Signal
    Christina Koch became the first woman to travel beyond LEO in history. Jeremy Hansen became the first non-U.S. astronaut to travel around the Moon. Both firsts are diplomatically significant: they reinforce the Artemis Accords’ framing of lunar exploration as an international enterprise, not a U.S.-only endeavor, directly countering China’s narrative about its own program.

    Crew debriefs will also feed back into Orion’s cockpit and habitability design. Sleeping arrangements, workload distribution, the manual attitude-control interface, the Earthrise viewing windows, all of this gets refined for Artemis III. That might sound like industrial design, but for a mission where crew error during lunar orbit insertion could be fatal, the human-factors data from Artemis II is as mission-critical as the heat shield telemetry.

    What Comes Next: When to Believe It

    NASA characterized Artemis II as a “textbook mission,” and by the metrics that matter for program continuation, that characterization holds. The heat shield worked. The parachutes worked. Four astronauts are alive and healthy. The program lives.

    But the path to Artemis III, the first crewed lunar landing since Apollo 17, is still complicated. Several timelines are in tension:

    SpaceX’s Human Landing System. The Starship HLS variant, selected by NASA to land crew on the Moon, is on its own development schedule. Artemis III requires Starship to complete at least one uncrewed lunar landing demonstration before astronauts board it. That demo hasn’t happened yet. Artemis III’s “late 2020s” target is real, but it’s gated by Starship progress as much as Orion’s certification.

    Root cause analysis. The helium anomaly and the ECLSS vent issue both require investigation. NASA’s standard process runs 6 to 12 months for flight anomaly resolution. That doesn’t automatically delay Artemis III, but it adds dependencies to an already complex schedule.

    Lunar Gateway. Artemis IV and V introduce the Lunar Gateway, a small space station in lunar orbit that will serve as a staging point for surface missions. Gateway components are under construction, but assembly in lunar orbit hasn’t started. The more complex missions depend on it.

    “NASA leadership under Administrator Jared Isaacman has publicly argued for increasing the cadence of Artemis missions and streamlining program execution to make regular lunar flights a norm rather than an exception.”

    Isaacman public statement, 2026
    The lunar economy framing matters here for investors. Analysts describe the sector as an emerging multi-trillion-dollar opportunity anchored on resource extraction (specifically polar water ice, which can be electrolyzed into rocket propellant), infrastructure, and advanced propulsion. That economic case depends entirely on mission cadence. One crewed landing per decade doesn’t build an economy. Six per decade might.

    Artemis II confirms the hardware can do the mission. What it can’t confirm is whether the institutional and commercial systems surrounding it can sustain the cadence required to make lunar operations economically meaningful.

    That’s the question Artemis III has to answer.

    Frequently Asked Questions

    What was the Artemis II mission? +
    Artemis II was NASA’s first crewed lunar mission since 1972. Four astronauts, Reid Wiseman, Victor Glover, Christina Koch, and Jeremy Hansen, launched aboard Orion on April 1, 2026, flew around the Moon on a free-return trajectory without landing, and returned to Earth on April 10 to 11, 2026. The mission’s primary objective was certifying the Orion capsule and Space Launch System for future crewed lunar landings.
    Did Artemis II land on the Moon? +
    No. Artemis II was a flyby mission, not a landing. Orion used a free-return trajectory to loop around the Moon’s far side at closest approach and return to Earth via gravity assist. The first crewed lunar landing of the Artemis program is planned for Artemis III, currently targeted for the late 2020s.
    Who was on the Artemis II crew? +
    Commander Reid Wiseman (NASA), Pilot Victor Glover (NASA), Mission Specialist Christina Koch (NASA, first woman to travel beyond LEO), and Mission Specialist Jeremy Hansen (Canadian Space Agency, first non-U.S. astronaut to travel around the Moon). All four were in good health following splashdown and recovery aboard USS John P. Murtha.
    How fast did Artemis II reenter the atmosphere? +
    Orion hit the atmosphere at approximately 24,000 to 25,000 mph, or around Mach 33. Peak plasma temperatures around the exterior of the capsule reached approximately 2,700 to 2,800°C. There was a 6-minute communications blackout due to ionized plasma around the capsule during peak heating.
    Why did NASA change the reentry profile from Artemis I? +
    Artemis I’s uncrewed 2022 mission revealed more char erosion on the heat shield than models predicted. NASA investigated and found the original skip-reentry profile caused complex heating patterns that drove unexpected ablator loss. For Artemis II, they switched to a steeper, single-pass entry. This increased peak deceleration to roughly 4g but produced a more predictable and manageable heating profile. Post-flight inspections indicate it worked as intended.
    What anomalies occurred during Artemis II? +
    Two minor anomalies were reported. First, a helium issue tied to oxidizer tank pressurization in the propulsion system, contained without mission safety impact but requiring root cause analysis. Second, a wastewater vent line partially obstructed by ice in the life support system, managed operationally. Neither threatened the crew or mission success.
    How far did Artemis II travel from Earth? +
    Orion reached approximately 252,760 miles (roughly 1.1 million km) from Earth, the farthest any humans have traveled since Apollo 13 in 1970, which held the previous distance record. The mission duration was 9 days, 1 hour, 31 minutes, and 35 seconds from launch to splashdown.
    When is Artemis III launching? +
    NASA currently targets Artemis III for the late 2020s, though an exact date has not been confirmed. The mission requires both Orion/SLS certification from Artemis II data analysis and a successful uncrewed lunar landing demonstration by SpaceX’s Starship Human Landing System. The helium anomaly investigation from Artemis II may add timeline dependencies.
    What does Artemis II mean for the lunar economy? +
    Artemis II validates the foundational transportation system for a sustained lunar presence. The broader lunar economy, built on water ice extraction, in-situ propellant production, and infrastructure development, requires consistent mission cadence to become commercially viable. Artemis II proves the hardware works. The economic case depends on whether NASA and its commercial partners can sustain 5 to 6 missions per decade rather than one every few years. Industry analysts describe the sector as a potential multi-trillion-dollar opportunity over the coming decades.

    The Bigger Picture

    Step back from the engineering details and a clearer pattern emerges. Artemis II proved that the 50-year knowledge gap in human deep-space operations is closeable. The heat shield works. Deep-space navigation works. Eleven parachutes deploy in sequence at Mach 33. Four people can survive 10 days beyond the protection of Earth’s magnetic field and come home healthy. That’s not trivial. That’s foundational.

    But here’s the part that gets underplayed: the most important deliverables from Artemis II aren’t the press conference photos. They’re the anomaly reports, the heat shield inspection data, the radiation biotelemetry, and the crew habitability debriefs. These documents won’t be public for months but will quietly determine the design parameters of every crewed lunar vehicle built over the next two decades. The Artemis program’s value isn’t in the missions we see. It’s in the margins those missions define.

    Watch for three developments through late 2026: the full heat shield inspection report (the most mission-critical data point for Artemis III greenlight), progress on SpaceX’s Starship uncrewed lunar demonstration (the real gating factor for a crewed landing), and whether NASA maintains or slips the program cadence that Administrator Isaacman has publicly committed to accelerating. The first humans back on the Moon are somewhere in that critical path.

    Stay Ahead of Deep-Space Developments

    NeuralWired tracks Artemis, commercial space, and the emerging lunar economy every week. Subscribe to The Neural Loop for frontier intelligence delivered to your inbox.

    Subscribe to The Neural Loop →

    Sources & References

    NASA: Artemis II Mission Overview · Wikipedia: Artemis II · Space.com: Live Mission Updates · Al Jazeera: Splashdown Coverage · ESA: Artemis II / European Service Module · KACU: Recovery Report · AInvest: Lunar Economy Analysis · Isaacman on Mission Cadence

    Disclaimer: This article is based on publicly available information from NASA, ESA, and verified press sources as of April 11, 2026. Full engineering inspection data from the Artemis II mission remains under analysis and has not been officially released by NASA. Nothing in this article constitutes investment advice.

  • Anthropic Project Glasswing: AI Found Zero-Days in Every OS

    Anthropic Project Glasswing: AI Found Zero-Days in Every OS

    Anthropic’s Claude Mythos & Project Glasswing: The AI Too Dangerous to Release | NeuralWired
    Frontier Intelligence for the People Who Build Tomorrow
    You’re reading NeuralWired — the publication built for technologists, CISOs, investors, and operators who can’t afford to be surprised by frontier AI. This piece is part of our ongoing series on AI Safety & Cyber Intelligence. For weekly briefings on what matters before everyone else covers it, subscribe to The Neural Loop.

    Breaking Analysis · AI Cybersecurity · April 10, 2026

    The AI Too Dangerous to Release Just Found Zero-Days in Every Major OS — Here’s What That Means for Your Security

    Claude Mythos Preview autonomously discovered thousands of high-severity vulnerabilities before Anthropic locked it away. Project Glasswing gives 50+ organizations early access. Everyone else gets a ticking clock.

    Trending Analysis By NeuralWired Editorial ~2,200 words · 9 min read Sources: Anthropic, Fortune, CrowdStrike, JPMorganChase, CoreWeave
    93.9%
    SWE-bench Verified score — Mythos Preview
    27yrs
    Age of oldest bug Mythos uncovered — OpenBSD
    $100M
    Compute credits Anthropic committed to Project Glasswing
    On April 7, 2026, Anthropic published a blog post that most security teams hadn’t fully absorbed by the time it went viral. The headline: an AI model they built — and chose not to release — had independently found thousands of critical vulnerabilities hiding in software that runs the internet, every major operating system, and every major browser. Some of those bugs had been sitting there for decades, surviving millions of automated fuzz tests and years of human review.

    The model is called Claude Mythos Preview. The initiative using it is called Project Glasswing. And understanding what both of these mean — not just for Anthropic, but for every organization that depends on software — is quickly becoming a baseline competency for any security leader.

    What Anthropic’s Claude Mythos Actually Is

    Mythos Preview is Anthropic’s most capable model by a considerable margin — and, crucially, the first frontier AI model any major lab has explicitly withheld from public release because of what it can do. This isn’t a safety decision born of ambiguity. It’s a deliberate choice backed by a stark internal assessment.

    According to Anthropic’s own Project Glasswing documentation, Mythos represents a model that is presently far ahead of any other AI in cyber capabilities and presages an era in which AI models can find and exploit vulnerabilities “in ways that far outpace the efforts of defenders.” That language, which appeared in Anthropic’s internal communications before the public announcement, is what triggered stock volatility across major cybersecurity vendors — CrowdStrike, Palo Alto Networks, SentinelOne, and others — when it began circulating in March.

    Mythos isn’t a specialized security scanner. It’s a frontier language model whose advanced agentic coding and reasoning capabilities happen to translate with frightening effectiveness into autonomous vulnerability discovery. Give it access to a codebase and a single prompt, and it can identify subtle logic flaws, construct working exploit chains, and document everything — without requiring human steering at each step.

    Why this matters beyond cybersecurity: Mythos demonstrates that the gap between “AI that helps you code” and “AI that can systematically break any software it touches” is smaller than the industry assumed. That asymmetry — offense scaling faster than defense — is the core challenge Project Glasswing is trying to answer.

    What It Found — And Why That Keeps CISOs Up at Night

    The specific vulnerabilities Mythos uncovered aren’t just impressive in aggregate. The type of bugs it found tells you something important about the limits of conventional security tooling.

    Consider: a 27-year-old vulnerability in OpenBSD that allowed remote machines to crash. A 16-year-old out-of-bounds write in FFmpeg that automated fuzz testing had touched over 5 million times without flagging. A 17-year-old unauthenticated remote root privilege in FreeBSD (CVE-2026-4747). Multiple Linux kernel vulnerabilities that Mythos chained together to escalate from user-level access to full system control. These weren’t obscure corner cases. They were in widely deployed software that billions of systems depend on.

    As Salt Data’s security analysis documented, the FFmpeg finding is particularly instructive. The bug had survived extensive automated testing precisely because discovering it required semantic understanding of intent — what the code was trying to do — not just syntactic pattern matching. Mythos brought that understanding.

    “The window between a vulnerability being discovered and being exploited by an adversary has collapsed — what once took months now happens in minutes with AI. Claude Mythos Preview demonstrates what is now possible for defenders at scale, and adversaries will inevitably look to exploit the same capabilities. That is not a reason to slow down; it’s a reason to move together, faster.”

    — Elia Zaitsev, CTO, CrowdStrike · Anthropic Project Glasswing blog
    The strategic implication Zaitsev is pointing at is the one that should drive your board conversation: the question isn’t whether adversaries will eventually access Mythos-class capabilities. It’s whether your organization will be patched, hardened, and instrumented before they do.

    The Benchmarks: Quantifying the Capability Jump

    Anthropic published direct benchmark comparisons between Mythos Preview and Claude Opus 4.6 — currently their top publicly available model. The gap is substantial across every relevant dimension.

    Benchmark What It Measures Claude Mythos Claude Opus 4.6 Delta
    SWE-bench Verified Real-world code bug fixing 93.9% 80.8% +13.1 pts
    CyberGym Cybersecurity vuln reproduction 83.1% 66.6% +16.5 pts
    Terminal-Bench 2.0 Agentic tool-use in terminal 82.0% 65.4% +16.6 pts
    Terminal-Bench 2.1 (extended) Agentic tool-use, longer horizon 92.1% — —
    OSWorld-Verified OS-level interaction tasks 79.6% 72.7% +6.9 pts
    Source: Anthropic Project Glasswing announcement, April 2026. All scores represent Mythos Preview at maximum effort with adaptive thinking.

    The CyberGym gap (+16.5 points) is the one that matters most for security practitioners. It measures a model’s ability to reproduce known cybersecurity vulnerabilities from documentation — a proxy for how effectively it can understand, replicate, and potentially construct exploit paths. Mythos at 83.1% isn’t just better than Opus 4.6. It’s operating in a different category.

    All benchmarks were run internally by Anthropic. No independent replication exists yet, which is a genuine caveat. But the real-world findings — decades-old zero-days in production codebases — function as an external validation that words in a benchmark table can’t fully capture.

    Project Glasswing: The Coalition Holding the Keys

    Anthropic’s response to having built something it judges too dangerous for public release isn’t to shelve it. It’s to run a structured, gated access program that uses Mythos’ capabilities defensively — finding and patching vulnerabilities in critical infrastructure before adversaries discover them independently.

    That program is Project Glasswing. The initial partner coalition includes some of the most significant institutions in global technology and finance:

    Amazon Web Services Apple Broadcom Cisco CrowdStrike Google JPMorganChase Linux Foundation Microsoft NVIDIA Palo Alto Networks 40+ Critical Infra Orgs
    “We’ve been testing Claude Mythos Preview in our own security operations, applying it to critical codebases, where it’s already helping us strengthen our code. We’re bringing deep security expertise to our partnership with Anthropic and are helping to harden Claude Mythos Preview so even more organizations can advance their most ambitious work with security that sets the standard.”

    — Amy Herzog, VP & CISO, Amazon Web Services · Anthropic Glasswing blog
    Beyond model access, Anthropic is committing up to $100M in usage credits to Glasswing partners, plus $4M in direct donations — $2.5M to Alpha-Omega and OpenSSF through the Linux Foundation, $1.5M to the Apache Software Foundation — to fund open-source security infrastructure. These donations aren’t symbolic. They fund the maintainer capacity needed to process and patch AI-generated vulnerability reports.

    The financial angle matters too. On April 10, 2026 — three days after the Glasswing announcement — CoreWeave and Anthropic announced a multi-year GPU infrastructure agreement to support Claude’s production deployment at scale. CoreWeave reported $5.13B in 2025 revenue with guidance for over $12B in 2026 and a contracted backlog exceeding $66B. Mythos-class workloads don’t run on commodity hardware, and the infrastructure commitments signal that Anthropic is building for sustained operation at frontier scale — not a one-off research demo.

    Risk Matrix: What Mythos-Class AI Means for Your Threat Model

    If Mythos-class capabilities reach adversaries — whether through model weight leakage, independent development by well-funded state actors, or gradual proliferation as the capability ceiling rises across the industry — the following risks move from theoretical to near-certain. Here’s how to prioritize them.

    Critical AI-accelerated zero-day discovery
    Models that scan codebases autonomously compress discovery timelines from months to hours. Every major OS and browser is exposed. Patch cycles become the primary survival variable.

    Critical Autonomous exploit chaining
    Mythos didn’t just find individual bugs — it chained multiple Linux kernel vulnerabilities into a privilege escalation path. AI-driven lateral movement becomes real-time.

    High Open-source supply chain exposure
    The FFmpeg and OpenBSD findings demonstrate that widely deployed OSS carries latent risk that conventional tooling misses. Every downstream dependency is a potential vector.

    High Unmanageable vuln backlogs
    If your team can’t patch faster than AI can find and report issues, you’re accumulating disclosed liability. AI discovery without AI-assisted triage creates a new failure mode.

    Medium Model access leakage
    Gated access programs can leak via insider misuse, prompt extraction, or model weight exfiltration. Current public docs don’t detail Glasswing’s mitigations for this.

    Medium Regulatory and compliance friction
    Anthropic proactively briefed governments on Mythos’ risks. Central banks and financial regulators are already evaluating systemic cyber-risk implications for large institutions.

    The CISO Playbook: 30/90/365-Day Action Framework

    You don’t need Mythos access to start hardening for a Mythos-class threat environment. Here’s a sequenced response.

    Defensive Framework: AI Zero-Day Era

    01

    0–30 Days: Assess & Triage

    Inventory your critical software, open-source dependencies, and highest-exposure services. Map your current vulnerability discovery pipeline — SAST, DAST, fuzzing, manual review — and identify where semantic understanding gaps exist. These are where Mythos-class systems will find what your tools missed. Check your patch SLA against realistic AI-accelerated exploitation timelines.

    02

    30–90 Days: Upgrade Detection & Response

    Deploy AI-augmented code scanning in your CI/CD pipeline — tools that can reason semantically about code behavior, not just match known patterns. Evaluate whether you qualify for Glasswing-adjacent programs as they expand. Conduct tabletop exercises assuming AI-assisted adversaries. Tune your EDR and XDR stack for novel, AI-generated exploit signatures you’ve never seen in the wild before.

    03

    90–365 Days: Structural Hardening

    Build AI-assisted red team capacity internally or through trusted partners. Implement rigorous SBOM tracking and dependency governance — supply chain exposure was central to Mythos’ most dramatic findings. Establish a board-level reporting cadence for AI cyber risk alongside traditional threat briefings. Push regulators for clarity on AI-generated vuln disclosure obligations before they mandate it.

    04

    Ongoing: Monitor & Participate

    Track Glasswing disclosures and CVE publications linked to AI-discovered vulnerabilities as leading indicators. Participate in ISACs and AI-security working groups. Watch for Anthropic’s planned expansion of Mythos-class access as safeguards mature — the organizations that participated in early access programs historically built the deepest defensive expertise.

    “AI capabilities have crossed a threshold that fundamentally changes the urgency required to protect critical infrastructure from cyber threats, and there is no going back. Our foundational work with these models has shown we can identify and fix security vulnerabilities across hardware and software at a pace and scale previously impossible. That is a profound shift, and a clear signal that the old ways of hardening systems are no longer sufficient.”

    — Anthony Grieco, SVP & Chief Security & Trust Officer, Cisco · Anthropic Glasswing blog

    The Contrarian View: Is This Defense or Theater?

    Glasswing’s defenders-first framing has attracted real skepticism, and it deserves engagement rather than dismissal.

    The first concern is structural. Concentrating Mythos access in a coalition of Big Tech companies and large financial institutions doesn’t just protect critical infrastructure — it entrenches it. Smaller enterprises, non-US organizations, academic researchers, and open-source communities without Fortune 500 relationships don’t get early access. The Mythos capability gap between Glasswing partners and everyone else may persist for years. Jim Zemlin of the Linux Foundation acknowledged this tension directly, framing Glasswing as a chance to give even resource-constrained maintainers an “AI-powered sidekick.” But early access remains concentrated at the top.

    The second concern is practical: disclosure without patch capacity creates liability, not security. Mythos can find vulnerabilities faster than human teams can validate, triage, and fix them. If the AI-generated discovery backlog overwhelms the humans responsible for remediation, the net effect could be a larger disclosed attack surface — not a smaller one.

    The third concern cuts to the core of the “defense-first” thesis itself. CrowdStrike’s Zaitsev and Palo Alto’s Lee Klarich both argue that adversaries will develop equivalent capabilities regardless, so the right move is to accelerate defenders. That logic is defensible but not closed. Capable state actors may already have models approaching Mythos-class performance, or they may be years away. The timeline assumption embedded in “move faster together” carries enormous strategic weight — and Anthropic hasn’t published it.

    “Perhaps even more important: everyone needs to prepare for AI-assisted attackers.”
    — Lee Klarich, Chief Product & Technology Officer, Palo Alto Networks
    None of this makes Project Glasswing a bad idea. It makes it an incomplete answer to a problem that will outlast any single initiative. The organizations that treat Glasswing as a complete solution will be wrong. Those who treat it as the opening move in a longer defensive buildout are closer to right.

    Frequently Asked Questions

    Claude Mythos Preview is Anthropic’s most capable and currently unreleased frontier AI model, built with advanced agentic coding and reasoning capabilities that enable it to autonomously discover and exploit software vulnerabilities at scale. It outperforms Claude Opus 4.6 on every major coding and cybersecurity benchmark — including a 93.9% score on SWE-bench Verified — and has already found thousands of high-severity zero-days across every major OS and browser.
    Anthropic determined that Mythos’ cyber capabilities are sufficiently advanced that general public release would materially increase the risk of large-scale AI-assisted cyberattacks. This makes Mythos the first frontier AI model explicitly withheld from public access for safety reasons. Access is restricted to vetted Project Glasswing partners for defensive vulnerability discovery while Anthropic develops safeguards sufficient for broader deployment.
    Project Glasswing is Anthropic’s gated-access initiative that allows a curated coalition of technology, security, and critical-infrastructure organizations to use Claude Mythos Preview for proactive vulnerability discovery and patching. Partners include AWS, Apple, Broadcom, Cisco, CrowdStrike, Google, JPMorganChase, the Linux Foundation, Microsoft, NVIDIA, and Palo Alto Networks, plus more than 40 additional organizations. Anthropic is also committing up to $100M in compute credits and $4M in open-source security donations.
    Mythos uses advanced semantic code understanding combined with agentic tool-use to analyze codebases autonomously, reason about developer intent, and identify flaws that pattern-matching tools miss. In documented cases, it found a 16-year-old FFmpeg vulnerability that had survived 5 million automated fuzz test passes, and chained together multiple Linux kernel flaws into a privilege escalation path — all without human steering at each step.
    Mythos substantially outperforms Opus 4.6 across all measured dimensions: 93.9% vs 80.8% on SWE-bench Verified (code bug fixing), 83.1% vs 66.6% on CyberGym (vulnerability reproduction), and 82.0% vs 65.4% on Terminal-Bench 2.0 (agentic tool use). The CyberGym gap is the most significant for security practitioners — a +16.5 point difference suggests a qualitative shift in autonomous exploit capability.
    In the near term: audit your open-source dependencies for vulnerabilities Mythos has flagged (watch for CVE disclosures tied to Glasswing), tighten patch SLAs to account for compressed exploitation windows, and evaluate AI-augmented code scanning for your CI/CD pipeline. For a full framework, see the 30/90/365-day playbook in this article.
    Yes, in a specific way. JPMorganChase joined Glasswing partly in response to concerns about systemic financial risk from AI-accelerated cyberattacks. Anthropic proactively briefed government agencies on this risk before the public announcement. Financial institutions face both the direct technical threat (AI-found zero-days in banking infrastructure) and a regulatory risk as central banks and financial supervisors assess whether AI-enabled cyber events require new systemic risk frameworks.
    Three main criticisms have emerged: (1) Access concentration — Glasswing primarily benefits large tech companies and financial institutions, leaving smaller organizations and non-US entities without early access or guidance; (2) Patch capacity bottlenecks — AI-generated vulnerability reports may exceed the human capacity to triage and fix them, creating disclosure liability without corresponding security improvements; (3) Timeline assumptions — the “move faster together” thesis assumes adversary development timelines that Anthropic hasn’t made public.
    On April 10, 2026, CoreWeave and Anthropic announced a multi-year GPU infrastructure agreement to support Claude’s production deployment at scale. CoreWeave reported $5.13B in 2025 revenue with $12B+ guidance for 2026. This matters for Mythos specifically because frontier vulnerability discovery at scale requires significant compute — the infrastructure commitment signals that Anthropic is building for sustained operation of Mythos-class workloads, not a single demonstration run.
    Anthropic has not published a timeline. Their stated plan is to expand Mythos-class access once safeguards are sufficiently mature to prevent misuse. Given the pace of capability development across the industry, most security analysts expect either Anthropic to widen Glasswing eligibility, or competing labs to approach similar capability levels, within 18–36 months. The more important question may be governance readiness, not model access.

    What Comes Next

    Project Glasswing and Claude Mythos Preview together represent something genuinely new: a frontier AI capability that a lab judged too dangerous to release, channeled through a structured coalition into a defensive mission. It’s not a perfect solution. The access concentration, patch capacity limits, and opacity around adversary timelines are real problems without clean answers.

    But the deeper pattern here matters more than any individual model or program. Mythos demonstrates that the asymmetry between AI-powered offense and conventional defense has already moved beyond theoretical concern. The bugs it found weren’t edge cases — they were in software your infrastructure depends on today, and they’d been there for decades while the security industry ran its best tools past them millions of times. That changes the security calculus for every organization regardless of whether they ever touch Mythos.

    Watch for three developments in the next 12–18 months: the pace at which CVEs tied to Glasswing disclosures appear in the public record (a proxy for how actively Mythos is being deployed); regulatory movement from financial supervisors treating AI-accelerated cyber risk as a systemic concern rather than an IT problem; and the emergence of competing initiatives from other frontier labs that will determine whether gated access models or open defensive deployments become the industry norm. The organizations building AI-augmented security operations now — before those norms solidify — will set the terms of what comes next.

    Stay ahead of what’s building

    NeuralWired covers the frontier AI stories that change decisions — for technologists, operators, and the people who fund them. Every week.

    Disclaimer: This article is produced for informational and editorial purposes. NeuralWired has no commercial relationship with Anthropic, CoreWeave, or any Project Glasswing partner named herein. Benchmark data is sourced from Anthropic’s April 2026 Project Glasswing announcement and has not been independently replicated at time of publication. This article does not constitute cybersecurity, investment, or legal advice. Readers should consult qualified professionals before making organizational security decisions based on this or any other publication.

  • Meta Muse Spark AI Model: Benchmarks, Strengths & Gaps

    Meta Muse Spark AI Model: Benchmarks, Strengths & Gaps

    Meta Muse Spark: What It Can Do, Where It Fails, and Who Should Care — NeuralWired
    Frontier intelligence for the professionals shaping technology’s future.
    Deep analysis. No hype. Actionable insight.
    AI Models · Frontier Intelligence · April 2026

    Meta Muse Spark: What the Benchmarks Actually Mean, Where It Falls Short, and Who Should Pay Attention

    Meta’s first model from its Superintelligence Labs is genuinely impressive on vision, health reasoning, and token efficiency. It’s also not the coding model you want. Here’s the unvarnished picture.

    Published: April 9, 2026 Reading time: ~14 minutes Category: AI Model Analysis Primary keyword: Meta Muse Spark AI model
    On April 7, 2026, Meta released a model it had been building for months inside a newly formed internal unit called Meta Superintelligence Labs. The model is called Muse Spark. It runs Meta AI on the Meta AI app and meta.ai right now, with WhatsApp, Instagram, Facebook, Messenger, and the Ray-Ban Meta AI glasses to follow in the coming weeks.

    The launch generated the usual wave of breathless coverage mixed with instant skepticism, which is roughly what you’d expect whenever a company with Meta’s reach announces a new frontier model. But if you’re a developer assessing whether to integrate it, a CTO deciding whether to move budget, or a researcher tracking the competitive dynamics of the frontier model race, the breathless/skeptical binary isn’t particularly useful. You need actual numbers, an honest accounting of where the model fits and where it doesn’t, and some sense of what the broader strategy actually is.

    That’s what this piece is for.

    The organizational context you need to understand first

    Muse Spark didn’t emerge from Meta’s existing AI research pipeline. It came from a new unit, Meta Superintelligence Labs, that was stood up specifically because Mark Zuckerberg was reportedly dissatisfied with the progress of Meta’s Llama program. That’s not a minor footnote. It signals that Zuckerberg looked at where Llama was heading and concluded it wasn’t going to get Meta where it needed to be fast enough.

    To lead the new lab, Meta recruited Alexandr Wang, co-founder and former CEO of Scale AI. Shortly before the launch, Meta also invested $14.3 billion in Scale AI for a 49% stake, securing not just Wang’s leadership but a massive data labeling pipeline. That kind of capital commitment tells you something about how seriously Meta is treating this bet. Analyst commentary frames Meta’s total AI spend, including infrastructure and partnerships, somewhere in the $115–135 billion range across the coming years.

    There’s one more structural fact worth registering: unlike Llama, Muse Spark is closed-source. Meta says it hopes to open-source future versions, but for now the model is proprietary. That’s a deliberate pivot away from the open-source positioning that made Llama popular with researchers and developers worldwide. Whether that’s a strategic shift or just a temporary posture for the flagship line is an open question, but for anyone who built their stack on the assumption that Meta’s models would remain open, it’s a significant change.

    What Muse Spark actually is

    The clearest way to describe Muse Spark is as a natively multimodal model designed to be small, fast, and capable at reasoning tasks, especially those involving images, charts, health information, and scientific content. Meta describes it as “small and fast by design, yet capable enough to reason through complex questions in science, math, and health.”

    “Small” here is relative, and Meta hasn’t disclosed exact parameter counts. But the design philosophy is deliberate: rather than scaling up a single massive model, Muse Spark uses what Meta’s team calls “thought compression” — a test-time scaling approach where multiple parallel subagents collaborate to solve hard problems. The idea is to spend more compute at inference time without making the base model grotesquely large. Alexandr Wang has framed this as a new scaling regime focused on efficient reasoning rather than brute-force parameter growth, a contrarian thesis relative to the prevailing assumption that bigger models always win.

    In practice, this manifests as two modes in the consumer product: an Instant mode for quick answers and a Contemplating mode that spins up the multi-agent reasoning pipeline for harder queries. The latter is where Muse Spark’s reasoning capabilities show up most clearly, and it’s also the mode that carries higher infrastructure cost — something developers will need to account for when thinking about scale.

    Natively multimodal means the model was built from the ground up to handle images, not retrofitted with a vision adapter. It can read charts, parse scientific diagrams, analyze product images, interpret health-related visuals, and process visual data in ways that are architecturally integrated rather than bolted on.

    The benchmark picture, unvarnished

    52
    AI Intelligence Index
    (Artificial Analysis)
    58M
    Output tokens for Index
    (vs 157M for Claude Opus)
    86.4
    CharXiv visual reasoning
    (beats GPT-5.4 at 82.8)
    42.8
    HealthBench Hard
    (leads all models)
    Artificial Analysis’s independent evaluation gives Muse Spark a score of 52 on their AI Intelligence Index — a composite measure running across reasoning, coding, multimodal understanding, and knowledge tasks. GPT-5.4 and Claude Opus 4.6 sit around 57-58; Gemini 3.1 Pro falls around 54-55. That 5-6 point gap is real but not catastrophic. The more interesting number is what it costs to get there.

    Muse Spark used 58 million output tokens to complete the Intelligence Index evaluation. Claude Opus 4.6 used 157 million tokens for the same run. GPT-5.4 used 120 million. Gemini 3.1 Pro Preview came in at 57 million — essentially tied with Muse Spark. For teams running high-volume inference at scale, this efficiency gap has real cost implications. A model that gets you most of the way there at less than half the token count of its nearest competitor on raw intelligence deserves serious consideration.

    Benchmark Muse Spark GPT-5.4 Claude Opus 4.6 Gemini 3.1 Pro
    AI Intelligence Index 52 ~57–58 ~57–58 ~54–55
    Output tokens (Index run) 58M Most efficient 120M 157M 57M
    MMMU-Pro (multimodal) 80.5% ~78–79% ~77–78% 82.4% Leads
    CharXiv visual reasoning 86.4 Leads 82.8 ~80 80.2
    HealthBench Hard 42.8 Leads High 30s–low 40s Similar band Slightly lower
    GDPval-AA (agentic) 1427 1676 Leads 1648 1320
    TerminalBench Hard (coding) Below leaders 75.1 80.8% SWE-bench 68.5
    τ²-Bench Telecom 92% Top tier — — —
    CritPT (hard physics) 11% Above Claude, Gemini Flash — 3% 9%
    Sources: Artificial Analysis, LushBinary, Meta AI blog. Competitor figures are approximate ranges from independent sources. All benchmarks reflect April 2026 evaluations.

    Muse Spark is the second-most capable vision model we have benchmarked. Agentic performance does not stand out, it scores 1427 on GDPval-AA, behind Claude Sonnet 4.6 and GPT-5.4, but ahead of Gemini 3.1 Pro Preview at 1320.
    Artificial Analysis — Independent AI benchmarking, April 7, 2026
    The overall pattern is consistent across sources. The New York Times noted that Muse Spark “performed better than Meta’s previous AI models but lags rivals on coding ability.” That framing is accurate as far as it goes, though it undersells the multimodal and health performance story.

    Where Muse Spark genuinely leads

    Visual reasoning and multimodal understanding

    This is the clearest competitive advantage. On CharXiv, a benchmark for reading charts, figures, and scientific diagrams, Muse Spark scores 86.4. GPT-5.4 comes in at 82.8, Gemini at 80.2, Claude Opus at around 80. That’s a meaningful lead, not a rounding error. For any workflow that involves parsing research papers, analyzing dashboards, extracting data from medical imaging reports, or reading technical schematics, Muse Spark has a real edge right now.

    On MMMU-Pro, which tests broader multimodal understanding across academic disciplines, Muse Spark scores 80.5%, just behind Gemini 3.1 Pro’s 82.4%, ahead of GPT and Claude. Artificial Analysis labeled it the second-most capable vision model they’ve evaluated, which tracks with these numbers.

    The key word is “natively.” Because multimodal processing is built into the architecture rather than added as a separate module, the model handles complex visual inputs with less prompt engineering overhead. Developers building visual Q&A systems, document parsing pipelines, or science-adjacent applications will find this integration practically useful, not just benchmark-impressive.

    Health reasoning

    Muse Spark leads HealthBench Hard with a score of 42.8, outperforming all major competitors on this evaluation. Meta has explicitly positioned health as a priority, noting that health questions represent one of the top reasons people turn to AI assistants. The benchmark performance backs this up.

    Important caveat for builders: HealthBench Hard measures question-answering accuracy, not clinical safety. Deploying Muse Spark in contexts that inform real medical decisions requires regulatory compliance, validation against clinical standards, and guardrails that are entirely beyond what any benchmark measures. The score tells you the model is good at health Q&A. It doesn’t tell you it’s ready for a clinical workflow without substantial additional work.

    Token efficiency

    The token efficiency picture is one of the most practically significant findings from independent evaluations. At 58 million output tokens to complete the Intelligence Index, less than half of Claude Opus 4.6’s 157 million, and less than half of GPT-5.4’s 120 million, Muse Spark offers a materially different cost profile at scale. If you’re running millions of reasoning queries per day, this number translates directly into infrastructure budgets.

    A 5-point gap from the leaders on raw intelligence is meaningful but not insurmountable, especially given Muse Spark’s strong cost-efficiency profile.

    LushBinary benchmark analysis, April 2026

    Domain-specific reasoning

    On τ²-Bench Telecom, Muse Spark scores 92%, placing it among the highest-performing models on telecom-domain reasoning tasks. On CritPT, a hard physics benchmark where every model scores in single or low double digits, Muse Spark reaches 11% against Claude’s 3% and Gemini Flash’s 9%. These numbers are low in absolute terms because the tasks are genuinely hard, but the relative gaps suggest Muse Spark carries an advantage on scientific reasoning that may generalize to other technical domains.

    Where it falls short, and why that matters

    Coding and software engineering

    This is the cleanest weakness in the profile. On TerminalBench Hard, a benchmark that evaluates models on real coding tasks interacting with a terminal environment, Muse Spark trails Claude Sonnet 4.6, GPT-5.4, and Gemini 3.1 Pro. Claude’s performance on SWE-bench Verified, the standard benchmark for software engineering tasks, sits at 80.8%. GPT-5.4 scores 75.1 on Terminal-Bench 2.0. Muse Spark’s specific score hasn’t been consistently reported, but the direction is clear across sources.

    For teams building coding copilots, automated code review pipelines, or software engineering agents, this isn’t a minor limitation. The gap is large enough that defaulting to Claude or GPT-5.x for these use cases is the rational choice, not a matter of preference. Muse Spark’s test-time scaling advantage through multi-agent Contemplating mode may close this gap on complex reasoning-heavy coding problems, but on general software engineering tasks, it’s behind today.

    Agentic and multi-step work

    On GDPval-AA, a benchmark designed to evaluate models on real-world, multi-step office workflows, Muse Spark scores 1427, against GPT-5.4’s 1676 and Claude Sonnet 4.6’s 1648. It beats Gemini 3.1 Pro Preview at 1320, but the gap with the top performers is significant. For anyone building long-running agents that need to orchestrate multi-step workflows, research automation, enterprise task execution, complex data pipelines, the top two are still GPT and Claude.

    The irony here is partially structural: Muse Spark’s own Contemplating mode uses multi-agent orchestration. But that architecture is optimized for single complex queries, not for sustained multi-step task execution of the kind GDPval-AA is testing.

    Closed-source means lock-in

    For organizations that have built their AI strategies partly around open-source models, using Llama as a foundation, running fine-tuned versions on their own infrastructure, controlling data flows and model behavior, Muse Spark’s closed-source design is a structural problem. You can’t fine-tune it, you can’t self-host it, and you’re entirely dependent on Meta’s API access decisions. Meta has said it hopes to open-source future versions, but “hopes to” is not a roadmap commitment.

    This is a legitimate concern for enterprises in regulated sectors, for research institutions with data governance requirements, and for any team that has learned to be cautious about single-vendor dependencies. The developer community that embraced Llama explicitly because it was open now faces a different proposition.

    Decision framework: who should actually use this

    Choose Muse Spark when

    Your workloads are vision-heavy or health-adjacent

    • Parsing charts, figures, scientific diagrams
    • Health Q&A at scale (with appropriate guardrails)
    • Document intelligence on mixed text-image content
    • Cost-sensitive high-volume reasoning inference
    • Deep integration with Meta’s social surfaces
    Stick with GPT-5.x or Claude when

    Coding quality and agentic execution are the priority

    • Software engineering copilots and code review
    • Long-running multi-step agent pipelines
    • Enterprise stacks needing mature governance tooling
    • Open-source flexibility and fine-tuning requirements
    • Mission-critical agentic workflow execution
    Choose Gemini when

    Google Workspace integration and search grounding matter

    • Tight integration with Google Cloud or Workspace
    • Top-tier MMMU-Pro multimodal score (82.4%)
    • Factual grounding through Google Search
    • Token efficiency matching Muse Spark’s profile
    The key principle for CTOs making this call: model selection should follow workload composition, not brand affinity. A team with 70% of their AI usage in visual document parsing and 30% in code generation probably wants Muse Spark for the former and Claude for the latter. Running a single model for everything because it simplifies billing isn’t a good enough reason to accept a material performance gap in either direction.

    Strategic implications for different stakeholders

    For ML engineers and developers

    The practical question right now is whether you’re on the API waitlist. Muse Spark is in private API preview for select partners. Broader developer access isn’t confirmed on a timeline yet. That matters for planning, you can evaluate the model’s benchmark profile today, but you can’t build production systems against it unless you’re in the preview cohort.

    For teams that do get access, the architecture is worth understanding before you deploy. Contemplating mode’s multi-agent design means per-query costs won’t scale linearly the way they do with a simpler inference call. Building Contemplating mode into a high-frequency pipeline without understanding the token and latency characteristics first is a straightforward way to blow past cost budgets.

    For CTOs and CIOs

    The most significant strategic signal from this launch isn’t Muse Spark’s specific benchmark scores. It’s the closed-source pivot. Meta is now building a proprietary frontier model alongside Llama, not instead of it. That gives Meta two distinct competitive levers, an open-source community play through Llama, and a proprietary capability play through Muse Spark. Watching how the two coexist over the next 12-18 months will tell you a lot about where Meta thinks the commercial value actually is.

    For CTO-level vendor strategy decisions, the practical implication is straightforward: Muse Spark is worth a pilot on visual and health workloads, but not worth treating as a primary strategic dependency until API access is broadly available, pricing is disclosed, and there’s at least 6-12 months of production usage data from early adopters.

    For VCs and investors

    Meta’s $14.3 billion Scale AI investment, combined with the Superintelligence Labs structure and Alexandr Wang’s leadership, signals a serious long-term capital commitment to personal AI at social scale. The model’s consumer deployment, rolling out across WhatsApp, Instagram, Facebook, and glasses, gives Meta an inference volume that no other frontier lab can match. That volume creates a data flywheel that other closed-source model providers don’t have access to. The strategic moat here isn’t the model itself. It’s the distribution.

    For investors evaluating AI infrastructure plays, this matters because Meta is essentially running a 24/7 real-world evaluation of Muse Spark at consumer scale. The feedback signal from billions of interactions on social surfaces will compound over time in ways that benchmark suites can’t capture.

    For policy makers and regulators

    The health positioning and the multimodal surveillance surface are the two things worth watching most carefully here. A model that leads HealthBench Hard and rolls out across WhatsApp and Meta glasses is, in practice, a health advisory system at population scale. The benchmark performance doesn’t resolve questions about misinformation risk, appropriate medical advice boundaries, or liability when the model gets something wrong in a health context.

    The multimodal perception capability combined with glasses deployment creates a different kind of regulatory surface, one that involves real-time visual data processing in the physical world. These aren’t hypothetical concerns. They’re the precise scenarios that existing AI safety frameworks were designed for, and Muse Spark’s deployment timeline moves faster than most regulatory processes can currently track.

    How to access Muse Spark today

    The simplest answer: use the Meta AI app or meta.ai. Muse Spark powers both right now. You can access Instant mode for quick queries and Contemplating mode for harder questions that benefit from the multi-agent reasoning pipeline.

    For API access, the model is in private preview. Meta has indicated that broader enterprise and developer API access will come, but no specific timeline or pricing has been announced. If your organization has an existing Meta partnership or is part of Meta’s developer ecosystem, it’s worth checking whether you qualify for preview access. For everyone else, the path is to watch Meta’s developer blog and the Meta AI technical blog for access announcements.

    The model will roll out to WhatsApp, Instagram, Facebook, Messenger, and Ray-Ban Meta glasses in the coming weeks. For most consumer-facing applications, that’s where exposure will initially come from rather than direct API integration.


    Frequently asked questions

    Muse Spark is Meta’s first model from Meta Superintelligence Labs, announced on April 7, 2026. It’s a natively multimodal, closed-source frontier model designed to be small, fast, and capable at reasoning tasks, particularly those involving images, charts, health information, and scientific content. It powers Meta AI on the Meta AI app and meta.ai, with rollout to WhatsApp, Instagram, Facebook, Messenger, and Ray-Ban glasses coming in the following weeks.

    On Artificial Analysis’s AI Intelligence Index, Muse Spark scores 52 versus GPT-5.4 and Claude Opus 4.6 at around 57-58 and Gemini 3.1 Pro at 54-55. Muse Spark leads on visual reasoning (CharXiv: 86.4 vs GPT-5.4’s 82.8) and HealthBench Hard (42.8, best in class). It trails on coding (TerminalBench Hard) and complex multi-step agentic tasks (GDPval-AA: 1427 vs GPT-5.4’s 1676). Token efficiency is a standout: 58 million output tokens on the Intelligence Index versus Claude’s 157 million.

    No. Unlike Meta’s Llama models, Muse Spark is closed-source and proprietary. Meta has stated it hopes to open-source future versions, but there’s no confirmed timeline. This is a significant departure from Meta’s previous AI strategy and has direct implications for organizations that relied on Llama’s open-source nature for fine-tuning, self-hosting, or data governance reasons.

    Consumer access is available now through the Meta AI app and meta.ai. API access is in private preview for select Meta partners, with broader developer access not yet announced. The model will also roll out across WhatsApp, Instagram, Facebook, Messenger, and Ray-Ban Meta glasses in the coming weeks. No pricing for API access has been disclosed.

    Not as a primary coding model. Multiple independent evaluations confirm that Muse Spark trails Claude Sonnet 4.6 and GPT-5.4 on coding benchmarks including TerminalBench Hard. For software engineering copilots, automated code review, or complex software agent workflows, Claude (which leads SWE-bench Verified at 80.8%) or GPT-5.4 are the stronger current choices. Muse Spark may close this gap over time, but as of April 2026 the coding weakness is clear and consistent across sources.

    Several things fundamentally distinguish them. Muse Spark is closed-source; Llama is open-source. Muse Spark is natively multimodal from the ground up; Llama’s vision capabilities have been added incrementally. Muse Spark uses a multi-agent Contemplating mode for hard reasoning tasks; standard Llama deployments don’t have this architecture. And Muse Spark comes from an entirely new organizational unit, Meta Superintelligence Labs, while Llama continues under the existing Meta AI research line.

    Contemplating mode is Muse Spark’s test-time scaling approach. Rather than running a single large inference pass, it spins up multiple parallel subagents that collaborate to solve hard problems, spending more compute at inference time without making the base model larger. Meta describes this as “thought compression.” The Instant mode is a direct, fast response for simpler queries; Contemplating mode activates the multi-agent pipeline for complex reasoning tasks. Developers should account for higher per-query costs in Contemplating mode compared to Instant mode.

    It performs better than competitors on HealthBench Hard (scoring 42.8), which measures health question-answering accuracy. But benchmark performance and clinical safety are different things. Deploying Muse Spark in applications that inform real medical decisions requires regulatory compliance, clinical validation, and guardrails well beyond what any benchmark measures. Policy observers have already flagged concerns about health AI at social scale without adequate safety infrastructure.

    Meta has confirmed that API access is available in private preview for select partners, with broader access expected in the future. No pricing, SLAs, or specific enterprise contract terms have been disclosed. Organizations planning integrations should monitor Meta’s developer channels for access announcements and factor in the current access limitations when building 2026 AI roadmaps.

    Four primary limitations matter for enterprise decision-making: (1) coding performance trails Claude and GPT-5.4, making it unsuitable as a primary development tool; (2) agentic task execution on GDPval-AA is behind the top two competitors; (3) closed-source design eliminates fine-tuning, self-hosting, and some data governance options; (4) API access is still in private preview with no disclosed pricing or SLAs. For regulated industries, the health deployment at consumer scale also raises compliance and liability questions that enterprises will need to address before adopting.

    The bottom line

    Muse Spark is a genuinely capable model in a specific and well-defined set of domains. The vision reasoning story is real, CharXiv at 86.4, MMMU-Pro near the top of the pack, HealthBench Hard leading the field. The token efficiency picture is also real and practically significant for anyone running reasoning tasks at scale. This isn’t hype padding. Independent benchmarkers at Artificial Analysis and LushBinary measured it, and the numbers hold up.

    The coding and agentic weaknesses are equally real, and equally well-documented. If your primary use case involves writing or reviewing software, or running complex multi-step workflows through an AI agent, Muse Spark isn’t the right tool today. That may change, Meta’s investment trajectory and the “thought compression” scaling philosophy suggest a serious long-term R&D commitment, but it’s the current reality.

    The closed-source pivot is probably the most strategically significant aspect of this launch, and it’s gotten less attention than the benchmark numbers. Meta is building a proprietary frontier model for the first time. Whether that ends up being a long-term strategic direction or a temporary posture for the flagship line will shape the competitive dynamics of the model market over the next 2-3 years. Watch for: broader API availability and pricing transparency (likely Q3 2026), Llama’s path forward now that Muse Spark holds the flagship position, and whether any of the health regulatory scrutiny around large-scale AI deployments on social platforms gains legislative traction in the EU or US in 2026.

    For your own organizations: if you work with visual data, scientific documents, or health content at scale, put Muse Spark in your evaluation queue now and request API preview access. If your stack is primarily about code and software agents, focus your attention elsewhere for the time being. And if you’re a policymaker or regulator, the combination of health positioning and imminent deployment across billions of WhatsApp and Instagram users probably warrants a closer look than a typical model launch would require.

    For ongoing frontier model coverage, benchmarks, and weekly AI intelligence, follow NeuralWired, and share this piece with someone who needs the unvarnished picture.


    Sources & further reading

    Disclaimer: This article is based on publicly available benchmark data, independent evaluations, and media coverage as of April 9, 2026. Benchmark scores for competitor models are approximate ranges drawn from independent third-party sources. All figures should be treated as indicative rather than definitive, as evaluation methodologies and model versions vary. NeuralWired has no commercial relationship with Meta, Anthropic, OpenAI, or Google. Nothing in this article constitutes investment, legal, or clinical advice.
  • Anthropic Mythos AI Model Preview: Cybersecurity 2026

    Anthropic Mythos AI Model Preview: Cybersecurity 2026

    Anthropic’s Claude Mythos AI Model Preview: The Locked-Down Weapon Reshaping Cybersecurity in 2026 | NeuralWired
    This analysis is published by NeuralWired, frontier intelligence for the professionals who build, fund, and govern technology’s future. For related coverage, see our AI Safety and Cybersecurity verticals.

    AI Security

    Anthropic’s Claude Mythos AI Model Preview: The Locked-Down Weapon Reshaping Cybersecurity in 2026

    The most powerful AI model Anthropic has ever built can find zero-days in every major OS. You can’t have it. Here’s why that decision might be the most consequential thing in enterprise security this year.

    Anthropic’s Claude Mythos AI model preview can find a 27-year-old vulnerability in OpenBSD, a 16-year-old exploit in FFmpeg that had survived five million automated scans without detection, and a multi-flaw chain in the Linux kernel. It can do all of this autonomously. And you cannot have access to it.

    That restriction is deliberate. Anthropic announced on April 7, 2026 that Claude Mythos Preview was its most powerful model yet, outperforming every earlier Claude iteration on coding, reasoning, and cybersecurity benchmarks by margins that security practitioners are calling a generational leap. The company simultaneously announced that it would not be releasing the model publicly.

    Instead, Mythos has been reserved for a closed network of 11 founding partners and over 40 additional vetted organizations under a new initiative called Project Glasswing. The logic is straightforward and the stakes are extraordinary: a model this capable in the hands of the wrong actor could automate exploitation of critical infrastructure at a scale and speed that no human security team could outrun.

    This analysis breaks down what Mythos actually is, what the benchmarks reveal, how Project Glasswing is structured, who already has access, and what every CISO, CTO, and security engineer needs to do before the end of 2026 regardless of whether they ever get near the model.

    What is the Anthropic Mythos AI Model Preview?

    Claude Mythos Preview is Anthropic’s description of it as “the most powerful AI model we’ve ever developed.” It supersedes Claude Opus 4.6 as Anthropic’s flagship frontier model and was developed with a specific focus on advanced code reasoning, agentic workflows, and cybersecurity vulnerability discovery.

    The model operates autonomously across multi-step technical tasks. It can be given a codebase, binaries, or a system specification and it will scan for weaknesses, generate exploit proof-of-concept code, and propose patches without requiring a human to guide each step. That level of agentic capability distinguishes Mythos from earlier language models that could discuss security topics but could not execute against them.

    Anthropic first began using Mythos internally in large-scale vulnerability hunts before the April announcement. The results were significant enough to warrant both a formal partner program and a decision not to release the model to the public. According to the Project Glasswing announcement, Mythos has already identified thousands of high-severity vulnerabilities across every major operating system and web browser. Those findings have been reported to software maintainers in a coordinated disclosure process.

    The model carries an internal codename of “Capybara” according to community tracking, and details about its architecture first became public in March 2026 through a content management system misconfiguration that exposed pre-release documentation. The official announcement in April aligned with that leaked framing.

    “AI capabilities have crossed a threshold that fundamentally changes the urgency required to protect critical infrastructure from cyber threats, and there is no going back.”

    Anthony Grieco, SVP and Chief Security and Trust Officer, Cisco

    Benchmark Dominance: The Numbers Behind the Hype

    Vendor benchmark claims deserve scrutiny, and Anthropic’s case for Mythos rests on a suite of evaluations that covers coding, cybersecurity, general reasoning, and agentic task performance. The numbers, drawn from Anthropic’s Glasswing announcement and confirmed by the Mythos system card summary at NxCode, represent double-digit gains over the previous flagship in most categories.

    Benchmark Mythos Preview Claude Opus 4.6 Delta
    CyberGym (vulnerability reproduction) 83.1% 66.6% +16.5 pts
    SWE-bench Verified 93.9% 80.8% +13.1 pts
    SWE-bench Pro 77.8% 53.4% +24.4 pts
    Terminal-Bench 2.0 82.0% 65.4% +16.6 pts
    SWE-bench Multimodal 59.0% 27.1% +31.9 pts
    GPQA Diamond 94.6% 91.3% +3.3 pts
    Humanity’s Last Exam (no tools) 56.8% 40.0% +16.8 pts
    USAMO 2026 97.6% N/A New benchmark
    BrowseComp (4.9x fewer tokens) 86.9% 83.7% +3.2 pts
    OSWorld-Verified 79.6% 72.7% +6.9 pts
    The most striking figures are in the coding categories. The 31-point lead on SWE-bench Multimodal and the 24-point jump on SWE-bench Pro reflect Mythos’s capacity to understand and act on code at a level that earlier models could approximate but not reliably execute. SWE-bench Pro targets professional-grade software engineering tasks, which maps more directly to real security work than sanitized benchmark conditions.

    The CyberGym score deserves attention specifically because it measures vulnerability reproduction rather than theoretical knowledge. A score of 83.1% means that in four out of every five cases, Mythos was able to independently reproduce a known vulnerability from minimal starting information. At Opus 4.6’s 66.6%, that figure was already impressive for an AI system. The Mythos gap represents a fundamentally different operational posture.

    “The window between a vulnerability being discovered and being exploited by an adversary has collapsed. What once took months now happens in minutes with AI.”

    Elia Zaitsev, Chief Technology Officer, CrowdStrike
    These benchmarks were run by Anthropic on its own infrastructure, which means independent replication has not yet occurred. That is a legitimate methodological caveat. But the case studies accompanying the Glasswing announcement, including the 27-year OpenBSD bug and the 16-year FFmpeg vulnerability, provide concrete evidence beyond benchmark scores. The FFmpeg flaw in particular had survived five million automated scans by existing tools without being flagged.

    Project Glasswing and the Partner Coalition

    Project Glasswing is the governance structure Anthropic built around Mythos to enable defensive use while limiting offensive exposure. Named after a transparent-winged butterfly, it functions as a vetted-access program that grants qualifying organizations the ability to run Mythos against their own codebases and infrastructure.

    The 11 founding partners represent a cross-section of the technology and critical infrastructure landscape:

    Amazon Web Services Apple Broadcom Cisco CrowdStrike Google JPMorganChase Linux Foundation Microsoft NVIDIA Palo Alto Networks
    Beyond those 11, more than 40 additional organizations that build or maintain critical software have received access for scanning their own first-party and open-source code. Anthropic has also committed up to $100 million in Mythos usage credits for Glasswing participants and $4 million in direct financial support to open-source security organizations, including $2.5 million to Alpha-Omega and the OpenSSF through the Linux Foundation, and $1.5 million to the Apache Software Foundation.

    Partners can access Mythos through four channels: the Claude API directly, Google Cloud Vertex AI, Amazon Bedrock, and Microsoft Azure Foundry. After the credit period ends, pricing is set at $25 per million input tokens and $125 per million output tokens. Anthropic has committed to publishing a formal progress report within 90 days, covering vulnerabilities fixed and security improvements that can be publicly disclosed.

    “By giving maintainers of critical open-source codebases access to a new generation of AI models that can proactively identify and fix vulnerabilities at scale, Project Glasswing offers a credible path to changing that equation.”

    Jim Zemlin, CEO, The Linux Foundation

    Why Anthropic Is Keeping Mythos Locked Down

    The decision not to release Mythos publicly is not primarily a product strategy. It reflects a specific risk calculation that Anthropic describes explicitly in the Glasswing documentation: a model this capable at finding and exploiting software vulnerabilities is also a model that attackers would pay to access.

    The threat model is not abstract. If a nation-state or ransomware syndicate had access to Mythos-class capabilities, they could automate zero-day discovery across widely deployed infrastructure at a scale that currently requires teams of elite researchers months to replicate manually. The FFmpeg vulnerability that survived 16 years of human and automated scanning is precisely the kind of target that AI-accelerated offense would identify faster than defenders could patch.

    Anthropic’s Dianna Penn, Research Product Management Lead, described the decision to CNBC as “a preliminary move to provide numerous cyber defenders with an advantage on a subject that will grow increasingly vital.” That framing matters. The restriction is presented as temporary. Anthropic has indicated it is working on model-level safeguards that would allow a future Opus-class model to incorporate Mythos-level capabilities with guardrails sufficient to permit broader deployment.

    What Anthropic is not doing is pretending that access controls alone solve the problem. The company acknowledged in its system card that Mythos presents a risk profile it considers too high for general release under current safety frameworks. That admission is more candid than typical vendor safety language and suggests that the internal debate about releasing the model was significant.

    There is also an arms race logic buried in Glasswing’s structure. If defenders do not have access to the best available AI tools, attackers with equivalent or near-equivalent capabilities will find vulnerabilities faster than they can be patched. The partner coalition represents Anthropic’s attempt to get the most capable defenders access to the most capable tools before that gap opens.

    The Enterprise Adoption Roadmap: A Five-Step Framework

    Most enterprises are not in the Glasswing partner list. That creates a strategic planning question: what should you actually do now, and what should you be prepared for when Mythos-class capabilities become more broadly available?

    1
    2 to 3 weeks

    Threat and asset mapping

    Inventory your critical software assets, open-source dependencies, and current vulnerability management stack. Mythos’s documented value is greatest where legacy tools have failed, specifically long-lived bugs in widely trusted components. Without a ranked list of high-impact targets, deploying AI scanning tools generates noise rather than intelligence.

    2
    2 to 4 weeks

    Vendor and access strategy

    Engage account teams at AWS, Google Cloud, and Microsoft to understand your eligibility path for Glasswing participation. If direct access is unavailable, identify which existing security partners are integrating Mythos-class capabilities and begin evaluating how those integrations interact with your stack. Document contractual and data residency constraints before any pilot.

    3
    Parallel, 2 to 4 weeks

    Governance and guardrails design

    Define explicit policies for what any Mythos-adjacent tool can do within your environment: read-only code analysis, no production credentials, mandatory logging, and human review gates for any exploit proof-of-concept or patch recommendation. Restrict initial access to development mirrors and security sandboxes. Get written policy approved by security leadership before any test deployment begins.

    4
    4 to 8 weeks

    Pilot deployment on high-value targets

    Run the model on one to three high-value codebases or attack surfaces. Capture metrics that matter: vulnerabilities found, severity distribution, false positive rate, and time from identification to triage and patch. Compare these numbers against your current SAST, DAST, and bug bounty outputs. If Mythos is not surfacing findings your existing tools miss, the integration cost is not justified at this stage.

    5
    3 to 6 months

    CI/CD integration and scaled automation

    Once the pilot validates incremental value, integrate scanning into pre-merge pipelines for critical services. Enforce human code review on all AI-generated patches. Track mean time to remediation, backlog reduction, and exploitable attack surface shrinkage as primary business metrics. Build a cost model against the $25 per million input and $125 per million output token pricing to ensure the economics hold at scale.

    Before any of the above steps, verify these prerequisites:

    • Complete inventory of critical software assets and open-source dependencies
    • Existing vulnerability management process with ticketing and SLA structures
    • Data-sharing agreements that permit code analysis by external AI services
    • IAM policies and network segmentation capable of sandboxing AI model access
    • Legal and compliance review completed, especially for finance, healthcare, and energy environments
    • Executive alignment on AI-augmented security as a budget priority for 2026

    Risk Matrix: What Could Go Wrong

    The “defense-first” framing of Project Glasswing is a policy choice, not a technical guarantee. Four risk categories deserve serious planning attention.

    Offensive enablement

    High Impact
    Attackers gaining Mythos-class capabilities through leaks, competitive model development, or access control failures. The March 2026 CMS misconfiguration that exposed pre-release Mythos documentation illustrates that access controls fail. Mitigation requires strict governance, model-level safeguards, and government coordination, not access controls alone.

    Code and data leakage

    Medium Impact
    Proprietary code or configuration data exposed through API integrations, logs, or vendor infrastructure. Data minimization protocols, redaction pipelines, and strong vendor data agreements are essential before any production codebase is submitted to external AI services. This risk is present today with all cloud-based code analysis tools.

    Over-reliance and skill atrophy

    Medium Impact
    Organizations reducing human security expertise in response to AI capability gains, creating blind spots when the model fails or is unavailable. Mythos should be positioned as a force multiplier for existing teams, not a replacement. Maintain independent red team capacity and human review of all AI security outputs.

    Regulatory and liability uncertainty

    Medium Impact
    Using frontier AI in safety-critical environments may trigger new regulatory duties, particularly in finance, healthcare, and energy under emerging AI governance frameworks. Early legal engagement with NIST, ENISA-equivalent bodies, and sector-specific regulators is preferable to retroactive compliance. The regulatory landscape around Mythos-class models is still being written.

    Who It Affects and What They Should Do

    The Mythos announcement touches every major stakeholder in the enterprise technology stack differently. The action items are not uniform.

    Stakeholder Immediate impact Key decision in 2026 Risk of inaction
    CISO / CTO New frontier defensive capability; AI-accelerated threats regardless of access Whether to pursue Glasswing access and restructure vuln management budget Increased breach risk from AI-enabled attackers
    Security engineers Access to autonomous vuln discovery that outperforms existing tooling How to integrate safely into workflows and maintain human oversight Tool sprawl, misuse, and missed efficiency gains
    Cloud / platform teams Need to offer Mythos-level capabilities through managed platforms Investment in AI-augmented security product offerings Competitive loss to providers with better AI-security integration
    Open-source maintainers New funding and AI tooling for security without requiring large security teams Whether to apply for Glasswing access via Linux Foundation or Apache programs Continued under-resourced security in widely deployed packages
    Policymakers and regulators Concrete evidence of dual-use danger from frontier models How to classify, oversee, and export-control Mythos-class capabilities Regulatory lag and uncoordinated national responses to AI-aided attacks
    For open-source maintainers specifically, the Linux Foundation’s Jim Zemlin framed the Glasswing funding as a structural shift: AI-augmented security as “a trusted sidekick for every maintainer, not just those who can afford expensive security teams.” The $2.5 million directed to Alpha-Omega and OpenSSF signals that Anthropic is treating the open-source supply chain as a specific attack surface that requires dedicated attention, which aligns with the FFmpeg and Linux kernel findings. These are libraries that underpin billions of deployments.

    For NeuralWired readers who are early-stage founders or investors, the Glasswing structure points toward an emerging category that might be called defensive AI as a platform: the combination of AI-powered vulnerability discovery, automated patch generation, and continuous CI/CD security scanning as a unified product layer. The companies that build on top of Mythos outputs, including automated patch pipelines, attack surface intelligence feeds, and compliance verification tools, represent a significant market opportunity that is only beginning to take shape. For further context on AI investment patterns in 2026, see our AI investment landscape report.

    The Skeptics Are Not Wrong

    The “defense-only” framing around Mythos should be treated as a current policy position, not a permanent technical guarantee. Several lines of criticism deserve attention before any organization makes strategic decisions based on Anthropic’s assurances.

    First, the leakage risk is real and has already occurred once. The March 2026 CMS misconfiguration that exposed Mythos documentation demonstrates that even well-resourced AI companies are not immune to the operational security failures that enable competitive intelligence and capability replication. If the architecture or training methodology behind Mythos-class vulnerability discovery becomes sufficiently well understood, competitive replication by less safety-conscious actors is plausible within two to three years.

    Second, the benchmarks, while impressive, are vendor-run. Anthropic’s CyberGym, SWE-bench configurations, and Terminal-Bench evaluations are conducted on internal infrastructure with internal filtering. Independent replication has not yet occurred. That is not a reason to dismiss the findings, particularly given the case study evidence of specific, patched vulnerabilities. But it is a reason to weight the absolute numbers less heavily than the directional signal they represent.

    Third, the economic reality of Mythos deployment may constrain its reach more than Anthropic’s access controls do. At $25 per million input tokens and $125 per million output tokens, scanning a large enterprise codebase continuously at the level required to capture long-lived vulnerabilities before attackers do could become expensive quickly. Organizations that lack the engineering maturity to integrate AI scanning into CI/CD pipelines will not realize the value, regardless of access.

    Finally, community discussion in spaces like r/Anthropic has raised alignment concerns about a model with Mythos-level offensive capability that is deliberately kept from broad safety review. The 244-page system card indicates Anthropic’s internal risk assessment is thorough. Whether it is sufficient is a question that independent researchers and regulators will need to answer over time.

    None of these objections invalidate the core strategic reality: AI-accelerated exploitation is coming regardless of what Anthropic does with Mythos. The question for every security-conscious organization is not whether to engage with AI-augmented defense. It is how to do so without creating new vulnerabilities in the process. For a broader view of how AI is changing the threat landscape, see our ongoing coverage at NeuralWired Cybersecurity.

    The realistic timeline runs roughly as follows. From 2026 through 2027, Mythos remains restricted to the Glasswing coalition while Anthropic develops the model-level safeguards intended to enable a broader Opus-class release. From 2027 through 2028, Mythos-level capabilities, whether from Anthropic or from competitive models, will become more widely available with better governance frameworks. Over a five to ten year horizon, AI-augmented vulnerability discovery becomes standard in large enterprises and the offense-defense balance shifts to whoever deploys these capabilities more effectively and more responsibly.

    Frequently Asked Questions

    What is the Anthropic Claude Mythos AI model preview?
    Claude Mythos Preview is Anthropic’s newest and most powerful frontier AI model, optimized for advanced coding, reasoning, and cybersecurity tasks. It can autonomously identify and exploit complex software vulnerabilities, outperforming the earlier Claude Opus 4.6 on benchmarks including CyberGym, SWE-bench Verified, and Terminal-Bench. Anthropic describes it as the most powerful model they have ever built and is currently limiting access to vetted organizations through Project Glasswing.

    Why is Anthropic restricting access to the Mythos AI model?
    Anthropic is keeping Mythos in a closed preview because the model can find and exploit software vulnerabilities with an effectiveness that creates serious dual-use and cyberattack risks if widely released. As outlined in the official announcement and follow-up reporting, the company plans to develop stronger model-level safeguards before considering broader deployment. The decision reflects a specific risk calculation, not a product strategy.

    How is Claude Mythos different from Claude Opus?
    Compared to Claude Opus 4.6, Mythos delivers double-digit gains across software engineering and cybersecurity benchmarks. On SWE-bench Pro, the gap is more than 24 percentage points; on CyberGym, more than 16. Mythos also demonstrates stronger agentic coding capabilities, autonomously discovering long-standing vulnerabilities in widely used systems like OpenBSD, FFmpeg, and the Linux kernel without human guidance at each step.

    What is Project Glasswing?
    Project Glasswing is Anthropic’s cross-industry initiative to use Claude Mythos Preview to secure the world’s most critical software. It brings together 11 founding partners including AWS, Apple, Microsoft, Google, and Cisco, plus more than 40 additional institutions, to scan and harden essential software and open-source infrastructure. Anthropic has committed up to $100 million in usage credits and $4 million in direct funding to open-source security organizations as part of the program. Full details are at anthropic.com/glasswing.

    Which companies have early access to Claude Mythos Preview?
    The 11 founding partners are Amazon Web Services, Apple, Broadcom, Cisco, CrowdStrike, Google, JPMorganChase, the Linux Foundation, Microsoft, NVIDIA, and Palo Alto Networks. More than 40 additional organizations that build or maintain critical software infrastructure also have access for defensive security work. The full partner list has not been made public beyond these named organizations.

    Can the public use the Claude Mythos AI model?
    No. Anthropic does not plan to make Claude Mythos Preview generally available. Access is restricted to vetted organizations through Project Glasswing and select cloud platforms including Google Cloud Vertex AI, Amazon Bedrock, and Microsoft Azure Foundry. Even Glasswing participants are expected to use the model exclusively for defensive cybersecurity purposes.

    How does Claude Mythos help with cybersecurity?
    Mythos can scan codebases and binaries autonomously to detect previously unknown vulnerabilities, generate exploit proof-of-concepts, and propose patches, often identifying issues that traditional automated tools and human researchers miss. Anthropic reports it has already found thousands of high-severity issues, including long-standing bugs in every major operating system and web browser, with specific documented cases in OpenBSD, FFmpeg, and the Linux kernel.

    What are the risks if a model like Mythos is weaponized?
    If attackers gain access to Mythos-class capabilities, they could automate zero-day discovery and exploitation across widely deployed software at a speed and scale no human security team could match. This is the primary reason Anthropic has restricted access and is working with governments on oversight frameworks. As CrowdStrike’s CTO noted, adversaries will inevitably seek equivalent capabilities, making governance as important as the access controls themselves.

    Is Claude Mythos available on Google Cloud or AWS?
    Yes, but only for vetted Glasswing participants. Claude Mythos Preview is available in private preview on Google Cloud Vertex AI and is being used within AWS security operations as part of the Glasswing program. This access is invitation-only and limited to organizations focused on defensive cybersecurity use cases. General-purpose access through these platforms is not currently available.

    What benchmarks does Claude Mythos achieve?
    According to Anthropic’s documentation and the Mythos system card summary, key scores include: CyberGym 83.1%, SWE-bench Verified 93.9%, SWE-bench Pro 77.8%, Terminal-Bench 82.0%, GPQA Diamond 94.6%, and USAMO 2026 97.6%. These are vendor-run benchmarks and have not yet been independently replicated, but specific vulnerability case studies accompany the claims as corroborating evidence.

    What the Glasswing Moment Actually Means

    The pattern across what Anthropic has revealed about the Anthropic Mythos AI model preview points to a more significant structural shift than a single model announcement. The combination of autonomous vulnerability discovery, agentic code analysis, and cross-industry partner governance represents the first serious attempt to operationalize frontier AI as critical security infrastructure rather than as a productivity layer. The distinction matters enormously for how organizations plan, budget, and staff their security functions over the next three years.

    Anthropic’s choice to restrict Mythos rather than release it broadly is not a setback for defenders. It is a recognition that the offense-defense balance in AI-augmented security is genuinely fragile and that deploying the most capable tools requires proportionally capable governance. Every organization that waits for the public release before engaging with this question will find itself two or three cycles behind when that release arrives.

    Watch for three developments that will define the next phase. First, Anthropic’s 90-day Glasswing progress report, which will be the first empirical evidence of what Mythos deployment at scale actually produces in terms of patched vulnerabilities and prevented exposure. Second, competitive responses from OpenAI, Google DeepMind, and open-source model developers, who will face pressure to match Mythos-class capability in their own security-oriented offerings. Third, the regulatory response in the United States and European Union to the category of intentionally withheld frontier models, which will shape how future access restrictions are governed and what disclosure obligations apply.

    Organizations that build the governance infrastructure, vendor relationships, and internal competency to work with AI-augmented security tools now, before the market matures and the regulatory environment solidifies, will hold a durable advantage. Those that treat Glasswing as a story to monitor rather than a signal to act on will find themselves reacting rather than leading when the next wave arrives.

    For more on how frontier AI models are reshaping enterprise risk frameworks, see the NeuralWired Enterprise AI Risk series and subscribe to The Neural Loop for weekly frontier intelligence delivered to your inbox.

    Disclaimer: This article is based on publicly available information from Anthropic’s official disclosures, partner statements, and third-party press coverage as of April 8, 2026. Benchmark data cited reflects vendor-reported figures that have not been independently verified. This article does not constitute financial, legal, or cybersecurity advice. NeuralWired has no commercial relationship with Anthropic or any Project Glasswing partner referenced in this piece.

  • Intel Joins Musk’s Terafab: What 1 TW/Year Actually Means for AI’s Future

    Intel Joins Musk’s Terafab: What 1 TW/Year Actually Means for AI’s Future

    Intel Joins Musk’s Terafab: What 1 TW/Year Really Means | NeuralWired
    Breaking APR 07, 2026  |  AI INFRASTRUCTURE
    Intel × Terafab — April 7, 2026

    Intel Joins Musk’s Terafab: What 1 TW/Year Actually Means for AI’s Future

    Intel’s surprise partnership with SpaceX, Tesla, and xAI pushes the world’s most ambitious chip factory from moonshot to credible threat. Here’s the technical reality, the strategic stakes, and the honest risk assessment every CTO and investor needs.

    Engineers CTOs Investors Roboticists Policy Founders

    What Actually Happened on April 7

    On Tuesday morning, Reuters confirmed that Intel will join Elon Musk’s Terafab project alongside SpaceX, xAI, and Tesla, making the audacious chip-factory announcement from March 21 considerably more credible. Intel shares jumped nearly 3% intraday on the news.

    This wasn’t a vague MOU. Intel CEO Lip-Bu Tan posted directly on X: “Intel is proud to join the Terafab project with SpaceX, xAI, and Tesla to help refactor silicon fab technology.” The statement committed Intel’s full stack — design, fabrication, and packaging, to Terafab’s central goal of producing 1 terawatt of AI compute per year.

    That’s not a typo. One terawatt. Per year. From a single facility.

    What does that actually mean? And should you restructure your AI infrastructure strategy around it? Those are the questions this analysis answers, with numbers, not hype.


    What Is Terafab and Why Did Musk Build It?

    Terafab was formally launched on March 21, 2026, via livestream from Austin. It’s a planned vertically integrated semiconductor complex that would house chip design, lithography, fabrication, memory production, advanced packaging, and testing under one roof, essentially a TSMC-killer with Musk’s name on the deed.

    The facility is anchored in Austin, Texas, near Tesla’s Gigafactory, with two distinct production lines: one for chips powering cars and humanoid robots, another aimed at AI data centers in space. Yes — orbital compute infrastructure is part of the roadmap.

    “We either build the TeraFab, or we don’t have the chips, and we need the chips, so we build the TeraFab.”

    Elon Musk, Terafab launch livestream, March 21, 2026
    That quote isn’t theater. Musk has claimed — via Tom’s Hardware’s recap of the launch, that today’s entire global AI compute output of roughly 20 gigawatts per year represents only about 2% of what Tesla, SpaceX, and xAI will eventually need. If you take that math at face value, his companies would require around 1,000 GW/year of compute. The external chip supply chain simply cannot deliver that on anyone’s timeline.

    Whether or not that demand projection proves accurate, the underlying strategic logic is sound: if you need a commodity at a scale the market won’t provide in time, you build the factory.

    The project carries an estimated price tag of US$20–25 billion — significant, but comparable to a single TSMC gigafab and within reach for a coalition of companies with Musk’s combined balance sheet.


    Intel’s 18A: The Technology That Makes This Plausible

    Before Intel’s announcement, Terafab was an interesting bet. After it, the project has a credible process technology backbone.

    Intel’s 18A node, featuring RibbonFET gate-all-around transistors and the industry’s first PowerVia backside power delivery, is the most significant process advancement Intel has shipped in a decade. The published specs show 15% better performance per watt and 30% higher chip density compared to Intel’s previous generation node (Intel 3).

    PowerVia deserves specific attention for AI applications. Modern AI accelerators run at sustained high current draws, where conventional front-side power delivery causes IR drop and limits clock speeds. Intel’s own benchmarks show PowerVia improves cell utilization by 5–10% and delivers up to 4% iso-power performance improvement, small numbers in isolation, but meaningful when you’re running hundreds of thousands of chips at sustained load.

    18A vs TSMC N2: How Do They Stack Up?

    Independent analysis from Introl’s CES 2026 chip breakdown positions Intel 18A’s transistor density as roughly equivalent to TSMC’s N2 process, expected in late 2026 — with approximately 2.5× the density of Intel 7. This would mark Intel’s first process-node parity or leadership since 2016.

    And there’s a roadmap beyond 18A. SemiWiki’s analysis of the 18A(P) variant (published April 4, 2026) projects an additional 10–15% performance improvement and approximately 10% better energy efficiency compared to base 18A. If Terafab eventually adopts 18A(P) for its high-performance AI chips, the efficiency delta over current-generation Nvidia/TSMC silicon could be substantial.

    The North America Angle

    Beyond raw performance, 18A carries geopolitical weight. It’s positioned as the earliest sub-2nm advanced node manufactured in North America, reducing dependency on TSMC in Taiwan and Samsung in South Korea. For any organization, corporate or government, that views AI chip supply concentration as a strategic risk, this matters considerably.

    High-volume manufacturing for 18A was targeted for late 2025 / early 2026. That ramp is underway. Intel’s involvement in Terafab isn’t just a partnership announcement, it’s a commitment to deploy its most advanced process at unprecedented scale.


    Translating 1 TW/Year Into Something Real

    The headline number, 1 terawatt of AI compute per year, is nearly impossible to intuit without a reference point. Here’s how to think about it.

    A modern high-performance AI accelerator (think H100-class) draws roughly 400–700 watts under sustained training loads. At a conservative 500W average, 1 terawatt of continuous installed compute power translates to roughly 2 billion watts, equivalent to around 4 million H100-class GPUs running simultaneously. That’s across installed base, not annual production; annual chip output to support that compute density would be a fraction of that number, but the scale remains staggering.

    For context: current U.S. AI compute sits at roughly 0.5 terawatts per year, according to Remio.ai’s detailed breakdown. Terafab’s target would double the entire country’s current AI compute production from a single facility. Musk himself has framed today’s entire global figure at just 20 GW/year, though that estimate is his own and unverified by independent bodies.

    ⚠ The “50× TSMC/Samsung” Claim Needs Scrutiny

    Remio.ai’s analysis characterizes Terafab’s ambition as “50 times the AI chip volume from TSMC and Samsung combined.” Treat this as rhetorical framing, not a verified figure. TSMC’s AI chip production is expanding rapidly, and the comparison depends heavily on which products count as “AI chips.” The number communicates magnitude; it isn’t a bankable projection.

    What’s the Terafab capacity trajectory for humanoid robots, specifically? Musk has indicated that 100–200 GW/year of Terafab’s output is earmarked for terrestrial applications, cars and humanoids, with the remainder allocated to space-based AI data centers. That terrestrial slice, if achieved, could significantly reduce the compute cost embedded in each robot’s bill of materials.

    Electrek, typically skeptical of Musk’s manufacturing claims, called Terafab “the largest semiconductor fab ever built, by an absurd margin.” That assessment is probably accurate, which is precisely why the execution risks are non-trivial.


    Strategic Implications by Audience

    For CTOs and Infrastructure Leaders

    Terafab + Intel 18A represents a potential third procurement path for advanced AI silicon, beyond Nvidia/AMD chips made at TSMC or Samsung. You shouldn’t restructure your 2026 roadmap around it, the ramp timeline makes that premature, but you should start mapping it into your 2028–2030 scenarios. If your AI infrastructure strategy has more than 60% concentration in one vendor (Nvidia/TSMC), the existence of a credible domestic alternative changes your negotiating posture today, even if the silicon doesn’t ship to external customers for years.

    For Robotics Founders and Product Leaders

    The compute-cost trajectory for humanoid robots is about to get interesting. If Terafab delivers even a fraction of its stated scale using 18A-class chips, the AI processing component of a robot’s bill of materials could drop materially over the next 3–5 years. One fab is explicitly dedicated to cars and humanoids, which means supply prioritization, not just process efficiency. If compute is more than 20% of your robot’s BOM, start modeling scenarios where that cost halves by 2029.

    For Institutional Investors

    Intel’s ~3% intraday jump signals that markets read the Intel-Terafab link as positive for the foundry narrative — not transformative, but directionally meaningful. Longer-term, the question is whether Terafab creates a durable competitive moat for Musk’s companies (insulating them from GPU scarcity) or whether the fab primarily serves as a signaling mechanism to extract better terms from Nvidia and cloud providers. Both outcomes are plausible; the answer determines whether external fab customers ever see competitive pricing.

    For Policy and Regulatory Professionals

    A U.S.-located advanced AI fab tied to Intel could reduce foreign semiconductor dependency, a clear win for domestic industrial policy. But it also concentrates cutting-edge AI compute manufacturing within a small cluster of companies, most of them inside Musk’s orbit. That raises legitimate questions around export controls, antitrust posture, and space-based compute regulation that don’t yet have clear answers in existing law.


    The Honest Risk Assessment

    Electrek’s framing, “Battery Day on steroids, and even less realistic”, isn’t dismissible. Tesla’s track record on aggressive manufacturing timelines is uneven. Full Self-Driving dates slipped repeatedly. Battery Day projections took years longer than promised. Terafab is orders of magnitude more complex than either.

    Execution Risk High
    Building and ramping the largest integrated fab ever attempted, on a bleeding-edge node, in a compressed timeline. First-of-kind mega-projects routinely run 2–3× over budget and schedule.

    Process Node Risk Medium
    Intel’s 18A must hit yield and performance targets in real AI chips. Projected metrics from vendor docs and analysts aren’t the same as measured silicon at volume.

    Demand Mismatch Medium
    If Musk’s projections of needing 50× current global compute prove optimistic, utilization risks and stranded capex become serious problems, especially at $25B in upfront investment.

    Regulatory / Geopolitical Medium
    Space-based AI data centers raise novel questions around spectrum, data jurisdiction, and military application that regulators will scrutinize. Export control regimes could complicate customer access.

    There’s also an organizational risk that rarely gets enough attention: Intel, Tesla, SpaceX, and xAI have genuinely different engineering cultures, risk tolerances, and internal bureaucracies. The history of ambitious cross-company manufacturing ventures is littered with coordination failures. Lip-Bu Tan’s Intel and Musk’s companies have never attempted anything remotely close to this level of integration.


    Realistic Timeline to External Access

    The most important question for anyone outside the Musk ecosystem: when do external customers actually get access to Terafab chips?

    Late 2025 / Early 2026
    Intel 18A High-Volume Manufacturing Ramp
    18A enters production. This is the foundation Terafab’s process technology is built on.

    April 2026 (Now)
    Intel Formally Joins Terafab
    Partnership confirmed. Design, fabrication, and packaging commitments are made. Austin prototype fabs begin configuration.

    2027–2028 (Optimistic)
    Initial Terafab Output — Internal Only
    Early capacity almost certainly serves Tesla, SpaceX, and xAI first. External customers are unlikely to see meaningful allocation during this phase.

    Late 2020s (Conservative)
    External Customer Access at Scale
    If the fab ramps successfully and demand from internal customers is partially met, third-party access becomes realistic, on a timeline of years, not months.

    If you’re planning AI infrastructure for 2026 or 2027, Terafab should not appear on your critical path. If you’re building a five-year compute strategy, it absolutely should appear as a scenario variable, potentially a significant one.


    Key Takeaways

    • Intel’s 18A partnership gives Terafab a credible process foundation, RibbonFET + PowerVia is competitive with TSMC N2.
    • 1 TW/year is genuinely extraordinary scale: roughly 50× current U.S. AI chip output, if projections hold.
    • Near-term (2026–2027) chip access will flow primarily to Tesla, SpaceX, and xAI — not external customers.
    • Execution risk is high. This is the most ambitious fab project ever attempted, with no proven precedent at this scale.
    • For CTOs: use this announcement as a negotiating lever with existing vendors. Don’t restructure procurement around it yet.
    • For investors: Intel’s stock reaction reflects narrative momentum, long-term value depends entirely on execution.

    Frequently Asked Questions

    Terafab is a planned semiconductor megafactory jointly developed by Tesla, SpaceX, and xAI that aims to produce more than one terawatt of AI compute per year by vertically integrating chip design, fabrication, memory production, advanced packaging, and testing in Austin, Texas. It was formally announced on March 21, 2026, with an estimated cost of US$20–25 billion.
    Intel is contributing its 18A advanced process node, chip design capabilities, and packaging technology. CEO Lip-Bu Tan framed the partnership as an opportunity to “refactor silicon fab technology” at unprecedented scale, aligning Intel’s foundry push with a massive guaranteed demand source.
    The stated target is 1 terawatt of AI compute per year. For comparison, current U.S. AI compute sits at roughly 0.5 TW/year, and Musk has claimed global output is only around 20 GW/year, 2% of his companies’ eventual needs.
    Intel 18A uses RibbonFET (gate-all-around) transistors and PowerVia backside power delivery. Intel’s specifications show 15% better performance per watt and 30% higher density vs Intel 3. Independent analysts place its density at roughly equivalent to TSMC N2, making it directly competitive for AI workloads.
    Potentially yes, but not in the near term. One of the Austin fabs is dedicated to chips for cars and humanoids. If compute costs drop significantly on 18A-class chips at scale, the processing component of a robot’s bill of materials could fall materially. Meaningful impact is more likely in the late-2020s window than 2026–2027.
    Currently, nearly all advanced AI accelerators run on Nvidia chips manufactured at TSMC. Terafab would create a parallel supply chain, U.S.-based, Intel-processed, primarily serving Musk’s companies. It’s a competitive alternative to, not a replacement for, the Nvidia-TSMC stack. External customers won’t have meaningful access for years.
    Initial operations are in Austin, Texas, adjacent to Tesla’s Giga Texas campus. The facility will house two advanced chip factories: one for terrestrial AI applications (cars and humanoids) and another for chips destined for space-based AI data centers. A full-scale location for broader expansion hasn’t been finalized.
    Realistically, not before the late 2020s. Early capacity will almost certainly serve Tesla, SpaceX, and xAI first. Advanced fab ramps typically take 2–4 years from initial operations to high-yield external production. Plan for access in the 2029–2030 window under an optimistic scenario.
    Four main categories: construction and yield execution on a historically unprecedented scale; Intel 18A performance in real-world AI chips vs. vendor projections; demand overestimation by Musk creating utilization risk on $25B of capex; and regulatory scrutiny around space-based compute and AI chip export controls. Electrek’s “Battery Day on steroids” comparison is pointed and worth taking seriously.
    Use Terafab’s existence as a negotiating lever with Nvidia and cloud providers now. Model it as a scenario variable in 2028–2030 infrastructure planning. Don’t restructure near-term procurement around it. Maintain strong relationships with existing vendors, and avoid any critical-path dependency until Terafab shows commercial silicon at scale. Diversification is the right posture, not substitution.

    The Bottom Line

    The Intel Terafab partnership does something no amount of Musk enthusiasm could do alone: it gives the project a credible semiconductor technology backbone. Intel’s 18A, with its RibbonFET architecture and PowerVia backside power, is genuinely competitive with TSMC’s best upcoming nodes. That’s not marketing. That’s measured silicon.

    But credible technology and operational delivery at 1 TW/year scale are two entirely different things. The history of first-of-kind mega-projects — in semiconductors, in rockets, in gigafactories, is a history of schedules that slipped and costs that climbed. Terafab is the most ambitious fab project ever attempted. The ambition itself is a risk factor.

    The right response to this announcement isn’t euphoria or dismissal. It’s strategic patience: acknowledge the shift in the long-range compute landscape, use it to strengthen your negotiating position with current vendors, and build contingency plans that don’t require Terafab to work on any specific timeline.

    Watch for three signals in 2026–2027 that will clarify how seriously to take the 1 TW/year target: (1) whether Intel 18A achieves published yield targets in production AI chips, (2) whether Terafab groundbreaking and fab construction stay on announced timelines, and (3) whether any external customers announce formal supply agreements. Each signal will tell you something real about whether this is a permanent shift in the compute landscape, or the most expensive negotiating tactic in semiconductor history.

    Either way, the Intel Musk Terafab AI chip project announcement of April 7, 2026, will be on the list of dates that mattered. The magnitude is still being written.

    Disclaimer: This analysis is based on publicly available reporting and third-party analyst estimates as of April 7, 2026. Financial figures, technical specifications, and timeline projections are directional and may change materially. This article does not constitute financial or investment advice. NeuralWired has no commercial relationship with Intel, Tesla, SpaceX, xAI, or Terafab.

  • Nvidia AI Accelerator Dominance | How Long Will It Last?

    Nvidia AI Accelerator Dominance | How Long Will It Last?

    NeuralWired is an elite frontier technology publication decoding the signals that shape tomorrow, for technologists, investors, and executives who need more than headlines. You are reading a Future Tech deep-dive. Every claim is sourced. Every number is verified. No fluff. Visit neuralwired.com

    Future Tech · April 2026

    Nvidia’s $4 Trillion AI Tax:
    How Long Before the Hyperscalers Stop Paying?

    Nvidia controls roughly 85% of the AI accelerator market and just became the most valuable company on Earth. But its biggest customers are quietly building the exit ramp, and the margins are already starting to slide.

    NeuralWired Staff April 7, 2026 Category: Future Tech 10 min read
    $4T+ Nvidia Market Cap (2026)
    ~85% AI Accelerator Market Share
    +69% Peak YoY Revenue Growth
    Nvidia became the world’s most valuable company not by making the flashiest product, but by owning the one thing every AI company on Earth desperately needs and cannot easily replace. Its AI accelerators power ChatGPT, Google Gemini, Meta’s Llama models, and virtually every frontier AI system running today. The AI accelerator market, which Nvidia controls at roughly 80 to 90 percent, has turned into the most profitable infrastructure position since Microsoft’s Windows dominated enterprise computing.

    By early 2026, Nvidia stood alone in a $4 trillion club of its own making. Apple was below that line. Microsoft was below it. Alphabet, Amazon, Meta, all below. For a chip company founded in 1993 to make graphics cards for video games, this is a remarkable place to stand.

    But the story doesn’t end there. Nvidia’s biggest customers, Microsoft, Google, Amazon, Meta, are each spending tens of billions of dollars trying to reduce their dependence on it. The margins are already sliding. The regulators are starting to watch. This analysis examines exactly how Nvidia built its dominance, what its real moat looks like, and how fast the hyperscalers can actually build the detour.

    01

    The $4 Trillion Tollbooth

    Every major AI company, OpenAI, Google DeepMind, Anthropic, xAI, needs massive compute to train and run frontier models. For the past five years, there has been one credible source for that compute at the performance levels frontier AI demands. That’s Nvidia.

    Its H100, H200, and Blackwell-series accelerators aren’t merely chips. They’re the atoms of the AI age. Every ChatGPT response, every AI-generated image, every real-time inference running at a hyperscaler almost certainly passed through Nvidia silicon. The hyperscalers have collectively spent hundreds of billions acquiring it.

    Nvidia’s data-center revenue grew at rates no megacap company had previously achieved, roughly 69% year-over-year on a multibillion-dollar base. Investors rewarded that with a valuation that now dwarfs companies generating more total revenue. Apple makes more money. Microsoft has more enterprise penetration. Neither is worth more.

    “Nvidia didn’t just win the AI hardware market. It became the tax that the entire intelligence economy pays, invisibly, on every inference, on every training run, on every model shipped.”

    NeuralWired Analysis
    This is what makes the toll road framing accurate: every byte of AI flowing through the world’s data centers generates, somewhere in its journey, a payment to Nvidia. Unlike Apple, which faces Android, Nvidia has no credible volume alternative at scale. Unlike Microsoft, which competes in software markets with real substitutes, Nvidia sells the hardware layer beneath every competitor’s product. That’s platform-level leverage.

    By early 2026, Nvidia stood alone above $4 trillion while Apple, Microsoft, and Alphabet had all slipped back below that mark. It has traded places with Apple and Microsoft repeatedly since 2024, but persistent AI-driven demand has kept it at or near the top.

    02

    CUDA: The Moat That Software Built

    Nvidia’s 80 to 90 percent AI accelerator market share is extraordinary. But market share alone doesn’t explain its staying power. AMD makes competitive AI GPUs. Intel is investing aggressively. Hyperscalers are building their own chips. So why does Nvidia keep winning?

    The answer is CUDA, and the 15 years of developer infrastructure built on top of it.

    Launched in 2006, a decade before “AI” became a boardroom priority, CUDA is Nvidia’s parallel computing platform. It allowed researchers and developers to write software that runs on Nvidia GPUs without speaking fluent hardware. Over fifteen years, a vast network of libraries, tools, frameworks, and institutional knowledge accumulated around it. PyTorch runs on CUDA. TensorFlow runs on CUDA. Every major AI research lab has workflows optimized for it.

    Why CUDA Is So Hard to Displace
    This structural advantage makes Nvidia’s position resemble Microsoft’s Windows more than any chip company of the past. Competitors don’t just need better silicon. They need a migration path, a comparable library network, and enough market pull to convince developers to invest their time in a new platform. That takes years. Nvidia has used those years well.

    03

    The Revolt of the Cloud Giants

    Here is the uncomfortable truth Nvidia’s investors must hold alongside the euphoria: the company’s biggest customers are also its most motivated adversaries.

    Amazon, Google, Meta, and Microsoft are not passively buying Nvidia chips while accepting permanent dependence. Each is building its own AI silicon. Google’s TPUs have been in production for years and are now sold to external cloud customers. Amazon has Trainium for training and Inferentia for inference. Meta is developing custom training chips. Microsoft is investing in its own AI silicon as well.

    The logic is simple. At the scale these companies operate, spending tens of billions annually on AI infrastructure, even a 10% reduction in Nvidia dependency is a multi-billion-dollar annual shift in economics. Every dollar spent on an internal chip that performs comparably is a dollar not paid to Nvidia.

    “The hyperscalers are spending generously to build side roads. They’re not trying to destroy the toll road, not yet. They’re trying to make sure they don’t need it exclusively, forever.”

    NeuralWired Analysis
    AMD is pursuing the same goal from the outside, with its Instinct MI300 and MI350 series chips achieving genuine competitiveness on certain workloads. It’s targeting double-digit AI GPU market share through the late 2020s. The performance gap to Nvidia has narrowed. The software gap, its ROCm platform versus CUDA, remains significant but is closing.

    What’s emerging is less a single competitor and more a slow-motion coalition: hyperscalers building custom silicon, AMD investing in CUDA alternatives, and open-source communities working on vendor-neutral AI software stacks. None of these individually threatens Nvidia’s near-term position. Together, over time, they represent the construction of real infrastructure around the toll road.

    04

    Where the Risks Are Real

    Nvidia’s position is formidable. It is not invincible. Four risk vectors deserve serious attention from anyone evaluating the company at a $4 trillion valuation.

    Risk 01 — Margin Erosion
    From Chips to Systems
    Gross margins have declined from a peak near 78% to the low 70s as Nvidia sells complete rack-scale systems with lower-margin third-party components. As competition intensifies, pricing power will face further pressure.
    Risk 02 — Geopolitics
    The China Constraint
    Export controls block Nvidia’s highest-end chips from China, forcing workaround products and ceding ground to domestic Chinese alternatives. Escalation of these restrictions is a real demand and competitive risk.
    Risk 03 — Regulatory Scrutiny
    The Antitrust Shadow
    As Nvidia becomes critical infrastructure for global AI, antitrust attention is a plausible next step, paralleling the scrutiny that Apple, Microsoft, and Google each faced at their respective peaks of market power.
    Risk 04 — Cycle Risk
    The ROI Question
    Nvidia’s valuation assumes AI capex keeps growing. If enterprise AI projects fail to demonstrate returns, or if more compute-efficient architectures emerge, demand growth could decelerate faster than the market expects.
    The margin story is the most immediate. In the crypto bust of 2018 and the gaming slowdown of 2022, Nvidia’s margins contracted meaningfully when demand softened. A similar dynamic in AI spending, even a temporary one, could compress earnings in ways a $4 trillion market cap cannot easily absorb.

    The regulatory risk is longer-dated but structurally important. What happens when the chip supplier for all of global AI faces antitrust scrutiny similar to what the DOJ brought against Microsoft in the 1990s? Nvidia’s CUDA bundling, its pricing practices, its role as gatekeeper to AI compute, all of it becomes politically reviewable at this level of consequence.

    05

    Jensen’s Bet on Permanence

    Jensen Huang’s response to competitive pressure is to move faster than competitors can follow, releasing new architectures (Hopper, Blackwell, Rubin) on cadences that force customers to keep buying even as they experiment with alternatives, and expanding Nvidia’s footprint from chips into full-stack AI infrastructure: networking, software, enterprise AI platforms, and robotics.

    The thesis Huang is betting on: AI compute demand will expand faster than any alternative infrastructure can be built. If frontier models keep scaling, requiring more parameters, more training compute, more inference capacity, the total market grows even as Nvidia’s share faces pressure. Nvidia doesn’t need to win every dollar. It needs to remain irreplaceable for the highest-stakes workloads.

    It’s a credible thesis. It’s also, at $4 trillion, a thesis the market has already priced in. The margin for error at this valuation is historically narrow. Any disappointment in growth, margins, or technology roadmap could trigger an outsized correction.

    06

    Frequently Asked Questions

    Everything you need to know
    How did Nvidia become the world’s most valuable company?
    Nvidia became the most valuable company by controlling roughly 80 to 90 percent of the AI accelerator market at a moment when every major technology company was spending billions on AI compute. Its data-center revenue grew at unprecedented rates, over 69% year-over-year on a multibillion-dollar base, as hyperscalers competed to buy H100, H200, and Blackwell chips. Investors rewarded this with a valuation that surpassed Apple and Microsoft, reaching $4 trillion by early 2026. Source: CNBC
    What is Nvidia’s market share in AI chips?
    Nvidia commands approximately 80 to 90 percent of the AI accelerator market, making its chips the default choice for training and running state-of-the-art AI models. This dominance means each incremental dollar of AI infrastructure spending disproportionately flows to Nvidia compared to any competitor. Source: Xpert Digital
    What is CUDA and why does it give Nvidia a competitive advantage?
    CUDA is Nvidia’s parallel computing platform, launched in 2006, that lets developers write software for Nvidia GPUs without deep hardware expertise. Over 15 years, every major AI framework including PyTorch, TensorFlow, and JAX built first-class CUDA support. This creates high switching costs: companies can’t simply replace Nvidia hardware without also migrating large codebases and retraining engineering teams.
    Who are Nvidia’s biggest competitors in AI chips?
    AMD is the primary external competitor, with its Instinct MI300 and MI350 chips achieving competitive performance on certain workloads. Google (TPUs), Amazon (Trainium, Inferentia), and Meta are building custom AI silicon internally. Intel is also investing in AI accelerators. None currently challenge Nvidia’s market share, but AMD and the hyperscaler custom-chip programs represent the most credible long-term competition. Source: Xpert Digital
    Why are Nvidia’s margins declining if it dominates the market?
    Nvidia’s gross margins have declined from a peak near 78% to around 73 to 74 percent because it increasingly sells complete rack-scale systems, full clusters with third-party networking, storage, and cooling components, rather than standalone chips. Those bundled system sales carry lower margins than GPU-only sales. Increased competition could put additional pressure on pricing power going forward.
    How do export controls affect Nvidia’s business?
    U.S. export controls prevent Nvidia from selling its highest-performance chips including the H100, H200, and B100 to China and certain other markets. Nvidia has responded with workaround products like the H20 and L20, but these generate less revenue and margin than full-capability chips. The restrictions also accelerate Chinese domestic chip development, creating longer-term competitive risk in a large market. Source: Reuters
    Could Nvidia face antitrust action?
    It’s a plausible risk at this scale. As Nvidia becomes critical infrastructure for global AI compute, regulators in the U.S. and EU may scrutinize its market position, CUDA bundling practices, and pricing power. This mirrors the scrutiny Apple, Microsoft, and Google each faced at their respective peaks. No formal action has been announced, but the risk rises with the company’s strategic importance.
    What is the risk that AI spending slows and hurts Nvidia?
    Nvidia’s $4 trillion valuation is built on the assumption that AI infrastructure spending keeps growing at current rates. If enterprises fail to see return on their AI investments, if more compute-efficient model architectures reduce the need for massive training runs, or if capital expenditure cycles normalize, Nvidia’s revenue growth could decelerate sharply. A high-multiple valuation leaves little room for disappointment.
    Can hyperscalers actually replace Nvidia with their own chips?
    Partially, and over time. Google’s TPUs, Amazon’s Trainium, and similar custom chips are already handling portions of AI workloads internally. But replacing Nvidia entirely would require matching not just raw chip performance but the full CUDA software network, which took 15 years to build. The realistic outcome is that hyperscalers use custom silicon for specific workloads where economics favor it, while continuing to buy Nvidia for frontier model training and high-performance inference.
    What is Nvidia’s next major chip architecture?
    Following the Blackwell architecture (B100/B200 series), Nvidia has announced Rubin as its next-generation platform. Jensen Huang has committed to annual architecture updates, a cadence designed to keep customers on upgrade cycles and make it harder for competitors to close the performance gap. Source: Reuters
    07

    Verdict and What to Watch

    Nvidia is the most important infrastructure company of the AI era and may remain so for the next several years. Its CUDA moat is real. Its execution has been exceptional. The demand for AI compute is not slowing. But the toll road is not eternal.

    The hyperscalers are building detours, methodically, expensively, and with serious long-term intent. The margins are already sliding. The regulators are paying attention. The valuation reflects dominance, not growing pressure.

    Investors who get this right are the ones who hold both truths simultaneously: durable structural advantage, and gathering competitive pressure. Right now the market prices mostly the first. The second is what’s worth watching.

    Three Signals to Watch in 2026 and 2027
    1. Hyperscaler capex disclosures: Watch what fraction of AI infrastructure spending Google, Amazon, and Meta attribute to third-party chips vs. custom silicon. A shift here signals the detour is working.
    2. AMD’s MI350 traction: If AMD wins a landmark hyperscaler contract at volume, not a pilot but at scale, it validates that the CUDA moat has a credible challenger on both hardware and software.
    3. Nvidia’s gross margin trajectory: If margins stabilize above 72% through 2026 despite competitive pressure, the moat is holding. If they continue declining, the pricing power story is weakening faster than bulls expect.
    For the broader AI infrastructure landscape, this Nvidia story is a template: platform-layer dominance is enormously valuable, right up until the moment the platform’s customers decide the value transfer is no longer worth it. Microsoft learned this with Windows. Intel learned it with x86. Nvidia is the next chapter, and how long its toll road holds will define one of the most important competitive dynamics in technology over the next decade.

    Follow NeuralWired’s Future Tech series for ongoing analysis of the power shifts reshaping the AI economy. Subscribe to The Neural Loop for weekly frontier intelligence.

    Disclaimer: This article is for informational and editorial purposes only. Nothing published by NeuralWired constitutes financial, investment, or legal advice. All market data and statistics are sourced from third-party publications and are accurate as of publication date. Readers should conduct their own due diligence before making any investment decisions.

  • Anthropic’s $400M Coefficient Bio Bet: What the Drug Discovery Acquisition Really Signals

    Anthropic’s $400M Coefficient Bio Bet: What the Drug Discovery Acquisition Really Signals

    Frontier Intelligence for the People Who Build Tomorrow
    NeuralWired decodes the moves that shape frontier technology so technologists, investors, and executives can act before the market catches up. This analysis is part of our AI x Life Sciences series.
    A $400 million all-stock deal for fewer than 10 people and a market projected to hit $25 billion. Here’s what Anthropic’s first major acquisition means for every pharma CTO, biotech founder, and life-sciences investor paying attention.

    $400M
    All-stock deal value, Anthropic’s first major acquisition
    <10
    Employees at Coefficient Bio at time of acquisition
    $25B
    Projected AI drug discovery market by 2035 (Roots Analysis)
    0.1%
    Dilution relative to Anthropic’s ~$380B Series G valuation

    What Actually Happened and Why the Timeline Matters

    On April 2, 2026, The Information broke the story: Anthropic had acquired Coefficient Bio, a stealth AI biotech startup, in an all-stock transaction worth approximately $400 million. The team, fewer than 10 people, will join Anthropic’s healthcare and life-sciences group to build AI agents for drug discovery, clinical trial planning, and regulatory workflows.

    Here’s what the straight news coverage missed: the timing isn’t incidental. Coefficient Bio was founded roughly eight months before the deal closed, a company that barely had time to name its product, let alone ship it to customers. The acquisition came just weeks after Anthropic’s February 2026 Series G closed at a reported ~$380 billion valuation. Put those two facts together: Anthropic is sitting on capital, and it wants to move fast.

    Coefficient Bio’s founders aren’t random bio-AI optimists. Nathan C. Frey, the co-founder and CTO, led biological foundation-model work, lab-in-the-loop systems, and NVIDIA BioNeMo collaborations at Genentech’s Prescient Design lab. He took home an ICLR 2024 Outstanding Paper Award for generative modelling applied to drug discovery. This isn’t an acqui-hire of generalists, it’s a targeted grab for one of the tightest niches in applied AI.

    “A tiny, high-caliber team with deep expertise from one of the top pharma AI groups got snapped up quickly to supercharge Anthropic’s push into using frontier AI for real biology and science, not just chat or code, but designing molecules, running virtual/physical experiments, and closing the discovery loop faster than traditional methods allow.”

    Michael Hochstat, AI practitioner at xAI, LinkedIn commentary, April 2, 2026
    The deal also represents Anthropic’s first major acquisition. That context is easy to gloss over. Anthropic has, until now, competed on raw model quality and partnership depth. Acquiring a bio-AI team is a different kind of signal, it says the company believes the fastest path to owning regulated science workflows isn’t building domain expertise from scratch inside a general-purpose lab. It’s buying teams who already know where the bodies are buried in a deeply complex, high-stakes field.

    What Coefficient Bio Actually Built

    Most news coverage described Coefficient as “a stealth AI biotech startup” and moved on. But the platform details matter enormously, because they tell you exactly where Anthropic is pointing Claude’s capabilities next.

    According to The Next Web’s reporting, Coefficient built a platform that lets AI models draft drug R&D plans, manage clinical regulatory strategies, and identify new drug candidates across the discovery pipeline. It integrates directly with tools already embedded in biotech workflows: Benchling (the electronic lab notebook standard), PubMed, and 10x Genomics data platforms.

    The company described its technical ambitions as “AI foundation models, generative modeling, and autonomous lab-in-the-loop systems specifically for biological research and drug discovery.” That phrase, lab-in-the-loop, deserves unpacking. It means AI doesn’t just analyze data; it actively designs experiments, interprets results, and proposes the next experiment in a tight feedback cycle. Think less “ChatGPT for scientists” and more “robotic research colleague that runs its own follow-up studies.”

    📡 Technical Integration Map
    Coefficient’s stack sits on top of Claude as the reasoning core. Domain-specific agents orchestrate workflows, protocol drafting, trial planning, regulatory submissions, while MCP connectors route data from Benchling, PubMed, Snowflake, EHRs, and genomics platforms. The result: end-to-end R&D workflow automation, not point-solution chatbots.

    Dimension Capital, one of the most sophisticated deep-tech investors in the market, owned approximately half the company. That’s not a detail, it’s a validation signal from people who do this for a living and who had full visibility into what Coefficient was building.

    When that team folds into Anthropic’s Claude for Life Sciences stack, which already scores 0.83 on the Protocol QA benchmark, beating the human baseline of 0.79, you get something genuinely new: a frontier language model with deep scientific reasoning and a purpose-built execution layer for the actual workflows that get drugs through to patients.

    Why Pay $400M for Fewer Than 10 People?

    The obvious skeptic’s response: this is an acqui-hire dressed up as strategy. Ten people, eight months old, no public product. Four hundred million dollars.

    It’s the right skepticism to voice. And it’s also, on closer examination, incomplete.

    First, the math. Relative to Anthropic’s ~$380 billion post-Series G valuation, this deal represents approximately 0.1% dilution. For a company of Anthropic’s scale, $400M in stock isn’t a bet-the-company move. It’s a rounding error on the balance sheet, but a very targeted one.

    Second, the alternative. To build equivalent domain expertise internally, Anthropic would need to recruit a team of computational biologists and drug-discovery AI researchers, wait years for institutional knowledge to develop, and navigate a talent market where Genentech-caliber computational biologists command extraordinary packages. The market for this specific expertise is tiny, and the best people don’t move for just compensation, they move for mission alignment and equity upside. Coefficient’s team had both reasons to join Anthropic.

    “Gen AI addresses these pain points by increasing efficiency across the entire clinical-development process, unlocking economic value across three dimensions: up to 50% cost reductions, a 12-plus-month acceleration in trial timelines, and at least a 20% increase in NPV.”

    McKinsey & Company, Generative AI in the Pharmaceutical Industry, January 2024
    Third, the market window. AI-drug discovery is at an inflection. The team that owns the incumbent relationships with pharma CTOs in 2026 will be very hard to dislodge by 2028. DeepMind has Isomorphic Labs. OpenAI is building partnerships. Vertical bio-AI startups are proliferating. Anthropic’s most natural advantage, Claude’s exceptional long-context scientific reasoning, needs a biotech-native execution layer to convert into enterprise contracts. That’s exactly what Coefficient provides.

    The $400M isn’t a valuation of what Coefficient built. It’s a price for the speed, the relationships, and the domain credibility that would otherwise take Anthropic three to five years to develop organically.

    The Market Anthropic Is Targeting: A $25B Window

    Three independent research firms have sized the AI-in-drug-discovery market, and their conclusions vary, which itself is instructive.

    Source 2025 Baseline End Forecast CAGR
    Roots Analysis $6.0B $25.0B (2035) 12.6%
    Precedence Research $6.93B $17.81B (2035) 9.9%
    Research and Markets $2.34B $5.98B (2029) 26.5%
    The range between estimates is wide, and that’s the honest answer. Early-stage markets are hard to size. But the direction is unambiguous: the market is large, growing fast, and currently dominated by fragmented point solutions.

    The broader economic context from McKinsey’s research is even more striking. Their modeling puts generative AI’s potential annual value creation in pharma and medtech at $60 to $110 billion, not as a market cap number, but as actual value delivered through cost reduction, faster timelines, and higher success rates.

    To put that in context: the entire AI-drug-discovery software market is smaller than the value McKinsey estimates the tools could create. That gap is where the real prize is. Anthropic isn’t just trying to sell software licenses, it’s trying to own a piece of the value that software creates in a $1.4 trillion global pharmaceutical industry.

    Another McKinsey report from June 2025 estimates AI could double the pace of R&D and unlock up to $0.5 trillion annually across R&D-intensive sectors including pharma. That’s the ceiling Anthropic is ultimately reaching for, not the near-term software TAM.

    The Competitive Landscape and Where Anthropic Now Fits

    Let’s be direct: Anthropic is late to the bio-AI space, and it knows it.

    DeepMind spun out Isomorphic Labs, a dedicated AI drug-discovery company, and has published foundational work on protein structure prediction that changed the field. OpenAI has been building life-sciences partnerships and has broader research relationships with top academic medical centers. A generation of vertical bio-AI startups, Recursion Pharmaceuticals, Insilico Medicine, Exscientia, built domain-specific models when general-purpose LLMs were still primitive tools for biology.

    So what’s Anthropic’s angle?

    The bet is that frontier general reasoning models, paired with domain-specific execution layers, will outcompete narrow vertical tools, not on molecular generation benchmarks, but on the workflow problem. Most of the time in drug development isn’t spent designing molecules. It’s spent writing protocols, drafting regulatory submissions, planning trial sites, interpreting results, and communicating with health authorities. Those tasks are where Claude already outperforms earlier models, and where Coefficient’s agents are designed to execute.

    🔬 Claude for Life Sciences: Benchmark Reality Check
    Protocol QA benchmark: Claude Sonnet 4.5 scores 0.83 vs. human baseline 0.79 and prior Sonnet 4’s 0.74. This is a task measuring AI understanding of lab protocols, exactly the kind of reasoning that matters in regulated workflows. Source: Anthropic, October 2025. Note: internal benchmarks should be independently validated before drawing strong conclusions.

    Claude in Microsoft Foundry already positions Anthropic inside enterprise pharma IT stacks with HIPAA-aligned deployment, MCP-based connectors to clinical systems, and the compliance credibility that smaller vertical players struggle to establish. Coefficient’s team accelerates the depth of that positioning, from “good general-purpose model with a life-sciences wrapper” to “purpose-built R&D intelligence platform.”

    Whether that’s enough to compete with DeepMind’s structural biology expertise or Recursion’s wet-lab data flywheel is still an open question. But Anthropic isn’t trying to win on every dimension. It’s trying to own the reasoning-and-workflow layer that sits above all those specialized systems.

    What This Means for Your Organization, by Role

    💊 Pharma / Biotech CTOs
    Anthropic is now a credible enterprise vendor, not a research experiment
    Start mapping R&D workflows against Claude’s life-sciences stack. The question is no longer whether to pilot, it’s which workflows to start with and how to structure governance.
    📊 C-Suite Executives
    AI-R&D platforms are a board-level strategic topic
    Use McKinsey’s 12+ month trial acceleration and 20% NPV uplift estimates to frame your internal business case. Build explicit budget lines. Assign accountability at VP level or above.
    🚀 Startup Founders
    AI-native bio teams with domain depth can command outsized exits, fast
    Focus on defensible combinations of proprietary data, domain-specific models, and tight integration with major LLM ecosystems. Generalist bio-AI tooling won’t survive consolidation.
    💰 Institutional Investors
    Consolidation is accelerating, portfolio reassessment is urgent
    Re-evaluate AI-biotech holdings with a lens on ecosystem alignment: which portfolio companies can become indispensable to Anthropic, OpenAI, or Google’s bio stacks vs. which will get acqui-hired or commoditized?
    For policy makers and regulators, the integration of frontier models into core R&D and clinical workflows raises immediate questions about explainability, auditability, and acceptable use in regulatory submissions. The FDA and EMA are watching. Proactive guidance on AI-assisted trial design and regulatory interactions, developed now, before widespread deployment, will be far easier than retroactive frameworks imposed after something goes wrong.

    The CTO Adoption Framework: 5 Steps Before You Deploy

    Based on McKinsey’s clinical IT modernization research and the specific capabilities Anthropic is building with Coefficient, here’s a structured adoption path for pharma and biotech technology leaders:

    • 1
      Map Your Workflow Portfolio (4 to 6 weeks)
      Inventory every R&D and clinical workflow by document intensity and data-analysis complexity. Identify which ones touch regulated data and which have measurable time-cost baselines. Your shortlist should be 5 to 10 candidate workflows with current cycle times documented. Don’t skip this, pilots that skip workflow mapping fail to show ROI.

    • 2
      Assess Data and Compliance Readiness (6 to 8 weeks)
      Evaluate data standardization against CDISC and HL7 FHIR. Map which datasets can be exposed to Claude-class systems via secure connectors without PHI risk. Define your GxP audit-trail requirements before choosing architecture. Many pilots fail here, not because AI isn’t capable, but because the data pipeline isn’t ready.

    • 3
      Choose Your Architecture (6 to 10 weeks)
      Evaluate Claude for Life Sciences against vertical bio-AI vendors and in-house build options. Criteria: integration fit with your existing stack (Benchling, CTMS, safety databases), IP terms, compliance certifications, and deployment model. The best model doesn’t always win, the best-integrated system does.

    • 4
      Run Defined-KPI Pilots (3 to 6 months)
      Launch 2 to 3 pilots, protocol drafting and regulatory response generation are natural starting points, with clear before-and-after metrics: time to draft, revision count, reviewer satisfaction. Run true A/B comparisons against your legacy process. McKinsey’s cited 15 to 30% productivity gains from IT modernization are real, but your baseline matters.

    • 5
      Scale with Governance (6 to 12 months)
      Integrate AI agents into SOPs with human review checkpoints. Log all prompts and outputs for audit readiness. Establish an AI governance board, this isn’t bureaucracy, it’s the thing that keeps a drug development error from becoming a regulatory crisis. Update your change-management plan: the people dimension kills more AI programs than the technology does.

    For a rough ROI estimate: use McKinsey’s upper-bound figures of up to 50% cost reduction in document-heavy processes and 20% NPV uplift as ceiling assumptions, then model your own portfolio’s specifics against conservative 20 to 30% efficiency scenarios. Most mid-size biotech organizations will see payback within 24 months in well-governed deployments.

    The Contrarian Take: What Could Go Wrong

    Anthropic’s Coefficient Bio acquisition is strategically coherent. It’s also a high-conviction bet in a field where hype regularly outruns outcomes. Here’s the honest risk register:

    ⚠ Medium Probability
    Pilots Don’t Scale
    Poor data governance, inadequate IT infrastructure, and change-management failures are the graveyard of enterprise AI programs. McKinsey finds that organizations without R&D IT modernization can’t unlock the 15 to 30% productivity gains the tools promise.

    ⚠ Medium Probability
    Benchmarks Don’t Transfer
    Claude’s Protocol QA score of 0.83 is impressive, but real-world lab data is messier than benchmarks. Edge cases, ambiguous results, and institutional variation can erode trust fast if outputs aren’t validated carefully.

    ✓ Lower Risk
    Regulatory Resistance
    FDA and EMA are moving toward AI guidance, not away from it. Near-term friction is likely in specific submission contexts, but the direction is accommodation, not prohibition. Transparency and human oversight remain non-negotiable.

    ⚠ Real but Manageable
    Competitive Response
    DeepMind, OpenAI, and well-funded vertical bio-AI companies won’t cede the market. Anthropic’s window to establish category leadership is real but not indefinite. Execution speed matters more than this deal alone.

    The most important limitation to name directly: very few AI-designed drugs have completed late-stage clinical trials or reached approval as of early 2026. The pipeline is filling, dozens of AI-originated molecules are in Phase I and II, but the clinical validation loop is long, expensive, and unforgiving. AI can compress timelines at the front end; it can’t escape the biology at the back end.

    The honest timeline: document-heavy workflows (protocol drafts, regulatory letters) will show productivity gains in 1 to 2 years. Deeper integration into experimental design and portfolio decision-making will take 3 to 5 years. Measurable shifts in clinical success rates and asset lifecycles won’t be visible for 5 to 10 years, contingent on adoption, validation, and regulatory adaptation at scale.

    Anyone promising faster than that is selling you the hype, not the reality.

    Frequently Asked Questions

    Answers to the questions professionals are actually asking about the Anthropic Coefficient Bio acquisition.

    Anthropic acquired Coefficient Bio, a stealth AI-native biotech startup founded in 2025, in an all-stock deal worth approximately $400 million. The company had fewer than 10 employees at the time of acquisition. Coefficient’s team is joining Anthropic’s healthcare and life-sciences group to build AI agents for drug discovery, clinical trial planning, and regulatory workflows. First reported by The Information, April 2, 2026.
    Coefficient built a platform enabling AI models to draft drug R&D plans, manage clinical regulatory strategies, and identify drug candidates across the discovery pipeline. It integrated with tools like Benchling, PubMed, and 10x Genomics. The founders described its mission as building “AI foundation models, generative modeling, and autonomous lab-in-the-loop systems” for biological research and drug discovery, meaning AI that not only analyzes data but designs and interprets experiments in an ongoing cycle.
    Three reasons. First, at ~$380B valuation, $400M in stock is 0.1% dilution, a small bet for a strategic priority. Second, recruiting equivalent Genentech-caliber computational biology talent organically would take years. Third, the market window is competitive: DeepMind’s Isomorphic Labs and OpenAI partnerships are already active. Paying a premium for an assembled, credentialed team closes a gap faster than any internal hiring plan could.
    Coefficient’s technology is expected to function as a domain-specific execution layer on top of Claude for Life Sciences. Coefficient-style agents will orchestrate specific workflows, protocol drafting, trial planning, regulatory submissions, using Claude as the reasoning core. Through MCP connectors (already available via Microsoft Foundry), these agents can tap into Benchling, EHR systems, genomics platforms, and scientific literature in real time.
    Current estimates put the global AI-in-drug-discovery market at $6 to $7 billion in 2025, with forecasts ranging from $18B to $25B by 2035 depending on the firm and methodology (9.9% to 26.5% CAGR). McKinsey separately estimates generative AI could create $60 to $110B annually in value for the broader pharma and medtech industry, a figure that dwarfs the software market itself. The range between analyst estimates reflects genuine uncertainty about adoption pace and regulatory evolution.
    Claude for Life Sciences is Anthropic’s version of Claude fine-tuned for scientific, biomedical, and clinical tasks. Launched October 2025, it scores 0.83 on the Protocol QA benchmark (human baseline: 0.79) and shows improvements on the BixBench bioinformatics evaluation. It integrates with platforms like Microsoft Foundry and connects to scientific tools and data sources for multi-step analysis and document drafting.
    Start by mapping your R&D workflows against what Claude’s life-sciences stack can actually do today, not what it promises to do in 18 months. Then assess data and compliance readiness before choosing a vendor. Design pilots with explicit before-and-after KPIs (time to draft, revision cycles, reviewer satisfaction). Use McKinsey’s 15 to 30% productivity gain and 20% NPV uplift estimates as benchmarking anchors, not guarantees. The full 5-step framework is covered above in this article.
    Three categories. Technical: AI models can hallucinate or misinterpret complex biology, human-in-the-loop review remains essential. Organizational: poor data governance and IT infrastructure failures kill more AI programs than technology limitations do. Regulatory: FDA and EMA expect human oversight and full audit trails for AI-assisted workflows; organizations that skip validation frameworks expose themselves to submission risk. The 5 to 10 year gap between AI-assisted discovery and proven clinical outcomes is real and should anchor realistic expectations.
    It validates AI-native biotech as a formal acquisition category for frontier model labs, not just a partnership or licensing target. The Coefficient deal is likely the first in a wave: expect OpenAI, Google, and Microsoft to make similar moves as the market matures. For investors, the implication is dual: consolidation risk (the best independent teams get absorbed early) and platform opportunity (LLM-centric R&D stacks becoming the default infrastructure for pharmaceutical R&D).

    The Bottom Line on the Anthropic Coefficient Bio Acquisition

    Here’s what the market coverage missed: this isn’t a story about $400 million. It’s a story about where the frontier model race goes next. Anthropic and every serious lab watching now understands that general-purpose reasoning alone won’t capture the biggest enterprise value pools. Domain depth wins. Execution infrastructure wins. The team that can actually write the trial protocol, file the regulatory submission, and interpret the omics data, inside a governed, audit-ready workflow, wins the pharma customer.

    The Coefficient acquisition gives Anthropic a credible answer to “but can your model actually do drug discovery?” in a way that no benchmark sheet could. It’s imperfect, early-stage, and genuinely uncertain in outcome. But so was every transformative bet in enterprise software before it became obvious in hindsight.

    Watch three developments through 2026 and 2027: (1) which pharma enterprises announce Claude-powered R&D workflows in production, not pilots, production; (2) whether competing labs match with their own domain-specific acquisitions; and (3) whether FDA releases formal guidance on AI-assisted clinical submissions. Those three signals will tell you whether this deal was the first domino or just an expensive acqui-hire.

    For now, if you’re building in life sciences, the conversation has changed. Frontier models are coming for your R&D stack, and unlike previous waves of “AI for drug discovery,” this time the team behind it knows what a Phase I protocol actually looks like.

    Disclaimer: This article is produced for informational and analytical purposes only. NeuralWired does not provide financial, investment, legal, or medical advice. All market projections cited are sourced from third-party research firms and are subject to significant uncertainty. Deal details are based on secondary reporting from The Information and other publications; Anthropic has not publicly confirmed all figures. Readers should conduct independent due diligence before making any investment or business decisions. All hyperlinks open source material in a new tab for verification.

    Home » Technology » Page 47